Turning Structured Output Into a Game: Hands-On with Token Arcade

Token Arcade turns the LLM's constrained decoding mechanism into a hands-on arcade mini-game experience.
Token Arcade is an interactive tool that gamifies the LLM structured output mechanism. The article explains the core of constrained decoding: the model computes a probability distribution over the next token at every step, and constrained decoding directly masks tokens that don't meet the rules (such as JSON Schema, regex, or case requirements), so the model is guided by the rules throughout generation rather than corrected afterward. The game's Heads or Tails level demonstrates how a case constraint excludes the highest-probability token `He`, while the Tiny Creature level shows step-by-step token decisions under a JSON Schema. Understanding this mechanism helps developers troubleshoot unstable output formats and offers a low-barrier entry point for anyone curious about how LLMs work.
When a large language model generates text, at every step it computes a probability distribution over the next token. Structured Output adds a layer of constraint on top of that—only tokens that satisfy a specific rule (such as a JSON Schema or a regular expression) are allowed through. A recent interactive mini-game called Token Arcade turns this obscure mechanism into an arcade experience you can operate with your own hands.
What Constrained Decoding Is Actually Doing
According to the project's demo video, the essential job of an LLM is to compute the probability of each token appearing. Constrained Decoding does something very direct: it masks or strips out tokens that don't meet the constraints.
This means that when you ask the model to output a JSON object, the tokens that would cause syntax errors never even enter the candidate set. The model isn't corrected "after the fact"—it's guided by the rules at every single step of generation.
Token is the basic unit of text an LLM processes. It can be a complete word (like Heads), part of a word (like He), a punctuation mark, or a space. The model doesn't generate text directly; instead, it first computes a probability for each token over its vocabulary (usually tens of thousands to hundreds of thousands of tokens), then samples the next token based on those probabilities, and repeats. The so-called "probability distribution" refers to the output of this step—a list of values spanning the entire vocabulary and summing to 1. Understanding this is key: constrained decoding can intervene at "every step" precisely because the granularity of generation is the token, not the whole passage of text.
JSON Schema is a specification that uses JSON itself to describe the structure of JSON data. It can declare that a field must be a string, which keys an object must contain, the valid range of a value, and so on. In structured output scenarios, it's often translated into a state machine: each time a token is generated, the parser advances its state and only keeps the tokens allowed by states that can still be reached.
Playing a Round of Coin Flip: Understanding Token Masking
The simplest level in Token Arcade is Heads or Tails. The prompt asks: flip a coin and reply only with Heads or Tails, nothing else.
The game interface shows two things: the constraint (it can only be Heads or Tails), and the list of token probabilities the model computed. The highest-probability token in the list is He—but when you try to select it, it's marked as forbidden.
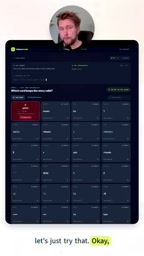
The reason is that the constraint requires starting with a lowercase h, while He starts with an uppercase H. Both Heads and he satisfy the condition. After selecting Heads, the constraint is satisfied, the prompt is answered, and you can then wrap up with an end token.
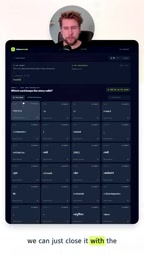
The value of this level is that it fully exposes the judgment process behind "why this token doesn't work." Normally we only see the model's output, not the options that were quietly filtered out of the candidate set.
Masking is the most common way to implement constrained decoding: set the probability of every token in the vocabulary that doesn't meet the current constraint to negative infinity (or 0), then renormalize the remaining tokens. This way, during sampling, the probability of forbidden tokens is strictly zero, and they can never be selected. The alternative is a "stripping" strategy, which trims after generation—but that can corrupt already-generated content, so the mainstream approach remains upfront masking. The crossed-out He in the game is a visualization of real-time masking.
Advanced Level: Assembling a JSON Object
The Tiny Creature level is more complex: generate a JSON object containing a name and an element attribute, with the prompt "invent a tiny fantasy creature."
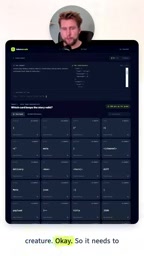
You must start with a left curly brace {—other tokens are rejected. Then come the key name, the colon, the value… at every step you can only pick from tokens that fit JSON syntax.
This level intuitively shows how structured output actually works: the model isn't generating freely and then relying on a parser to validate—it's constrained by the schema at every step. For application scenarios that need stable JSON output—such as tool calling, API response parsing, and data extraction—this mechanism is the foundation of reliability.
Tool Calling / Function Calling is one of the scenarios in current LLM applications that most depends on structured output. The model needs to output a function name and parameters in an agreed-upon JSON format so the application layer can reliably parse and execute them. If the model generates freely and a parser validates afterward, a single syntax error renders the entire output useless, forcing a retry—slow and unstable. Constrained decoding turns this "error then retry" into "it can't go wrong from the start," making it an important underlying capability for building reliable Agents and API integrations.
Why It's Worth Paying Attention To
The author of Token Arcade says the project was made to make structured output "easier to understand." From the actual experience, it genuinely succeeds: it breaks the abstract constrained decoding process into individual, clickable decision points, and immediately gives the reason when something fails.
For developers building applications with LLMs, understanding constrained decoding helps troubleshoot unstable output formats. For anyone who wants to grasp how LLMs work, this game offers a low-barrier entry point. At the end of the video, the author invites viewers to try it themselves and share their impressions.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.