Ultrafast Goes Live: GPT-6 Astra Inference Speed Gets a 7x Boost

OpenAI's Ultrafast tier makes GPT-6 Astra generate tokens 7x faster than standard, without sacrificing intelligence.
OpenAI has launched Ultrafast, a new inference tier for GPT-6 Astra, rolling out simultaneously across the API, ChatGPT Work, and Codex. Official figures show token generation speeds over 7x faster than the Standard Tier and 4x faster than the Fast Tier, with OpenAI emphasizing that full model intelligence is preserved rather than traded away for speed. A racing game sprite-generation demo illustrated the practical value for real-time use cases. Key questions around pricing, consistency across task types, and independent benchmarks for the "no intelligence loss" claim remain publicly unanswered.
OpenAI has launched a new inference tier called Ultrafast for GPT-6 Astra, now available across the API, ChatGPT Work, and Codex. The headline feature is simple — speed — but what it actually addresses is a long-standing tension in large model applications: the trade-off between speed and intelligence.
Just How Fast Is Ultrafast?
According to official demos, Ultrafast generates tokens more than 7 times faster than the Standard Tier and more than 4 times faster than the Fast Tier in API scenarios. This means developers calling the same model can now choose their inference tier based on latency requirements, with Ultrafast sitting at the top of the speed hierarchy.
For applications that rely on streaming output, real-time interaction, or high-concurrency requests, a 7x throughput improvement isn't just a numerical upgrade — it's a variable that could fundamentally reshape product design. Many use cases have historically been forced into compromise: either sacrifice model capability for speed, or tolerate slower generation to preserve intelligence. Ultrafast is designed to break that binary choice.
Large model inference performance is typically measured by two metrics: TTFT (Time To First Token) and TPS (Tokens Per Second). TTFT determines how "responsive" the system feels to the user, while TPS determines the total time to generate long outputs. The "7x faster" claim primarily refers to TPS — that is, throughput during the generation phase — and doesn't necessarily imply an equivalent reduction in TTFT. For real-time interactive scenarios, both metrics matter: even if subsequent generation is blazing fast, a high first-token latency will still leave users feeling like they're waiting. Developers evaluating whether Ultrafast suits their application should distinguish between these two dimensions, rather than relying solely on the aggregate throughput multiplier.
A Live Generation Demo: Outputs Flying Out Mid-Run
OpenAI used a racing game as its showcase for Ultrafast's value: a developer wants to dynamically generate sprites during gameplay — things like "generate a pelican riding a bicycle" on the fly.
The most telling moment in the demo: while a standard generation request is still running in the background, the Ultrafast request has already crossed the finish line. This "generate while running" capability is a concrete illustration of what low-latency inference means in real engineering — content generation is no longer a blocking step that requires waiting, but something that can be embedded into a real-time loop.
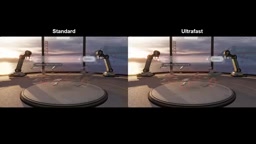
For latency-sensitive scenarios like game development, real-time content creation, and interactive applications, this kind of instant generation opens up significant possibilities. Developers can place model calls inside game loops, user interaction flows, or pipelines requiring rapid feedback — without worrying that generation will slow down the overall experience.
Speed and Intelligence Are No Longer Mutually Exclusive
Ultrafast's positioning is clear: it's not a smaller, less capable but faster model. It's an inference-level acceleration of the same GPT-6 Astra. OpenAI explicitly states that developers previously had to trade off between speed and intelligence — and that "now you can have both."
If that claim holds up, it's significant. Conventional methods for speeding up large models — distillation, quantization, context pruning — almost always come at the cost of capability. Ultrafast's emphasis on dramatically improving speed while preserving the full intelligence of GPT-6 Astra suggests the gains come from inference architecture, hardware scheduling, or service-layer optimization rather than model capability reduction.
Traditional large model inference acceleration techniques fall into a few main categories: model distillation (training smaller models from larger ones, trading parameters for speed), quantization (reducing weight precision from FP32 to INT8 or lower), Speculative Decoding (using a smaller draft model to predict token sequences, then batch-verifying with the larger model), and hardware-level operator fusion (merging redundant operations in the compute graph on GPUs/TPUs). The first two methods almost inevitably introduce some capability loss, while Speculative Decoding and operator fusion can theoretically improve throughput without modifying model weights. Although OpenAI hasn't disclosed Ultrafast's specific technical approach, the "no intelligence trade-off" positioning aligns more closely with Speculative Decoding or service-layer scheduling optimization — methods that make the same model weights "run more efficiently" rather than trading capability for speed. Understanding this context helps evaluate the technical credibility of Ultrafast's "no intelligence loss" claim.
Simultaneous Coverage Across Three Product Lines
Ultrafast launches across three major product lines at once: the API, ChatGPT Work, and Codex. This simultaneous rollout signals that this is not a limited experiment, but a general capability upgrade targeting different user groups.
- API: Aimed at developers, where the choice of speed tier directly affects application architecture and cost structure.
- ChatGPT Work: Aimed at enterprise collaboration, where faster responses improve efficiency in day-to-day work and knowledge processing.
- Codex: Aimed at code generation, where low latency is especially critical for the programming assistant experience — the less you wait, the smoother your development flow.
Questions Worth Asking
It's worth noting that the publicly available information so far focuses primarily on speed metrics and demo results. Several key questions remain unanswered: How does Ultrafast's pricing compare to other tiers? Does the 7x acceleration hold consistently across all task types and context lengths? And is the "no intelligence loss" claim backed by independent benchmark results?
For teams considering deploying Ultrafast in production, speed is just one factor. Cost, stability, and real-world quality under actual load all need to be validated. Until that data is available, the official demos are better understood as a capability showcase rather than a definitive performance guarantee.
That said, the direction Ultrafast points toward is still worth recognizing: making top-tier model response speeds match their intelligence level is becoming the next competitive frontier in large model services.
Related articles

Gemini 4 Argon Hands-On: AI Builds Board Games, Constructs Temples, and Trains Robots Autonomously
Gemini 4 Argon hands-on roundup: AI autonomously builds a desk racetrack and temple in Blender, writes a ray tracing engine, trains a humanoid robot to sink 7 shots, plus API pricing and developer access.

The Magic Octagonal Coin: Why Only 9% of People Can Predict Its Flip?
Only 9% of people can correctly predict the Magic Octagon coin flip. This article explains its spatial rotation mechanism, common cognitive pitfalls, and a new hypothesis based on Relevance Theory, exploring the limits of human spatial reasoning.

Sam Altman: AI Is Entering the Era of Scientific Discovery — Math Breakthroughs Will Replicate in Biology and Energy
Sam Altman says AI is entering the era of scientific discovery — math breakthroughs will replicate in biology, materials science, and energy to help develop new drugs and energy sources.