vLLM Integrates Chord Kernel: Up to 2.15x Inference Speedup for Kimi K2.x
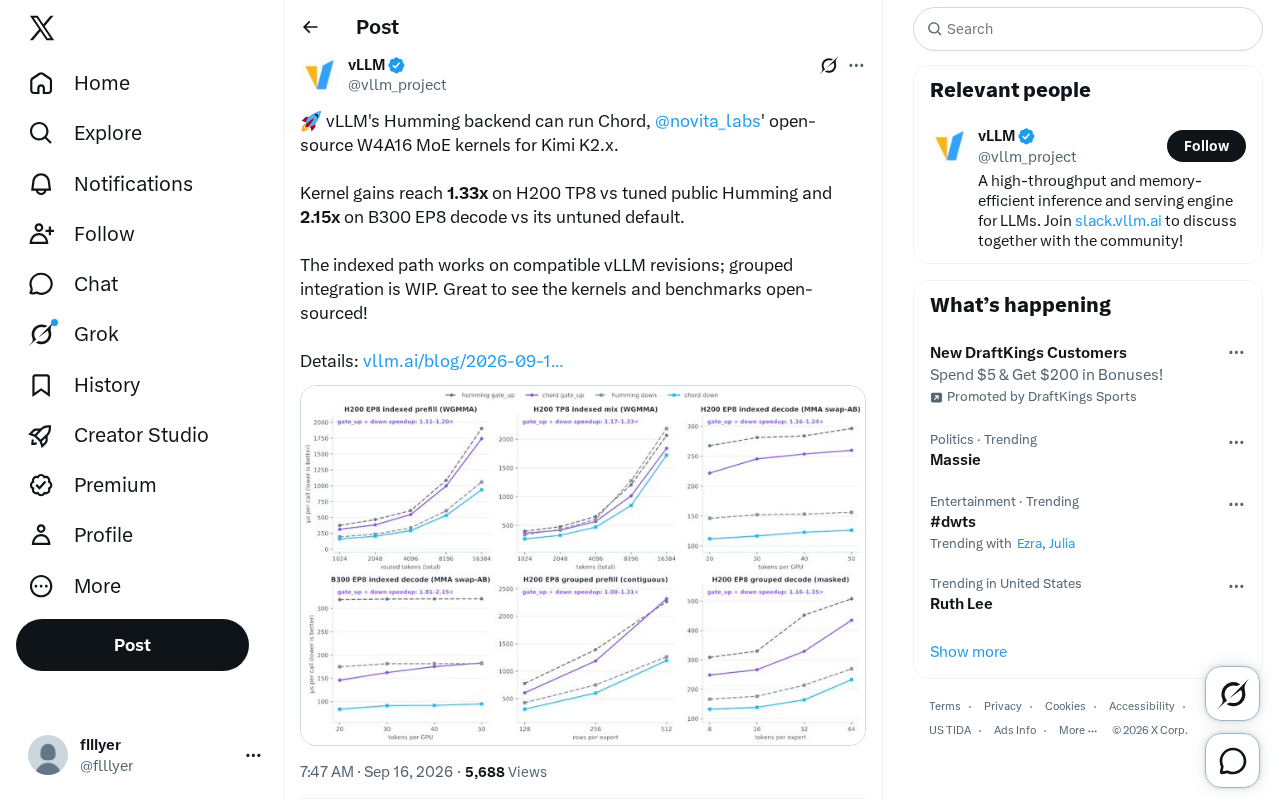
vLLM integrates Chord W4A16 MoE kernels for up to 2.15x faster Kimi K2.x inference on H200/B300.
Novita Labs' open-source Chord kernels — a suite of W4A16 quantization inference kernels designed for large-scale MoE models like Kimi K2.x — have been integrated into vLLM's Humming backend. Benchmarks show 1.33x kernel speedup on H200 TP8 over the tuned public Humming release, and up to 2.15x speedup on B300 EP8 decoding over the default implementation. The indexed path is already available on compatible vLLM versions, while grouped integration is still in development. Both kernels and benchmarks are open-sourced, providing a reproducible engineering reference for W4A16 quantization combined with expert parallelism.
vLLM Adds Chord Kernel Support
vLLM's Humming backend can now run Chord — an open-source W4A16 MoE kernel suite from Novita Labs, specifically optimized for the Kimi K2.x model family. This development marks a meaningful step forward for the open-source community in achieving efficient inference on large-scale MoE (Mixture of Experts) models.
For teams running massive MoE models like Kimi K2.x, inference cost and throughput efficiency have always been core bottlenecks. Chord's W4A16 quantization kernels (weights at 4-bit, activations at 16-bit) significantly reduce memory footprint and improve computational efficiency while preserving accuracy. Its integration into the mainstream vLLM inference stack means more users can benefit directly.
W4A16 quantization is a mixed-precision quantization strategy: model weights are stored as 4-bit integers, while activation values during inference are kept at 16-bit floating-point precision. The logic behind this asymmetric design is that weights are static after loading and can tolerate more aggressive compression, whereas activations change dynamically during the forward pass, so maintaining higher precision helps reduce accumulated error. Compared to full FP16 inference, W4A16 can reduce model memory usage by roughly 50–60%, while achieving near-FP16 compute throughput on modern GPUs through specialized CUDA kernels. MoE (Mixture of Experts) architecture is the other key context here: MoE models consist of a large number of "expert" sub-networks, with only a small subset activated per inference pass — total parameter count is enormous, but computational load is relatively manageable. Kimi K2.x is a massive-scale model built on this architecture. The challenge of applying W4A16 quantization to MoE models lies in co-optimizing the sparse expert routing patterns with the memory access patterns of quantization kernels — which is precisely what Chord is designed to address.
Kernel Performance: Measured Gains on H200 and B300
The published benchmark numbers show impressive speedups. On H200 TP8 (8-way tensor parallelism), Chord delivers a 1.33x kernel performance improvement over the tuned public Humming release.
Even more notable is the B300 EP8 (8-way expert parallelism) decoding scenario, where the speedup reaches 2.15x over the untuned default implementation. This figure demonstrates that optimized MoE kernels can unlock significantly more performance headroom on the expert-parallel decoding path — and decoding latency is one of the most sensitive metrics for interactive inference and online serving.
It's worth noting the baseline context: on H200, the comparison is against the "tuned public Humming" release, while on B300 it's against the "untuned default implementation." The 2.15x gain therefore reflects both Chord's own optimizations and the headroom left by the default configuration — interpretation should be tailored to your specific use case.
Tensor Parallelism (TP) and Expert Parallelism (EP) are two primary distributed inference strategies for MoE models, each with a different optimization focus. Tensor parallelism splits individual matrix operations across multiple GPUs for synchronized execution, which helps reduce per-operation latency but carries higher communication overhead. Expert parallelism assigns different expert sub-networks to different devices, where each GPU hosts only a subset of experts and tokens are routed between devices according to the routing decision — this approach is especially effective during the decoding phase, where token generation is sequential, batch sizes are small, and expert parallelism makes better use of multi-GPU resources. The 2.15x speedup in the B300 EP8 decoding scenario was achieved on this expert-parallel path, reflecting Chord's targeted optimizations for sparse expert activation and cross-device communication.
Integration Status: Indexed Path Available, Grouped Still in Progress
As things stand, the indexed path is already available on compatible vLLM versions — users on the corresponding vLLM revision can enable it right away. The grouped integration is still a work in progress (WIP) and not yet fully ready.
This phased rollout approach is common in open-source inference framework development: deliver the well-validated, compatibility-confirmed path first, then gradually fill in more complex integration modes. For users who want to try it immediately, the first step is verifying that your vLLM version is on the compatibility list.
In MoE inference kernels, indexed and grouped refer to two different ways of organizing expert computation. The indexed path processes experts one at a time based on routing results — relatively straightforward to implement and suitable for validating correctness and baseline performance. The grouped path batches together all tokens routed to the same expert and processes them as a unified batch, making fuller use of the GPU's batched matrix multiply capabilities and typically yielding better throughput under high concurrency — but it's significantly more complex to implement, requiring careful handling of dynamic batch sizes and memory alignment. The current sequencing — indexed first, grouped to follow — reflects a sound engineering philosophy of "get it working, then make it fast."
The Significance of Open Source
The open-sourcing of the Chord kernels along with accompanying benchmarks is an equally important part of this development. The implementation details of W4A16 MoE kernels typically involve extensive low-level hardware-specific optimizations. Making these kernels available together with reproducible benchmarks enables the community to verify performance claims, reuse optimization techniques, and accelerate adaptation across different hardware and model configurations.
For Kimi K2.x users, this means being able to deploy efficient quantized inference services on mainstream accelerators like H200 and B300 at lower cost. For the broader MoE ecosystem, Novita Labs' open-source release provides a reproducible engineering reference for the "quantization + expert parallelism" combination.
For more technical details, refer to the official release documentation.
Related articles
Gemini 3.5 Transcribe: Transcription Tools Are Becoming Content Understanding Engines
Google's Gemini 3.5 Transcribe supports 85+ languages, timestamps, and up to 3-speaker diarization, plus key point and sentiment recognition — marking a shift from archiving to content understanding.
AI and Data Centers Take Center Stage in U.S. Midterms: Vox Breaks Down Five Key Issues
Vox's midterm election breakdown: Trump's historic low approval, Israel dividing Democrats, AI and data center anxiety crossing party lines, affordability politics, and election security concerns.
Which AI Model Writes Better Fiction? A Head-to-Head Plot Generation Showdown Across 5 Models
Head-to-head test of DeepSeek, GLM, Qwen, Gemini, and Claude on fiction plot generation. GLM leads in story logic; Claude and Gemini shine in prose quality.