Warning: Why Developers Should Run Away from the Financial AI Track
The barrier to financial AI isn't algorithms—it's the structural costs of compliance, data, liability, and long-cycle commercialization.
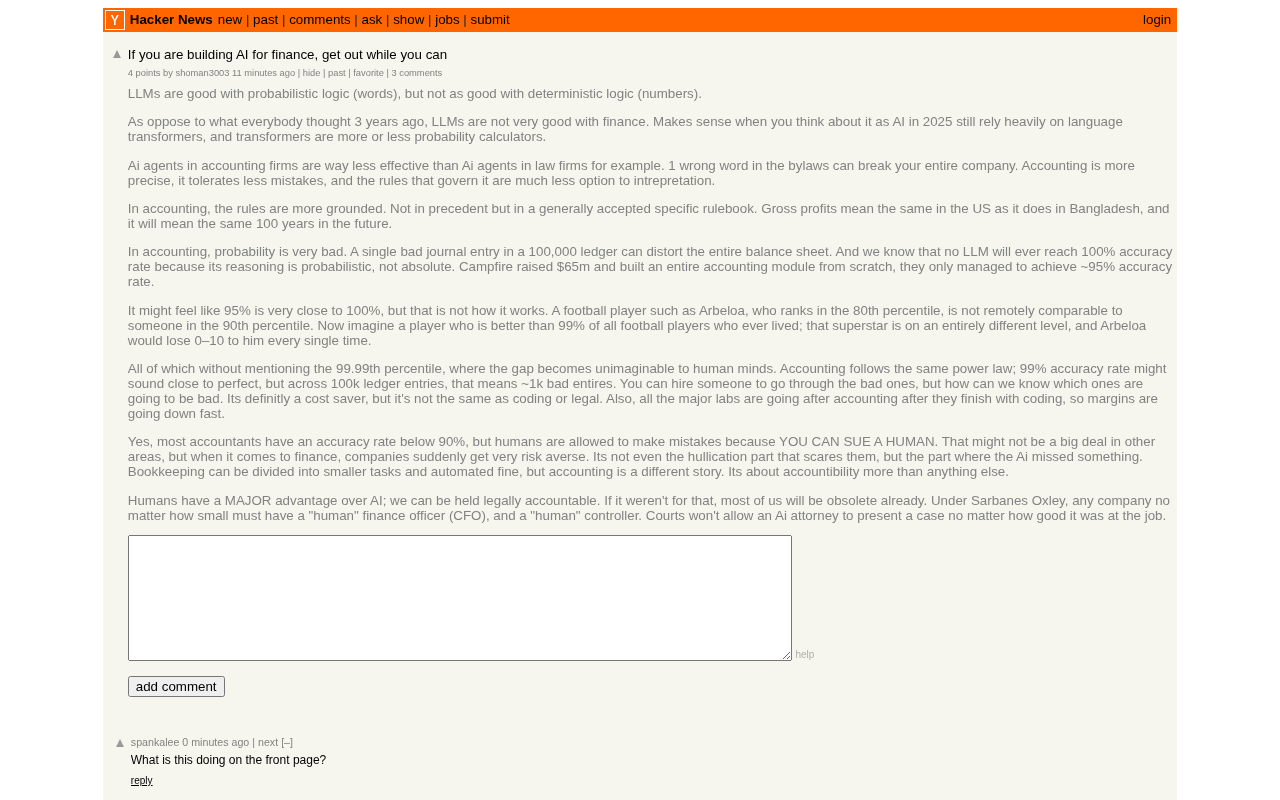
Starting from a low-engagement but provocatively titled Hacker News post, this article breaks down the structural risks of financial AI startups. The core argument: the real barrier isn't model development capability but four dimensions—regulatory compliance complexity and inconsistent cross-border rules drive up costs; high-quality financial data is highly concentrated and non-stationary, making models prone to failure in real scenarios; liability is ambiguous when AI participates in credit and anti-fraud decisions, potentially exposing developers to compensation beyond their technical scope; large financial institutions have long procurement cycles and prefer building in-house teams, limiting commercialization space for third-party AI companies. The conclusion: "get out while you can" isn't a rigorous judgment, but entrants must first answer three questions about compliance endurance, data channels, and risk-bearing.
A Harsh Warning from Hacker News
On Hacker News, a post with only 4 upvotes and 1 comment threw out a highly provocative title: "If you are building AI for finance, get out while you can." The title itself offers no technical details or data, yet it precisely hits a sensitive nerve in the current AI startup boom: the financial industry is seen as one of the most valuable scenarios for AI deployment, but it is also one of the most trap-dense domains.
The post's extremely low engagement suggests it did not spark widespread discussion, but that doesn't mean the topic lacks value. On the contrary, such "low-score, high-information-density" titles often come from the genuine frustration of frontline practitioners. Combining the current state of financial AI, we can break down several structural risks worth watching out for.
The Deep Waters of Financial AI Compliance
The financial industry is far more heavily regulated than most fields. From algorithm interpretability requirements to model risk management guidelines, regulators are tightening their scrutiny of AI systems. A model that performs excellently in the lab must pass multiple hurdles—model validation, stress testing, audit trails, data privacy—before entering real trading or credit decision processes.
What's trickier is that rules differ across jurisdictions. Cross-border financial AI products need to satisfy multiple compliance frameworks simultaneously, which directly drives up development and maintenance costs. For startup teams, the speed of building a compliance team often can't keep up with product iteration, ultimately creating a stalemate where "technology runs fast while compliance drags its feet."
Model Risk Management (MRM) is a core framework in financial regulation, explicitly required by the Federal Reserve's SR 11-7 guidance and relevant Basel Committee documents. MRM requires financial institutions to conduct independent validation, continuous monitoring, and periodic review of every model, and to establish a complete model inventory and documentation system. For AI systems, this means not only proving model performance on training sets but also explaining assumptions, limitations, failure boundaries, and human intervention mechanisms. Many regulators also require "challenger model" comparison testing—continuously challenging the main model's outputs with alternative models. This process creates significant friction for AI teams accustomed to rapid iteration: a single model update may trigger a full re-validation cycle lasting months.
Algorithm interpretability in financial scenarios is not an academic concept but a regulatory necessity. Article 22 of the EU's General Data Protection Regulation (GDPR) grants individuals the right to explanation for automated decisions, with credit and insurance pricing being particularly sensitive. In practice, regulators typically accept post-hoc explanation tools like SHAP and LIME, but for black-box models such as deep neural networks, the sufficiency of explanations remains controversial. Some regulators prefer requiring inherently interpretable models (e.g., logistic regression, decision trees), which directly limits the deployment space for complex models.
Data Barriers Are Far Higher Than Imagined
Financial data appears abundant, but high-quality, labelable, and legally usable data is highly concentrated in the hands of a few institutions. Banks and exchanges won't easily open up core data, and public datasets often suffer from poor timeliness and narrow coverage. There is a huge gap between the data developers obtain and the data distribution in production environments, causing models to frequently fail in real-world scenarios.
Moreover, financial data exhibits strong non-stationarity. Changes in market structure, regulatory policy adjustments, and macroeconomic shocks can quickly invalidate historical patterns. A strategy that performs well in backtesting may collapse entirely after going live due to a single policy change. This uncertainty places extremely high demands on AI engineering and means that continuous data procurement and labeling costs are hard to compress.
Non-stationarity is a core concept in time series analysis, referring to changes in the statistical properties of data (mean, variance, autocorrelation structure, etc.) over time. Non-stationarity in financial markets is particularly pronounced: volatility clustering, structural breaks, and regime shifts are all common manifestations. This means the generalization assumption of models trained on historical data—that training and test distributions are identical—often fails to hold in financial scenarios. Common approaches to handling non-stationarity include rolling window retraining, online learning, ensemble methods, and explicit regime detection modules, but all of these increase engineering complexity and operational costs.
Distribution Shift has a special meaning in finance: because data is highly sensitive, developers often can only use desensitized, sampled, or synthetic data, which may have systematic differences in joint distribution from production data. Even if a model performs well in offline evaluation, it may rapidly degrade after deployment due to drift in feature marginal distributions or feature-label relationships. Monitoring distribution shift and establishing automated alerting and rollback mechanisms is an indispensable part of financial AI engineering.
The Gray Zone of Model Risk and Liability
When AI systems participate in credit approval, anti-fraud, or investment advice, who bears responsibility when erroneous decisions occur? The developer, the financial institution, or the model vendor? The current legal framework has yet to clearly define this. This liability ambiguity puts developers in a weak position during contract negotiations and may even force them to bear compensation liabilities beyond their technical scope.
The financial industry has extremely low tolerance for errors. A single model misjudgment can cause direct financial losses or regulatory penalties, and the black-box nature of AI systems makes post-hoc attribution difficult. This combination of "high error cost + low interpretability" is one of the core contradictions facing financial AI developers.
Algorithmic Accountability has been a hot topic in regulatory discussions in recent years. The EU's Artificial Intelligence Act classifies AI applications in finance as high-risk, requiring providers to establish risk management systems, technical documentation, human oversight mechanisms, and post-deployment monitoring processes. Regarding liability allocation, the Act distinguishes obligations between "providers" and "deployers," but in financial scenarios the boundary is often blurred: third-party AI vendors provide models, financial institutions embed them into decision processes, and when errors occur, regulatory penalties typically fall on licensed institutions, which then transfer some liability to vendors through contracts. This liability chain transmission mechanism is a risk point that AI companies must carefully evaluate when signing contracts with financial clients.
Black-box attribution difficulties also involve operational risk capital provisioning. Under the Basel framework, operational risk includes losses arising from internal processes, personnel, systems, or external events. When AI system errors cause losses, financial institutions need to classify them and provision capital, and model inexplicability increases the difficulty of loss attribution and capital measurement, indirectly driving up institutional compliance costs. This is also one of the deeper reasons why large financial institutions are cautious about black-box models.
The Invisible Ceiling of Commercialization Paths
Financial AI customers are mainly large institutions such as banks, insurers, and brokerages. These clients have long procurement cycles, complex decision chains, and stringent qualification requirements for vendors. Even startups with strong technology are often shut out due to lack of industry credentials. That said, large financial institutions prefer to build their own AI teams or acquire mature targets, continuously squeezing the space left for third-party AI companies.
On pricing, financial clients often directly link AI value assessment to quantifiable business metric improvements—how much the bad debt rate drops, how much approval efficiency increases. This results-oriented pricing model lengthens the return cycle on technology investment, putting pressure on cash flow management.
Conclusion: It's Not That You Can't Do It—You Need to Recognize the Cost
The original post's "get out while you can" is more of an emotional warning than a rigorous industry judgment. Financial AI is not without opportunities, but its barriers lie not in the algorithms themselves but in compliance capability, data acquisition capability, liability-bearing capability, and long-cycle commercialization endurance. If a team only has model development capabilities but lacks basic respect for financial industry rules, then pivoting to other tracks early is indeed the more rational choice.
For developers still persisting, it's recommended to answer three questions before committing: Can you endure a compliance approval cycle of 12+ months? Do you have stable data acquisition channels? Are you willing to bear clear legal and financial responsibility for model errors? If the answer is no, the original post's advice may be worth taking seriously.
Related articles

A Single Prompt Triggers a Global PHP Security Storm: Is AI a Savior or a Hidden Risk?
A single AI prompt triggered a global PHP security crisis affecting Wikipedia and the Internet Archive. This article reviews the incident, analyzes the OpenAI-Amazon controversy, and explores the security paradox of lowered vulnerability discovery barriers in the AI era and developer response strategies.

When AI Is Taken Away: How Reliance on Shortcuts Undermines Your Problem-Solving Resilience
A study of 1,222 people found that after using AI to answer questions, once AI was removed, people gave up on more problems than a control group that never used AI. The article analyzes the impact of AI reliance on learning resilience and metacognition, and explores design implications for AI learning tools.

Carta and NewView Partner to Let Startup Employees Cash Out Equity Early
Carta and NewView Capital partner to simplify startup tender offers, helping employees sell equity early. Analysis of the mechanism, liquidity pain points, and impact.