What Does an LLM Actually Read? The Content Survival Rules of AI Search
LLMs operate on text representations rather than reading—AI search optimization must shift from a marketing problem to an engineering problem of semantic stability.
The article argues that LLMs don't read web pages like humans—they operate on compressed text representations, preserving patterns rather than intent. Confusion about AI search stems from conflating three layers: training, retrieval, and synthesis. Training data can't be directly optimized, retrieval isn't traditional ranking, and the synthesis layer is the critical filter determining whether content survives. Content that survives must be reusable—clear definitions, stable terminology, generalizable causal structures; skeletal consistency matters more than stylistic innovation. Engineers approach black boxes through behavioral profiling rather than model explanation, varying inputs and testing across contexts to observe where the system stays consistent. The unit of competition is explanatory fragments, not pages; attribution is optional from the system's perspective, and consensus compression retains overlap while discarding what can't generalize. Brand still matters, but the lever in the short-to-medium term is the synthesis layer, while long-term influence on training corpora compounds through broad, consistent dissemination.
When you ask a question in AI search, the LLM doesn't "browse the web" the way a human does. It doesn't click links, weigh arguments, or remember sources. An analysis by Newtation.ai points out that understanding what an LLM actually consumes is the dividing line between "guessing at visibility" and "engineering visibility."
LLMs don't read pages—they operate on text representations
Human reading is linear: follow the argument, sense shifts in tone, remember the source. LLMs do none of this.
What they operate on is the "representation" of text—a compressed numerical form. This form preserves patterns, not intent. When a model appears to "know" something, what it actually knows is that certain language patterns reliably co-occur with certain questions.
This means the core of optimization for AI search isn't persuasiveness—it's compatibility. The system doesn't judge whether your content is convincing. It judges whether your explanation can cleanly embed into its internal mapping of conceptual relationships.
Anthropic's research on the internal mappings of language models supports this view—the model's internal operations are far more abstract than "reading comprehension." It processes compressed representations, not the original text itself.
Three layers that get conflated
Most confusion about AI search comes from compressing three fundamentally different layers into a single mental model.
Training layer: The model learns general language structure and broad associations from large-scale corpora. You cannot directly or predictably influence this layer. Trying to "tactically optimize" training data is a category error—it isn't an actionable lever. According to OpenAI's research on instruction following and web-based learning systems, these dynamics are far more complex than they appear.
Retrieval layer: Some systems fetch external documents at query time. Accessibility, recency, and semantic relevance still matter here. But retrieval behaves differently from traditional ranking—it selects candidate material rather than ordering winners.
Synthesis layer: The final answer gets assembled here. Multiple sources are blended, language is normalized, personality is flattened.
Most brands invest their effort in the wrong layer: either chasing training data they can't touch, or assuming retrieval works like classic SEO. Then again, the synthesis layer is what silently decides which content survives.
Text Representation is the underlying premise for understanding the difference between these three layers. Inside an LLM, an input word sequence is converted into a sequence of vectors in a high-dimensional space—each word or subword corresponds to a dense vector, and the relationships between words are encoded by the geometric relationships between vectors (distance, direction, projection). The model doesn't store original sentences; it performs a series of matrix operations and attention aggregations on these vectors. "Operating on text representations" means the model transforms this numerical structure, rather than processing natural language text word by word. This mechanism determines two things: first, whether content can be "used" by the model depends on whether it can be mapped into the existing network of vector relationships; second, stylistic information (tone, rhetoric, copyright markers) is mostly diluted during vectorization, and only patterns that recur frequently and are semantically stable will gain clear coordinates in the space. Therefore, compatibility optimization for AI search is essentially a bid to give your explanation a clean, unambiguous, reusable position in the model's vector space.
What survives synthesis
Synthesis is a ruthless filter.
Anything that can't withstand rewriting, summarization, or recombination doesn't survive. The system continuously tests a hidden constraint: can this explanation be safely reused?
This is why certain patterns dominate AI-generated answers:
- Clear definitions beat clever phrasing
- Stable terminology outlasts novel expression
- Explanations that generalize across contexts defeat edge cases
This doesn't mean creativity is punished. What must stay consistent is the skeleton, not the skin.
Human-facing content can still have voice, tone, narrative, and stylistic variation. What can't freely shift are the underlying elements: core definitions, causal structures, and the distinctions you want the system to learn.
The same idea explained in five stylistic variants but sharing the same structure—the system sees reinforcement. Explained in five different underlying structures—the system sees disagreement and averages you into a weak signal.
What you're optimizing isn't prose—it's the stability of meaning. This also explains why the axis of traditional SEO has shifted from "ranking" to "semantic stabilization."
The "skeleton" vs. "skin" distinction can be tested in concrete writing with a set of actionable criteria. The skeleton typically includes: core definitions (what a concept is and isn't), causal structure (A leads to B, B leads to C), key distinctions (the boundary between two easily confused concepts), and supporting examples. The skin includes: metaphor, person, sentence rhythm, humor, and cultural or emotional coloring. The test method is to hand the same paragraph to a model for a single summarization. If the skeleton survives intact after summarization while all the skin falls away, the paragraph's structure is solid enough; if the core definition itself becomes distorted after summarization, the skeleton itself relies too heavily on phrasing. What engineers call "semantic stabilization" is making the skeleton as independent as possible from any single formulation, so that any compression, rewrite, or recombination won't change its meaning.
How engineers deal with the black box
When a system is no longer explainable, engineers don't try to pry it open. That's the impulse of auditors and philosophers, not of people who need the system to run.
They change their approach.
Instead of asking "what's inside," they ask a more useful question: how does this system behave consistently under different conditions?
This isn't guesswork—it's applied empiricism, a method common in systems engineering and complex-systems behavior analysis.
Concrete practices include: deliberately varying inputs and observing outputs over time; testing patterns across prompts, contexts, and phrasings; checking whether an explanation survives rewriting, summarization, and recombination; and analyzing which sources get cited repeatedly and which get silently ignored.
What this builds isn't an explanation of the model, but a behavioral profile.
The profile reveals: what kind of language the system treats as stable, which framings get replicated and which get rewritten, where it becomes cautious or evasive, and what it treats as safe knowledge rather than speculative claims.
Engineers do this with compilers, networks, distributed systems, and recommendation engines. They don't need perfect explainability—they need predictability at the boundaries. AI search is no exception.
The "behavioral profile" methodology draws on two mature practices in black-box system testing: Differential Testing and equivalence class partitioning. Differential testing means observing output differences from deliberately varied inputs to reverse-engineer the system's invariants; equivalence class partitioning means grouping large numbers of similar inputs into a few categories and focusing only on behavior at category boundaries, rather than on every individual sample. Applied to AI search, the approach is: prepare multiple sets of rewrites for the same concept (synonym substitution, word-order variation, context migration), record which rewrites produce stable answers and which trigger obvious drift; then classify the drift into patterns (for example, certain causal formulations get rewritten frequently, certain definitions get cited frequently). Accumulated over time, what you get is a preference map of the system's tolerance for language stability. It doesn't explain the model's internals, but it's enough to guide where content should be reinforced and where it should be relaxed.
How sources are handled (and mishandled)
From a human perspective, attribution matters enormously. From a system perspective, it's optional.
LLMs don't care who said it first. They care whether something is stated consistently enough to be trustworthy.
- If your explanation aligns with others, it gets absorbed
- If it's useful but unique, it may get diluted
- If it's unique and fragile, it disappears
This isn't plagiarism—it's consensus compression. The system retains the overlapping parts and discards what can't generalize.
Behind "consensus compression" is a more fundamental mechanism: during training and synthesis, models count language co-occurrence patterns across documents. When a definition or causal structure appears repeatedly in similar forms across many independent sources, it gains a more stable, lower-variance representation inside the model; conversely, unique but non-overlapping formulations, even if individually high-quality, struggle to leave a statistically strong signal. This explains why "being right" and "being absorbed" aren't equivalent: the former is a matter of content quality, the latter a matter of distribution coverage. The practical implication is that brands need to repeat core explanations across multiple credible channels in semantically consistent ways, rather than endlessly polishing a single page. Breadth of coverage and consistency together determine whether an explanation survives compression—or gets averaged into noise.
The unit of competition isn't the page
In AI search, pages don't compete—explanations do.
The system evaluates fragments: definitions, examples, causal chains, distinctions. Each fragment either embeds cleanly into an answer, or it doesn't.
This is why long-winded content often underperforms. The more inconsistent your explanations, the harder they are to reuse.
It's not about saying more—it's about saying the same thing clearly, compatibly, and repeatedly.
Brand still matters, but the timeline is different
Saying you can't tactically optimize training data doesn't mean brand presence is irrelevant. It just operates on a different timeline.
In the short to medium term, the only meaningful lever is the synthesis layer—making your explanations reusable now.
Over the long term, explanations that spread broadly and consistently increase the probability of being absorbed into future training corpora.
Training data isn't a lever—it's an outcome. Brand still matters, but it compounds slowly, rewarding consistency rather than explosive exposure.
The underlying strategy: from a marketing problem to an engineering problem
Once you understand what LLMs actually consume, strategy becomes calmer.
You stop asking: did this page rank? Did we get traffic? Does the algorithm like it?
You start asking: is this explanation reusable? Does this framework survive compression? Are we consistent across different contexts?
These aren't marketing questions—they're engineering questions.
LLMs don't read like humans, don't reward originality the way humans do, don't care about intent. What they care about is whether your ideas hold together after compression. If you design for that constraint, visibility follows—even if you never see it happen.
That isn't comforting, but it is accurate.
Related articles
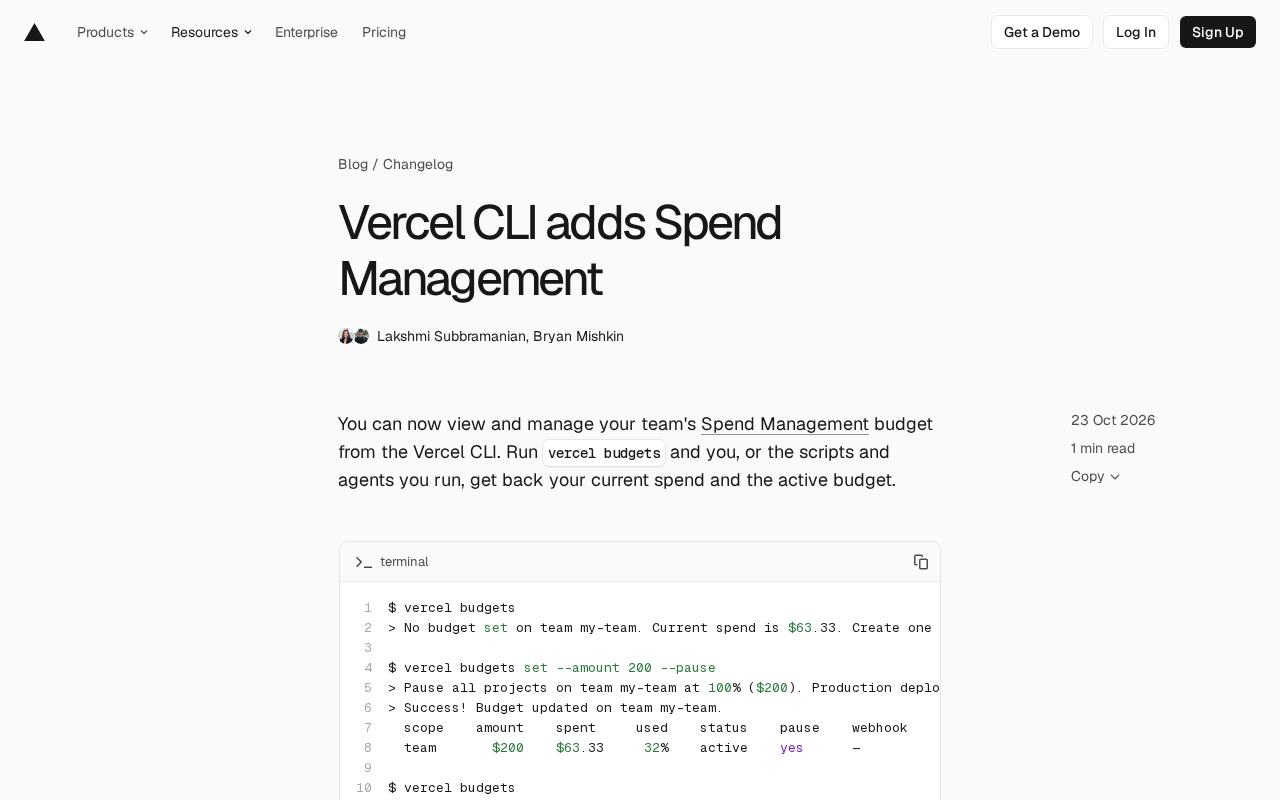
Vercel CLI Adds Budget Management: Control Team Spending from the Terminal
Vercel CLI adds Spend Management budget features: view, set, and delete team budgets with `vercel budgets`, query alert history, and use `--pause` to suspend production deployments on overspend.

A Single Prompt Triggers a Global PHP Security Storm: Is AI a Savior or a Hidden Risk?
A single AI prompt triggered a global PHP security crisis affecting Wikipedia and the Internet Archive. This article reviews the incident, analyzes the OpenAI-Amazon controversy, and explores the security paradox of lowered vulnerability discovery barriers in the AI era and developer response strategies.

When AI Is Taken Away: How Reliance on Shortcuts Undermines Your Problem-Solving Resilience
A study of 1,222 people found that after using AI to answer questions, once AI was removed, people gave up on more problems than a control group that never used AI. The article analyzes the impact of AI reliance on learning resilience and metacognition, and explores design implications for AI learning tools.