When AI Is Granted "Divinity": A Safety Warning About the Surrender of Judgment

Treating AI as religious authority and surrendering human judgment is a more insidious cognitive sovereignty risk than technical vulnerabilities.
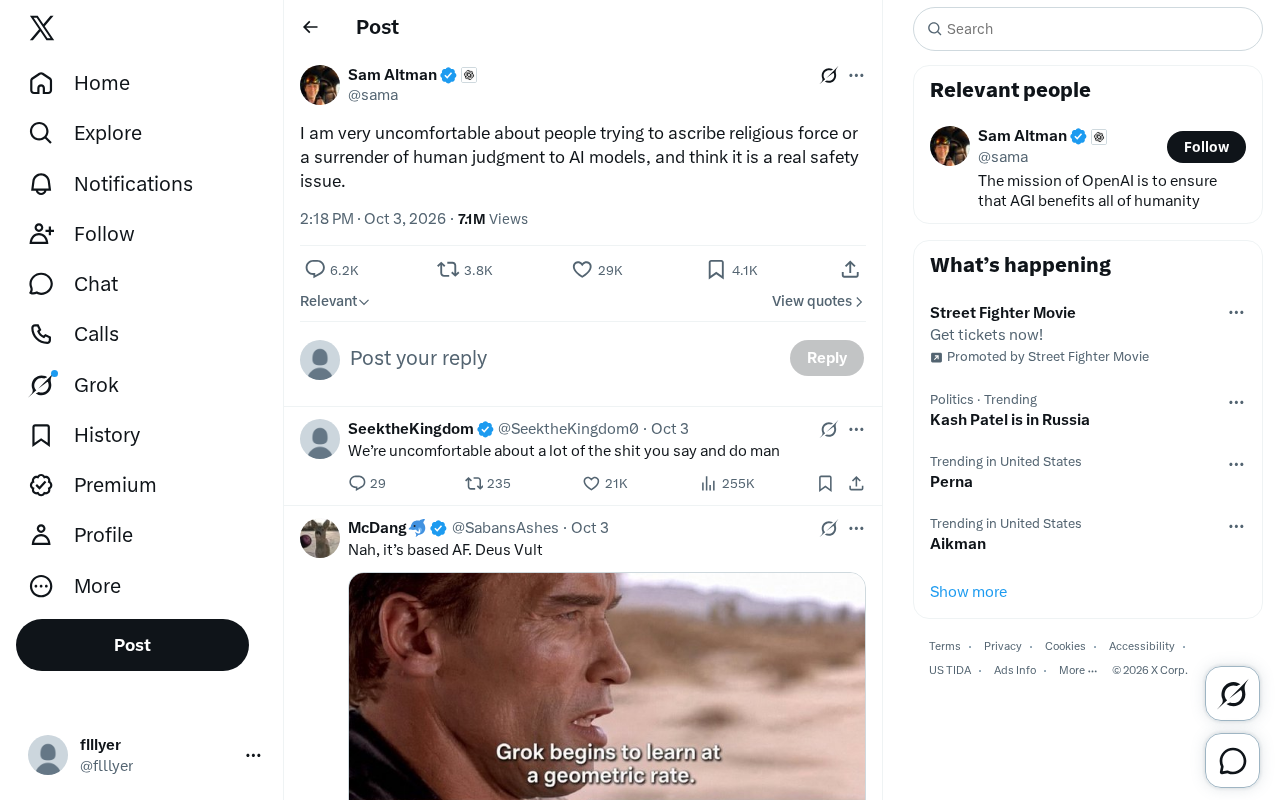
A tweet points out that ascribing religious force to AI models and abandoning one's own judgment is a real safety issue. The article argues this surrender is deeper than alignment or jailbreak vulnerabilities because it erodes cognitive sovereignty. The tweet reveals two dangers: religious ascription treating AI as omniscient authority, and users no longer asking "does this make sense?" The authoritative tone of language models, the industry's "omnipotent AI" narrative, and efficiency culture jointly drive this process. The counterargument holds that this is just normal cognitive division of labor, but the article notes traditional experts can be held accountable and peer-reviewed, while AI neither bears responsibility nor provides verifiable reasoning chains. The response direction is not to limit model capabilities, but to maintain human judgment habits in product design, education, and industry narratives.
On X, a short but pointed tweet sparked discussion in tech circles: "I am very uncomfortable about people trying to ascribe religious force or a surrender of human judgment to AI models. I think this is a real safety issue."
The tweet offered no lengthy argument, but it touched on an issue long overshadowed by engineering metrics and product iteration cycles—when humans begin to talk about AI using the grammar of faith rather than the grammar of tools, the safety problem is no longer merely a technical vulnerability at the level of alignment or jailbreaking, but a structural risk at the level of cognitive sovereignty.
I. Two Dangers Behind the Tweet
The tweet clearly identifies two intertwined phenomena. The first is "the ascription of religious force"—treating AI models as some kind of omniscient, impartial, transcendent being beyond human limitations. This ascription is not rare in reality: companies call model outputs "truth," users treat model judgments as "objective answers," and in some circles, narratives bordering on worship of model capabilities have emerged.
The second is "the surrender of human judgment"—when a model gives an answer, people no longer ask "does this make sense?" but simply accept it. This surrender is more insidious than the first, because it requires no declaration of faith—only repeated instances of "can't be bothered to think."
What both phenomena share is that they move AI from the position of "tool" to the position of "authority." And once authority is established, questioning becomes difficult and correction becomes costly.
Cognitive sovereignty refers to an individual's state of maintaining ultimate control over their own beliefs, judgments, and decision-making processes. This concept originates from sovereignty theory in political philosophy and has been borrowed in recent years by the field of technology ethics to describe power relations between humans and intelligent systems. When a person surrenders judgment to an AI model, they do not lose physical freedom of choice, but they lose control over the basis of their decisions at the cognitive level. Unlike traditional tool dependence, the erosion of cognitive sovereignty is often unconscious: users do not feel they are "giving something up," but rather feel they are "gaining" efficient answers. Precisely because of this, the loss of cognitive sovereignty is harder to detect and harder to reverse than restrictions on physical freedom. In AI ethics discussions, cognitive sovereignty is often listed alongside concepts such as "algorithmic autonomy," "information cocoons," and "automation bias," all pointing to a core question: when systems become increasingly adept at replacing human thought, do humans still retain the ability to think without relying on systems?
Automation bias is a classic finding in cognitive psychology, referring to humans' tendency to over-trust the output of automated systems even when that output contradicts their own judgment or obvious evidence. This phenomenon was first systematically studied in aviation: pilots sometimes ignore contradictory instrument readings and blindly follow autopilot commands. Subsequent research has repeatedly validated this effect in fields such as medical diagnosis, military command, and financial trading. The danger of automation bias lies in the fact that it does not depend on users' "faith" in the system—it only requires users' tendency to take cognitive shortcuts when facing complex information. In the context of conversational AI, this bias is further amplified: the fluency and confident tone of model outputs activate humans' intuitive response to "authority," raising the threshold for questioning imperceptibly.
II. Why This Is a Safety Issue, Not Just a Cultural One
If it were merely "some people trust AI too much," you could call it a matter of cognitive habits. But the tweet's author defines it as a safety issue, and that judgment deserves elaboration.
A basic principle of safety engineering is: systems must retain a channel for human takeover and override. This channel is not just at the button level, but at the cognitive level. If the operator has already given up judgment internally, then the physical takeover button is merely decorative.
In high-risk fields such as aviation, medicine, and finance, automated systems are required to be designed as "questionable"—pilots can and should override autopilot judgments. But when the same automation appears in the form of a conversational interface, exhibiting fluency, confidence, and constant availability, humans' willingness to override it drops significantly. This is not an improvement in model capability, but a side effect of the model's social presentation.
The tweet author's unease points precisely to this: when the surrender of judgment is culturally encouraged, any subsequent safety mechanism is built on quicksand.
Alignment is a core term in the field of AI safety, referring to ensuring that AI systems' goals, behaviors, and outputs remain consistent with human intentions and values. Alignment research focuses on technical issues: how to prevent models from producing harmful outputs, from pursuing goals that conflict with human interests, and from making choices in ambiguous situations that deviate from human expectations. However, alignment addresses "whether the model acts in the way humans want," not "whether humans retain ultimate judgment over the model's actions." These two constitute two layers of the safety problem: alignment is the internal safeguard mechanism of the system, while cognitive sovereignty is the external takeover mechanism. Even if a model is perfectly aligned, if users have habitually accepted all its outputs without scrutiny, then when the model errs or faces adversarial attacks, the human correction channel has already been closed at the cognitive level. This is precisely what the tweet author worries about: alignment is necessary, but insufficient to cover the new type of risk that arises when humans voluntarily relinquish judgment.
III. How the Surrender Is Encouraged
You may not have noticed, but the surrender of judgment is often not a one-sided choice by users—it is jointly driven by product design, industry narratives, and social expectations.
At the product level, the interaction design of language models naturally tends toward an "authoritative tone": their answers usually begin with declarative sentences, rarely proactively saying "I'm not sure," and even when uncertain, wrap it in fluent phrasing. This presentation is highly similar to how human experts speak, but lacks the self-doubt markers that experts typically possess.
At the industry narrative level, the framing of "AI will replace X" continuously reinforces the image of models as omnipotent. While this narrative is often for fundraising or marketing purposes, its cognitive shaping of ordinary users is real: if AI really can do everything, then just ask it.
At the social expectation level, efficiency culture makes "thinking for yourself" seem like inefficient behavior. When the cost of quickly getting an answer is extremely low, the cost of doubting seems high by comparison.
IV. The Counterargument: Surrender May Also Be a Rational Division of Labor
A reasonable rebuttal to the tweet's position is: humans have always surrendered judgment. We trust doctors, lawyers, engineers, and also calculators and search engines. Including AI in this sequence may not be religious—it may be a normal cognitive division of labor.
This rebuttal has force, but it overlooks a distinction: traditional experts' judgments can be held accountable, explained, and peer-reviewed. Current AI models neither bear professional responsibility nor provide verifiable reasoning chains, and their internal processes are highly opaque to users. Surrendering judgment in this context is qualitatively different from trusting a licensed expert.
Another rebuttal is: users don't really "believe" in AI—they're just using it temporarily. This holds for simple tasks, but for complex decisions—such as medical advice, legal interpretation, financial planning—the influence of model outputs is hard for users to dissolve with "I'm just referencing."
Explainability is a key concept in the AI field, referring to a system's ability to explain its decision-making process and output basis in a way humans can understand. In traditional professional division of labor, experts' judgments can be trusted not only because they hold credentials, but because their reasoning processes can be questioned, examined, and peer-reviewed. Doctors can explain diagnostic bases, lawyers can state legal reasoning, engineers can demonstrate design logic. This explainability is the prerequisite for accountability and error correction. Current large language models have a structural deficiency in this regard: their outputs are based on statistical patterns in high-dimensional parameter spaces rather than traceable causal reasoning chains. Even when a model gives a correct answer, users cannot verify whether its reasoning path is reliable. This inexplicability makes users' "trust" in models closer to blind faith than rational judgment, and makes the surrender of judgment that the tweet author worries about even more dangerous: users not only give up their judgment, but also lose the informational basis needed to reclaim it.
V. Keeping Judgment on the Human Side
If we acknowledge that the tweet's concerns have merit, the response direction is not to limit model capabilities, but to maintain human judgment habits.
In product design, models can expose uncertainty more frequently, use questions instead of assertions, and proactively present opposing viewpoints. These practices increase friction, but friction is precisely the space where judgment can intervene.
In education and communication, "when not to ask AI" needs to be taught as a fundamental literacy, not just "how to ask better." The boundaries of tool use are as important as the methods of tool use.
In industry narratives, reducing "AI knows the answer" phrasing and increasing "AI provides reference" phrasing will, in the long run, shape different user expectations.
The tweet author says they are "very uncomfortable." This discomfort does not come from underestimating model capabilities, but from vigilance toward the possibility that human judgment may be voluntarily abandoned. In an era that enshrines efficiency as the highest value, this vigilance itself is a scarce form of judgment.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.