When Is an AI Feature 'Ready to Ship'? A Decision Problem No One Talks About

An ASU grad student's Reddit survey exposes the technical, process, and organizational hurdles behind shipping AI features.
An ASU graduate student posted a Reddit survey focused on three questions: what metrics teams check before launching an AI feature, where the biggest friction in evaluation lies, and who approves the testing tool budget. The article uses this as a lens to show why AI feature validation is far harder than traditional software — probabilistic outputs break binary pass/fail logic, forcing teams to rely on eval sets, A/B tests, and human review. Key friction points include lack of shared standards for "good enough," high costs of building test data, and the near-impossibility of quantifying subjective quality. Most overlooked is the organizational barrier of budget approval: when evaluation tooling is seen as non-value-generating spend, teams default to gut-feel launches — which is where AI product risk truly originates.
A Grad Student's Very Real Question
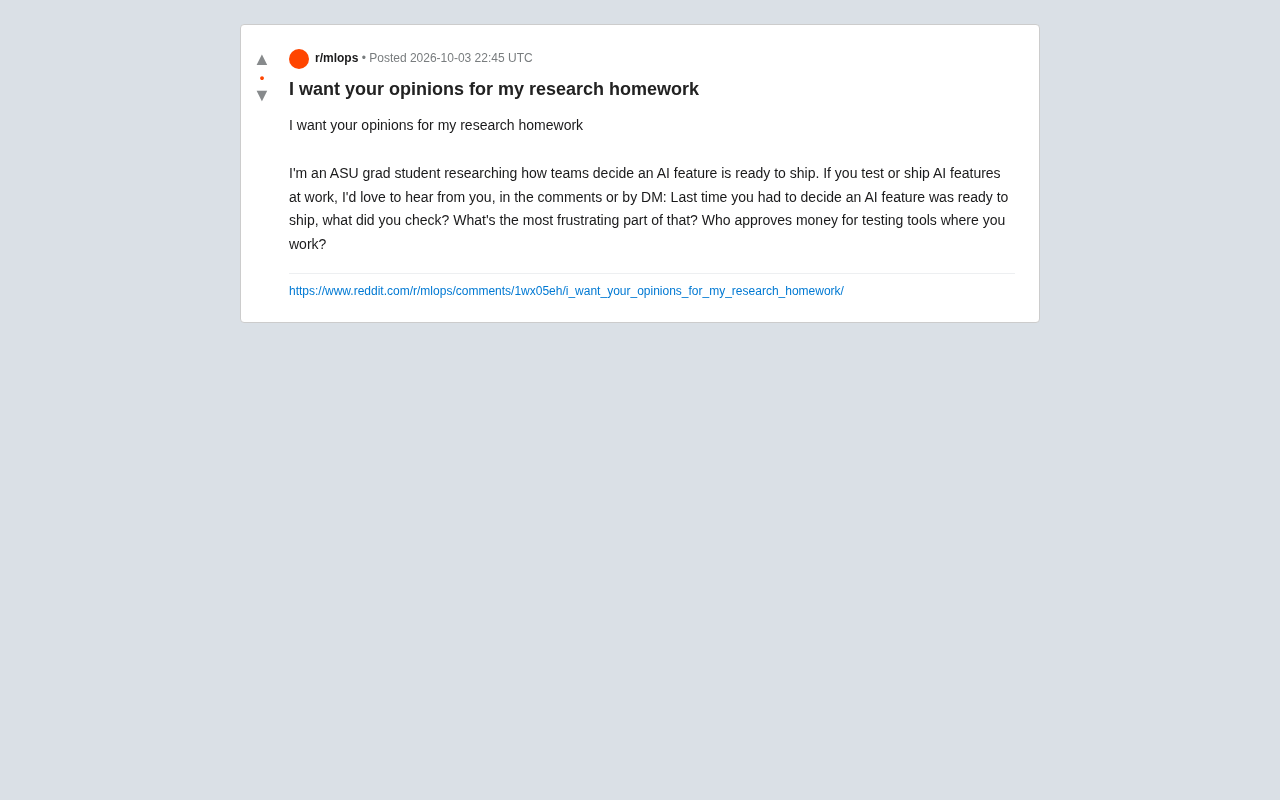
A graduate student at Arizona State University (ASU) posted a survey on Reddit with a deceptively simple premise that cuts right to an industry pain point: how do teams actually decide that an AI feature is "ready to release"?
He asked three core questions: What metrics did you check the last time you decided an AI feature was ready to go live? What part of that process gave you the most headaches? And who at your company approves the budget for testing tools?
These three questions connect a hidden chain that's often overlooked in AI product delivery: technical acceptance criteria, friction in the evaluation process, and resource approval authority. The original post is still an open-ended call for responses without conclusions — but the questions alone are enough to provoke serious reflection among practitioners.
Why "Is This AI Feature Ready?" Is Such a Hard Question
The bar for shipping a traditional software feature is relatively clear: the feature works, it passes test cases, there are no blocking bugs — then it goes through the release process. But judging whether an AI feature is "ready" is far more ambiguous.
A feature powered by a large language model might perform brilliantly 90% of the time, yet produce wildly off-base responses in the remaining 10% of long-tail scenarios. What accuracy rate is "good enough"? What level of hallucination is acceptable? There are no universal answers — it usually depends on the fault tolerance of the specific business context.
Even trickier is the probabilistic, non-deterministic nature of AI outputs. The same input can yield different results at different times, which breaks the traditional binary pass/fail judgment. Teams are forced to rely on eval sets, manual spot-checks, A/B testing, and similar methods to build confidence — and the coverage and representativeness of those methods become new variables in themselves.
An eval set is the core tool for AI feature acceptance testing. At its heart, it's a carefully constructed set of input samples along with their expected outputs or evaluation criteria, used to systematically measure how a model performs on a specific task. A high-quality eval set needs to cover typical scenarios, edge cases, and potentially high-risk inputs (such as adversarial prompts or rare linguistic expressions). The problem is that eval sets carry inherent "representativeness bias" — they can only cover situations the builders anticipated, while real user behavior often far exceeds those expectations. This creates a paradox: a model that performs perfectly on the eval set can still fail in real traffic after launch. Continuously iterating and maintaining eval sets is just as important as iterating on the model itself — yet this work remains chronically underfunded in many teams.
Typical Friction Points in the Evaluation Process
The original post specifically asked about "the most painful parts" — and that's precisely where the most authentic real-world struggle lies.
Drawing on common industry experience, the typical friction points in AI feature acceptance testing fall into several categories. First is lack of consensus on evaluation criteria: product, engineering, and business stakeholders all have different ideas of what "good enough" means, and teams often find themselves arguing about metric thresholds the night before a planned launch. Second is the high cost of building test data: constructing an eval set that truly represents the real-user distribution requires significant human annotation effort and ongoing maintenance — many teams abandon this step halfway through.
Third is the difficulty of quantifying subjective quality. For generative AI, whether content is "good" often involves subjective dimensions like tone, style, and relevance that are hard to capture in a single number. Teams ultimately fall back on human review — which is slow, expensive, and hard to standardize.
The Overlooked Question of "Who Approves the Budget"
The third question — "who approves the budget for testing tools" — seems minor but points to a deep organizational tension.
High-quality AI evaluation often requires a dedicated toolchain: evaluation platforms, annotation services, monitoring systems, and even paid third-party judge models (LLM-as-a-judge). These are real costs. But in many organizations, "testing" and "evaluation" are seen as expenditures that don't generate direct value — they sit low in approval queues with long sign-off chains.
The fact that the researcher included budget approval authority in his study shows he understands that rigorous AI feature validation isn't just a technical problem — it's a resource allocation and organizational power problem. When no one is willing to pay for evaluation tooling, teams often end up launching based on gut feel that "it seems about right" — and that's exactly where the risk originates.
LLM-as-a-judge is an automated evaluation approach that has gained traction in recent years: using a more capable or specially fine-tuned language model to score or adjudicate the outputs of the model being tested, in place of human reviewers. This approach scales far better than human evaluation and can cover large volumes of samples at low cost — making it especially well-suited for assessing open-ended generative tasks like summarization, dialogue, and code explanation. However, it introduces new risks: the judge model's own preferences, stylistic tendencies, and known limitations seep into the scores, causing evaluation results to carry systematic bias. Additionally, using a commercial model as a judge raises data privacy concerns and incurs extra API costs — which is precisely why budget approval for this approach often meets resistance.
What This Means for Practitioners
This research is still in the data-gathering phase, but the framework it raises is worth every AI product team turning inward to examine.
If you're responsible for delivering AI features, consider running an internal audit with these three questions: Do we have clear, quantifiable, cross-stakeholder-approved launch criteria? Where is the biggest friction in our evaluation process, and has it been systematically addressed? Do we have the budget and the mechanisms to continuously invest in building evaluation capabilities?
Moving from "ship by gut feel" to "ship with evidence" is an important marker of AI engineering maturity. The ASU grad student's questions may matter a great deal more than they appear to.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.