When Will Mistral Release New Models? Community Speculation and Current Analysis
Community speculates on Mistral's next move as the company goes quiet and adds GLM to its platform.
A Reddit post has sparked community discussion about Mistral's direction after a prolonged period without new model releases. Known for Mistral 7B and the Mixtral MoE series, the company's slower release cadence has raised questions, especially after its platform began offering Zhipu AI's GLM models. Speculation points to possible strategy shifts — from enriching the model lineup to transitioning toward a platform-as-a-service model — but no official new release timeline has been confirmed.
A Question from the Community
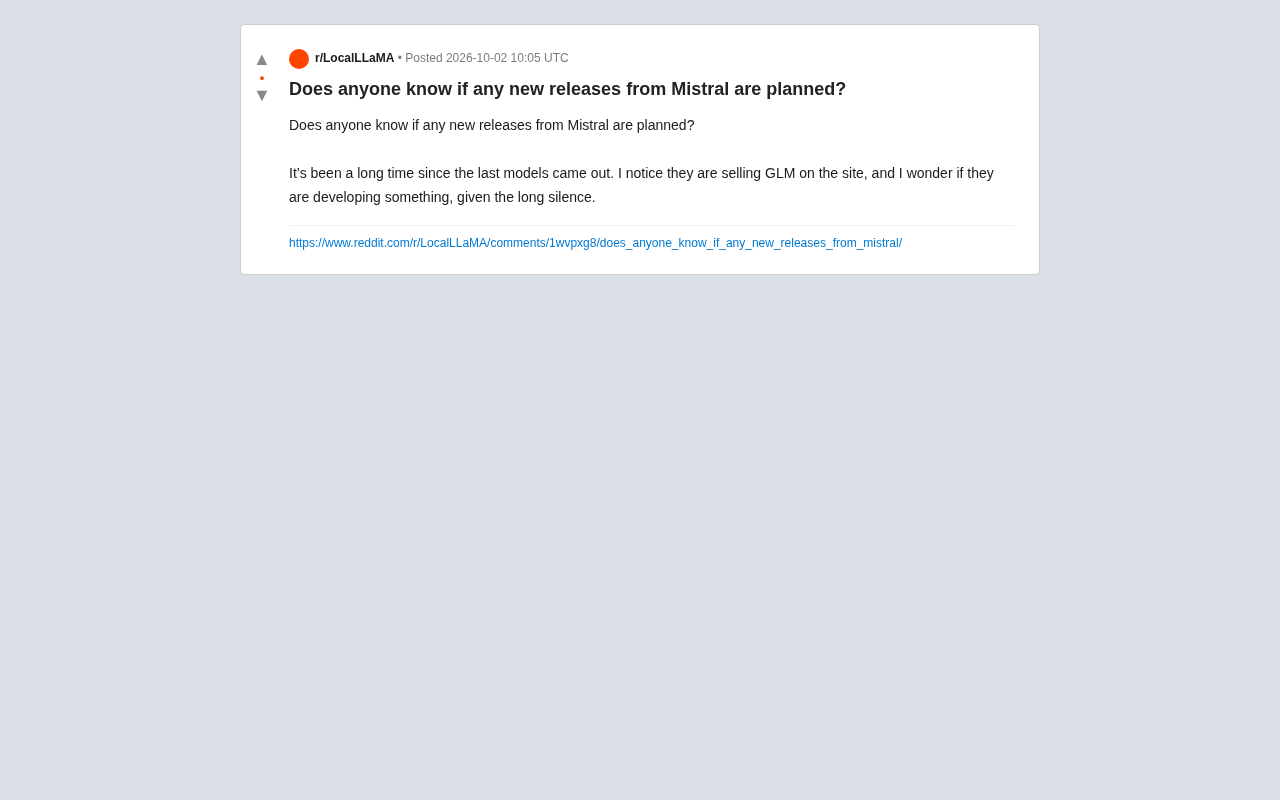
Recently, a post about Mistral sparked discussion in Reddit's AI community. The original poster raised a question that many open-source model enthusiasts have been thinking about: does Mistral have any plans to release new models?
The post read: "It's been a long time since the last batch of models was released. I noticed they're selling GLM on their website, and I'm wondering if they're working on something new behind this long period of silence."
This seemingly simple question reflects the open-source LLM community's ongoing attention to the moves of Mistral, the French AI company. As one of Europe's most closely watched AI startups, every model update from Mistral tends to generate widespread discussion.
Why the Community Cares About Mistral's Silence
Mistral has built a strong reputation in the open-source community through its efficient and openly available model series. From the early Mistral 7B to the subsequent Mixtral series of Mixture-of-Experts (MoE) architecture models, the company was once known for its high-frequency, high-quality release cadence — a significant open-source counterpart to Meta's Llama series.
Precisely because of this, when the release pace slowed down and a prolonged "silent period" emerged, the community naturally began to speculate. The poster astutely noticed one detail: Mistral's platform began offering GLM (a model series from Zhipu AI). This observation led to speculation that Mistral may be adjusting its product strategy, or preparing for the launch of a new generation of in-house models.
It should be noted that the post itself is a community inquiry and does not include any confirmed information from Mistral officially. No authoritative source has confirmed a specific timeline for new model releases.
Mixtral and the Mixture-of-Experts (MoE) Architecture is essential context for understanding Mistral's technical direction. MoE is a model architecture whose core idea is to divide the model into multiple "expert" sub-networks, activating only a subset during each inference pass. This allows the model to maintain a large total parameter count (raising its capability ceiling) while significantly reducing actual computational costs. Mixtral 8x7B, released by Mistral in late 2023, is a landmark example: despite having roughly 46B total parameters, it activates only about 13B per inference pass. It outperformed Meta's Llama 2 70B on multiple benchmarks while being far cheaper to run than dense models of comparable parameter size. This achievement greatly boosted Mistral's reputation in the open-source community, which is precisely why the subsequent slowdown in releases has drawn so much attention.
Reading the Tea Leaves: Possible Directions
The post's mention of "selling GLM on their site" is worth reflecting on. If Mistral is indeed integrating third-party models into its services, this could reflect several strategic considerations:
First, enriching the product portfolio. By offering a diverse range of model options, the platform can serve different user needs without being entirely dependent on its own release schedule.
Second, bridging a transition period. When in-house models are not yet ready, incorporating established external models can help maintain the platform's competitiveness and user retention.
Third, exploring a new business model. Transitioning from a pure model publisher toward a platform that offers model-as-a-service is a path many AI companies are currently pursuing.
That said, these remain speculations based on publicly observable phenomena. For the open-source community, the real concern is: will Mistral continue its tradition of releasing open-weight models that users can freely use?
GLM (General Language Model) is a large language model series jointly developed by Tsinghua University and Zhipu AI, with flagship products including ChatGLM and the GLM-4 series. GLM excels at bilingual Chinese-English tasks and uses a distinctive autoregressive blank-filling pre-training objective, which differs from the mainstream GPT-style purely autoregressive architecture. Mistral's choice to integrate GLM rather than other models may be related to GLM's strengths in multilingual support and flexible commercial licensing. For Mistral, a European company, integrating high-quality models from different regions also helps its platform cover a broader range of users in global competition.
Advice for Open-Source Model Users
While waiting for official clarity, users following Mistral's developments can keep an eye on a few things:
Prioritize official channels. Authoritative information about model releases should come from Mistral's official blog, GitHub repository, and social media announcements. Community speculation is for reference only.
Take a measured view of release cycles. Training and fine-tuning large models requires substantial time and compute investment. Longer gaps between releases are not uncommon in the industry — silence doesn't necessarily mean stagnation.
Evaluate existing alternatives. If you have immediate needs, the existing Mistral models as well as other open-source options (such as Llama, Qwen, GLM, etc.) are all worth evaluating. There's no need to put projects on hold while waiting for a new release.
Conclusion
This Reddit post captures the genuine expectations the open-source community has for Mistral, and reflects users' desire for a continued supply of high-quality open models. As a representative force in Europe's AI ecosystem, Mistral's next moves will undoubtedly be closely watched. Until the company provides an official response, everything about new model releases remains in the realm of community speculation — and following official channels remains the best way to get accurate information.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.