Why Can't the M5 Ultra's 512GB RAM Run Fast? Bandwidth Is the Real AI Performance Bottleneck

M5 Ultra's memory quadrupled but bandwidth barely doubled — it fits giant models but can't run them fast enough.
Apple's M5 Ultra brings 512GB of unified memory to a personal workstation for the first time, making massive local models theoretically possible. But its 1.2TB/s memory bandwidth grew less than 2× compared to the M5 Max, far behind the 4× capacity increase. Since LLM Decode is memory bandwidth-bound — token speed ≈ bandwidth ÷ model size — the largest models that need 512GB are also the most bottlenecked by 1.2TB/s. Long-context KV Cache growth worsens the slowdown, and the NVIDIA RTX Pro 6000's 1.792TB/s outpaces it despite having only 96GB VRAM. A true Ultra-worthy design would need at least 2.4TB/s bandwidth.
Apple's new M5 Ultra has thrown out a spec that makes local AI enthusiasts' hearts race — 512GB of unified memory. Models in the 200B, 300B, or even larger range, which simply couldn't fit on a single GPU before, can now potentially be loaded directly into a Mac Studio. But scroll a little further down the spec sheet, and something feels off: the memory bandwidth is only 1.2TB/s.
This article, based on a Bilibili creator's analysis of the M5 Ultra, breaks down a core contradiction — why a machine with a jaw-dropping amount of memory might still feel frustratingly slow when actually running large models.
512GB Is Tempting, But Bandwidth Barely Doubled
The M5 Ultra's most explosive spec isn't its CPU or GPU — it's the 512GB of unified memory. For local AI users, this number means running massive models locally is no longer exclusive to server operators.
The problem lies in how the bandwidth scales by comparison. For reference, the M5 Max with 128GB already delivers 614GB/s of memory bandwidth. The M5 Ultra's memory capacity jumped from 128GB to 512GB — a full 4× increase — yet bandwidth only went from 614GB/s to 1.2TB/s, barely under 2×.
Here's a vivid analogy: Apple built you a warehouse four times larger, then widened the highway leading to it by less than twice. It looks impressive, but when you actually start moving goods, you find the exit is congested. That's exactly what makes the M5 Ultra so frustrating.
What Really Determines LLM Performance Is Bandwidth, Not Capacity
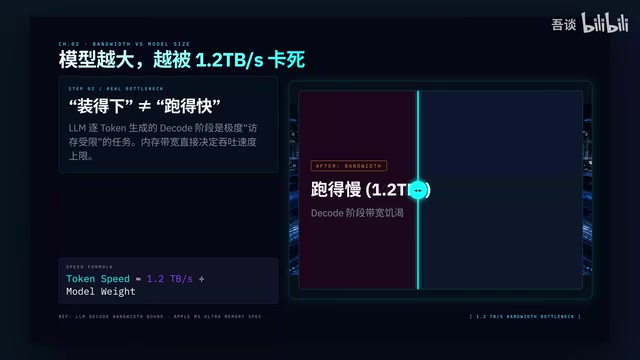
You might ask: isn't 512GB more than enough? The issue is that running large models locally has never been purely about whether the model "fits" — it's about how fast it runs once it's loaded.
For LLM token generation, particularly during the Decode phase of large models, memory bandwidth is often the single most critical bottleneck. A rough but intuitive formula:
Theoretical token speed ≈ Memory bandwidth ÷ Model weight size
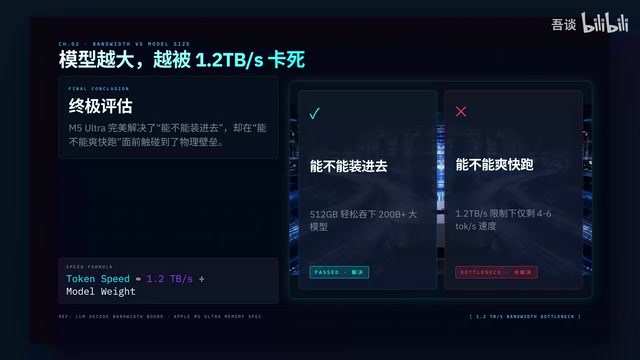
Assume a quantized model weighs 100GB. With M5 Ultra's 1.2TB/s bandwidth, the theoretical speed is around 12 tokens/s. At 200GB, that drops to 6 tokens/s. At 300GB, roughly 4 tokens/s.
Real-world speeds won't match this formula exactly — caching, MTP, Speculative Decoding, KV Cache, and various kernel optimizations all play a role. But the physics don't change: the larger the model, the more data must be moved to generate each token, and the more bandwidth matters.
This relates to two distinct phases of LLM inference: Prefill and Decode. The Prefill phase processes all input tokens at once — it's compute-intensive, and GPU/NPU FLOPS are the primary bottleneck. The Decode phase is autoregressive, generating one token at a time, requiring the full model weights to be read from memory to the compute units for each token — a classic memory bandwidth-intensive operation. In actual conversations, the "typing speed" users perceive is almost entirely determined by Decode efficiency. Since the M5 Ultra's Neural Engine and GPU core count saw proportionally larger compute gains, Prefill speed improves noticeably — but Decode speed is capped by the 1.2TB/s bandwidth ceiling, offering very limited improvement for very large models. This is why "the larger the model, the more prominent the bandwidth bottleneck" — scaling from 30B to 300B parameters means 10× more weight data to move per token.
The Larger the Model, the More Likely It Gets Bottlenecked at 1.2TB/s
Here lies an awkward closed loop. Why would you buy 512GB? Clearly not to run 27B or 32B models — the M5 Max with 128GB already handles those well. People buying a 512GB Ultra are aiming for 100B, 200B, or even larger models.
The irony: the larger the model, the more you need 512GB of capacity — and the more you need it, the more likely you are to get throttled by 1.2TB/s of bandwidth. In other words, the M5 Ultra's strongest use case is precisely where it exposes its biggest weakness most completely. It solves "can it fit?" without truly solving "can it run smoothly once it fits?"
In Long-Context Scenarios, Speed Degrades Even Further
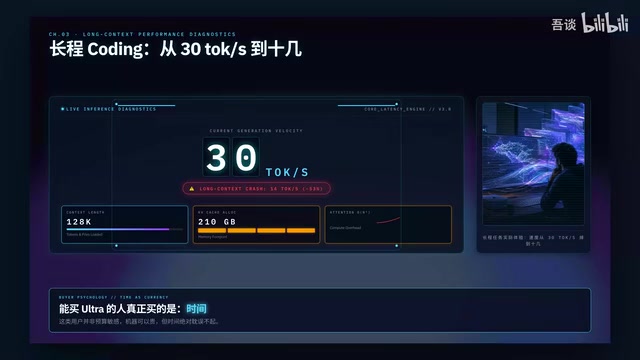
The more practical concern is long contexts. A benchmark showing 30 tokens/s sounds decent, but actually using Claude Code or a Coding Agent on a complex project is a completely different story.
As a project progresses, the context keeps growing — more files read, more conversation history stacked up — KV Cache keeps expanding, Attention overhead climbs, and tool calls become more frequent. A model that runs at 30 tokens/s on short contexts might drop to the teens in a long-running task.
What does that feel like? You spent a fortune on a 512GB Ultra, and when doing actual complex work, the AI is still trickling out words one by one. It's almost absurd — people who can afford an Ultra are rarely budget-sensitive. What they're actually buying is time. They can accept a more expensive machine, but they can't accept paying several times more for less than twice the speed.
KV Cache (Key-Value Cache) is the caching structure in Transformer architectures that stores historical attention computation results. Every token in every layer generates Key and Value vectors that get cached to avoid redundant computation. As context length grows, KV Cache size expands linearly at O(n) — for a model with 128 layers and a large hidden size, a 100K token context can produce a KV Cache occupying tens of gigabytes. More critically, generating each new token requires reading the complete KV Cache to perform Attention computation, meaning long contexts don't just consume memory space — they add additional bandwidth overhead at every generation step. This is exactly why long-running tasks like Claude Code or Coding Agent sessions can cut token speed in half: the cost of loading model weights is fixed, but the KV Cache read overhead accumulates continuously with context length.
Comparison with NVIDIA: A Small Warehouse with a Superhighway
Put the M5 Ultra next to the NVIDIA RTX Pro 6000, and the contrast becomes stark. The Pro 6000 has only 96GB of VRAM — a small warehouse compared to 512GB. But it uses 28Gbps GDDR7, delivering 1.792TB/s of memory bandwidth.
The result is an almost ironic picture: the M5 Ultra has over five times more memory capacity than the Pro 6000, yet only about two-thirds of its bandwidth. One is a small warehouse with a superhighway; the other is a massive warehouse with an ordinary expressway.
If a model fits within 96GB, NVIDIA clearly has the advantage in achieving higher throughput. Apple's edge only becomes real when models exceed 96GB — but once they do, Apple's own bandwidth pressure starts ramping up fast. This is the awkward loop again.
What Bandwidth Would Actually Match 512GB?
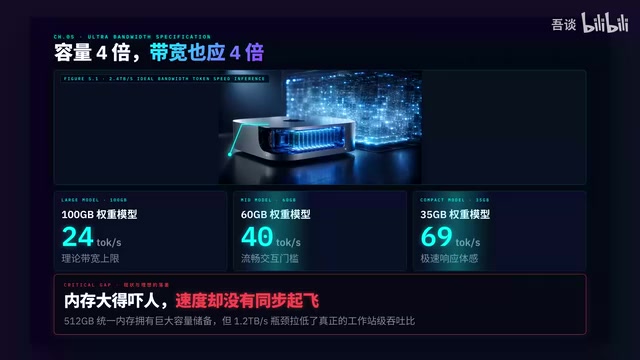
According to the Bilibili creator's estimate, the bandwidth truly worthy of a 512GB Ultra shouldn't be 1.2TB/s — it should be at least 2.4TB/s.
The logic is simple: M5 Max is at 614GB/s. From 614 to ~2400 is roughly 4×, and 128GB to 512GB is also 4×. If capacity quadruples, bandwidth should nearly quadruple too. That would actually be Ultra.
With 2.4TB/s, a 100GB model would theoretically hit ~24 tokens/s, a 60GB model ~40 tokens/s, and a 35GB model nearly 69 tokens/s. Stack MTP and Speculative Decoding on top of that, and 100B–200B-class models would finally have a shot at the interactive speeds you'd expect from a high-end workstation.
MTP (Multi-Token Prediction) and Speculative Decoding are two inference acceleration techniques that can partially work around bandwidth bottlenecks. Speculative Decoding uses a small draft model to rapidly generate candidate token sequences, which the large model then verifies in parallel — increasing the number of tokens produced per memory read to amortize bandwidth costs. MTP allows the model to predict multiple subsequent tokens in a single forward pass. These techniques are most effective when bandwidth is sufficient, but their optimization headroom shrinks when bandwidth is already a hard constraint. For models above 200B, the data movement per forward pass is enormous, and the overhead of verifying draft model outputs scales accordingly — making Speculative Decoding's speedup ratio less favorable than on smaller models. This is why software optimizations alone can't fundamentally solve the M5 Ultra's bandwidth deficiency.
Conclusion: Capacity Leapt a Generation Ahead; Bandwidth Stayed a Generation Behind
The M5 Ultra's real problem isn't that 512GB is useless — on the contrary, 512GB is genuinely valuable. The problem is that Apple pushed capacity to the next generation while leaving bandwidth at roughly a generation and a half ago. That's what makes it so frustrating.
For casual users, it's too expensive. For serious AI professionals, it's not fast enough. The people willing to spend this kind of money aren't asking "can it run?" — they're asking "is it worth it?" When a 512GB Ultra delivers less than 2× the core AI inference speed of a 128GB M5 Max, that gap is going to be hard to ignore.
Here's perhaps the harshest characterization: it may be one of the most capable personal computers for loading large models — and also one of the most likely to mislead buyers into thinking "more memory equals more performance." What truly determines a local AI experience has never been just that impressive 512GB figure. It's the less glamorous number that actually determines speed: 1.2TB/s.
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.