Why Do LLMs Hallucinate? Understanding the Fundamental Reason RAG Exists

LLMs hallucinate because they predict tokens, not facts — RAG fixes this by injecting real context before generation.
LLMs fundamentally predict the next statistically likely token rather than storing or retrieving verifiable facts. This causes them to generate "convincingly wrong" responses — fluent, structured, and confident, yet potentially fabricated. The root issue isn't a lack of intelligence but a lack of proper context and grounding. RAG (Retrieval-Augmented Generation) addresses this by retrieving relevant external information and injecting it into the prompt before generation, anchoring predictions in reliable facts.
When AI Starts Confidently Making Things Up
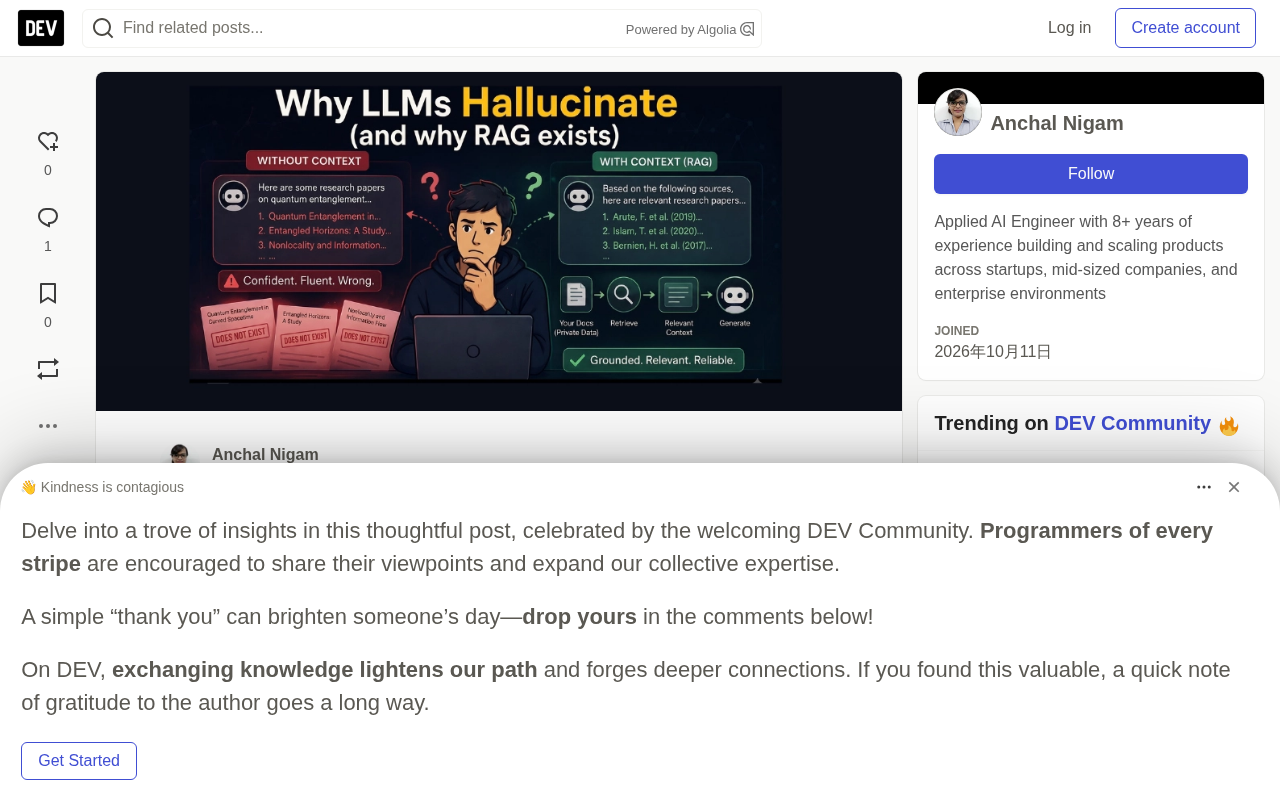
An engineer once shared the moment he first realized large language models (LLMs) couldn't be fully trusted: he asked an LLM to list research papers on a niche topic, and instantly received what looked like an impeccably professional list — paper titles, author names, publication years, even DOI links.
Everything seemed perfectly reasonable: well-structured, academically flavored, delivered with confidence. But when he actually went online to look up these papers, he found that several of them simply didn't exist.
These weren't obvious fabrications or blatant errors. They were convincingly wrong. The titles sounded real, the author names were plausible, and the citation format was completely consistent with academic standards. For engineers, this is a particularly troubling situation — the problem is no longer "the model failed," but rather "the model can't be trusted."
LLMs Don't Store or Retrieve Knowledge Like Humans Do
We often hear things like: "LLMs understand language," "they reason like humans," "they know everything." So when a model generates incorrect content, our instinct is often — maybe the model just isn't advanced enough yet.
But the truth is more unsettling: LLMs don't store or retrieve knowledge the way humans do.
At the most fundamental level, LLMs do one thing — predict the next token. They generate responses based on patterns learned during training and the probability of what most likely comes next in a given context.
This means three critical things:
- They don't inherently verify truth;
- They don't automatically know your data;
- They don't "look up" facts when generating a response.
This distinction explains a lot.
Where Hallucinations Actually Come From
Back to the research paper example. The reason the model's response was so convincing is that during training, it had almost certainly encountered tens of thousands of research papers, academic citations, DOI formats, and author naming conventions.
So even though it didn't truly "know" the answer, it still attempted to generate the statistically most plausible continuation. That's why the fake paper titles sounded real, the invented authors seemed credible, and the nonexistent citations appeared academically correct.
The model was never verifying truth at all. And this is precisely why hallucinations are dangerous — these responses tend to be fluent, well-structured, authoritative, and highly confident. Humans naturally associate "confidence" with "correctness," and over time, misinformation starts to seem believable.
From a technical perspective, hallucination is not an occasional bug — it's an intrinsic property of language model architecture. LLMs learn conditional probability distributions over token sequences during training: "given what came before, what token is most likely next?" There is no separate "fact storage layer" or "knowledge verification module." All of the model's "knowledge" is compressed and blended into billions of neural network parameters. This compression process inevitably causes information distortion and conflation: details from two similar domains may get "remixed" by the model, producing a "synthetic fact" that never existed. More critically, there is no confidence-gating mechanism during generation — the model cannot determine whether it actually "knows" something, so when it hits a knowledge gap, it doesn't stop and say "I'm not sure." It keeps generating the statistically smoothest continuation. This is the fundamental reason why fabricated citations sound so convincing.
The Problem Isn't Intelligence — It's Context
Since LLMs are essentially predicting statistically probable text, how do we get them to generate more accurate answers?
The key insight here is sharp: the model itself hasn't changed — it's still doing the same thing, predicting the next most likely word. So the real problem may not be about intelligence, but about context.
This exposes one of the biggest limitations of today's LLMs. They:
- Don't automatically access real-time information;
- Don't automatically access your company's or private data;
- Can't read your documents unless you explicitly provide them.
Your PDFs, databases, Slack conversations, API endpoints, and internal knowledge are all "invisible" to the model by default. The reason a model generates fake citations is that it has no way to cross-reference authoritative sources while answering — it's making predictions without any factual grounding.
RAG: Give the Model the Right Information Before It Generates
What if, instead of expecting the model to "magically" know everything, we gave it the right information before it started generating?
Here's a fitting analogy: it's like asking a friend about something. If they're going purely from memory, they can only answer based on a vague impression. But if they consult the relevant documents before responding, the quality of the answer changes completely. The friend didn't suddenly get smarter — they just had better context.
This is the core insight:
Better context → better predictions.
When we inject relevant information into the prompt, we change what the model "sees" before predicting the next token, which changes the direction of generation. This isn't some magical new model or a hidden intelligence upgrade — it's a shift at the system design level. This is Retrieval-Augmented Generation, or RAG.
At its core, RAG is simply a smarter approach: use relevant external information to ground the generation process before the model starts predicting.
A typical RAG pipeline consists of two phases: Retrieval and Generation. In the retrieval phase, the system converts the user's question into a vector embedding, performs a semantic similarity search in a pre-built vector database, and identifies the most relevant document chunks. In the generation phase, these retrieved chunks are concatenated into the prompt as "reference material" for the model's response. The model's task is no longer to generate from nothing — it's to summarize and reason based on the provided text. Vector databases (such as Pinecone, Weaviate, and Chroma) are the core infrastructure of a RAG pipeline, responsible for storing and retrieving semantic representations of documents. Context engineering is the higher-level design challenge: how to filter, rank, and truncate retrieved results so they maximally improve answer quality without exceeding the model's context window. Understanding this full pipeline is what reveals why RAG is a systems engineering problem — not simply "plug in a database."
Hallucination Is a Feature of the Mechanism, Not a Bug
LLMs hallucinate not because they're "broken." They hallucinate because they can generate convincing-sounding answers without automatically verifying whether those answers are true.
Until we give LLMs a way to anchor their answers in reliable information, we will keep getting responses that sound right but aren't. This is the fundamental reason RAG exists — and why it has become a core component of modern AI systems.
Once you understand this, technologies like vector databases, retrieval pipelines, and context engineering are no longer a scattered collection of tools. They become a coherent, systematic solution to the fundamental limitations of LLMs.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.