Why Do RAG Chatbots Still Hallucinate? 5 Design Mistakes and How to Fix Them

RAG hallucinations usually come from upstream retrieval flaws—chunking, search, and stale data—not the model.
RAG chatbots hallucinate not because of the generation model, but because of upstream retrieval design. This article covers five recurring mistakes: fixed-length chunking that breaks semantics, vector-only search that loses exact matches, stale and conflicting indexed data, a lack of quantitative evaluation, and models with no way to say 'I don't know.' For each, it offers concrete fixes—structural chunking with heading metadata, hybrid BM25 + vector search with a reranker, storing version and update metadata, building a 30–50 question test set that separates retrieval from generation, and using prompt constraints plus retrieval score thresholds to let models refuse. It closes with a four-step debugging order: confirm the information is indexed, retrieved, ranked high enough, and only then suspect the model.
You built a RAG chatbot. The documents are indexed, the vector database is running fine, and the demo looks great. Then a user asks about the refund policy, and the bot confidently cites a rule that was repealed last year.
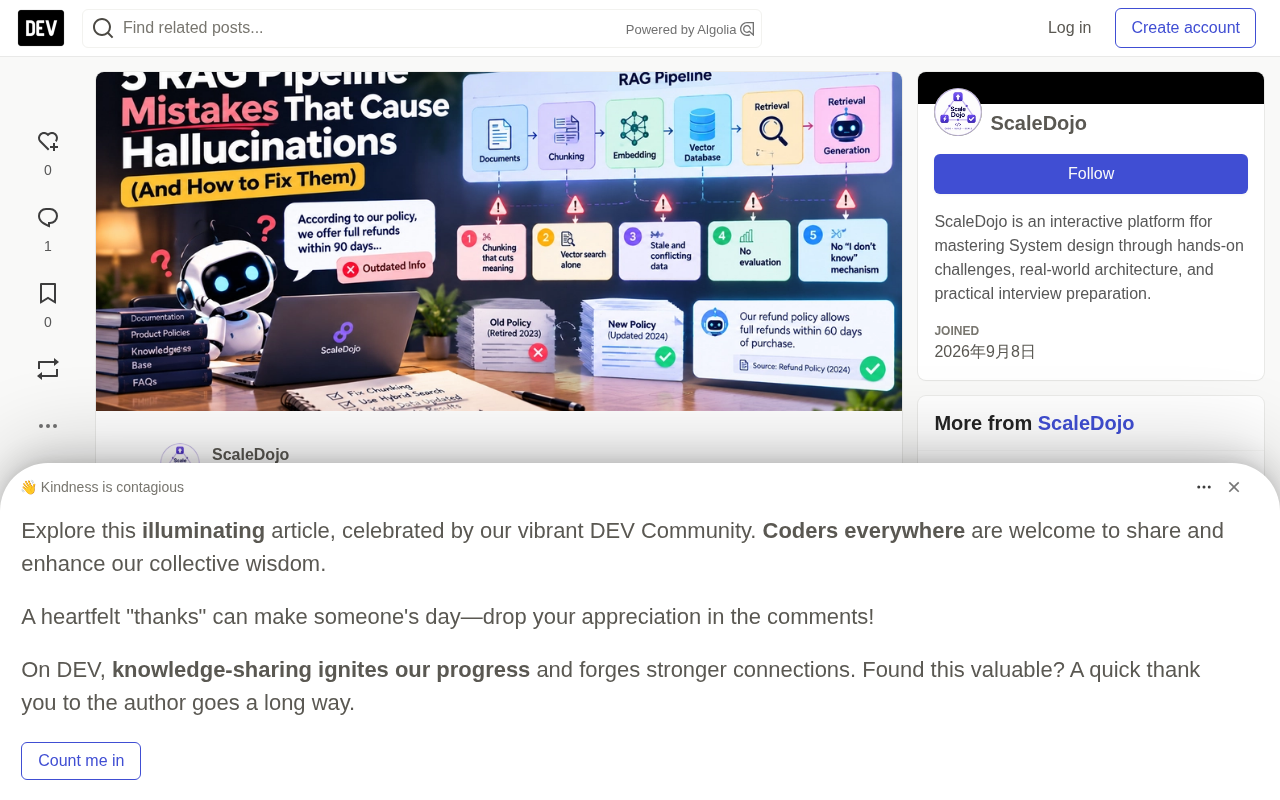
RAG is supposed to reduce hallucinations. And it does—but only if retrieval quality is good enough. The whole pipeline has two steps: find the relevant text, then generate an answer based on it. If the retrieved text is itself wrong, incomplete, or outdated, the model will have no hesitation in writing a fluent, confident answer on top of it.
In most projects, the problem isn't the model itself—it's the design upstream of the model. The following five mistakes come up again and again.
Mistake 1: Chunking cuts semantics in half
Splitting every document into fixed 500-token pieces is easy, but it cuts tables in half, separates a step from its warning, and tears a definition away from the term it defines. When a chunk doesn't make sense read on its own, any answer built on it won't make sense either.
How to fix it:
- Prefer splitting by structure: headings, paragraphs, list items
- Keep a small overlap between adjacent chunks
- Attach the document title and section heading to each chunk
- Keep tables and step lists intact
A quick sanity check: randomly pull 20 chunks and read them. Without looking at the rest of the source document, can you understand each one? If you can't, neither can your model.
Mistake 2: Relying on vector search alone
Embeddings are great at semantic matching, but they're powerless for exact matches. Product numbers, error IDs, version numbers, and names often get lost. When a user searches for "error E4021," they don't want something vaguely about errors.
How to fix it: Use hybrid search. Combine keyword search (BM25 or similar) with vector search, then hand the top 20 to 50 candidates to a reranker, which selects the best 3 to 5 to send into the prompt. A good rule of thumb: retrieve wide, rerank narrow.
What is BM25? BM25 (Best Matching 25) is a classic sparse retrieval algorithm—an improved version of TF-IDF. It scores documents based on term frequency, inverse document frequency, and document length normalization. Its core strength is exact term matching: when a query contains a rare but critical token like "E4021" or "RFC-7231," BM25 hits documents containing that string directly, whereas vector models tend to compress it into a fuzzy semantic direction.
Why does hybrid search work? Vector search and BM25 are complementary: vectors handle "similar meaning," BM25 handles "identical wording." A common approach is to run both retrieval paths separately, then merge the candidate sets using reciprocal rank fusion (RRF) or weighted scores.
A reranker is usually a cross-encoder: it concatenates the query with each candidate chunk, runs them through the model together, and outputs a relevance score directly. Because it has to do a separate forward pass for each candidate, it's much slower than vector retrieval—so it's only used on a small number of candidates (20–50). That's where "retrieve wide, rerank narrow" comes from: use cheap recall for breadth, expensive reranking for precision.
Mistake 3: Data is outdated and conflicting
Documents get updated; indexes usually don't. Worse, the old and new versions of a policy can both sit in the index, and the retriever has no idea which one is current.
How to fix it:
- Store metadata for every chunk: source, version, and last-updated date
- Re-index when documents change, or rebuild the index on a fixed schedule
- Remove or filter out superseded versions
- Show sources and their dates in answers so users can judge for themselves
Mistake 4: No evaluation—just vibes
"Seems to work" is not a metric. Without measurement, you can't tell whether a new chunk size is helping or hurting.
How to fix it: Build a small test set. Start with 30 to 50 real questions, each with a correct answer and the document that contains it. Then measure two things separately:
- Retrieval: Does the correct chunk show up in the top results?
- Generation: Is the final answer actually supported by the retrieved text?
Re-run the test set after every change. This turns tuning from guesswork into measurement.
Mistake 5: No ability to say "I don't know"
Language models always want to be helpful. If the retrieved context doesn't contain the answer, many models fill the gap with something plausible. That's exactly the hallucination users notice.
How to fix it:
- Instruct the model to answer only from the provided context
- Give it an explicit exit when the answer isn't there
- Require a citation for every claim
- Set a retrieval score threshold; below it, refuse to answer or ask a clarifying question
- Log rejected questions, because they expose gaps in your documentation
A starter prompt:
Answer the question using only the context below. If the context does not contain the answer, reply: "I can't find this in the documentation." Cite the source title for each claim. Context: {retrieved_chunks} Question: {question}
Why are models reluctant to say "I don't know"? Instruction tuning and reinforcement learning from human feedback (RLHF) reward "giving a helpful answer," and over time the model develops a strong tendency to fill in blank context. When the context truly doesn't contain the answer, the model doesn't treat that as a signal that it can't respond—it treats it as a generation task and stitches together something plausible from similar phrasing in the corpus.
What a retrieval score threshold does is move the "should I answer?" decision from the model to the retrieval layer. Vector search typically returns cosine similarity or inner-product scores, and you can set a floor on them: below the floor, no chunk is close enough to the question, so you return "not found" directly and skip the generation stage. The threshold needs to be tuned with your evaluation set—too high and you'll refuse answerable questions; too low and it's effectively useless. Logging rejected questions has an added benefit: they often point to missing documentation or bad chunking, which is free signal for improving your knowledge base.
A time-saving debugging order
When you see a wrong answer, work through the following order:
- Is the correct information in the index?
- Was it retrieved?
- Did it rank high enough to make it into the prompt?
- Did the model actually use it?
Most bugs show up in the first three steps—long before you need to blame the model.
For a deeper look at the full architecture (data ingestion, embeddings, vector databases, and retrieval), see the RAG and vector database guide on ScaleDojo, which walks through each component one by one.
This debugging order is essentially layer-by-layer attribution: breaking an end-to-end failure into four independently verifiable stages—indexing, retrieval, ranking, and generation.
Step 1, "Is the correct information in the index?" checks data ingestion—whether document parsing, chunking, and embedding correctly wrote content into the vector store. You can bypass retrieval and verify this with a full-text scan directly against the index.
Step 2, "Was it retrieved?" narrows the scope to recall. If the correct chunk isn't among the top 50 candidates from hybrid search, the problem is in chunking or the embedding model.
Step 3, "Did it rank high enough?" checks reranking and truncation—the correct chunk may have been retrieved but ranked 12th, while the prompt only has room for the top 5.
Only at Step 4 do you turn to the model itself. If the first three steps all pass and the model still gives a wrong answer, then it's a problem with the prompt, context ordering, or model capability. In practice, most bugs end at Step 2 or Step 3.
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.