Why Do Shallow Neural Networks Learn Sine Components First? A Framework Based on Orthogonal Polynomial Dynamics Offers a New Explanation

A new study uses an orthogonal polynomial dynamics framework to explain why neural networks learn low-frequency sine components first, based on the graded structure of matrix H.
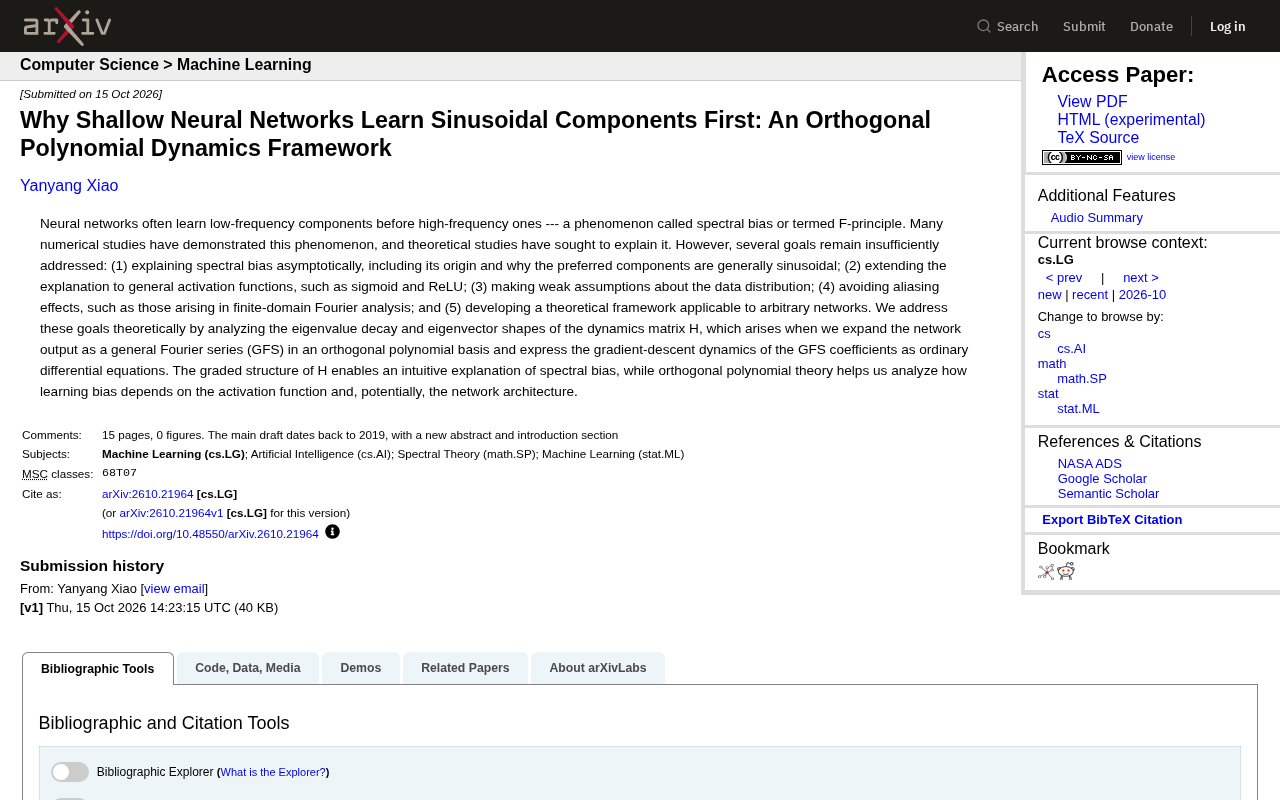
The article introduces a theoretical study on spectral bias (F-principle) in neural networks. Traditional explanations rely on finite-domain Fourier analysis and have limitations such as aliasing, strong data distribution assumptions, and difficulty extending to general activation functions. The new work expands the network output into a generalized Fourier series under an orthogonal polynomial basis, writes the evolution of coefficients under gradient descent as a system of ordinary differential equations, and constructs a dynamics matrix H. The graded structure of H explains why low frequencies are learned first and how activation functions influence learning order by changing the spectral structure of H.
Neural networks consistently learn low-frequency, smooth patterns first during training, and only later fit high-frequency, rapidly varying changes. This phenomenon, known as spectral bias or the F-principle, has been repeatedly observed in numerous numerical experiments. But a more fundamental question has long remained unresolved: why is it precisely sine components that neural networks prefer? And why do different types of activation functions exhibit similar tendencies?
A recent theoretical study attempts to answer these questions from a dynamical perspective. The authors expand the network output into a generalized Fourier series (GFS) under an orthogonal polynomial basis, and write the evolution of the coefficients under gradient descent as a system of ordinary differential equations, thereby constructing an analytically tractable dynamics matrix H. The core of the entire explanatory framework rests on the eigenvalue decay and eigenvector shapes of this matrix.
Traditional Explanations of Spectral Bias and Remaining Challenges
Spectral bias is not a new topic. Early studies mostly characterized this phenomenon using Fourier analysis on finite domains, which is simple and intuitive but brings several unavoidable limitations. The paper explicitly lists five goals that previous studies have not fully addressed:
- How to explain spectral bias asymptotically, including its origin and why the preferred components are typically sinusoidal in form;
- How to extend the explanation to general activation functions such as sigmoid and ReLU;
- How to make weaker assumptions about the data distribution;
- How to avoid aliasing effects—which are nearly unavoidable in finite-domain Fourier analysis;
- How to establish a theoretical framework applicable to arbitrary network architectures.
These questions appear disparate but in fact point to the same demand: existing explanations are more like approximations under specific settings rather than a unified characterization of the learning dynamics itself.
Spectral Bias and the F-Principle: Spectral bias, also known as the F-principle (Frequency principle), refers to the phenomenon that when a neural network fits a target function, the convergence rate of its output error across frequency components systematically slows down as frequency increases. This phenomenon was first systematically characterized by Xu et al. around 2019 through extensive numerical experiments, and subsequently Rahaman et al. provided an approximate theoretical explanation in their 2019 work. Its most intuitive manifestation is that the training trajectory in function space always passes through low-frequency, smooth approximate solutions first, and then gradually approaches high-frequency, oscillatory details; even if the network has sufficient capacity to fit high-frequency components, the dynamics of gradient descent will preferentially push low-frequency components to extremely small errors. It is worth noting that this bias is not a defect, but rather one of the key clues for understanding generalization, implicit regularization, and why networks are still not prone to overfitting despite being overparameterized.
The Dynamics Matrix H Under an Orthogonal Polynomial Basis
The authors' approach is to project the network output onto a set of orthogonal polynomial bases for expansion. This step replaces the trigonometric basis that traditional Fourier analysis relies on, with the direct benefit that orthogonal polynomial theory itself possesses a mature set of approximation and spectral analysis tools that can be directly used to analyze how learning bias depends on activation functions.
Under this expansion, the update of the generalized Fourier series coefficients by gradient descent is written as a set of ordinary differential equations. The coupling structure in the equations is described by a dynamics matrix H. The key property of H is that it exhibits a graded structure: the eigenvalues corresponding to different frequency components decay in a predictable manner. The higher the frequency of a component, the smaller its eigenvalue, and the slower the corresponding dynamical timescale—this is the direct reason why low frequencies are learned first.
The original text calls this structure an "intuitive explanation of spectral bias," while orthogonal polynomial theory further takes on the task of analyzing activation function dependence. This means that the choice of activation function is not an irrelevant detail; rather, by altering the spectral structure of H, it directly shapes the relative speed of each component during learning.
Orthogonal Polynomials and Generalized Fourier Series (GFS): A generalized Fourier series refers to expanding a function in terms of any set of polynomial bases orthogonal with respect to some weight function, rather than being limited to trigonometric functions. Common orthogonal polynomial systems include Legendre polynomials, Chebyshev polynomials, Hermite polynomials, and others. They satisfy orthogonality under a weighted inner product, so expansion coefficients can be computed independently term by term, and truncation errors have mature approximation-theoretic bounds. Compared with trigonometric bases, a key advantage of orthogonal polynomial bases is that they are naturally defined over the entire real interval, and with an appropriate weight function they can adapt to different activation functions and data distributions, thereby avoiding restricting the analysis to a finite domain. After writing the network output as a GFS, the original discussion about 'frequency' is transformed into a discussion about 'polynomial degree' or 'spectral index,' which facilitates writing the evolution of gradient descent as ordinary differential equations in coefficient space.
The meaning of graded structure: The graded structure of the H matrix in the paper refers to the regular hierarchical decay of its spectrum (eigenvalue distribution) with respect to the index. Specifically, the eigenvectors corresponding to low-frequency or low-order components have larger eigenvalues, and these directions contract faster under gradient flow, so they are learned preferentially; while the eigenvalues corresponding to high-frequency or high-order components are smaller, their dynamical timescales are longer, and they require longer training time to decrease significantly. This pattern of eigenvalues decaying monotonically or nearly monotonically with frequency is precisely the direct mathematical source of spectral bias. The graded structure also implies coupling between different components: H is usually not a diagonal matrix, but rather approximately block-diagonal or banded, and the learning of higher-order components is influenced by the residual error of lower-order components, which provides a richer picture for understanding fine-tuning in the later stages of training.
Three Improvements Over Existing Frameworks
The value of this framework can be assessed against the challenges listed earlier.
First, it escapes the aliasing predicament of finite-domain Fourier analysis. When traditional approaches perform Fourier decomposition on a finite domain, high-frequency components can become confused with low-frequency components due to sampling or boundary effects, causing judgments about "which frequencies are preferred" to potentially be distorted. After switching to an orthogonal polynomial basis, this source of interference is bypassed.
Second, the assumptions about data distribution are weaker. The paper emphasizes that its analysis does not rely on strong assumptions about the data distribution, which makes the conclusions applicable more broadly, rather than holding only under specific input distributions.
Third, activation function coverage is more general. Common but very different activation functions such as sigmoid and ReLU are both incorporated into the same analytical path. This is especially important—ReLU is non-smooth and sigmoid saturates, and their spectral behaviors differ significantly, yet both can be accommodated by the eigenstructure of H.
As for the goal of being "applicable to arbitrary network architectures," the original text is relatively cautious: orthogonal polynomial theory "has the potential" to help analyze how learning bias depends on network architecture. This indicates that extension to deep or arbitrary-topology networks remains a direction that this framework needs to continue validating, rather than a completed result.
Finite-Domain Fourier Analysis and Aliasing: In traditional approaches, researchers usually restrict the network input to a finite grid or finite interval, and perform a discrete Fourier transform after discretely sampling the network output. This treatment introduces aliasing: when the signal contains frequency components higher than half the sampling rate, they are incorrectly folded into the low-frequency range, making high-frequency and low-frequency components indistinguishable in the spectrum. In addition, periodic extension on a finite domain artificially introduces discontinuities at the boundaries, further contaminating the spectrum. For the question of 'which frequencies the network prefers,' aliasing means that the observed frequency components may not be the components the network actually learns, thus reducing the reliability of the conclusions. After switching to an orthogonal polynomial basis defined over the entire real domain, the expansion does not suffer from folding problems caused by periodic extension and discrete sampling, thereby avoiding this interference in principle.
An Explanatory Perspective Worth Noting
The significance of this work is not that it overturns anything, but that it uses a different mathematical language to describe the same phenomenon. The Fourier basis is naturally suited to talking about "frequency," but it carries a heavy technical burden on finite domains; the orthogonal polynomial basis sacrifices a bit of frequency intuition in exchange for cleaner spectral analysis and more flexible adaptation to activation functions.
The graded structure of the matrix H provides an actionable intuition: the order in which learning proceeds is essentially determined by the spectrum of the dynamics matrix. This also suggests that if the spectrum of H could be adjusted through architecture or initialization, it might be possible to regulate the model's learning order to some extent—which could be a valuable clue for tasks that need to prioritize capturing high-frequency details.
Of course, there is still a considerable distance between shallow networks and arbitrary architectures, and between theoretical characterization and predictability in actual training. The paper positions itself as building a theoretical framework rather than providing an engineering solution, and this sense of proportion is appropriate.
One-line Summary
A new study uses an orthogonal polynomial dynamics framework to explain why neural networks learn low-frequency sine components first, based on the graded structure of matrix H.
Paragraph Summary
The article introduces a theoretical study on spectral bias (F-principle) in neural networks. Traditional explanations rely on finite-domain Fourier analysis and have limitations such as aliasing, strong data distribution assumptions, and difficulty extending to general activation functions. The new work expands the network output into a generalized Fourier series under an orthogonal polynomial basis, writes the evolution of coefficients under gradient descent as a system of ordinary differential equations, and constructs a dynamics matrix H. The graded structure of H makes high-frequency components correspond to smaller eigenvalues and slower timescales, thereby explaining from a spectral perspective why low frequencies are learned first, and showing that activation functions influence learning order by changing the spectral structure of H. This framework bypasses aliasing issues, weakens data distribution assumptions, and can cover general activation functions such as sigmoid and ReLU, but extension to arbitrary network architectures remains to be verified.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.