Why Has Deep Learning Struggled with Tabular Data for a Decade? Frank Hutter Explains

Frank Hutter explains why tabular deep learning long failed and how in-context learning finally delivers a breakthrough.
AutoML scholar Frank Hutter reveals the fundamental reasons deep learning has long failed to conquer tabular data: tables are dirty and heterogeneous, and different domain tables share no transferable semantics at the row level. Using Google's 2019 TabNet as a case study, he identifies a generation of methods that looked good on benchmarks but couldn't generalize. Unlike images, where a single large dataset like ImageNet enables universal feature learning, tabular knowledge transfer must happen at the abstract statistical pattern level — not the data row level. In-context learning, as embodied by TabPFN, achieves exactly this, and is now challenging the long-held default of using gradient boosting trees for all tabular tasks.
Tabular data is the most common and commercially valuable data format in machine learning — from medical records to actuarial analysis, from banking risk control to retail analytics, structured row-column tables are everywhere. Yet throughout the decade that deep learning swept through images, text, and speech, tabular data remained a fortress that neural networks simply could not conquer. Traditional gradient boosting methods like XGBoost and LightGBM have long dominated this space. AutoML authority Frank Hutter, in a recent interview, offered a remarkably insightful explanation for why.
Dirty Data and the Generalization Problem
Hutter got straight to the point: "Tabular data is very dirty, and I think that's one of the reasons why deep learning took so long to really do well on it."
Unlike images and text — which are highly structured with semantically continuous features — tabular data is riddled with missing values, heterogeneous data types (a mix of numeric, categorical, and date fields), inconsistent encoding schemes, and domain-specific noise. Neural networks excel at learning in continuous, smooth feature spaces, and the discrete, heterogeneous nature of tabular data hits them right where they're weakest.
Hutter specifically highlighted a landmark case: TabNet, introduced by Google in 2019. "TabNet was hyped enormously at the time — thousands of citations, seen as the new darling of tabular data. But it just didn't work; it couldn't generalize to new datasets."
TabNet's failure was not an isolated incident — it was emblematic of an entire generation of deep learning methods for tabular data. They might produce impressive numbers on specific benchmarks, but the moment they were applied to new, real-world datasets, performance collapsed rapidly. This lack of generalization was precisely the pain point that deep learning should have been good at, yet repeatedly failed to overcome in the tabular domain.
The reason gradient boosting trees have long dominated tabular data is that their design naturally suits the characteristics of this type of data. Algorithms like XGBoost and LightGBM, built on decision tree splitting mechanisms, natively support mixed data types, have built-in strategies for handling missing values, and are insensitive to feature scale — no need for the normalization preprocessing that neural networks require. More critically, tree models capture piecewise linear relationships between features through axis-aligned splits, and many business rules in tabular data happen to follow exactly this structure — for example, "if income exceeds X and age is below Y, then risk level is Z." Neural networks must approximate such patterns, which could be described with just a few rules, through large numbers of parameters and nonlinear activation functions, making them highly prone to overfitting when data is limited.
The ImageNet Analogy and the Fundamental Difference with Tabular Data
Hutter drew a clever analogy with ImageNet to explain the core of the problem.
"You can have an ImageNet that basically covers all kinds of images in the world, and learning on that one dataset is enough." The visual world has an intrinsic unity — whether cats, dogs, or cars, they share low-level visual features like pixels, edges, and textures. One sufficiently large image dataset can enable a model to learn transferable, general-purpose representations.

But the logic of tabular data is entirely different. "What tabular data really needs is a large number of different tables, because if you have one table from medicine and another from insurance, there's nothing you can learn from a single row in one table that tells you anything about the other table."

This is a profound observation: a single row from a medical table (a patient's lab results) and a single row from an insurance table (a policy's parameters) share no common semantics at the raw data level. You cannot, as with images, stack massive amounts of homogeneous samples to learn universal features.
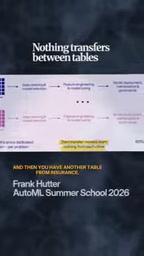
This was the fatal flaw of past tabular deep learning methods — they attempted to learn and transfer at the level of "rows," and that path was fundamentally a dead end.
The Breakthrough from In-Context Learning
So where does the breakthrough lie? Hutter's answer: transfer should not happen at the level of data rows, but at the level of patterns.
"What you can do, where you can achieve transfer, is at the level of these patterns." Although a medical table and an insurance table have no specific data in common, they may share certain regularities in statistical structure — patterns of correlation between features, the shape of certain distributions, how outliers manifest. This abstract meta-knowledge of "how to learn from data" is what can genuinely transfer across datasets.
The key technology enabling this pattern-level transfer is in-context learning. "With in-context learning, you can indeed transfer across different datasets, and that's why, yes, with in-context learning, we're finally seeing breakthroughs in tabular data."
This idea is the core of a new generation of tabular foundation models exemplified by TabPFN. The model is pretrained on a massive, diverse collection of synthetic tabular tasks, learning not the patterns of any specific dataset, but a general capability of "how to reason about a new table." At inference time, the entire training table is fed in as context, and the model produces predictions in a single forward pass — no retraining on the new dataset required. This paradigm completely sidesteps the generalization challenges that traditional deep learning faces with tabular data.
In-context learning first became widely known through large language models like GPT-3: the model completes new tasks at inference time without updating any parameters, relying solely on a few examples provided in the prompt (the "context"). TabPFN transfers this idea to tabular data: during pretraining, the model is trained on millions of synthetic classification tasks, each corresponding to a randomly generated small table; at inference time, the entire training set is concatenated into the input as context, and the model uses the Transformer's attention mechanism to establish relationships across rows, directly outputting the predicted distribution for test samples. This is equivalent to the model internally simulating a Bayesian inference: it has learned how to perform posterior estimation of a new sample's label distribution based on observed training samples, rather than memorizing the statistical patterns of any specific dataset. This design — where "the algorithm itself serves as the pretraining objective" — is the theoretical foundation for its ability to zero-shot generalize to tables from entirely new domains.
Implications for Practitioners
Hutter's analysis is not merely an academic retrospective — it has direct implications for engineering practice.
For a long time, "use gradient boosting trees for tabular data" was the near-universal default among data scientists, with deep learning viewed as a poor value proposition. But the maturation of the in-context learning paradigm is rewriting this rule. For small to medium-sized datasets, pretrained tabular foundation models are poised to match or even surpass carefully tuned tree models, at a fraction of the hyperparameter tuning effort.
More importantly, it represents a shift in thinking: understanding that "transfer happens at the pattern level, not the data level" is essential to truly grasping why some approaches work and why others are doomed to fail. TabNet's story reminds us that whenever a new paper claims to have conquered tabular data, the ability to generalize to real, unseen datasets is always the ultimate test of value.
From TabNet's fanfare to the breakthrough of in-context learning, the decade-long detour of deep learning for tabular data has ultimately been a long journey of exploration into the question: what is truly transferable knowledge?
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.