Zero-Shot Wafer Map Classification: A Training-Free Multimodal LLM Approach

Training-free zero-shot wafer map defect classification combines connected-component highlighting and rule-ordering prompts for strong multi-dataset results.
A recent study proposes a training-free six-class wafer map defect classification framework using frozen multimodal LLMs with connected-component highlighting and multi-dimensional rule prompts for zero-shot classification. It achieves 93.8% overall accuracy on Mixed-WM38 and 81.3% on WM811K. Rule ordering in prompts is found to matter, with the chosen order beating eight alternatives by 2–3 points. The method needs no labeled data or fine-tuning, but validation is limited to public datasets.
Wafer map defect classification is a critical step in yield analysis for semiconductor manufacturing. Traditional methods rely on large amounts of labeled data and require model retraining when production conditions change. A recent study proposes a training-free six-class classification framework that leverages frozen large multimodal models to achieve zero-shot classification through connected-component highlighting and rule-ordering prompts, delivering significant results across multiple datasets.
Core Design of the Training-Free Framework
The key innovation of this research lies in combining connected-component highlighting with multi-dimensional prompts. Specifically, the system first performs connected-component analysis on the wafer map to highlight potential defect regions, then feeds this visual information along with morphology-, position-, and exclusion-aware prompts into a frozen multimodal large model. Since the model parameters are completely frozen, the entire pipeline requires no labeled data or fine-tuning, achieving true zero-shot classification.
The core advantage of this approach is its adaptability: when production condition changes cause defect pattern drift, traditional models need to recollect data and retrain, whereas this framework only requires adjusting prompt rules for rapid deployment.
Connected-component analysis is a classic technique in image processing used to aggregate adjacent pixels (typically under 4- or 8-connectivity criteria) in a binary image into distinct regions. In wafer map analysis, defects usually appear as localized anomalous pixel clusters; connected-component analysis can quickly locate the boundaries and positions of these clusters and highlight them. This step does not rely on any model training—it is purely geometry-based—making it naturally compatible with frozen multimodal large models and able to provide spatial and morphological structural information for subsequent prompts.
Zero-shot classification refers to a model directly predicting categories without ever having seen labeled samples of the target classes. Its feasibility depends on the generalization capability of representations acquired during large-scale pretraining, as well as on injecting task knowledge into the model through natural language prompts. Unlike traditional supervised learning, zero-shot classification performs no parameter updates, so adaptation to new categories is extremely fast—but performance is highly dependent on the quality of prompt design.
Performance: Mixed-WM38 and WM811K
On the Mixed-WM38 dataset (containing 6,866 wafer maps), the multi-region prompting strategy achieved 92.9% macro-average accuracy and 93.8% overall accuracy. On the larger WM811K dataset (9,000 images), the same method achieved 79.1% macro-average accuracy and 81.3% overall accuracy. The performance gap between the two datasets may stem from differences in defect class distribution and image complexity, but the overall results demonstrate the method's effectiveness across different data scales.
Compared with traditional methods that require training, this training-free approach is not inferior in accuracy while eliminating the costs of data annotation and model iteration.
Macro-average accuracy and overall accuracy are two different aggregation metrics in classification tasks. Overall accuracy is the proportion of correctly predicted samples among all samples and is easily affected by the distribution of sample counts across classes; macro-average accuracy first computes the accuracy for each class separately and then takes the arithmetic mean, making it more sensitive to the performance on minority classes. In wafer map defect classification, sample sizes across defect types are often imbalanced, so macro-average accuracy reflects the model's ability to recognize each defect type more fairly—which is why the study reports both metrics.
WM811K is one of the most commonly used public benchmark datasets in the field of semiconductor defect map analysis, containing approximately 810,000 wafer maps covering various defect patterns. The study selected 9,000 images from it for experiments, constituting a subset validation. Since the class distribution and image noise levels of WM811K differ from those of Mixed-WM38, cross-dataset performance degradation is expected—which also suggests that zero-shot methods need prompt adaptation to the data characteristics of the target production line before practical deployment.
Impact of Rule Ordering
The study also explored the effect of rule ordering within prompts on classification performance. Besides the selected optimal order, eight alternative rule orders yielded overall accuracies ranging from 90.1% to 91.9%, all lower than the 93.8% of the chosen order. This indicates that rule ordering has a substantive impact on the final results, and a well-designed order can bring about a 2–3 percentage point improvement. Although the gap is modest, such gains have practical value in scenarios like wafer map classification that demand high precision.
This finding also suggests that in prompt engineering for multimodal large models, how rules are organized is not trivial but rather a component that requires careful design.
Rule ordering in prompt engineering affects outputs due to the attention mechanisms and context processing of large multimodal models. When multiple rules are fed sequentially in text form, the model typically assigns higher attention weight to earlier content, and later rules may be partially diluted or overridden. Moreover, if rules have semantic overlap or potential conflicts, their ordering changes the model's path for resolving ambiguity. Thus, even with an identical rule set, different organizational orders can shift classification decisions. This phenomenon is especially prominent in zero-shot settings, since there is no training process to smooth out fluctuations caused by prompt variations.
Industry Significance and Limitations
From an industry perspective, this research offers a new path for defect detection in semiconductor manufacturing. The training-free nature means lower deployment barriers and faster response times, making it especially suitable for low-volume, high-mix production environments. However, the method has so far been validated only on two public datasets; complex noise and rare defect patterns in real production lines may pose challenges. In addition, tuning rule ordering still requires certain domain knowledge, and how to automatically search for the optimal rule order is a direction worth exploring in the future.
Overall, this study demonstrates the potential of multimodal large models in industrial vision tasks—zero-shot classification is no longer confined to theory but now has a practical, deployable technical solution.
One-line Summary
Researchers propose a training-free zero-shot wafer map defect classification framework combining connected-component highlighting and rule-ordering prompts, achieving notable results across multiple datasets.
Paragraph Summary
A recent study proposes a training-free six-class wafer map defect classification framework that uses frozen large multimodal models to achieve zero-shot classification through connected-component highlighting and multi-dimensional rule prompts. It reaches 93.8% overall accuracy on Mixed-WM38 and 81.3% on WM811K. The study also finds that rule ordering in prompts substantively affects performance, with the chosen order outperforming eight alternatives by about 2–3 percentage points. The method requires no labeled data or model fine-tuning and adapts to production condition changes, offering a low-barrier new path for semiconductor yield analysis—though validation is currently limited to public datasets, and complex noise in real production lines and automated tuning of rule ordering remain open challenges.
Related articles
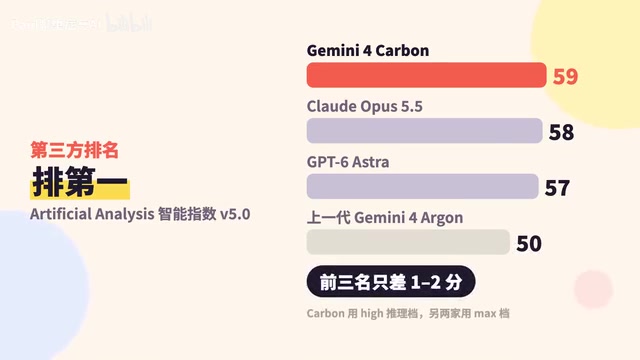
Google Releases Gemini 4 Carbon: Its Strongest Model Yet, Debuting with a Cybersecurity Focus
Google releases Gemini 4 Carbon, calling it its strongest model, with a cybersecurity focus. It tops the third-party composite ranking at 59 points but leads by only one or two. This article analyzes its security test results, staged rollout, token pricing, and the divergence between self-reported and third-party tests on hallucinations.

LangChain Adds SchemagateRetriever: On-Demand Table Retrieval Cuts Text-to-SQL Prompts by 92.9%
LangChain docs add SchemagateRetriever: retrieves only the tables needed for text-to-SQL with permission filtering, cutting median prompt size by 92.9% on Spider 2.0 large schemas via offline BM25 selection with no model calls.

Multi-Step AI Agent Guardrail in Practice: Fact-Change Detection Drives False-Alarm Rate to 0%
Developer shares first version of a multi-step AI Agent guardrail: re-verifying dependency facts before irreversible actions cut false alarms from 50% to 17% across 23 scenarios, then to 0% via conservative normalization without lowering catch rate. Runs on local qwen2.5-7b.