1,000 AI Agents Formalize Fermat's Last Theorem in 30 Hours, Anthropic Releases New Claude Models

Anthropic releases Fable 5.2 and Mythos 5.2, with 1,000 agents formalizing Fermat's Last Theorem in 30 hours.
Anthropic has released Claude Fable 5.2 and Claude Mythos 5.2, two versions of the same underlying model: Fable has strong safety guardrails, while Mythos is available by application to cybersecurity and biomedical organizations. The company says they are a notch above OPUS 5.5, with output up to 30% faster and pricing cut to $8 per million input tokens and $40 for output. The headline demo: 1,000 Fable 5.2 agents fully formalized Fermat's Last Theorem in 30 hours, while OPUS 5.5 reached only 26%. The models also advanced on MIPLIB optimization problems, hardware design, black-hole-related theoretical physics, protein structure prediction, and robot control. Anthropic recommends OPUS 5.5 for everyday work and the new models for the hardest, most open-ended technical tasks.
Anthropic has released two new models at once, Claude Fable 5.2 and Claude Mythos 5.2, with a very clear positioning: they target the hardest technical problems. The company says both models improve on coding, reasoning, and vision capabilities, and the most striking demonstration is a team of 1,000 Fable 5.2 agents that completed a full formalization of Fermat's Last Theorem in 30 hours.
Two names, one underlying model
Fable and Mythos are easy to confuse, but they are actually two versions of the same underlying model. Fable has strong safety guardrails to prevent misuse; Mythos requires an application and is aimed at organizations doing cybersecurity and biomedical research, applied for through the official life sciences and cybersecurity verification programs.
According to official evaluations, both models are a notch above OPUS 5.5 in almost every capability. Testers also found them clearer in expression, with output speed up to 30% faster than version 5.1, and the price actually dropped: $8 per million input tokens and $40 for output, down from $10 and $50.
Coding capabilities: half the cost, higher scores
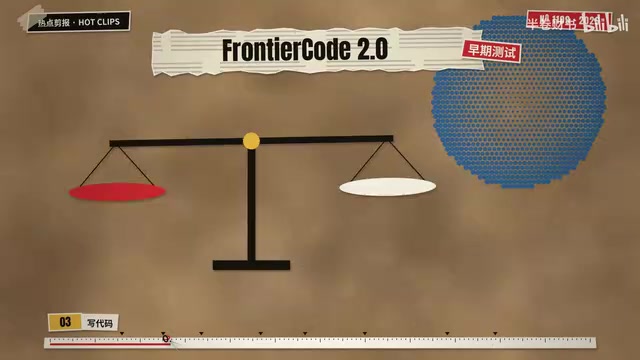
In early testing on Frontier Code 2.0, Fable 5.2 on the High setting scores roughly the same as OPUS 5.5 on Max, but costs only about half per task. On the X High setting, it has the highest score of any released model. In the Claude app and Claude Code, the default setting is Medium.
This combination of "more performance, lower price" means that for developers who heavily use coding assistants every day, the same budget can run more tasks, or more complex tasks can be handed to a higher setting.
A thousand agents formalize Fermat's Last Theorem in 30 hours
Formalization means translating an entire proof into a language a computer can check step by step, where no step can be fudged. With the same setup swapped to OPUS 5.5, after 18 hours it had completed only 26%, and running the full 30 hours it barely progressed further; meanwhile 1,000 Fable 5.2 agents completed everything within 30 hours. On one side is full delivery, on the other a stall at roughly a quarter — the gap is obvious.
The significance of this result is not that "AI can do math," but the engineering feasibility of multi-agent collaboration on extremely long tasks: how to split the proof, how to keep agents consistent with each other, and how to stay on target over a 30-hour span — these are challenges harder than raw single-point capability.
Fermat's Last Theorem is one of the most famous propositions in number theory: for integers n > 2, the equation xⁿ + yⁿ = zⁿ has no positive integer solutions. It was proposed by Fermat in 1637 and only completed in 1995 by Andrew Wiles using modern tools such as elliptic curves and modular forms, spanning more than three centuries. Formalization goes a step further: using interactive theorem provers like Lean, Coq, and Isabelle to rewrite every logical step of the proof into a formal language that a machine can mechanically verify line by line. Unlike natural-language papers, formal proofs do not rely on readers "believing" the author's argument; any incorrect derivation is directly rejected by the compiler. Because of this, formalizing a large theorem is extremely lengthy and tedious, and doing it manually often takes years. The value of this demonstration therefore lies more at the engineering level — it verifies whether a multi-agent system can, over dozens of hours of continuous work, stably complete formalization work at this scale.
From hardware to scheduling: hard problems across domains
Fable 5.2's capabilities go beyond code and math. Given only a paragraph-long prompt, it designed three working electronic devices, one of which is a home voice assistant hub. It wrote the specifications itself, selected the components itself, routed the four-layer circuit boards itself, and also made the 3D-printed enclosure and software; each board could be sent to production in under a day, and all three devices worked directly without any modifications.
Among the 203 unsolved problems in the optimization problem library MIPLIB, Claude beat the listed solution on 72 and proved optimality on 45. One problem was how to schedule the timetables of 42 trains to minimize peak power consumption; in under two hours the agent improved on the previous best solution by 2.6%, and later proved that no better timetable exists. The answer has been submitted to MIPLIB for anyone to verify.
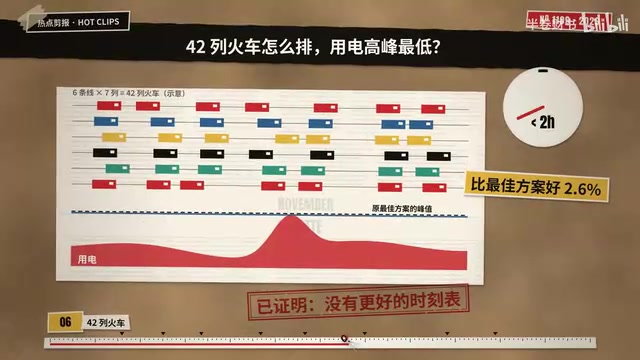
MIPLIB (Mixed Integer Programming Library) is the standard benchmark set in the field of mixed integer programming, containing a large number of real optimization problems from industry and academia, and has long been used as a yardstick for measuring solver performance. Mixed integer programming is a class of optimization problems: the objective function and constraints are linear, but some variables must take integer values. Such problems appear widely in scheduling, logistics, production planning, network design, and other scenarios, and most are NP-hard, making optimal solutions computationally very challenging. Instances marked as "unsolved" in MIPLIB mean that no one has yet proved their optimal value, and only upper or lower bounds can be given. Therefore, a model being able to "beat the listed solution" or "prove optimality" on some problems is a fairly strong signal — it means it not only found a better feasible solution, but in some cases also completed an optimality proof.
Progress in theoretical physics and biomedicine
Fable 5.2 solved two open problems in theoretical physics related to black holes. The first concerns a 1983 discovery by physicists that in certain larger theoretical universes, black holes form very abruptly as temperature rises; in 2003 someone proposed a calculation to test whether this also happens in a set of extremely small universes, and this calculation remained open for 23 years. Fable 5.2 completed it, and the transition there is likewise abrupt. The second problem relates to a technique used for 15 years called modular tensor physics, which physicists use to rule out invalid candidate theories of quantum gravity in theoretical universes; Fable 5.2 found the exact limit of its simplest version. Both physics results have been written up as preprints.
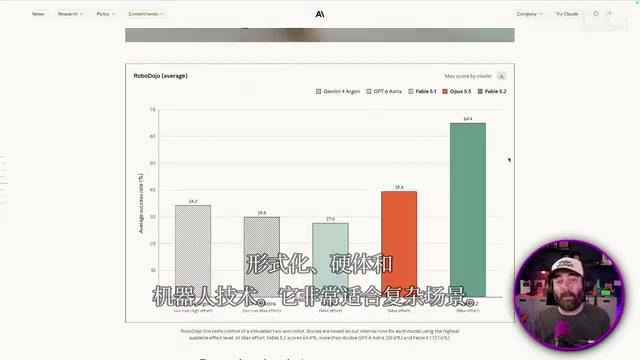
There has also been progress in biology and robotics. Gene therapies can be delivered into the body inside a protein shell called a "single shell," and Mythos 5.2 found a new method for predicting the entire single-shell structure; in tests it tried 34 and accurately modeled 28. On robotics, on the dual-arm simulated robot benchmark Robo Dojo, Fable 5.2 outperformed other models and also most AI systems specialized in robot control.
Modular tensor physics borrows mathematical structures from condensed matter and topological quantum field theory, in which "modular tensor categories" are used to describe physical objects such as anyons and topological order. Physicists use this framework to impose consistency constraints on candidate quantum gravity theories: a theory that cannot correspond to a valid modular tensor structure can be ruled out. The "exact limit of the simplest version" found by Fable 5.2 refers to determining the boundary of some admissible parameter range under such constraints. Results of this kind are usually technical advances in mathematical physics rather than direct experimental discoveries; the release of this result as a preprint also means it has yet to undergo peer review.
Stronger capabilities — what about safety?
Officially, on most alignment metrics these two models are as good as or better than recent models, and before release external organizations such as the UK AI Safety Institute and METR were invited to test them. Fable 5.2 is available starting today on all paid plans, the Claude platform, and major cloud platforms. The official usage recommendation is: start with OPUS 5.5 for everyday coding and knowledge tasks, and hand the hardest, most open-ended technical work to Fable and Mythos.
The most memorable thing about this release is not another few points of improvement, but 1,000 agents spending 30 hours turning an entire famous proof into something a machine can verify step by step. The pattern of multi-agent collaboration tackling long-cycle hard tasks may be more noteworthy than the score of any single model.
One-line Summary
Anthropic releases Fable 5.2 and Mythos 5.2, with 1,000 agents formalizing Fermat's Last Theorem in 30 hours.
Paragraph Summary
Anthropic has released two models at once, Claude Fable 5.2 and Claude Mythos 5.2, which share the same origin: Fable has strong safety guardrails, while Mythos is available by application to cybersecurity and biomedical organizations. The company says their capabilities are a notch above OPUS 5.5, output speed is up to 30% faster, and pricing drops to $8 per million input tokens and $40 for output. The most closely watched demonstration is 1,000 Fable 5.2 agents completing a full formalization of Fermat's Last Theorem within 30 hours, while OPUS 5.5 completed only 26% over the same period. The models also made progress on MIPLIB optimization problems, hardware design, open problems in black-hole-related theoretical physics, protein structure prediction, and robot control. The official recommendation is to use OPUS 5.5 for everyday tasks and give the hardest, most open-ended technical work to the new models.
Related articles
Claude Fable 5.2 Hands-On: Top Intelligence but Absurdly Expensive
Anthropic releases Claude Fable 5.2 and Mythos 5.2, topping the Artificial Analysis intelligence leaderboard with big gains in scientific reasoning, strong game and hardware design, but max mode costs ~$26.54 per task. Hands-on game, circuit board design, and pricing advice.

Claude Fable 5.2 Released: A Thousand AI Agents Build a Bootable OS in 8 Days
Anthropic releases Claude Fable 5.2 and Mythos 5.2—same model, two safety tiers. Demo shows 1,000 AI agents build a bootable OS in 8 days, formalize Fermat proof in 30 hours, score 64.6 beating Gemini 4 Carbon, price cut 20%.

Claude Fable 5.2 Release Analysis: The Strongest Model Deliberately Weakened?
Analysis of Claude Fable 5.2 and Mythos 5.2: Anthropic deliberately restricted accelerator kernel optimization and architecture improvements during training, drawing a line before recursive self-improvement. The video also reconstructs a 1,000-agent, eight-day OS-building experiment and discusses whether open-source models will overtake.