11 Tested Rules to Slash Claude Token Costs to the Bare Minimum
Claude Code's token costs mostly hide in cache expiration and context bloat—eleven rules teach you to plug the black hole.
The article starts from the phenomenon that Claude's one-hour cache expiration can make the same message cost about 20 times more, and systematically lays out Claude Code's token-saving rules. The core idea has four layers: source control (default to medium effort, have Claude interview you to clarify requirements), context cleanup (uninstall unused skills and connectors, use /clear when switching tasks, /compact before leaving for over an hour), using the right tools (use /rewind to roll back instead of repeatedly correcting, claim free reset credits, use /usage to locate consumption sources, enable concise output style), and the agent and quota defense line (downgrade the Explore subagent to Haiku, set a monthly usage cap). The author emphasizes that six old rules have become obsolete, and what's truly stable are the habits: medium effort, clear requirements, frequent context cleanup, new sessions when switching, compress before leaving, and cheaper models for auxiliary tasks.
Where Your Tokens Go: An Overlooked Cost Black Hole
Ask Claude the same question an hour later, and it might cost several times more than the first time. The reason isn't a price hike—it's Claude's caching mechanism: under the subscription plan, Claude Code's conversation cache is retained for only one hour, and each message resets the timer—but if you're away for more than an hour, the next message forces Claude to re-read the entire conversation from scratch.
According to YouTube creator Doobie, he went through his own 30 days of Claude Code logs and found that every time he returned from a long break, Claude had to re-read about 92% of the chat history. Anthropic's Lydia Hawley did the math: reading from cache costs about one-tenth of the normal price, while rewriting the cache can cost up to twice as much—meaning the same message sent an hour later can cost roughly 20 times more.
Doobie previously shared 11 token-saving rules that were widely copied by users, but he admits 6 of them have become obsolete due to product updates. He re-reviewed Anthropic's official documentation and the past six months of patch notes to compile a new set of rules. They are presented below, grouped logically.
The Billing Logic of Prompt Caching: Anthropic's caching mechanism allows the conversation prefix (system prompt, historical messages, etc.) to be temporarily stored; subsequent requests that hit the cache are billed at about 1/10 the normal input price, while cache misses that require rewriting are billed at about 1.25x the normal price (5-minute cache) or 2x (1-hour cache) for the written portion. This means "sending an hour later" isn't just paying an extra input fee—it's replacing a cheap cache read with an expensive cache write. Under Claude Code's subscription plan, the 1-hour cache is used by default, and each new message refreshes the cache's validity period—but once the interval exceeds 1 hour, the cache expires, and the next message must rewrite and bill the entire history, which is exactly the source of the "20x price difference" mentioned in the article.
Tokens and the Context Window: A token is the smallest billing unit for text processed by the model, roughly equivalent to 0.75 English words or half a Chinese character. Each message actually sends not just the text you type, but also the system prompt, CLAUDE.md, skill descriptions, connector tool definitions, historical conversation, and other "context." The context window has an upper limit, and you pay for the entire context on every request—so "the cleaner the context, the cheaper each message." The 190,000 tokens cited in the article is about 140,000 English words, which precisely illustrates that in everyday conversation, what you actually say is only a tiny fraction.
Rules 1 and 2: Control Consumption at the Source
Leave the Effort Level at Medium
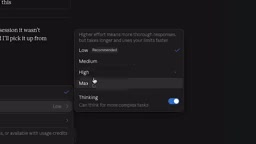
On Opus 5.5, Anthropic set medium as the default effort level. Kat Wu, who leads Claude Code, says that with the same Opus 5.5, rate limits can last 25% longer than the previous generation model.
A higher effort level means Claude spends more time checking work, testing edge cases, and making autonomous decisions—but it doesn't equal a qualitative leap in results. Anthropic's chief engineer Tariq ran a test: first have Claude interview him to clarify the requirements for a fitness app, then give the same requirements to different effort levels. Medium took 22 minutes, high took 33 minutes, and max took 79 minutes—yet the final design and implementation were quite close—max just spent extra time simplifying details, but you waited over an hour for what medium could deliver in 22 minutes.
Tariq's own advice is also: use medium for everyday development, and turn it up only when you hit a nasty bug, need a security check, or encounter a weird scenario you didn't anticipate.
Don't Let Claude Guess Your Intent
There's a key detail in the test above: having Claude interview Tariq first and obtaining a detailed requirements brief significantly narrowed the gap between different effort levels. Conversely, a single sentence like "build me a fitness app" makes Claude decide for you who the users are, what features they need, and what the interface looks like—the higher the effort level, the more decisions it makes on your behalf, and the more compute it burns.
The practical method is simple: before starting work, have Claude interview you first—"Interview me first, ask about anything unclear, organize my answers into a plan I can approve, and then start." Everyday questions should also come with verifiable goals—for example, instead of saying "the settings page is broken," say "the notification toggle turns itself back on after a refresh; it should remember my choice."
Effort Level and Reasoning Tokens: On models that support reasoning, the effort level controls how deeply the model thinks internally before giving a final answer. Higher levels generate more "reasoning tokens" and trigger more tool calls, self-checks, and edge-case testing, so time and cost rise together—but output quality doesn't necessarily improve linearly. For tasks with clear requirements and well-defined acceptance criteria, medium often already hits the point of diminishing returns; only in scenarios like subtle bugs, security audits, or architectural trade-offs that require exploring multiple paths is a higher level worth it. Understanding the effort level as "how much trial-and-error budget you give the model" rather than a "smartness knob" helps you make more rational trade-offs between cost and quality.
Rules 3 to 5: Clean Up Context, Don't Let History Drag You Down
Uninstall What You Don't Use First
Before what you say, every message carries a pile of extra content: system prompt, CLAUDE.md, names of installed skills, enabled connectors. Anthropic's documentation notes that connectors and skills are the most token-hungry parts. Writing an email doesn't require Notion, Drive, and Calendar all hanging at once.
In Claude Code, start a new session and type /context to see the current context usage, then multiply by the number of messages you send per day. The screenshot shows this kind of context composition. Doobie also wrote a custom skill called "Claude Cleanser" that automatically cleans up skills unused for over 30 days—because Anthropic's skills library interface doesn't fully display installed items, making it easy to install and forget.
/clear When Switching Tasks
Anthropic's official documentation calls this "the single most effective lever for quality and cost." Doobie admits he often makes this mistake: fixing an app bug in the morning, then writing a landing page in the same conversation, then asking about a thumbnail—three unrelated tasks sharing one context. He checked his logs and found that a typical message of his carried about 190,000 tokens of context, equivalent to 140,000 words—just to say "polish this."
When switching tasks, click New Chat in the app, or type /clear in the terminal.
The Difference Between /compact and /clear: /clear completely wipes the current session and starts from zero—history is not retained at all, which is the cheapest option but loses all context. /compact, on the other hand, asks the model to compress the existing conversation into a summary, retaining key information and continuing—it still incurs a call cost, but far less than having the entire original text repeatedly participate in subsequent requests. The principle for choosing: use /clear when the task is finished or you're completely switching domains; use /compact when the same task still needs to continue but the history is too long—and it's best to do it proactively before leaving or taking a break, rather than waiting for the cache to expire and then catching up, because the latter requires re-reading the full text before compressing.
Don't Leave Claude Idle for Over an Hour
This is the cost black hole from the beginning. The one-hour cache expires; re-reading costs one-tenth of the normal price, rewriting costs up to double—the same message can differ by 20 times in price. Doobie's first message after returning from the gym was just to say "continue," and it cost about 290,000 tokens.
If you're running /loop, the cache doesn't update with it, and running for over an hour will likewise re-read the entire history. His approach: always start a new conversation for loop tasks; finish tasks before leaving for a long time, or run /compact first—compressing before a break is much cheaper than doing it after.
Rules 6 to 9: Use the Right Tools, Stop Wasting Money
Rewind Instead of Arguing
When Claude goes in the wrong direction, you spend five minutes correcting it—each correction adds a round of messages and responses, all of which enter the subsequent context. At this point, type /rewind (or press Esc twice when the input box is empty), go back to the node before the error, and select "restore conversation"; if you also need to roll back code, select "restore code and conversation," then start over with a clearer prompt. Failed attempts no longer remain in the active conversation.
Claim Your Free Reset Credits
When Opus 5.5 launched, paid users received a free usage reset they could save and use at will. The path is Settings → usage → resets; click "reset for free" to zero out your usage. Note that it only works on the web or desktop app—not in the terminal or on mobile—but after resetting, limits are restored across all platforms (including Claude Code). All stored resets have a 30-day validity period, so don't let them expire.
Use /usage to Find Leaks
Type /usage in Claude Code, and it breaks down usage sources line by line by skill, subagent, plugin, and each MCP server, highlighting items that recently accounted for over 10%, such as long context or cache misses. It's recommended to look at a full week of data for a larger sample size. If you don't understand it, just ask Claude: "Look at my usage this week—what are some things I could do to reduce my token consumption?" The AI itself can help you analyze.
Make Claude Talk Less
Output tokens cost about five times more than input tokens. If you ask Claude to rename a file and it replies with a long rethinking process, that money is wasted.
Doobie mentions an open-source skill called caveman that once had 100,000+ GitHub stars, with documentation claiming it could save 65% of tokens—but his own testing averaged about 41%. Still, it's somewhat outdated. A simpler approach is to use Claude Code's built-in concise output style: /config → output style → concise. Claude gives the result first and skips the narration—the workload is unchanged, and it doesn't consume extra context.
Rules 10 and 11: The Last Line of Defense for Agents and Quotas
Downgrade Auxiliary Agents to Sonnet 5.5
Claude Code's auxiliary agent Explore originally ran on the cheaper Haiku, but after an update it was changed to follow the main model—which for most users is Opus. It's like an intern copying documents being billed at a senior engineer's rate. The fix takes ten seconds: tell Claude "make me a custom Explore agent that runs on Haiku," and it will write the file automatically; the custom agent overrides the built-in version, and you can repeat this for other projects. Doobie cites the Spotify team: delegating file reading to a cheaper agent reduces costs by about 90%—your numbers will differ, but the direction of the benefit is the same.
Subagents and Model Routing: Claude Code can delegate auxiliary work—exploring the codebase, reading files, searching—to subagents, with the main agent only receiving summaries returned by the subagents. Which model a subagent uses is determined by configuration; built-in agents adjust their defaults with product updates, so they may quietly switch from the cheaper Haiku to the main model. Custom subagents are defined by writing a Markdown file with frontmatter in the project or user directory, where the model field can specify Haiku, Sonnet, etc.; custom versions override built-in agents of the same name. Pinning high-throughput, low-judgment reading work to a cheaper model is one of the most direct ways to control costs—but it needs periodic review, because built-in defaults can still change with versions.
Set a Cap on Your Usage Quota
Once you hit the limit, Claude continues running at the per-token price to avoid interrupting tasks midway. Be sure to set a monthly cap, especially since agent runs consume quickly. There's a trap: once you enter pay-as-you-go billing, Claude Code's cache shrinks from one hour to five minutes—a trip to the restroom is enough for Claude to re-read the entire history. After entering billing status, it's best to stay on task until it's done.
Rules Expire, Habits Don't
The comparison between old and new rules is itself a reminder: 6 old rules have become obsolete because model versions, default settings, and agent model assignments are all changing. What's truly stable are a few principles—default to medium effort, clarify requirements first, clean context frequently, start a new session when switching tasks, compress before long absences, and delegate auxiliary tasks to cheaper models. Turning these into muscle memory is more useful than memorizing any version of the rules.
One-line Summary
Claude Code's token costs mostly hide in cache expiration and context bloat—eleven rules teach you to plug the black hole.
Paragraph Summary
The article starts from the phenomenon that Claude's one-hour cache expiration can make the same message cost about 20 times more, and systematically lays out Claude Code's token-saving rules. The core idea has four layers: source control (default to medium effort level, have Claude interview you before starting to clarify requirements), context cleanup (uninstall unused skills and connectors, use /clear when switching tasks, /compact before leaving for over an hour), using the right tools (use /rewind to roll back instead of repeatedly correcting, claim free reset credits, use /usage to locate consumption sources, enable concise output style to compress replies), and the agent and quota defense line (downgrade the Explore subagent to Haiku, set a monthly usage cap). The author emphasizes that six old rules have become obsolete, and what's truly stable are these habits: "medium effort, clear requirements, frequent context cleanup, new sessions when switching, compress before leaving, and cheaper models for auxiliary tasks."
Related articles
Build Your First AI Agent with Zero Code: A Claude Code Practical Guide
Build an AI agent in Claude Code with zero code. Learn the full workflow: folder setup, claude.md rulebook, plan-mode briefs, skills, and independent review.
Claude Code Advisor Mode Explained: How Fable 5.2 and Sonnet 5.5 Collaborate on Code
A deep dive into Claude Code's experimental Advisor mode: how Fable 5.2 and Sonnet 5.5 split the work, access requirements, version thresholds, three ways to enable it, Fable's special billing rules, and a fact-check of the "3.4x cost reduction" claim against official docs.
Claude Code Advisor Mode: Two-Model Collaboration for Cost-Effective Coding
Explaining Claude Code's experimental Advisor Mode: primary model writes code, strong model intervenes at key points. Covers version requirements, three activation methods, model pairing rules, and real cost boundaries, clarifying the community's 3.4x savings claim.