74M-Parameter Open-Source Model Partially Outperforms Jev AI in Testing

Fastino AI's 74M-parameter Glider 2.5 outperforms Jev AI in some guardrail tests, showcasing small models' competitiveness on specific tasks.
The article introduces Fastino AI's Glider 2.5 series, ranging from 74M to 300M parameters, runnable locally on consumer hardware. According to hands-on testing shared by a YouTube channel, the 74M-parameter version outperformed the compared Jev AI in some guardrail benchmarks and was used to play Doom, demonstrating its potential in real-time closed-loop tasks. The author cautions that this is a single-source preliminary observation lacking complete benchmark names, score gaps, and testing environment details, so conclusions should be treated as directional reference. For developers, the case shows model size isn't the only variable—on classification, filtering, and rule-based judgment tasks, fine-tuned small models offer high cost-effectiveness and suit local and edge deployment, though full evaluation on proprietary data is still needed before production adoption.
Small Models, Big Impact: Glider 2.5's Real-World Performance
In an era when large language models routinely have tens of billions of parameters, a model with just 74 million parameters has outperformed the Jev AI it was benchmarked against in some tests. According to testing shared by a YouTube channel, the latest model from Fastino AI, Glider 2.5, performed better than Jev AI in guardrail benchmarks in at least a few scenarios. Even more surprising, the 74M-parameter version was also used to play the game Doom during testing—which in itself demonstrates its runnability on consumer-grade hardware.
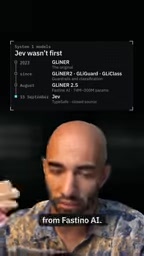
The video's creator explicitly states that the Glider series isn't an entirely new concept, but Glider 2.5 is the latest iteration. He used this version in testing and gave it a "performs very well" assessment. What truly sparked discussion is the contrast between model size and performance—on specific tasks, small models don't have to be "shrunken versions"; they can have their own advantage scenarios.
From 74M to 300M: Feasibility on Consumer Hardware
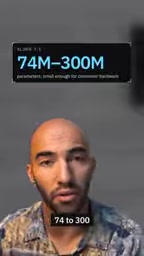
The Glider 2.5 series covers a range from 74 million to 300 million parameters. According to the video, these models are "very small and very easy to run on consumer hardware." The 74M-parameter model stands out especially because it's small enough to deploy smoothly on ordinary devices while retaining usable reasoning capability.
What does this scale of model mean? For developers, local execution, rapid iteration, and low-latency inference become possible without relying on cloud GPU clusters. For researchers, it provides a practical sample for studying the "capability boundaries of small models." Compressing parameter count doesn't necessarily mean capabilities drop to zero—the key is whether training objectives and architecture design match the task.
Cross-Validation in Guardrail Testing
The video's creator mentions that in guardrail benchmarks, Glider surpassed Jev AI on "at least a few" tests. This isn't a comprehensive domination but a lead in specific dimensions. You may not have noticed that conclusions from such comparative testing need to be viewed with caution: benchmark selection, prompt design, and scoring criteria all affect final rankings. The video itself doesn't disclose complete testing methodology and all metrics, so the "partial outperformance" conclusion is better suited as directional reference rather than a definitive verdict.
Based on multi-source information, the comparison between Glider 2.5 and Jev AI currently comes primarily from this YouTube channel's hands-on sharing. The original content doesn't mention specific benchmark names, score gaps, or testing environment details, so deeper cross-validation isn't possible. What can be confirmed is that the tester himself holds a positive assessment of Glider 2.5's performance and considers it competitive on guardrail tasks.
What are Guardrail Benchmarks?
Guardrails in large model applications refer to a set of safety mechanisms that constrain model outputs, with typical goals of intercepting harmful content, jailbreak prompts, sensitive information leakage, or responses that deviate from the task scope. Guardrail benchmarks evaluate the interception rate, false positive rate, and response latency of models or filters by constructing large numbers of adversarial prompts (such as jailbreak templates, leading questions, and boundary instructions). Unlike general capability evaluations, guardrail tasks are essentially classification and judgment problems that don't demand high parameter counts but rely heavily on training data coverage and the specificity of instruction fine-tuning. This precisely explains why a 74M-parameter model might match or even lead larger models in this dimension—the more focused the task, the more easily the scale advantage is offset by data quality and task alignment.
What Playing Doom Means
The video mentions that the 74M-parameter Glider model was used to play Doom in testing. This sounds like a fun demo, but it reflects the model's potential as an agent in real-time decision-making scenarios. The game environment requires the model to react across consecutive frames, imposing requirements on inference speed and context processing that differ from static Q&A. Small models actually have an advantage here—fewer parameters mean lower inference latency, making it easier to meet real-time interaction demands.
Of course, Doom performance can't be directly equated with general capability. It demonstrates more that small models can play a role in specific closed-loop tasks, and such tasks are precisely a microcosm of many practical applications (such as automated control, real-time filtering, and edge inference).
Real-Time Constraints of Small Models as Agents
The core difference between game agents and static Q&A lies in closed-loop timing: the model must complete perception, decision-making, and output within each frame or fixed time interval, and any inference delay accumulates into action lag. Taking Doom as an example, if a single inference takes more than tens of milliseconds, the agent may miss shooting or dodging windows. A 74M-parameter model can achieve high throughput on consumer CPUs, making end-to-end real-time control pipelines possible without offloading inference to the cloud. This also explains why small models are repeatedly mentioned in edge inference, real-time content filtering, and automated control scenarios—their capability ceiling may be limited, but the advantages in latency and deployment cost often matter more than absolute capability in closed-loop tasks.
Implications for Developers
The Glider 2.5 case points to a pragmatic trend: model size isn't the only variable—task fit is equally critical. The fact that a 74M-parameter model can go toe-to-toe with larger models in guardrail testing shows that on tasks like classification, filtering, and rule-based judgment, fine-tuned small models can deliver extremely high cost-effectiveness. For teams needing to deploy AI capabilities locally or on edge devices, such models deserve a place on the evaluation list.
At the same time, remain rational: the video testing is a single-source preliminary observation with limited sample size and testing scope. If adopting for production environments, complete evaluation on your own data distribution is still necessary. Where the ceiling of small models lies remains an open question, but Glider 2.5 at least provides a direction worth watching.
Related articles

Building an AI Employee with Kimi Claw + Obsidian: Knowledge Base and Automation Workflow in Practice
Bilibili creator BlinkAI shares a complete tutorial on building a local AI employee with Kimi Claw + Obsidian: from web chat to delegated Agents, using Skills like Load to Daily and My Context to sink chats into a knowledge base, plus a daily automated Follow Builders task and the Claude for Kimi Obsidian sidebar chat plugin.

Prompt Engineering for Beginners: From Vague Instructions to Precise AI Control
What's the difference between prompts and prompt engineering? This Bilibili course explains four functions of prompts, the six-step engineering process, and three technical limits.

When Agent Fixes Cause New Failures: Observation-Driven Regression Testing
Agent changes often trigger cascading runtime failures. Based on an Arize engineer's talk, this article explains a five-step regression testing loop built on production traces, using LLM evaluators and CI gates to avoid 'fix one thing, break ten.'