A Must-Read for FDEs: A Full Breakdown of 30 Evaluation Metrics for AI LLM Projects

A Bilibili creator breaks down 30 AI product evaluation metrics for FDEs across five capability layers and three core contradictions.
The article systematically organizes 30 quantitative metrics that FDEs should watch in AI product deployment into five layers: model quality, user experience, system efficiency, business value, and the data loop. It opens with three core contradictions—accuracy as entry qualification, cost control as sustainability, and moats as protection against rapid replication by big tech—then details thresholds and trade-offs for metrics such as resolution rate, hallucination rate, RAG recall, token cost, LTV/CAC, and model drift, emphasizing the analytical habit of metric-attribution-optimization.
Title
A Must-Read for FDEs: A Full Breakdown of 30 Evaluation Metrics for AI LLM Projects
Meta Description
A must-read for FDE engineers: a detailed breakdown of 30 evaluation metrics for AI LLM projects, from resolution rate, hallucination rate, and recall at the model quality layer to user experience, system efficiency, business value, and the data loop. A five-layer capability framework for evaluating AI products, with trade-off relationships among metrics and optimization ideas.
Article Content
Whether an AI product is good or not cannot rely on feelings—it has to be backed by numbers. A Bilibili creator systematically broke down the 30 major evaluation metrics that FDEs (Forward Deployed Engineers) need to pay attention to, covering the complete chain from model intelligence to commercial monetization. This framework divides an AI product's capabilities into five layers: model quality, user experience, system efficiency, business value, and the data loop. Each layer has corresponding quantitative levers.
Three Core Contradictions: Accuracy, Cost, and Moats
The creator boils down the key to AI products to three points. First is accuracy, that is, the product's "intelligence level," which determines whether you even have a ticket to enter. Second is the cost battle. AI products are naturally "anti-SaaS"; a model where every deal loses money cannot last, and costs must be controlled. Third is the survival battle, namely where the product's moat lies—can Tencent or Alibaba quickly replicate you? If this problem cannot be solved, the product can easily be a flash in the pan. The creator says bluntly that many AI products today have no moat at all. This is the hardest problem to solve and the one that most needs industry-wide discussion.
Starting from these three contradictions, the metric system is divided into five layers of capability: model quality layer, user experience layer, system efficiency layer, business value layer, and data loop layer. The ultimate goal is to be "smart enough, fast and cheap, and able to self-evolve." The creator used DeepSeekAd to give simple scores to various products, but emphasized that these are for reference only.
FDE (Forward Deployed Engineer) as a role was first used at scale by Palantir in government and defense projects. It refers to engineers who are stationed at the customer site, directly connect with business requirements, and are responsible for adapting a general-purpose platform into a usable system. Unlike traditional pre-sales or implementation consultants, an FDE must understand the customer's business, be able to write code, and define success metrics. In essence, it is a combination of product, engineering, and delivery. In generative AI deployment, the FDE's responsibilities are further amplified: foundation models are general-purpose, while customer data, business processes, and compliance requirements are highly heterogeneous. Someone must be on site to break down metrics, get the harness working, and clearly attribute bad cases. This is also why this article emphasizes that FDEs need a quantitative framework that runs from model quality to commercial monetization—without shared metrics, FDEs cannot align with customers or with headquarters R&D.
Model Quality Layer: How to Measure Intelligence
Model quality is not just the capability of the foundation model. It also includes the interlocking results of intent recognition, RAG recall and ranking, hallucination control, and other capabilities, ultimately presented in the form of resolution rate.
Resolution rate is the ultimate goal: how many users the AI handles on its own without needing human fallback. For customer service products, 60% to 80% is already good; when the business is harder, 30% to 40% is also reasonable. This number is directly related to how much money can be saved for the company.
Hallucination rate concerns trust. In vertical industries such as legal and healthcare, errors are basically intolerable. The creator's experience is that the hallucination rate should not exceed 1%. Achieving 0% completely is unrealistic because the model samples probabilistically, but at least large-scale testing should ensure that no errors that make users uneasy occur. The creator also joked: it is not scary when a model hallucinates; what is scary is when a human hallucinates.
Empty-answer rate is the opposite of hallucination: the system gives correct but useless boilerplate, talking in circles and being overly conservative. The creator suggests keeping the empty-answer rate below 10%.
Intent recognition accuracy is common in Agent scenarios. When different systems or tools are connected downstream, whether the right tool can be selected is key. The requirement is usually around 85% to 95%—if the first shot misses, everything after it is wasted.
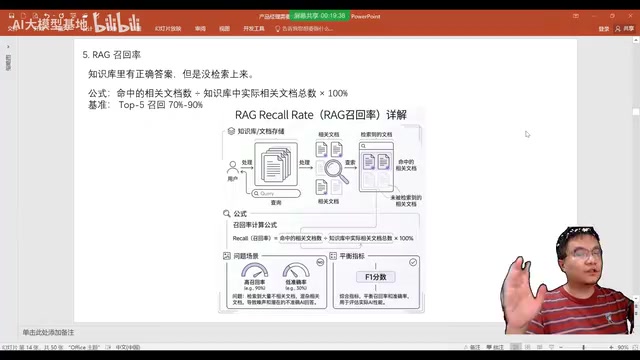
RAG recall rate is the core of knowledge-base question answering. The creator emphasizes that recall generally needs to reach above 90% (the required information is contained in the top 5 recalled results). Only when recall is high is the model less likely to make things up.
Factual consistency distinguishes the root cause of the problem: if the knowledge base recalls the correct knowledge but the LLM answers incorrectly, the foundation model is not good enough and should be replaced; if recall itself is poor, it often has little to do with the foundation model, and the recall and ranking strategy needs optimization.
Skill trigger rate and completion rate are new metrics in Agent scenarios. When multiple Skills are attached to the system, can the corresponding Skill be correctly triggered (trigger rate), and after triggering, can the foundation model correctly execute the workflow described by the Skill (completion rate)? The creator offers an analysis approach: if a Skill is not triggered, first check whether its description is well written and whether multiple Skills interfere with each other, and give each Skill clear boundaries; if it is correctly triggered but does not work properly, the foundation model's capability may be weak.
These question-answering metrics have trade-offs. Intent recognition is the gate; if it is wrong, everything after it is wrong. Hallucination rate and empty-answer rate trade off against each other—suppressing hallucinations often uses conservative strategies, which easily produce correct but useless answers. Recall rate and factual consistency have a sequential dependency. So when performance is poor, do not optimize blindly. First use specific examples to compare against the metrics and locate the stage.
RAG (Retrieval-Augmented Generation) is currently the mainstream architecture for knowledge-base question answering: first vectorize the user's question, recall Top-K relevant chunks from the document library, then insert the chunks into the prompt and hand them to the LLM to generate an answer. It externalizes "memory" into an updatable knowledge base, thereby bypassing the problem of outdated knowledge caused by fixed model parameters. There are three key stages: chunking and indexing determine recall granularity, vector retrieval and reranking determine recall quality, and prompt organization determines whether the model can correctly use the recalled content. The recall rate, factual consistency, and empty-answer rate discussed in this article essentially correspond to the failure modes of these three stages—failure to recall is a retrieval problem, recalling correctly but answering incorrectly is a foundation model problem, and being afraid to answer is often caused by prompts or threshold strategies that are too conservative.
User Experience Layer: Is It Usable End to End?
This layer measures the product from the user's perspective and is more the domain of product manager optimization.
First-round satisfaction: the user gets the desired answer in the first round of interaction. Excellent products usually need this metric to be above 65%, analogous to search—users want the answer on the first page, not after paging through several pages.
Human handoff rate: common in customer service scenarios. If users keep using the product and then all switch to human agents or even call to complain, the AI performance is poor. This is an end-to-end user-perspective measure and complements technical metrics.
Task completion rate: in Agent systems, whether the user's request to write code, file a ticket, or request leave can ultimately be completed successfully. The creator believes that above 40% is already a good AI product—basically, the model can achieve the goal after two or three attempts.
Customer satisfaction is traditional scoring, but pay attention to extreme values: a full score is extreme, and a one-star rating often means the user is already at risk of churning.
System Efficiency Layer: The Key to Whether You Can Make Money
Intelligence and experience determine whether this is a good product; system efficiency determines whether it can stay online long term and whether it can make money.
Token consumption is the biggest cost component. Optimization methods include streamlining prompts, using KV Cache, switching to cheaper models for less complex tasks, and using memory or RAG for context management. The creator particularly emphasizes: whether this round of AI products succeeds is one thing, but the eventual winners are often the companies that can drive costs extremely low. Cost is sometimes more important than revenue.
First-token response time (RT): the wait from input to the first token being emitted, usually on the order of milliseconds. When it cannot be reduced, it is better to give users some cute prompts ("thinking," "working hard") to ease anxiety.
End-to-end latency: how long the entire answer output takes, requiring the foundation model's answers to be relatively concise. In Agent scenarios, latency of tens of seconds is normal.
QPS measures the system's overall throughput capability. The creator gives an example: one GPU handles one request and finishes answering in 5 seconds; 20 GPUs handle 20 concurrent requests, so QPS is 20 divided by 5, equal to 4. But high QPS does not mean short waiting time for an individual user; the two cannot be conflated. The QPS of AI products is much lower than that of traditional internet backends—internet products can have QPS in the hundreds, while an AI Agent project may average 100 seconds per request, so a QPS of 1 is already fast. This is also one reason AI burns money.
Token usage efficiency: the ratio of the total tokens of the input question, prompt, retrieved documents, context conversation, and answer to the tokens of the actually useful answer. Too low efficiency means there is a lot of room for optimization in the system—can the prompt be shorter, can the recalled documents be fewer and more accurate, can the conversation history be trimmed? The creator has encountered many companies that only look at results and do not pay attention to efficiency. Internal use may be acceptable, but when it comes to marketization, they may not be competitive.
System availability: binding to only a single model provider means external failures will directly interrupt the business. Dependence on a specific model must be reduced, which requires good Agent capabilities and harness. Some companies optimize heavily for a certain model, and after switching models all the optimization is wasted—if the harness is not good enough, the product will be overly dependent on a single provider.
KV Cache is one of the core methods for reducing the cost of LLM inference. During autoregressive generation, Transformer recomputes attention over all previous tokens each time it outputs a token, and the computation grows quadratically with context length. KV Cache stores the already computed Key and Value tensors so that subsequent tokens can reuse them directly, avoiding repeated computation and significantly reducing generation latency and compute consumption after the first token. In multi-turn conversations and long-prompt scenarios, if the prefix remains unchanged, the cache hit rate will be high; conversely, frequent prompt changes will invalidate the cache. This also explains why this article lists "streamlining prompts" and "context management" as key points for token cost optimization—they not only reduce input tokens but also directly improve cache reuse.
Business Value Layer: How to Get Customers to Pay
The creator admits that different businesses vary enormously, and AI itself is a non-standard product. "The gap between AI products is bigger than the gap between humans and dogs." How much is model selection and how much is harness depends on the specific business.
Repeat usage rate: if 1,000 people came within 7 days and 600 of them used it more than twice, the repeat usage rate is 60%. AI products should inherently be high-frequency products. If users use it once and never again, the product is not new enough.
Unit resolution cost: do not calculate only compute cost; also include vector storage, labor, fine-tuning annotation, monitoring, and all other inputs. If a cost of 2 million per year serves 10,000 users, the cost per user is 200 yuan, and the product must earn more than 200 yuan per user to be worthwhile. Annotated data and model fine-tuning are sunk costs that do not grow with users, so the more users there are, the more they can be amortized.
Ticket deflection rate: commonly used in customer service scenarios. The average cost per human customer service ticket is 15 yuan. If AI handles 10,000 tickets per month, that saves 150,000 yuan. But note that sometimes it is not that users do not need a human, but that the entrance is too deep and they cannot find one, so they give up—Tencent's human customer service is a typical example.
AI efficiency improvement: check whether end-to-end time is truly shortened. The creator gives the example of an official document writing system: after using AI, writing time actually increased from five hours to six or seven hours because a lot of time had to be spent reviewing. AI Coding is also typical: there are reports that code volume increased by about 130% but workload increased by 300%, and repeatedly revising what was written actually wastes more time. Using AI for the sake of using AI will make AI a burden.
LTV and CAC: AI products must deduct compute cost from LTV, which is different from internet products. If a user pays 500 yuan over their lifetime and compute cost is 100 yuan, the actual profit is only 400; if acquisition cost is 200 yuan, the ratio is only 2 to 1, and it is very likely a loss. The creator's experience is that AI products need to reach 5 to 1 to make money—an acquisition cost of 200 yuan should correspond to at least 1,000 yuan in profit.
ROI: the numerator is quantifiable benefit (user payment, labor savings, efficiency improvement, revenue growth), and the denominator is all inputs such as labor, infrastructure, and machine procurement. ROI must be greater than 1; otherwise every deal loses money.
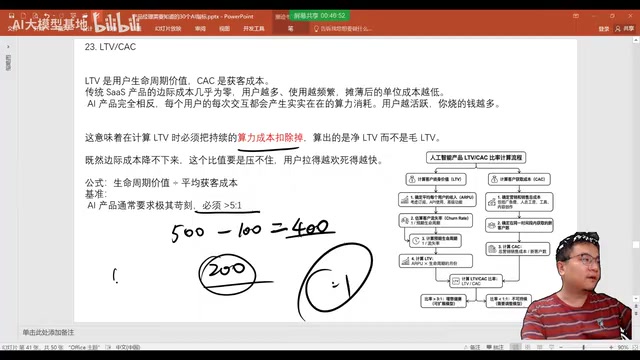
LTV (Life Time Value) and CAC (Customer Acquisition Cost) are unit economics metrics that the SaaS industry has used for years: LTV measures the total gross profit contributed by a user from acquisition to churn, and CAC measures the average marketing and sales expense spent to acquire a paying user. The common healthy line for traditional SaaS is LTV/CAC greater than 3. This article emphasizes that AI products must additionally deduct compute cost from LTV because the marginal cost of LLM inference is much higher than that of traditional software—traditional software serving one more user costs almost nothing, while an AI product incurs an extra GPU cost for every additional call. Therefore, the same 3 to 1 may already mean a loss in AI scenarios. The author's empirical line of 5 to 1 is essentially a safety buffer for compute as a new variable cost.
Data Loop Layer: Does the Product Have a Future?
When doing FDE work or taking on freelance projects, you need to make it clear to the client: this 500,000 is only phase one; there will be phase two and phase three optimization later. This depends on the data loop layer to support the imagination of future value.
Feedback return rate: both positive feedback (likes) and negative feedback (complaints) must be collected to optimize the system. Many companies build AI products without data return; the operator does not know whether users are satisfied or not, and the product cannot be optimized.
Bad case attribution: effectively analyze which of the first four layers a bad case belongs to—not smart enough, unfriendly interaction, or too slow response. Do not be afraid of errors, but know where the error is.
Evaluation set coverage: the creator reminds that benchmark metrics have overfitting problems, equivalent to leaking the exam questions. Many models rank first on leaderboards but fail as soon as they are used; benchmarks may also fail to cover your special scenario. Therefore, build your own dataset and evaluation harness, and make evaluation data close to real scenarios. Benchmark evaluation is like a standardized exam: getting into Tsinghua via the gaokao is impressive, but asking a Tsinghua student to host a livestream may not work.
Model drift rate is a hidden killer. Knowledge changes over time—seasonal recommendations for travel Q&A, ticket prices, and nearby restaurants are all changing; user questions are also seasonal: in March and April people ask about buying houses, in June and July about finding jobs, and in September about school enrollment. Without updates, satisfaction will gradually decline. Cloud services may also quietly downgrade models. The creator draws an analogy with running your own media: content must keep pace with the times.
Execution calibration rate: have the model output with confidence levels attached. If confidence is high, output directly; if the model itself is not satisfied, hand off to a human.
Data flywheel: user usage generates feedback, feedback is collected in a timely manner, problems are located and solved in a timely manner, and user experience is improved. This cycle must keep turning. Do not challenge users' patience. AI products now have no threshold; ideas you can think of, others can think of too. The faster the data flywheel turns, the greater the advantage.
Final Thoughts
The value of these 30 metrics is not in memorizing the numbers, but in establishing the analytical habit of "metric—attribution—optimization." The creator repeatedly emphasizes that different businesses vary enormously and that all thresholds are empirical references. What really matters is: when a problem occurs, be able to locate which layer and which metric are affected, and then optimize accordingly, rather than blindly tuning parameters. For FDEs and technical leads of AI products, this is both an evaluation tool and a common language for talking with customers and bosses.
One-line Summary
A Bilibili creator breaks down the 30 major AI product evaluation metrics FDEs need to watch, covering five capability layers and three core contradictions.
Paragraph Summary
The article systematically organizes the 30 quantitative metrics that FDEs (Forward Deployed Engineers) should pay attention to in AI product deployment, grouping them into five capability layers: model quality, user experience, system efficiency, business value, and the data loop. The author begins by pointing out the three core contradictions of AI products: accuracy determines entry qualification, cost control determines sustainability, and moats determine whether you can avoid being quickly replicated by big tech. Then the article unfolds layer by layer: the model quality layer takes resolution rate as the ultimate goal and gives specific thresholds and trade-off relationships for hallucination rate, empty-answer rate, intent recognition accuracy, RAG recall rate, and more; the user experience layer focuses on end-to-end metrics such as first-round satisfaction and human handoff rate; the system efficiency layer focuses on token cost, latency, QPS, and provider dependence; the business value layer discusses repeat usage rate, unit resolution cost, LTV/CAC, and ROI; and the data loop layer emphasizes feedback return, bad case attribution, self-built evaluation sets, and model drift. Throughout the article, it repeatedly reminds readers that thresholds are only empirical references and that the real value lies in establishing the analytical habit of "metric—attribution—optimization."
Related articles

World's First Humanoid Robot Company Agility Lists on Nasdaq: Buy or Not?
Agility becomes the world's first pure-play humanoid robot company to list on Nasdaq. This article analyzes what the landmark event means for the industry and investors, unpacking the commercialization test and investment framework for the pure humanoid robot sector.

Agent-Browser: A Browser Automation CLI for AI Agents
Vercel Labs open-sources agent-browser, a Rust-built browser automation CLI designed for AI agents, with over 45,000 GitHub stars and command-line-first browser control.

LZ4: The Open-Source Benchmark for Blazing-Fast Compression
Explore the LZ4 blazing-fast compression algorithm: its design philosophy, performance advantages, and wide use in the Linux kernel, databases, and more. How a 12k+ star open-source project became the speed benchmark.