A New Breakthrough in Parallel Thinking: How DPT Makes LLM Reasoning Paths More Diverse

DPT solves the mode collapse problem in reinforcement learning-based parallel thinking by penalizing the prefix similarity of parallel paths.
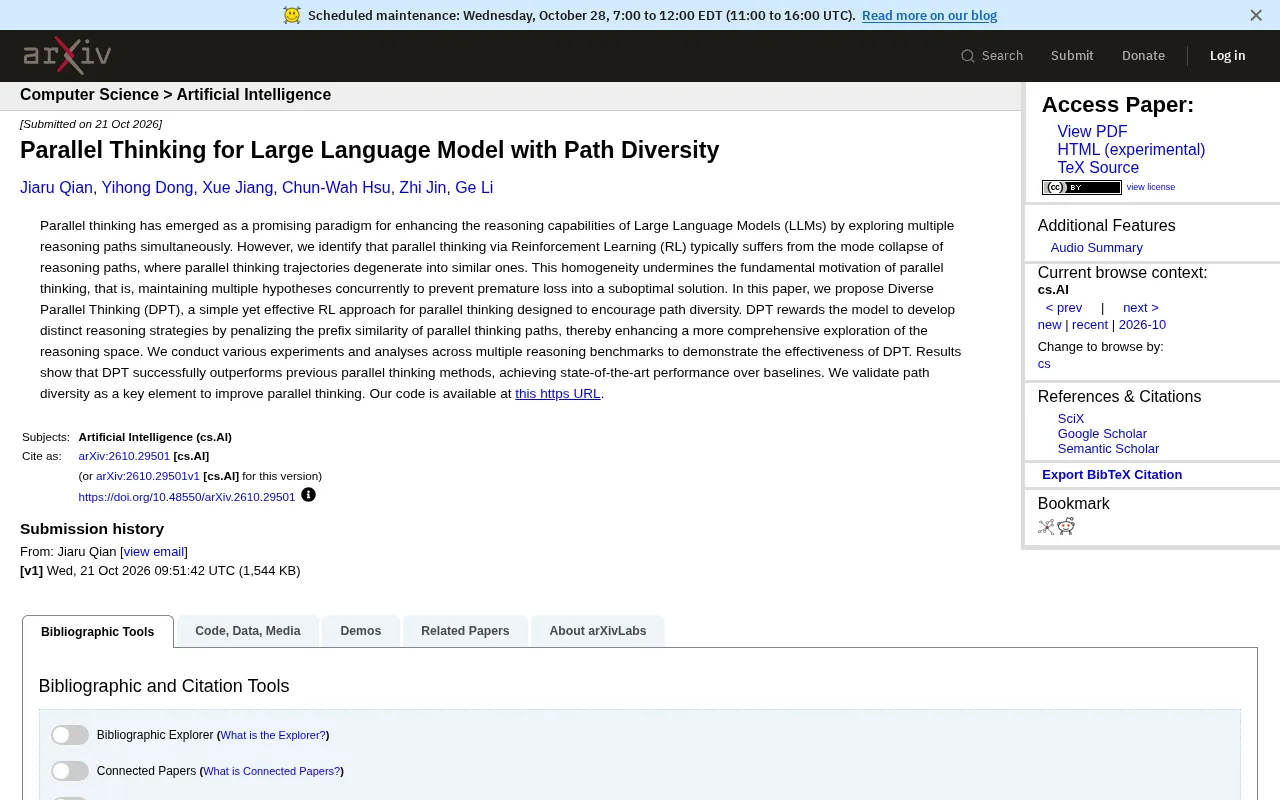
The article points out that when training large models with reinforcement learning for parallel thinking, mode collapse occurs: multiple reasoning paths degenerate into similar trajectories, losing the value of maintaining multiple hypotheses simultaneously. To address this, the researchers propose Diverse Parallel Thinking (DPT), which penalizes path prefix similarity in the reward function to guide the model toward genuinely different reasoning strategies. Experiments show that DPT surpasses existing parallel thinking methods on multiple reasoning benchmarks, achieving state-of-the-art performance and validating path diversity as a key element for improving parallel thinking. The code is open-sourced. The article also discusses open questions such as penalty strength settings and single-path quality trade-offs.
Why Parallel Thinking Needs "Path Diversity"
Having large models explore multiple reasoning paths simultaneously is an effective approach to improving their reasoning capabilities. But a new study finds that the mainstream practice—training models with reinforcement learning for parallel thinking—has a fundamental flaw: mode collapse. The multiple parallel paths a model outputs degenerate into highly similar trajectories, losing the value of "maintaining multiple hypotheses simultaneously" that parallel thinking is supposed to offer, and ultimately may still converge prematurely to suboptimal solutions.
To address this, the researchers propose Diverse Parallel Thinking (DPT), a simple yet effective reinforcement learning scheme whose core goal is to encourage the model to produce genuinely diverse reasoning strategies.
Mode collapse was originally a term in generative models (such as GANs), referring to a generator's tendency to produce only a few kinds of samples and fail to cover all modes of the data distribution. In the reinforcement learning context, mode collapse manifests as a policy converging prematurely onto a few high-reward trajectories, losing its ability to explore. For parallel thinking, the model may discover that a certain type of reasoning path is more likely to earn rewards, and thus repeatedly generates similar trajectories, making the "diversity" of multiple parallel paths exist in name only. Understanding this concept helps explain why DPT must intervene at the level of the reward function rather than merely increasing the sampling temperature or the number of paths.
How DPT Works: Trading a Penalty Mechanism for Reasoning Breadth
The design philosophy of DPT is quite straightforward: in the reinforcement learning reward function, it applies a penalty to the prefix similarity between parallel thinking paths. When multiple paths overlap heavily in their opening stages, the model receives negative feedback and is thus guided to develop reasoning strategies that differ from one another.
The value of this mechanism lies in turning "path diversity" from an expectation into an optimizable objective. Traditional parallel thinking methods often assume that multiple paths will naturally diverge, but in reality reinforcement learning tends to push the model toward the same class of high-probability trajectories. By penalizing prefix similarity, DPT is essentially expanding the model's exploration of the reasoning space.
The paper points out that path diversity is a key element for improving parallel thinking, not an optional byproduct.
Prefix similarity measures how much multiple reasoning paths overlap in their starting stages. Common calculation methods include the n-gram overlap rate of the first several tokens of the paths, edit distance, or the cosine similarity of embedding vectors. If two paths are highly consistent at the beginning, it means the model made the same decision early in reasoning, compressing the room for subsequent divergence. Adding a prefix similarity penalty term to the reward function is equivalent to imposing a cost on "locking onto the same line of thought too early," thereby incentivizing the model to explore different directions early in reasoning. The coefficient of penalty strength needs to be balanced: too strong harms the coherence of individual paths, while too weak makes it difficult to break mode collapse.
Experimental Validation: Surpassing Existing Parallel Thinking Methods
The researchers conducted experiments and analyses on multiple reasoning benchmarks, and the results show that DPT successfully surpasses previous parallel thinking methods, achieving state-of-the-art performance in baseline comparisons.
The significance of this result lies not only in the score improvement but also in the validation of a judgment: the performance bottleneck of parallel thinking may not lie in an insufficient number of paths, but rather in insufficient differences between paths. DPT achieves significant performance gains with a relatively small methodological change, demonstrating that path diversity is indeed a dimension worth optimizing separately.
The researchers have open-sourced the code on GitHub (JiaruQian/DPT) to facilitate community reproduction and further exploration.
Reasoning benchmarks are standardized test sets for evaluating a model's logical reasoning ability; common ones include GSM8K (elementary school math word problems), MATH (competition-level math problems), and StrategyQA (multi-hop commonsense reasoning). These benchmarks typically require the model to perform multi-step derivations, and the answers can be automatically verified, making them suitable for measuring whether parallel thinking methods genuinely improve reasoning depth and breadth. DPT achieving state-of-the-art results on multiple such benchmarks shows that the gains from path diversity are transferable across tasks, rather than effective only for a certain type of problem.
Implications for the Parallel Thinking Paradigm
Parallel thinking holds great promise because it mimics the process by which humans weigh multiple hypotheses simultaneously when dealing with complex problems. But if multiple paths ultimately converge to the same destination, this "parallelism" is merely formal parallelism, and the information gain bought by computational cost is limited.
DPT's contribution lies in locating the problem at the level of the training signal: rather than simply increasing the number of samples during inference, it is better to teach the model to "split up and act separately" during training. This approach has reference value for subsequent research on reasoning enhancement, and also prompts us to re-examine the reward design of reinforcement learning in parallel thinking tasks.
Of course, how to set the strength of the prefix similarity penalty, whether it sacrifices the quality of individual paths, and how well it generalizes across models of different scales all still require more experiments to answer. The paper's open-source code provides a starting point for these follow-up questions.
One-line Summary
DPT addresses the mode collapse problem in reinforcement learning-based parallel thinking by penalizing the prefix similarity of parallel paths.
Paragraph Summary
The article points out that when training large models with reinforcement learning for parallel thinking, mode collapse occurs: multiple reasoning paths degenerate into similar trajectories, losing the value of maintaining multiple hypotheses simultaneously. To address this, the researchers propose Diverse Parallel Thinking (DPT), which applies a penalty to path prefix similarity in the reward function to guide the model toward developing genuinely different reasoning strategies. Experiments show that DPT surpasses existing parallel thinking methods on multiple reasoning benchmarks, achieving state-of-the-art performance and validating that path diversity is a key element for improving parallel thinking effectiveness. The code has been open-sourced. The article also discusses open questions such as setting the penalty strength and the trade-off with individual path quality.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.