A Second Look: What LLM Progress in Pokémon Actually Tells Us
Pokémon as a mirror for LLMs: real progress, clear bottlenecks in long-horizon planning and persistent memory.
The article examines the growing trend of using classic games like Pokémon to evaluate LLM capabilities. Unlike static Q&A benchmarks that are easily gamed, completing a Pokémon game demands sustained goal-tracking, state management, and self-correction over dozens of hours — directly probing persistent memory and long-horizon planning. Community observations confirm real generational improvement, but current successes remain heavily dependent on external scaffolding such as memory databases and sub-goal decomposition systems. Interpreting "AI completed Pokémon" headlines therefore requires clearly distinguishing between the model's own abilities and the broader engineering system supporting it.
When Pokémon Becomes a Testing Ground for AI
Among the many ways to evaluate large language models (LLMs), having an AI attempt to complete a classic Pokémon game has emerged as a surprisingly revealing window into model capabilities. The topic recently sparked discussion on Reddit, where a post titled "I want to be the very best" (Revisiting LLM progress on Pokémon) attempted to reexamine models' reasoning and long-horizon planning abilities through the lens of in-game performance.
Why Pokémon? On the surface, it's a turn-based RPG aimed at children. But for an AI, it represents a comprehensive and genuinely demanding test. Completing the game requires a model to sustain goals, remember maps, manage a team, handle random battles, and self-correct when stuck — all across dozens of hours of continuous play. This is nothing like a standard one-shot Q&A benchmark. It tests coherent decision-making over an extended time horizon.
Why Game-Based Benchmarks Are More Convincing Than Traditional Evaluations
Most traditional LLM evaluations are static: give a question, get an answer. These benchmarks are easy to game and struggle to reflect how a model performs in real, dynamic environments. Interactive tasks like playing a game place the model inside a closed loop that demands continuous action and continuous feedback.
What makes a game like Pokémon especially interesting is the length of the task chain. The model must not only understand what's happening on the current screen, but also remember what its goal was a dozen steps ago, which areas it has already visited, and which moves are available across its team. Any loss of context — any misreading of the map — can send the AI wandering in circles, unable to advance the main story. This exposes current LLMs' genuine weaknesses in "persistent memory" and "spatial reasoning."
In other words, a model that performs impressively on standard math problems may still fail to escape the first town. That contrast is exactly where the value of game-based benchmarks lies — they measure the stability and continuity of capability, not just peak performance at a single point.
The "benchmark gaming" phenomenon frequently discussed in LLM evaluation is formally known as benchmark contamination or dataset leakage: because training corpora are vast and wide-ranging, models may have encountered a test set's questions and answers during pretraining, causing scores to be inflated and failing to reflect true generalization ability. Static Q&A benchmarks — such as MMLU and HumanEval — are especially vulnerable to this problem. The advantage of interactive game tasks is that game states are generated in real time: random events differ each run, and team compositions change at every step, making it impossible for a model to rely on "memorized answers." This gives game-based benchmarks a natural resistance to contamination that static datasets lack, even as they introduce their own engineering challenges around standardization and large-scale automated evaluation.
Progress Is Real, But Bottlenecks Remain Clear
Based on community discussion, there are visible performance improvements across model generations when it comes to Pokémon. Newer models are better at maintaining long-term goals, less prone to falling into repetitive action loops, and more capable of leveraging in-game hints. This suggests that models are steadily improving in long-context handling and tool-use coordination.
But progress doesn't mean the problem is solved. The post's title borrows the line "I want to be the very best" from the anime theme song — with a touch of irony. The reality is that even stronger models still depend heavily on external scaffolding: purpose-built memory systems, structured inputs representing map state, and manually defined sub-goal decomposition. Without these aids, models' ability to independently complete long-horizon tasks remains limited.
This raises a critical question for evaluation: when an AI completes a game, are we actually measuring the model's own capabilities, or the capabilities of the entire engineering system built around it? The two are frequently conflated, and that's precisely the confusion to guard against when interpreting these kinds of "completion achievements."
The "scaffolding" mentioned here refers to an external engineering framework built around a base language model to compensate for its inherent limitations in memory, state tracking, and long-horizon planning. Typical scaffolding components include: a vision-parsing module that converts game screenshots into text descriptions; an external memory database that stores historical actions and map information; a task decomposition system that breaks "complete the game" into hierarchical sub-goals like "find the Gym → defeat the Gym Leader → earn the Badge"; and a watchdog process that detects when the AI is stuck in a loop and forces an intervention. The complexity of this system can rival the model itself. This is why the phrase "AI completed Pokémon" is a highly compressed statement in technical terms — what it actually describes is: "an AI agent, using an LLM as its core decision engine and supported by a purpose-built engineering system, achieved game completion." A more rigorous way to evaluate genuine model progress is to run controlled comparisons while systematically reducing scaffolding dependency.
How to Interpret These Achievements Rationally
For those tracking AI progress, news of an AI completing Pokémon is worth paying attention to — but also worth approaching critically.
The positive case is that it provides an intuitive, reproducible, and hard-to-fake demonstration of capability. The AI either reached the destination or it didn't; the process is visible and clear. Compared to abstract benchmark scores, this kind of "observable" progress is far easier for the public to use as a gauge of what models can and can't do.
At the same time, it's important to guard against overinterpretation. A single successful run may be backed by hundreds of failed attempts, extensive prompt engineering, and customizations built specifically for that game. Treating it as equivalent to "AI now has general-purpose long-horizon planning ability" is a misreading. The genuinely meaningful signal is whether a model can reliably execute longer task chains with progressively less human assistance.
Conclusion
Using games to test AI is, at its core, a search for evaluation methods that better approximate the real world. Pokémon — with its visible difficulty curve, clear objectives, and extended runtime — happens to illuminate the gap between what current LLMs can "think about" and what they can "consistently carry out." The progress is real. So are the bottlenecks. Rather than fixating on which model clears the game first, it's more productive to watch how they gradually overcome the more fundamental challenges: memory, planning, and self-correction.
Related articles
Anthropic IPO Countdown: The Compute Cost Ledger Behind a $2 Trillion Valuation
Anthropic's IPO targets up to $2 trillion — double its Series H valuation. We break down the timeline, compute cost logic, and the key question investor day must answer.
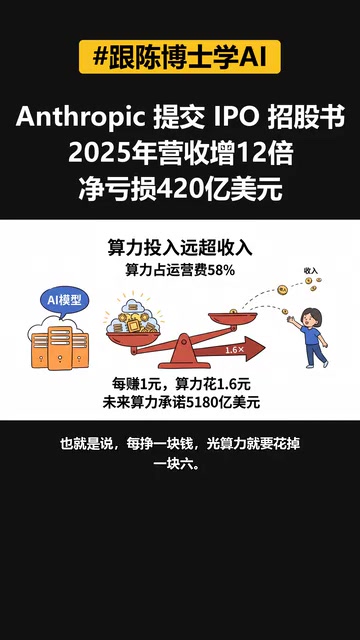
Anthropic IPO Prospectus Revealed: Behind 12x Revenue Growth, the Twin Tests of Compute Costs and Customer Concentration
Anthropic filed its IPO prospectus: 2025 revenue up 12x to $4.6B, net loss $42B including $34B non-cash. Breaking down compute costs, $2T valuation logic, customer concentration risks, and founder control.
Xteink X4 Pro Review: A Mini E-Reader That Fits in Your Pocket, Now More Affordable
Xteink X4 Pro is a 4.26-inch mini e-reader, smaller and thinner than a 6-inch Kindle, magnetically attachable to phones, and cheaper than ever. We analyze its screen, design, use cases, and value.