AI Can Read Neural Network Weights Directly: Do Models Already Exceed Expectations?

Language models can infer network function from plain-text weights; multiple models agree, but the mechanism is unclear.
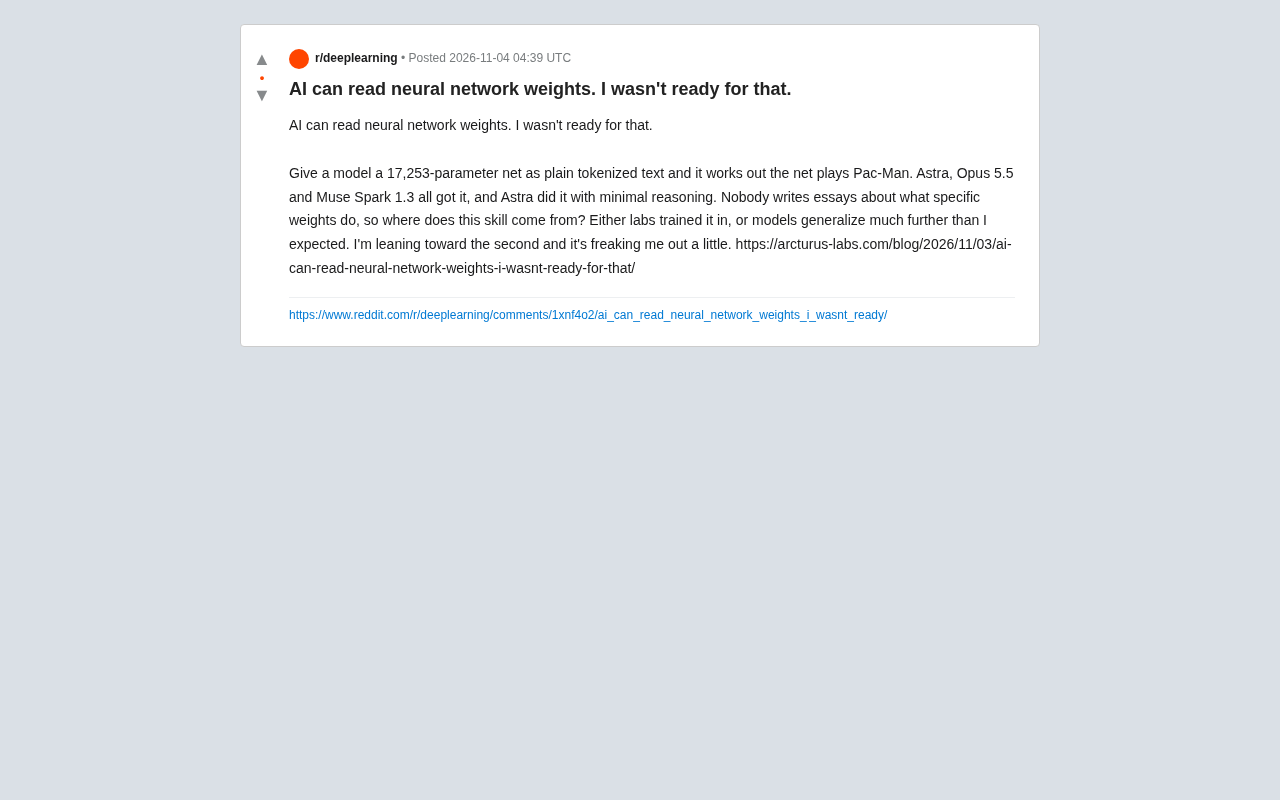
A Reddit post sparked discussion: a developer encoded 17,253 neural network weights as plain text and fed them to language models. The models successfully determined the network was used to play Pac-Man, with Astra, Opus 5.5, and Muse Spark 1.3 all completing the task. The author is puzzled that no "weight-function" paired text exists in training data and leans toward the model's generalization exceeding expectations. Multi-model consistency reduces the likelihood of coincidence, but the experiment lacks reproducible details. If the capability is real, it will have practical significance for AI safety auditing and model transparency research, while also suggesting possible blind spots in current capability evaluations.
A Capability That Surprised Developers: Reading Weights with a Language Model
Recently, a developer's post on Reddit sparked discussion: he fed a language model the weights of a neural network, encoded as a plain-text token sequence totaling 17,253 parameters. The model not only parsed the numbers but determined that the network was used to play Pac-Man. Even more surprising, according to the developer, three models—Astra, Opus 5.5, and Muse Spark 1.3—all accomplished this, with Astra using only a minimal number of reasoning steps.
The post title expresses the surprise bluntly: "AI can read neural network weights. I wasn't ready for that."
The experiment itself is not complicated: feed the weight sequence to the model as ordinary text and observe whether it can extract information about the network's function. But the result points to a more fundamental question: a language model's ability to understand numerical sequences may far exceed what we infer from the premise of "text training."
Where Did the Model Learn to "Read Weights"?
The post author raises a key question: "Nobody has written articles about what specific weights do, so where does this skill come from?"
This is indeed a logical gap. Language model training data consists primarily of human-written text, while neural network weights are numerical matrices produced by training and typically do not appear in internet documentation in the form of "this set of weights implements a Snake game." If the model can reliably infer network function from weight sequences, there are two possible explanations:
- Specifically trained in a lab: A research team, to give models weight-understanding capability, actively constructed weight-function description data pairs for training.
- Generalization beyond expectations: The model acquired some lower-level pattern recognition ability from large amounts of code, mathematics, and system descriptions, enabling it to map numerical structures onto functional semantics.
The post author leans toward the second explanation and admits it makes him "a little uneasy." This unease is not unfounded—if the model can understand numerical patterns cross-modally without explicit supervision, it means its internal representations are more abstract and general than we typically assume.
To understand the difficulty of "weight reading," one must first understand the form of weight tensors themselves. Taking a small policy network as an example, 17,253 parameters are typically distributed across several matrices and bias vectors, with each number being a floating-point value lacking any semantic label. When human engineers inspect these numbers, they see only statistical distributions and norms, and can hardly say directly what task they correspond to. For a language model to perform the same interpretation, it is essentially doing reverse semantic mapping on unlabeled numerical sequences: matching statistical features such as weight matrix dimensions, numerical ranges, and sparsity patterns to functional priors formed during training. This ability can be viewed as cross-modal pattern recognition, but it differs from the human path of "reading code"—it relies more on implicit associations between numerical structures and algorithm descriptions that the model encountered during pretraining.
Multi-Model Verification: Not a One-Off From a Single Model
It is worth noting that this result did not appear in just one model. According to the original post, Astra, Opus 5.5, and Muse Spark 1.3 all completed the task. Multiple independent models showing consistent capability on the same weight-reading task suggests this is unlikely to be an accidental coincidence in one model's training data.
Of course, this is currently just an individual experiment from Reddit, with no public evaluation details, no controlled variables, and no description of what form of judgment the models actually output. To confirm whether this is a stable capability or a coincidence under specific conditions, more reproducible tests are needed. But the consistency across models at least makes the "pure coincidence" explanation less convincing.
The term "generalization" deserves further clarification here. In machine learning, generalization usually refers to a model's predictive ability on unseen data; the generalization discussed here is closer to "out-of-distribution reasoning": the model faces a training data distribution that does not contain "weight-function" paired text, yet can still extract functional information from numerical structures. One possible mechanism is that the model has seen large amounts of code, mathematical derivations, and system architecture descriptions during pretraining, and these texts implicitly encode rules about "which numerical structures correspond to which computations." When weight sequences are input as text, the model may activate these internal representations to complete the inference. This does not mean the model truly understands the role of each parameter, but is more likely a reasonable guess based on statistical patterns. Distinguishing "understanding" from "pattern matching" is crucial for evaluating the practical significance of this capability.
Why This Matters
If models truly possess the ability to infer function from weights, the impact goes beyond an interesting experiment.
On one hand, it means the model's understanding of code and systems may already reach the parameter level. For AI safety research, being able to "read" weights means some form of behavioral auditing of closed-source models becomes possible—a direction worth attention in discussions of model transparency. On the other hand, it also suggests that our current evaluation systems for model capabilities may underestimate the generalization boundary of models on structured numerical data.
The post author describes his feeling as "freaking me out a little," and behind this emotion is a reasonable question: when a model demonstrates capabilities we did not explicitly teach it, is our understanding of it still reliable enough?
This experiment does not provide an answer, but it raises a question worth tracking.
Original link: https://arcturus-labs.com/blog/2026/11/03/ai-can-read-neural-network-weights-i-wasnt-ready-for-that/
Model transparency and behavioral auditing are core issues in the AI safety field. Traditionally, auditing closed-source models relies on external behavioral testing—observing model performance through inputs and outputs—without being able to directly inspect internal parameters. If language models can reliably "read" weights and infer function, this could theoretically serve as an auxiliary auditing tool: without obtaining full weights, one could use textual parameter summaries to detect whether a model hides specific behaviors or backdoors. However, this idea presupposes that weight-reading capability is sufficiently stable and verifiable, and the current experiment is still clearly far from that standard. In addition, weight reading also involves the other side of model security risks: if a model can infer the function corresponding to weights, attackers could also use similar capabilities to reverse-engineer or identify sensitive model structures, requiring a balance between capability disclosure and security protection.
Related articles

India's Microdrama Market Explodes: EloElo Secures $80M Investment from NBCUniversal
EloElo secures $80M from NBCUniversal to boost StoryTV, its microdrama platform with over 33M monthly active users, as India's microdrama market draws global capital.

Acoustic Detection of Multi-Rotor UAVs: Fusing Handcrafted Features with Pre-Trained Embeddings
Study reveals data leakage from random splits in UAV acoustic detection, proposes source-disjoint protocol with stacked ensemble of handcrafted features and YAMNet embeddings, achieving 95.29% accuracy for low-cost drone detection.

The Key Blind Spot in GNN Explanation Evaluation: What Does Deleting an Edge Really Mean?
Deletion fidelity in GNN explanation evaluation is not an intrinsic property of edge rankings: structural deletion and message suppression lead to different conclusions. The paper formalizes the distinction, derives sufficient conditions for equivalence, and validates across nine datasets and GIN/GCN/GATv2 that relative fidelity changes with the intervention, calling for evaluation protocols to explicitly report the intervention method and target quantity.