AI Multi-Stage Pipeline for Androgenetic Alopecia Assessment: From Scalp Images to Clinical Decision Support

Multi-stage AI pipeline combining YOLOv8m and EfficientNet-B5 for automated androgenetic alopecia assessment.
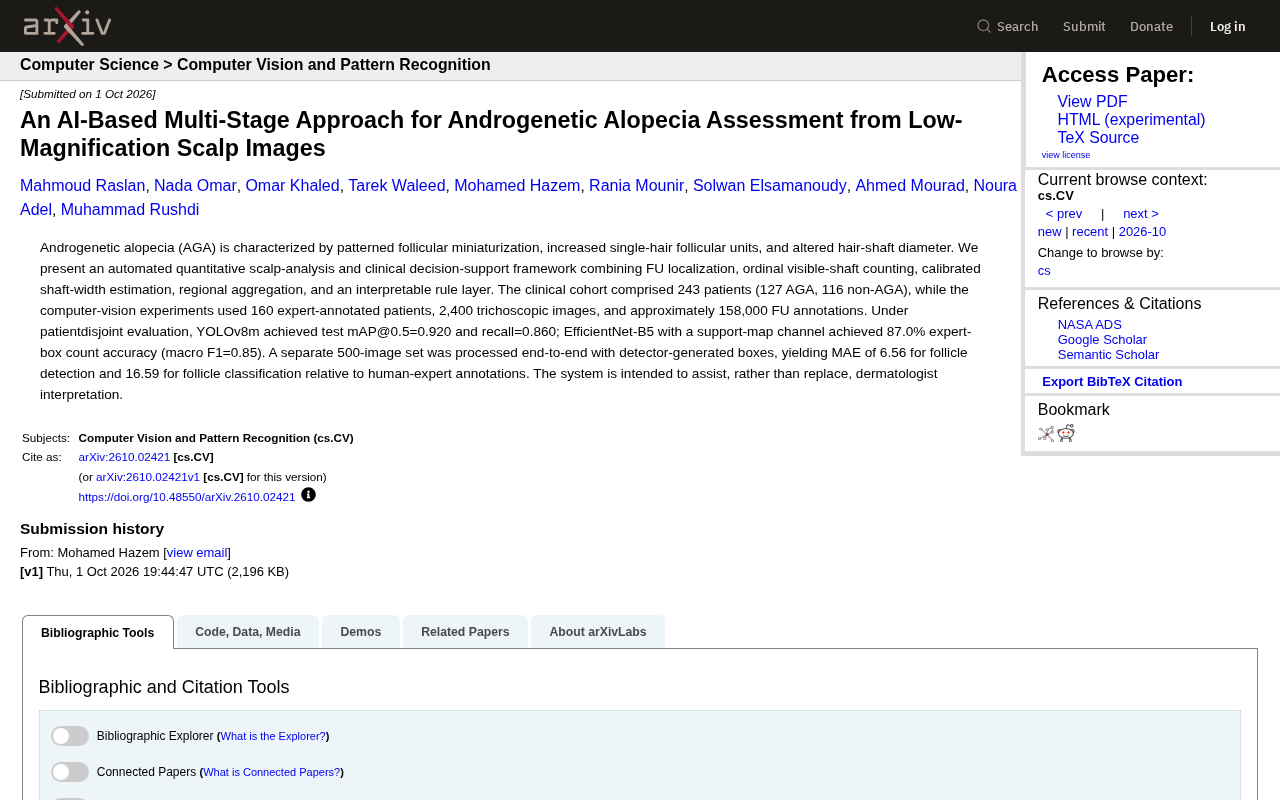
This arXiv study presents a multi-stage AI system for automated assessment of androgenetic alopecia (AGA), chaining follicular unit localization, hair shaft counting, width estimation, and an interpretable rule layer. Built on 243 clinical patients and ~158,000 expert annotations, the core models achieve mAP@0.5 of 0.920 (YOLOv8m) and 87.0% counting accuracy (EfficientNet-B5). End-to-end testing reveals error cascading: detection MAE of 6.56 versus classification MAE of 16.59. The system is explicitly positioned as an assistive tool for dermatologists, emphasizing interpretability over black-box decision-making.
When Hair Loss Diagnosis Meets Computer Vision
Androgenetic Alopecia (AGA) is the most common type of hair loss, characterized by progressive follicular miniaturization, increased single-hair follicular units, and changes in hair shaft diameter. Traditionally, this type of assessment has relied heavily on dermatologists' clinical experience — inherently subjective and difficult to reproduce consistently.
A recent study published on arXiv proposes an AI-based multi-stage automated pipeline aimed at quantifying and standardizing this diagnostic process. Rather than a single monolithic model, the researchers built a framework that chains together follicular unit (FU) localization, ordinal counting of visible hair shafts, calibrated hair shaft width estimation, regional aggregation, and an interpretable rule layer — forming a complete scalp analysis and clinical decision support system.
Dataset Scale and Experimental Design
The study's data foundation is substantial. The clinical cohort includes 243 patients — 127 diagnosed with AGA and 116 without — forming the sample pool for diagnostic validation. On the computer vision side, the experiments drew on data from 160 expert-annotated patients, totaling 2,400 trichoscopic images and approximately 158,000 follicular unit annotations.
This density of annotation provided ample supervised signal for training detection and classification models. Crucially, the study used a patient-disjoint evaluation protocol — meaning patients in the training and test sets were entirely non-overlapping. This design prevents data leakage from the same patient's images appearing in both training and testing, yielding a more realistic estimate of generalization performance.
Performance of the Two Core Models
The system's technical stack centers on two primary models.
YOLOv8m for Follicular Unit Localization
For the follicular unit detection task, the study employed YOLOv8m, achieving mAP@0.5 = 0.920 and recall = 0.860 on the test set. For densely packed follicular targets in medical images, an average precision above 0.9 indicates the detector can reliably localize the vast majority of follicle positions.
YOLOv8m is the medium-sized variant of the YOLOv8 series released by Ultralytics in 2023, built on a single-stage detection architecture. Compared to its predecessors, YOLOv8 introduces an anchor-free detection head and decoupled classification/regression branches, striking a better balance between inference speed and accuracy. mAP@0.5 is the standard evaluation metric in object detection: it measures the mean average precision across all classes at an IoU threshold of 0.5 — in plain terms, a detection is considered correct if the predicted box overlaps with the ground-truth box by more than 50%. In trichoscopic images, where targets (follicular units) are small, densely distributed, and visually similar, achieving mAP@0.5 = 0.920 is practically meaningful.
EfficientNet-B5 for Hair Shaft Counting
The hair shaft counting task is handled by EfficientNet-B5 augmented with a support-map channel, achieving 87.0% counting accuracy against expert-annotated boxes and a macro-average F1 score of 0.85. Separating detection and counting into two dedicated models — each handling its own subtask — is a common strategy in multi-stage pipelines for improving overall accuracy.
EfficientNet is a family of efficient convolutional neural networks proposed by Google in 2019. Its core idea is compound scaling — simultaneously adjusting network depth, width, and input resolution to maximize accuracy gains with minimal parameter increases. B5 is a mid-to-large variant in the series, with stronger representational capacity than the lightweight B0–B2 models, making it well-suited for medical imaging tasks that require capturing fine-grained texture. The support-map channel introduced in this study encodes spatial prior information (e.g., a heatmap of follicle positions from the detector's output) as an additional input channel — essentially telling the classifier "where to look," allowing the counting model to focus on relevant image regions rather than performing a global scan of the entire image.
End-to-End Evaluation: The Real-World Gap
A noteworthy detail in the paper is that the researchers conducted a full end-to-end evaluation on a separate set of 500 images — using automatically generated bounding boxes from the detector rather than manually annotated ones, more closely mirroring real deployment conditions. Under this setup, compared to expert annotations, the follicular detection MAE was 6.56, while the follicular classification MAE rose to 16.59.
These numbers reveal a practical reality: when upstream detection results are imperfect, errors propagate downstream and get amplified. The classification error is markedly higher than the detection error. This highlights a persistent gap between laboratory "ideal inputs" and clinical "real inputs" — a challenge inherent to all multi-stage cascaded systems.
Error cascading is an inherent risk of multi-stage pipeline systems: uncertainty in upstream module outputs becomes input noise for downstream modules. Errors don't merely accumulate at each stage — they can be non-linearly amplified if later-stage logic assumes high-quality inputs. In this study, the detection MAE of 6.56 versus the classification MAE of 16.59 represents a nearly 2.5× difference, vividly illustrating this effect. MAE here measures the average deviation between the model's predicted follicle counts/classifications and expert judgments. This comparison also underscores why the researchers chose to report end-to-end results honestly — it distinguishes between module-level performance and system-level performance, pinpointing where engineering improvements are most needed.
Assistive, Not Replacement: The System's Role
The researchers explicitly emphasize that the system's goal is to assist, not replace, dermatologists' clinical judgment. The framework deliberately incorporates an interpretable rule layer rather than producing a black-box final diagnosis. This design philosophy is especially important in medical AI — interpretability allows clinicians to understand the reasoning behind the system's conclusions, preserving their professional oversight in clinical decision-making.
Starting from low-magnification scalp images and converting hard-to-quantify indicators like follicular miniaturization into computable, comparable numerical values — that is the core value proposition of this pipeline. It offers a viable path toward objective AGA assessment, treatment response monitoring, and standardized documentation.
Closing Thoughts
This work demonstrates the real-world potential of computer vision in quantitative dermatological diagnosis: a solid data foundation, rigorous patient-disjoint evaluation, and honest disclosure of end-to-end error all reflect strong engineering discipline. At the same time, the elevated classification error in end-to-end testing shows that such systems still have ground to cover before independent clinical deployment. As a quantitative assistant for dermatologists, this pipeline may well be a meaningful first step on the road to standardized hair loss assessment.
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.