Alibaba Releases Qwen 3.8 Omni Flash Multimodal Model
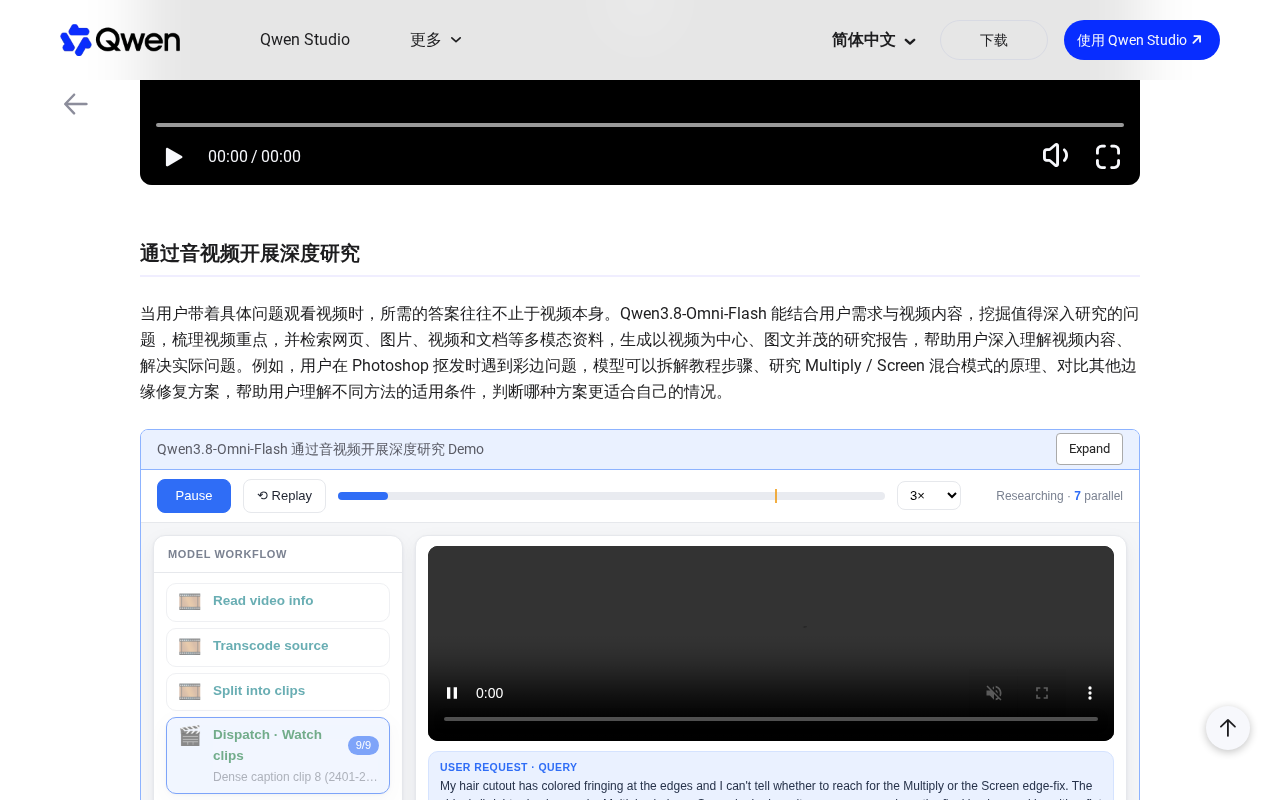
Alibaba's Qwen 3.8 Omni Flash blends full multimodal capability with lightweight, low-latency efficiency.
Alibaba has released Qwen 3.8 Omni Flash, the latest addition to its Qwen series. "Omni" signals cross-modal capabilities spanning text, images, and audio, while "Flash" denotes a lightweight, low-latency design — together reflecting Alibaba's goal of deploying full-modal AI at lower cost. The release drew 25 upvotes and 4 comments on Hacker News, showing continued international developer interest in the Qwen series. Key details such as parameter count, benchmark scores, supported modalities, and licensing terms are still pending official disclosure.
Alibaba Introduces Qwen 3.8 Omni Flash
Alibaba has recently released a new addition to its Qwen series — Qwen 3.8 Omni Flash. The announcement attracted community attention on Hacker News, sparking a moderate level of discussion. As the latest iteration of the Qwen (通义千问) family, the model's name itself signals two key positioning points: "Omni" points to multimodal capabilities, while "Flash" suggests a version optimized for speed and efficiency.
Looking at Alibaba's release cadence with the Qwen series, the company has maintained a high-frequency update cycle in the open-source LLM space, progressively expanding its coverage to handle multiple modalities including text, images, and audio. The launch of Omni Flash continues this technical trajectory.
The Product Logic Behind "Omni" and "Flash"
Omni: Full-Modal Positioning
The label "Omni" (all-capable / omni-modal) in the industry typically implies that a model can simultaneously understand and process multiple input types — text, images, audio, and even video. The value of such models lies in unifying cross-modal tasks under a single architecture, reducing the complexity of deploying multiple specialized models for different tasks.
For developers, an omni-modal model can cover a much broader range of use cases — from image-text understanding and voice interaction to multimodal content generation — all through a single unified interface.
The key distinction between an omni-modal architecture and earlier multimodal models lies in a unified feature space and end-to-end training. Earlier approaches typically combined vision encoders, speech encoders, and language models in a "stitched" fashion, with each module trained independently before alignment. By contrast, next-generation omni-modal models tend to natively process tokens from multiple modalities within a shared Transformer backbone, enabling genuine cross-modal reasoning rather than simple information concatenation. OpenAI's GPT-4o and Google's Gemini 1.5 both follow a similar philosophy. Alibaba's own Qwen-Audio and Qwen-VL series had been gradually evolving in this direction, and the Omni Flash name suggests another step forward on that unified architecture path.
Flash: Efficiency First
The "Flash" suffix in LLM naming conventions typically denotes a lightweight, low-latency, cost-efficient variant. These models generally preserve core capabilities while improving inference speed through architectural optimizations or distillation techniques — making them better suited for latency-sensitive applications or large-scale deployments.
Combining "Omni" with "Flash" reflects Alibaba's intent to strike a balance between multimodal capability and operational efficiency, enabling full-modal features to be deployed at lower cost.
Model distillation is one of the key techniques behind "Flash"-class models: a large "teacher model" is used to train a smaller "student model," allowing the latter to retain strong reasoning ability despite a significantly reduced parameter count. Beyond distillation, quantization, pruning, and operator fusion optimizations at inference time are also common methods. Following the examples of Google Gemini Flash and Anthropic Claude Haiku, leading industry players have established a "flagship + Flash/lightweight" product matrix — the former pursues peak capability, while the latter prioritizes per-token cost and response latency, serving different audiences with varying sensitivity to quality versus cost/speed.
Community Reaction and Interest Level
The announcement received 25 upvotes and 4 comments on Hacker News. Compared to some blockbuster tech topics, this level of engagement is moderate to low — but it does indicate that the international developer community continues to track releases from Chinese LLM providers.
In recent years, the Qwen series has grown increasingly visible in the international open-source community, with its models frequently appearing in benchmark comparisons and open-source leaderboards. The Omni Flash release continues this trend of being followed by the global tech community.
Significance for the Open-Source LLM Landscape
Alibaba's sustained investment in open-source LLMs has become a force that cannot be overlooked in the global large model competition. Multimodal capability is rapidly becoming a baseline expectation for next-generation models, while the release of efficiency-optimized variants directly addresses the real-world deployment demands around cost and latency.
For enterprises and developers, models that balance multimodal capability with efficiency offer greater flexibility. Whether building intelligent assistants, content generation tools, or multimodal search and understanding applications, there is potential value to be gained.
Closing Thoughts
Given the limited public information currently available, key details about Qwen 3.8 Omni Flash — including its specific parameter scale, benchmark results, supported modalities, and open-source licensing — are still pending official disclosure. Developers interested in this model are advised to monitor Alibaba's official channels and its listings on major model hosting platforms for complete technical documentation and empirical benchmarks.
Judging by its name and positioning, Omni Flash represents a clear direction in LLM development: delivering powerful multimodal capabilities in a faster, more cost-effective package for real-world use cases.
Related articles
Andrew Ng on Agentic AI: Cutting Through the Hype to Find Real Value in Agent Development
Andrew Ng's Agentic AI course intro: separating hype from real value, exploring agent workflows in customer service, research, law, and healthcare, and why evals and error analysis define expert-level agent development.
The Netflix Microservices Myth: An Architecture Migration Misunderstood by an Entire Industry
The real story behind Netflix's cloud migration and microservices transformation — and why the entire industry copied the solution while missing the actual problem.
Java 27 Deep Dive: How Default Changes Are Quietly Reshaping Production Environments
Java 27 has just 9 JEPs but changes key defaults: compact object headers on by default, G1 as unconditional default GC, Flight Recorder redaction, and built-in post-quantum TLS 1.3.