Ancher 2.0: The AI Knowledge Workbench That Turns Reading Collections into Deliverables

Ancher 2.0 uses AI to connect the chain from collection to output, aiming to make knowledge management more than storage.
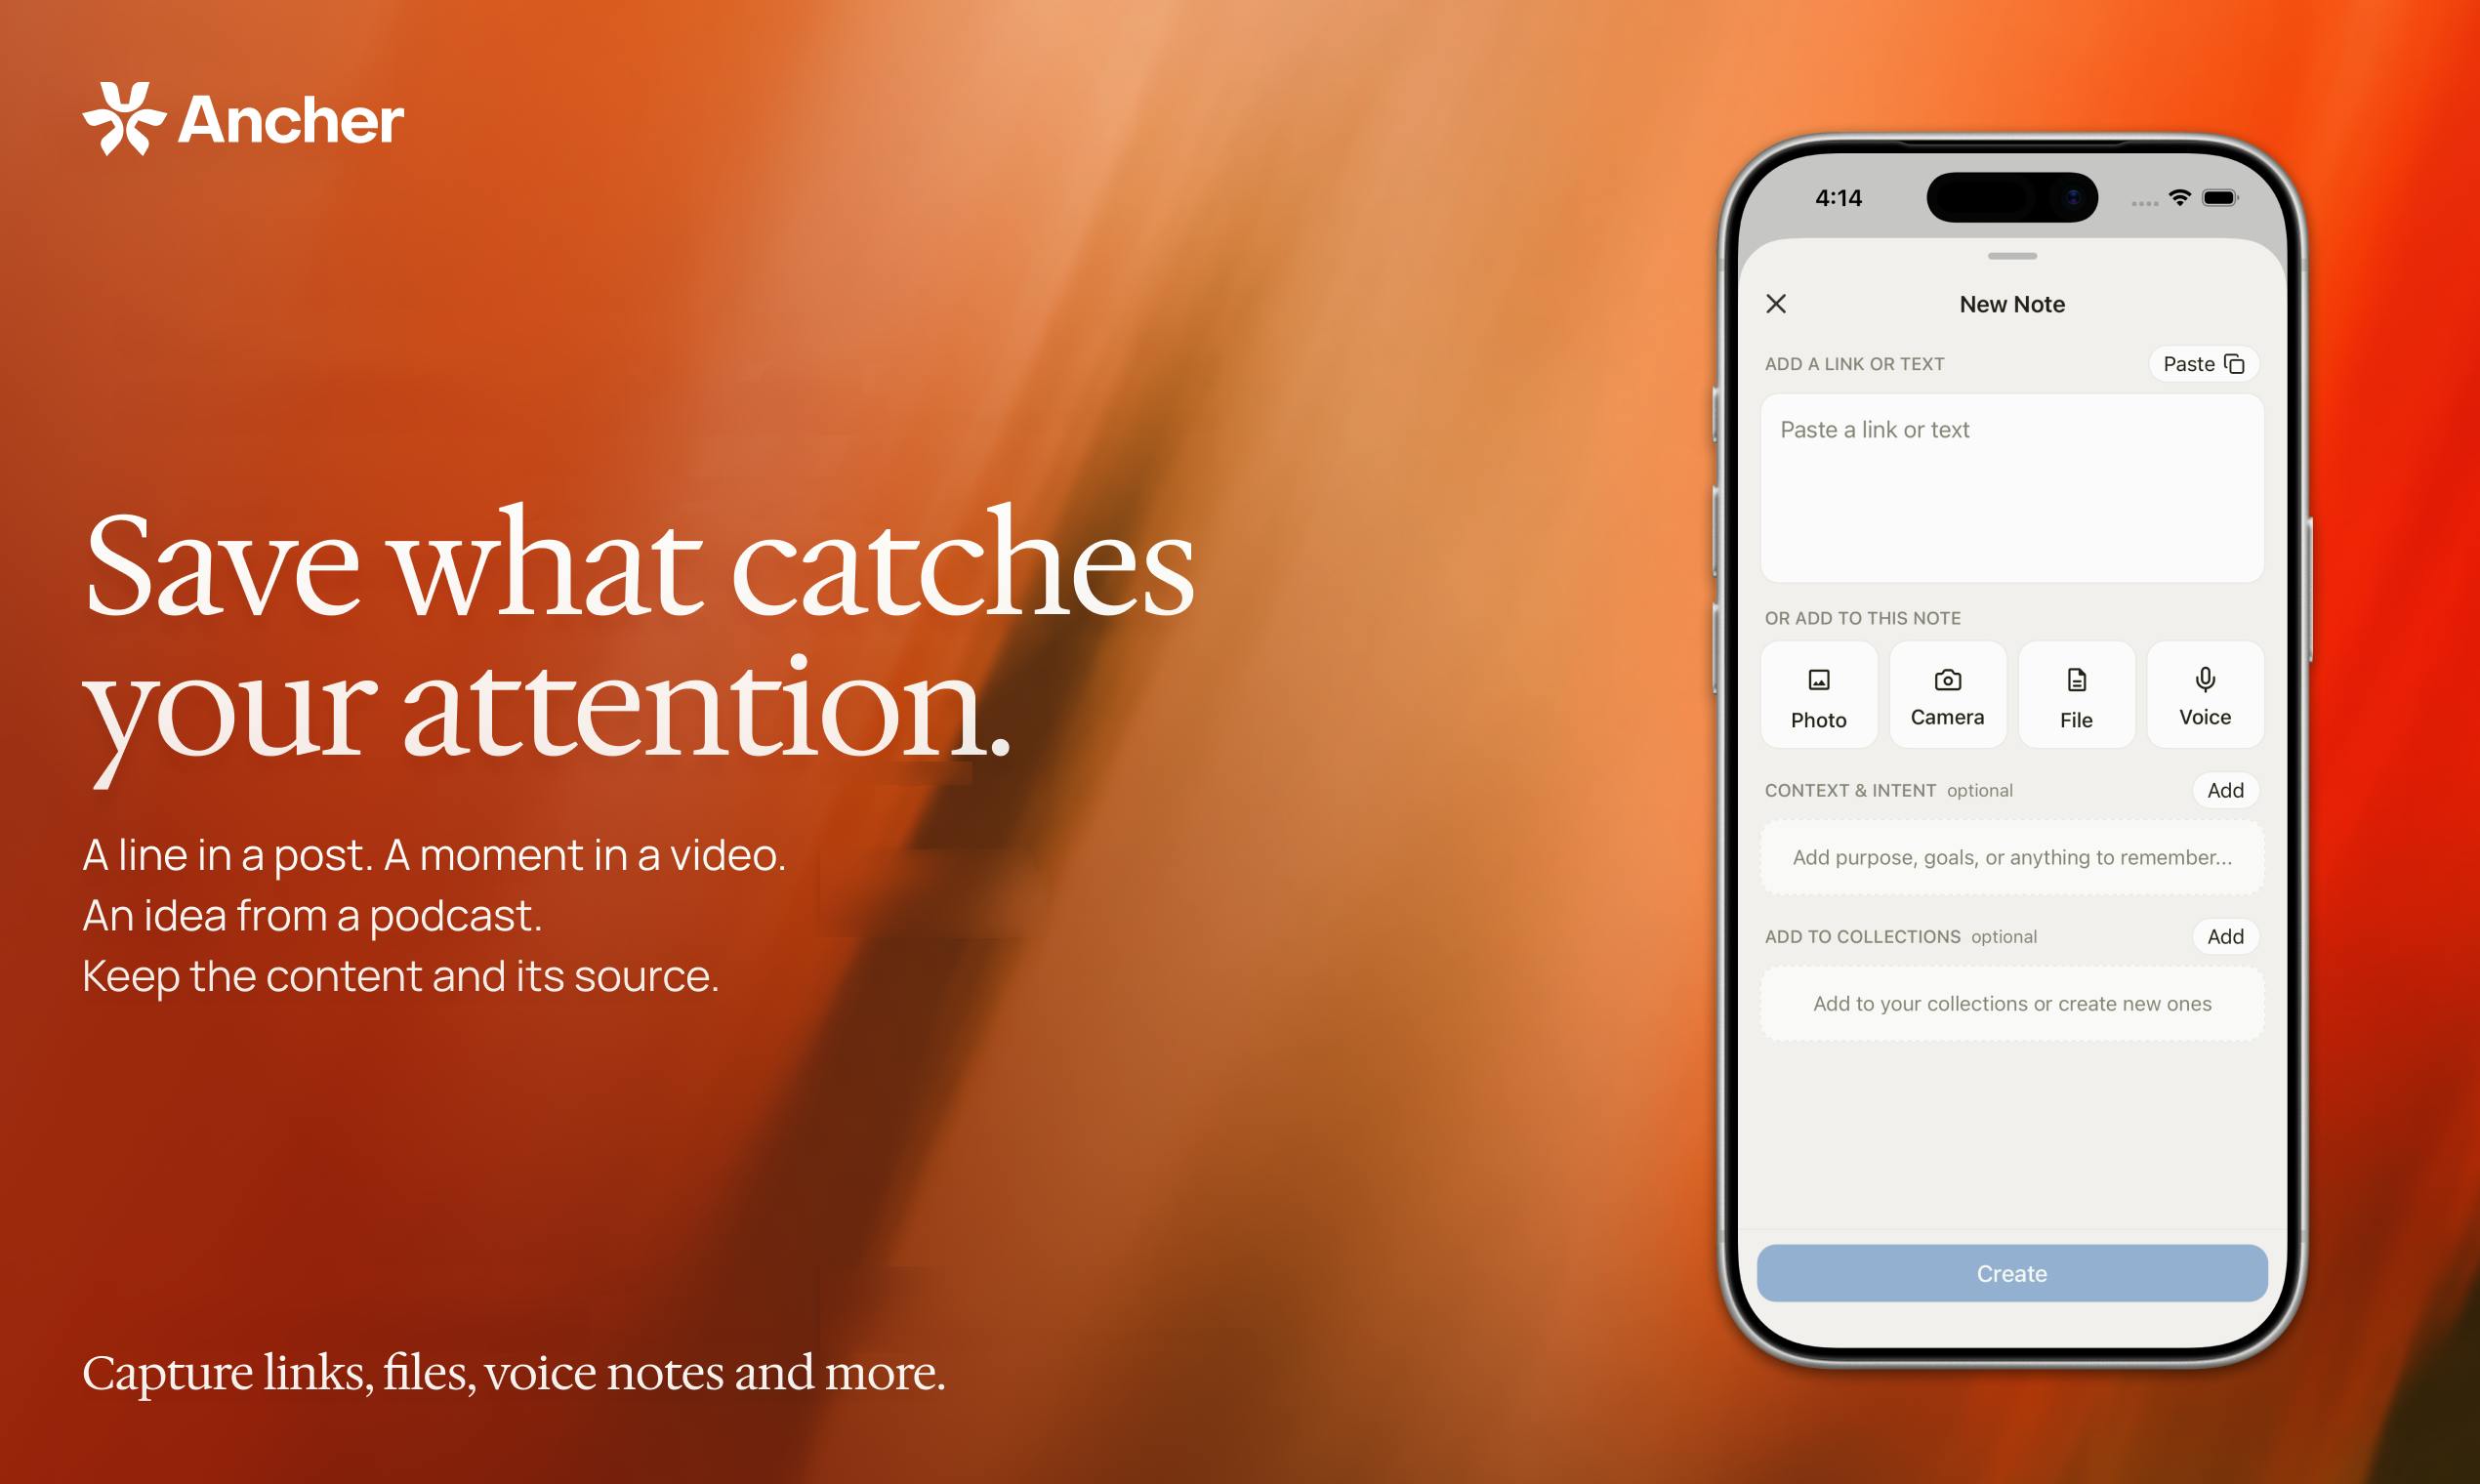
Ancher 2.0 is an AI knowledge workbench that turns everything you read into deliverable work. It eliminates folder-based management and supports uncategorized saving of articles, videos, PDFs, and fragmented thoughts. AI automatically discovers semantic associations between content, addressing the long-standing contradiction of high organizing cost and low reuse. It also offers cross-source search and conversational Q&A. Its core differentiator is output: turning collected material into research briefs, reports, presentations, and content in your own voice. It debuted on Product Hunt with 96 upvotes and a #6 daily ranking. Key open questions include AI association accuracy, real output usability, migration cost, and sustainability.
The Knowledge Management Dilemma: Collecting Never Stops, Output Never Starts
Almost every knowledge worker has been through this loop: you read a great article and bookmark it; you watch a valuable video and save it; you come across an inspiring post and screenshot it. Over time, your collection grows thicker and thicker, but the information that actually gets used is pitifully little.
The core problem isn't laziness — it's that the design logic of the tools themselves is flawed. Traditional note-taking apps require you to manually create folders, add tags, and organize structures. The maintenance cost is absurdly high, which leads most people to eventually give up on organizing, and their collections become a "digital junk yard."
Ancher 2.0 made its debut on Product Hunt with 96 upvotes, 22 comments, and a #6 finish for the day (categories: Productivity / Writing / Notes), attempting to redefine the knowledge workflow with AI. Its core proposition comes down to one sentence: Turn everything you read into work you can deliver.
What Problem Does It Actually Solve
No Organizing, No Losing Things
Ancher's entry point is clear — it eliminates folder-based management. Users throw articles, videos, PDFs, social media posts, and fragmented thoughts into it, without needing to categorize anything in advance. The system automatically connects related content.
The logic behind this: the associations between pieces of knowledge shouldn't be manually established by the user, but automatically discovered by AI based on semantics. When new content you save is related to existing content, Ancher proactively surfaces that connection.
This approach resolves a long-standing contradiction: the cost of organizing knowledge vs. the probability of knowledge being reused. In traditional tools, content you spend a lot of time organizing may not be opened again for months; Ancher bets that AI-powered automatic association can dramatically increase the "reappearance rate" of information.
Semantic association and vector retrieval are the key technologies behind Ancher's "automatic knowledge discovery." Traditional note-taking relies on manual structures like folders and tags to organize information, whereas a semantic system converts each piece of content into a high-dimensional vector (embedding), where semantically similar content sits closer together in vector space. When a user saves new content, the system calculates its vector similarity to existing content and proactively suggests associations once a threshold is exceeded. This approach breaks through the limitations of keyword matching — two articles with completely different wording but related topics can still be identified. However, vector similarity is only mathematical "closeness," which doesn't necessarily equal "usefulness" in the user's eyes — and this is precisely why the original piece worries that association accuracy could introduce information noise.
Cross-Source Search and Q&A
Ancher supports searching and asking questions across all your saved sources. This means you don't need to remember which note, which PDF, or which video a particular piece of information is buried in — just ask in natural language.
This is a typical application of the RAG (Retrieval-Augmented Generation) approach in personal knowledge management: treating your personal collection as a knowledge base and replacing keyword search with conversational interaction. Compared to full-text search in traditional notes, the advantage here is the ability to synthesize answers across formats and sources.
RAG (Retrieval-Augmented Generation) is a technical architecture that combines information retrieval with the generative capabilities of large language models. Its basic process has two steps: first, retrieve content fragments semantically relevant to the user's question from an external knowledge base; then feed those fragments as context to the large model, so it generates answers based on real sources rather than pure parametric memory. Compared to simply letting a model "answer from memory," RAG can significantly reduce hallucinations, improve factual accuracy, and make answers traceable. In personal knowledge management scenarios, the articles, PDFs, and video subtitles a user saves constitute a private knowledge base, and RAG makes it possible to "answer questions using your own collection" — this is also the technical foundation behind Ancher's cross-source Q&A capability.
From Input to Output: The Real Differentiator
The market isn't short on "AI + notes" products, but most stop at "help you summarize" or "help you Q&A." Ancher 2.0's selling point sits closer to the end of the workflow: helping users transform what they've learned into research briefs, reports, presentations, and content creation.
This positioning is worth noting because it touches on the ultimate pain point of knowledge management — collecting doesn't equal mastering, and mastering doesn't equal producing. Many tools have solved "input" and "storage," but few have seriously tackled the "output" segment.
According to the product description, generated content is presented "in your own voice." If this capability is genuinely usable, its value for content creators, researchers, consultants, and similar roles would be very direct: it eliminates the most time-consuming step of converting raw material into a first draft.
From a product logic standpoint, Ancher forms a complete chain:
- Capture — frictionless saving of multi-format content
- Connect — AI automatically discovers associations between knowledge
- Retrieve — cross-source search and conversational Q&A
- Produce — generate deliverable documents and content
None of these steps is a first, but stringing them into a smooth chain is the competitive moat Ancher is trying to build.
Generating content "in your own voice" technically usually relies on style transfer or persona prompting. There are generally two approaches: one is to let users specify a style at generation time; the other is for the system to extract features such as word choice habits, sentence length, and tonal tendencies from the user's past writing samples, and use these as constraints during generation. To achieve something natural and not jarring, the model needs to imitate personal writing style while maintaining factual accuracy, which places higher demands on material selection and context organization. This is also the core metric for judging whether such tools can truly replace the "from material to first draft" step — whether the tone matches and whether the content is accurate directly determines whether the output saves time or instead increases rework costs.
Several Questions Worth Watching
Ancher 2.0's product thinking is clear, but to judge whether it can truly deliver on its promises, the following dimensions are worth ongoing attention:
Accuracy of AI associations. Automatically discovering knowledge connections sounds great, but if the suggested connections are inaccurate or too broad, they instead create information noise. It's currently unclear how precise its association algorithm is.
Whether output quality is truly "usable." Generating reports or presentations from collected material involves multiple steps: information filtering, structural organization, tone matching, and more. The Product Hunt page presents the vision, but actual output quality needs real-world use to verify.
Integration cost with existing workflows. Can data users have already accumulated in tools like Notion, Obsidian, and Readwise be easily migrated in? This question determines the startup barrier for new users.
Sustainability of an independent product. The knowledge management space is fiercely competitive, and big players could launch similar features at any time. Ancher needs to build a sufficiently deep user-data moat to form a long-term barrier.
The competitive ecosystem and migration cost are background factors easily overlooked when evaluating new tools like this. The personal knowledge management space has already formed a fairly mature tool matrix: Notion focuses on all-in-one collaboration and databases, Obsidian is known for local Markdown files and bidirectional links, and Readwise specializes in reading highlights and review. Data users accumulate on these platforms often sits there for years, in varying formats and structures. If a new tool can't provide convenient import paths (such as migration from Markdown, CSV, APIs, or browser extensions), the startup barrier will be very high. Ancher faces not only feature competition but also the challenge of users' existing data inertia — which is also a key variable in whether it can retain new users.
Who Should Pay Attention to This Tool
If you fall into the following groups, Ancher 2.0 is worth adding to your trial list:
- Content creators: need large amounts of reading material and continuously transform it into articles, scripts, or social media content
- Researchers and analysts: frequently handle multi-source information and need to quickly produce research briefs or reports
- Consulting and strategy roles: intensive information input with high-frequency demand for structured output
Conversely, if your requirement for knowledge management is simply "find a place to store links," or you already have a well-functioning manual management system (like a heavy Obsidian user), Ancher's appeal may be limited.
Ancher 2.0 represents a clear product direction: the endgame of knowledge tools isn't a better collection box, but a shorter path to output. Whether this path can be paved depends on how deeply AI can go in "understanding personal knowledge."
One-line Summary
Ancher 2.0 uses AI to connect the chain from collection to output, trying to make knowledge management no longer stop at storage.
Paragraph Summary
Ancher 2.0 is an AI knowledge workbench that advocates turning everything you read into deliverable work. It eliminates folder-based management, supports uncategorized saving of articles, videos, PDFs, and fragmented thoughts, and uses AI to automatically discover semantic associations between content, resolving the long-standing contradiction of "high organizing cost, low reuse probability." The product also offers cross-source search and conversational Q&A, using natural language to retrieve your personal knowledge base. Its core differentiation lies at the output end: transforming collected material into research briefs, reports, presentations, and content, presented in the user's own voice. The product debuted on Product Hunt with 96 upvotes and a #6 finish for the day. The article also notes that AI association accuracy, actual output usability, migration cost, and sustainability remain key questions yet to be verified.
Related articles

JobRunner MCP Server: AI Agents Can Now Fix Failed Java Jobs
JobRunner launches an open-source MCP server enabling AI agents to view cluster status, diagnose failures, and recover Java jobs—incident response from any cloud coding environment or existing agent.

MLAI Digital Launches 9 Security Agents: MCP Server Safeguards the Full Lifecycle of Agentic AI
MLAI Digital launches Security MCP Server with nine built-in specialized security agents covering vulnerability discovery, attack simulation, prompt injection detection, API and infrastructure assessment, and accelerated remediation—embedding security validation across the full Agentic AI lifecycle from development to production.

Running Isaac Lab on H100 GPUs: Exploring Better Approaches
Exploring optimization methods for running Isaac Lab on NVIDIA H100 GPUs, including MIG configuration, mixed precision, TensorRT acceleration, and community experience to improve robotics simulation and reinforcement learning efficiency.