Building a Bank KYC Document Management Module with Claude AI: A Practical Guide

Developer uses a two-phase Prompt strategy with Claude to convert a KYC module from mock data to a real database-driven compliance system.
This article documents a developer's hands-on process of overhauling a KYC document management module in an enterprise loan application. The core methodology is a "two-phase Prompt" approach: the first Prompt has Claude perform a read-only audit of the existing codebase and database, with explicit constraints against modifying anything; the second delivers the implementation instructions, emphasizing reuse of existing services and a centralized document table. Code was deployed file-by-file with incremental validation, ultimately achieving a full end-to-end workflow for uploading, reviewing, rejecting, and downloading documents across PAN cards, passports, driver's licenses, Voter IDs, and more — with direct database queries confirming real data persistence.
From Mock Data to Real Business Logic: KYC Module in Practice
In the development of enterprise-grade loan applications, KYC (Know Your Customer) document management is an unavoidable core module. This article documents how one developer used Claude AI to transform a KYC page that previously only displayed mock data into a fully functional module capable of real-time database interaction.
The KYC module covers a comprehensive range of document types: PAN cards, passports, driver's licenses, Voter IDs, GST business documents, and general file uploads. The development goal was clear — these menu items shouldn't just open; they needed to behave like a real application, supporting refresh, Excel export, document number updates, file uploads, and persistent database storage.
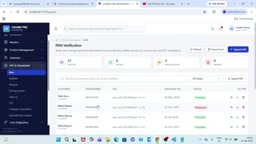
Before the overhaul, information like PAN and Aadhaar numbers were hardcoded mock data — static displays with no interactivity. The core task of this iteration was to transform this "hollow shell" into production-ready functionality with update, validation, and storage capabilities.
KYC (Know Your Customer) is a mandatory compliance requirement in financial regulation, rooted in Anti-Money Laundering (AML) and Counter-Terrorism Financing (CFT) regulatory frameworks. In India, KYC compliance is jointly overseen by the Reserve Bank of India (RBI) and the Securities and Exchange Board of India (SEBI) — lending institutions must verify borrower identity before disbursing loans. A PAN card (Permanent Account Number) is a unique tax identification number issued by India's Income Tax Department, while Aadhaar is the government's 12-digit biometric identity number. Both are required for credit applications. GST (Goods and Services Tax) business documents are used to verify the legal registration status of a corporate entity. This document ecosystem directly shapes the KYC module's data structure design — different documents have different validation rules (e.g., PAN format is ABCDE1234F), which is one key reason the developer chose a "centralized document table" over separate tables for each document type.
Two-Phase Prompting: Audit First, Implement Second
The most instructive aspect of this case is the author's two-phase Prompt strategy — rather than jumping straight to code generation.
The first Prompt was for a read-only audit. The author explicitly told Claude: this is "Part 7" of an enterprise loan application, the KYC pages already exist, and listed each page by name. The critical constraint was — do not modify, delete, rename, or create any existing files or database tables. The prompt also included database instance details, Windows Authentication configuration, and a list of existing tables to prevent the AI from making incorrect assumptions.
Claude returned a comprehensive read-only audit report, confirming "no files or database objects were altered," and summarized the existing records from Parts 3, 4, and 5 of the project. This step was essentially having the AI "read and understand" the entire codebase's current state.
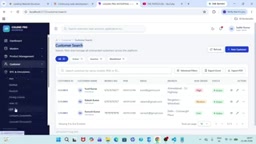
The second Prompt was the actual implementation instruction. The author asked to convert the entire KYC document module from mock data to a real database-backed module, with several key architectural principles:
- Do not create duplicate APIs or schemas
- Reuse existing services, utilities, and authentication mechanisms
- At the database level, design and create the minimum necessary new tables
- Prioritize a centralized document table over separate tables for each document type
Notably, the author openly admits that both structured Prompts were drafted with ChatGPT's help — first explaining the goals in sequence, then having ChatGPT convert them into well-structured prompts, which were finally passed to Claude for code generation. This is a "use one AI to write prompts, use another AI to execute" combination workflow.
The practice of "using AI to help write Prompts" has sound practical logic behind it. When describing complex enterprise requirements directly to a code-generation AI like Claude, the ambiguity of natural language can cause the model to make excessive assumptions — such as creating new tables on its own, renaming existing APIs, or ignoring existing authentication middleware. By first using ChatGPT to organize goals into structured, constraint-laden prompts, you explicitly separate "requirements analysis" from "instruction writing." Structured Prompts typically include: context (which part, tech stack), explicit prohibitions (a not-to-do list), input parameters (database connection method, existing table names), and expected output format (file list + SQL scripts). This approach reduces ambiguity for the AI and allows developers to review the completeness of instructions before execution — a low-cost substitute for a formal requirements review.
Incremental Deployment: Database Scripts and Service Files
Claude's implementation was delivered as a plugin-style package, containing a SQL database script and a set of new source files to be created. The author took a conservative approach of creating and executing files one by one:
- Execute the database scripts first
- Create
upload.tsunderserver/src/middleware(file upload middleware) - Create
auditlog.service.tsunderserver/src/services(audit log service) - Create and populate all remaining Claude-generated files one by one
After completing all files, the author restarted the server and mock environment, then verified success by checking the API health endpoint. This "one file at a time" validation approach, while somewhat tedious, effectively reduces the risk of large-scale changes going wrong in an enterprise codebase.
upload.tsandauditlog.service.tsserve distinct roles in this module and are worth explaining individually.upload.tsis an Express/Fastify middleware — typically built onmulteror a similar library — that handles file upload logic: processing multipart/form-data requests, validating file types and sizes, writing files to local server paths or object storage, and injecting file paths into the request context for downstream routes.auditlog.service.tsimplements operation audit tracking — recording "who did what to which record and when." In financial compliance scenarios, this is a mandatory requirement; regulators may demand complete operation logs at any time to demonstrate KYC process compliance. Extracting audit logic into a dedicated service rather than scattering it across business routes also reflects the Separation of Concerns architectural principle.
Feature Validation: A Complete Document Review Workflow
After the module went live, the author tested each feature individually, validating a relatively complete document review workflow.
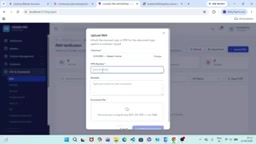
Using PAN cards as an example: four real customers created in the customer module (such as Ramesh) appear synchronously on the KYC page. After selecting a customer, you can enter a new PAN number, add remarks, and upload a document. Upon successful upload, the system shows "document uploaded successfully," the PAN number updates immediately, and the document status defaults to "pending."
The review workflow covers multiple status transitions:
- Mark as verified: Flag the document as verified
- Reject: Requires a rejection reason
- Download / View: Download or view the uploaded document
- Delete: Remove the document record
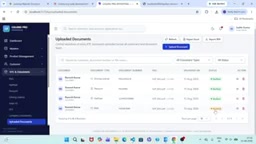
The same workflow was validated across all document types: Aadhaar, passport, driver's license, Voter ID, and business documents. The top-level filters (verified / pending / rejected) work correctly, as do document type search, Excel export, refresh, and record statistics (total count, pending count).
Finally, the author queried the database tables directly to verify: all processed data — including stored filenames, file paths, and review statuses — was genuinely persisted, and previously deleted records were confirmed removed from the database. This confirmed that the frontend operations and backend storage were fully connected end-to-end.
Key Takeaways for AI-Assisted Enterprise Development
While this case doesn't involve a particularly complex tech stack (TypeScript backend + SQL database), it demonstrates a replicable AI-assisted development methodology:
- Constraints first. Before letting AI touch any code, use a clear Prompt to define "what not to touch" and provide the real database and architecture context. This is key to preventing AI from inadvertently modifying existing systems.
- Separate audit from implementation. Having the AI do a read-only analysis to understand the current state before generating any changes is more controllable than a one-shot approach.
- Reuse over rebuild. Emphasizing the reuse of existing services, authentication, and utilities — and using a centralized document table instead of multiple scattered tables — reflects a commitment to architectural cleanliness.
- Manual incremental deployment. Even when AI generates all the files, the developer still chose to create them one by one and restart to verify, keeping a human in the loop as a quality gate.
The author notes that the next step is to apply the same methodology to other modules like Leads, continuing to transform the mock application into a real, production-ready business system. For teams looking to use Claude or similar tools to assist with enterprise backend development, this "two-phase Prompt + incremental deployment" workflow offers a genuinely useful reference model.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.