Building an Agent-Based Security Review System on Databricks
Upgrade security reviews on Databricks from rule-driven scripts to goal-driven intelligent agents with autonomous reasoning.
This article introduces an agent-based enterprise security review approach built on Databricks. While traditional automation scripts handle deterministic checks, they fall short in complex scenarios requiring contextual judgment and multi-source correlation. LLM-powered agents work in a goal-driven manner, dynamically collecting information and forming reasoning chains to cover gray areas rules cannot reach. Databricks' unified data and AI environment lets agents access code repos, permission inventories, and access logs directly. The recommended implementation strategy treats agents as incremental additions to existing automation, maintains clear responsibility boundaries, and preserves a human-in-the-loop review mechanism to build trust gradually.
From Automation to Intelligent Agents: The Evolution of Security Reviews
Security reviews have long been one of the most time-consuming and repetitive tasks for enterprise security teams. As noted in the source material, teams had already introduced automation into certain stages of the security review process — and those automation scripts delivered real value by handling standardized, predictable checks.
But traditional automation has clear limitations: it only covers the parts of a workflow that have been explicitly coded. The moment a task requires judgment, reasoning, or cross-contextual correlation, human intervention is still necessary. This is precisely the gap that Agent (intelligent agent) technology aims to bridge.
Why Build Agents on Databricks
As a unified data and AI platform, Databricks offers natural advantages for building agent-based applications. Security reviews are fundamentally data-intensive tasks — they require reading code repositories, configuration files, access logs, permission inventories, and large volumes of both structured and unstructured information.
Deploying agents on Databricks means you can directly leverage the platform's existing data pipelines, compute resources, and large model serving capabilities, without spending extra effort on data migration or environment setup. Agents can access data, run analysis, and generate review conclusions all within the same environment, forming a closed loop.
Databricks' core product suite includes a unified analytics engine built on Apache Spark, the Delta Lake storage layer, the MLflow model management platform, and the recently introduced Mosaic AI (formerly related to Dolly/DBRX) large model capabilities. For agent applications specifically, Unity Catalog provides unified permission management across data assets — which is especially critical in security contexts. Agents themselves must be subject to fine-grained access controls when calling various data sources, to prevent agents from becoming a new vector for privilege abuse. Storing agents' reasoning processes, tool call logs, and final conclusions within the same platform also simplifies post-hoc auditing and compliance evidence — aligning with security teams' fundamental requirement for traceability.
The Core Difference Between Agents and Traditional Automation
Traditional automation is rule-driven: judgment logic is written in advance, and the system follows a fixed path. Agent-based solutions are goal-driven: given a security review objective, the agent can independently decide what information to collect, which tools to invoke, and how to structure its reasoning chain.
This distinction is especially critical in security contexts. Security threats are often highly context-dependent — the same configuration can carry completely different risk levels depending on the business context. Agents can integrate information from multiple sources to make holistic judgments, filling in the gray areas that hard-coded rules struggle to cover.
From a technical architecture standpoint, agents in the security domain are typically built on a "tool calling + reasoning loop" pattern — i.e., ReAct (Reasoning + Acting) or similar frameworks. After receiving a review objective, the agent repeatedly cycles through "think → call tool → observe result → think again" until it reaches a conclusion. The tools available to it may include static code scanners, permission query APIs, threat intelligence databases, log search interfaces, and more.
This is fundamentally different from the linear execution of traditional automation scripts. Agents can dynamically adjust their next action based on intermediate results — for example, upon detecting an anomaly in a service account's permissions, automatically tracing its recent access logs without needing a pre-written branch in the logic. This dynamic dispatch capability is precisely what makes it possible to handle the gray-area problems inherent in security reviews.
Key Considerations for Real-World Implementation
Based on the practical path reflected in the source material, integrating agents into security reviews is not an overnight transformation — it's an incremental evolution built on top of existing automation. This suggests a pragmatic implementation approach:
- Preserve effective automation: Rule-based checks that are already running reliably don't need to be replaced. Agents should complement, not substitute.
- Define clear boundaries for the agent's responsibilities: Let agents handle complex tasks requiring reasoning and correlation; leave simple, deterministic tasks to traditional scripts.
- Human-in-the-loop: Security reviews involve high-stakes decisions. Agent conclusions should be reviewed by humans, especially before the system matures.
"Human-in-the-loop (HITL)" is an important principle in reliable AI system design — it means preserving the ability and mechanism for human intervention at critical nodes in an automated workflow. In security review contexts, HITL can take forms such as: having the agent generate a structured report for security engineers to review after completing initial analysis; automatically closing high-confidence, low-risk findings; and mandating human escalation for ambiguous or high-risk findings — a tiered triage strategy.
As an agent accumulates sufficient historical performance data in specific scenarios, teams can make evidence-based decisions to gradually expand the agent's autonomous decision-making scope. This creates a progressively built trust relationship, rather than delegating full authority to the automated system from day one.
Implications for Enterprise Security Teams
The value of this practical case lies in demonstrating the real-world applicability of large model agents in actual enterprise security workflows — not merely as a concept demonstration. For teams evaluating AI security tools, the key is not to pursue full automation, but to find the right division of labor among humans, traditional automation, and agents.
As data platforms and large model capabilities become more deeply integrated, unified environments like Databricks may become a critical vehicle for enterprises building vertical-domain agent applications. Security reviews are just a starting point — the same pattern can extend to compliance auditing, incident response, and many more scenarios.
Note: Due to the limited scope of the source material, technical implementation details in this article have been reasonably extrapolated based on general practices in security review and agent technology. Refer to the official original for specific architecture details.
Related articles
Anthropic IPO Countdown: The Compute Cost Ledger Behind a $2 Trillion Valuation
Anthropic's IPO targets up to $2 trillion — double its Series H valuation. We break down the timeline, compute cost logic, and the key question investor day must answer.
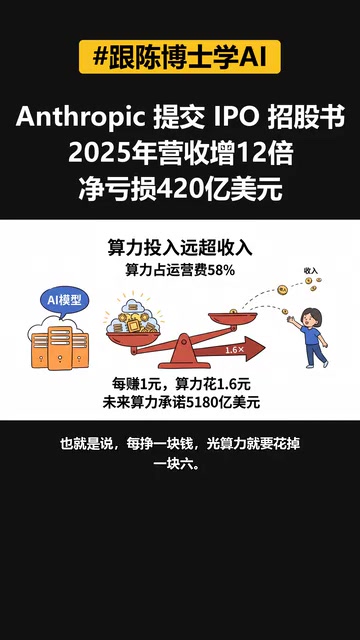
Anthropic IPO Prospectus Revealed: Behind 12x Revenue Growth, the Twin Tests of Compute Costs and Customer Concentration
Anthropic filed its IPO prospectus: 2025 revenue up 12x to $4.6B, net loss $42B including $34B non-cash. Breaking down compute costs, $2T valuation logic, customer concentration risks, and founder control.
Xteink X4 Pro Review: A Mini E-Reader That Fits in Your Pocket, Now More Affordable
Xteink X4 Pro is a 4.26-inch mini e-reader, smaller and thinner than a 6-inch Kindle, magnetically attachable to phones, and cheaper than ever. We analyze its screen, design, use cases, and value.