Building an AI Directory Content Pipeline with LangGraph and Contentful

Quicknode used a 5-node LangGraph workflow to populate 60+ fields per directory tool, with separation of concerns as the key lesson.
Quicknode's Builder's Guide requires over 60 structured fields per tool entry, and Monogram's case study shows how a 5-node LangGraph workflow covers retrieval, generation, category validation, and quality scoring. The core argument is "separation of concerns": evidence gathering, text generation, category judgment, and publishing decisions each need different acceptance criteria, and lumping them together under "make the model better" is exactly the problem. In practice, retrieved sources need to distinguish evidence from interpretation—use case descriptions can synthesize reasoning, while factual fields like pricing need precise source support; category validation must reference the directory's own definitions; quality scoring criteria must be self-defined with actionable results. When evaluating automation, track how many entries pass publishing criteria, not how many the system can generate.
The Content Engineering Challenge Behind a Directory Tool
When building content for Quicknode's Builder's Guide, the team wasn't facing something as simple as "write a tool introduction." Each tool entry needs to be populated with over 60 structured fields—spanning descriptions, pricing, categories, use cases, links, and more. This means that generating a readable summary is only a small part of the entire publishing workflow.
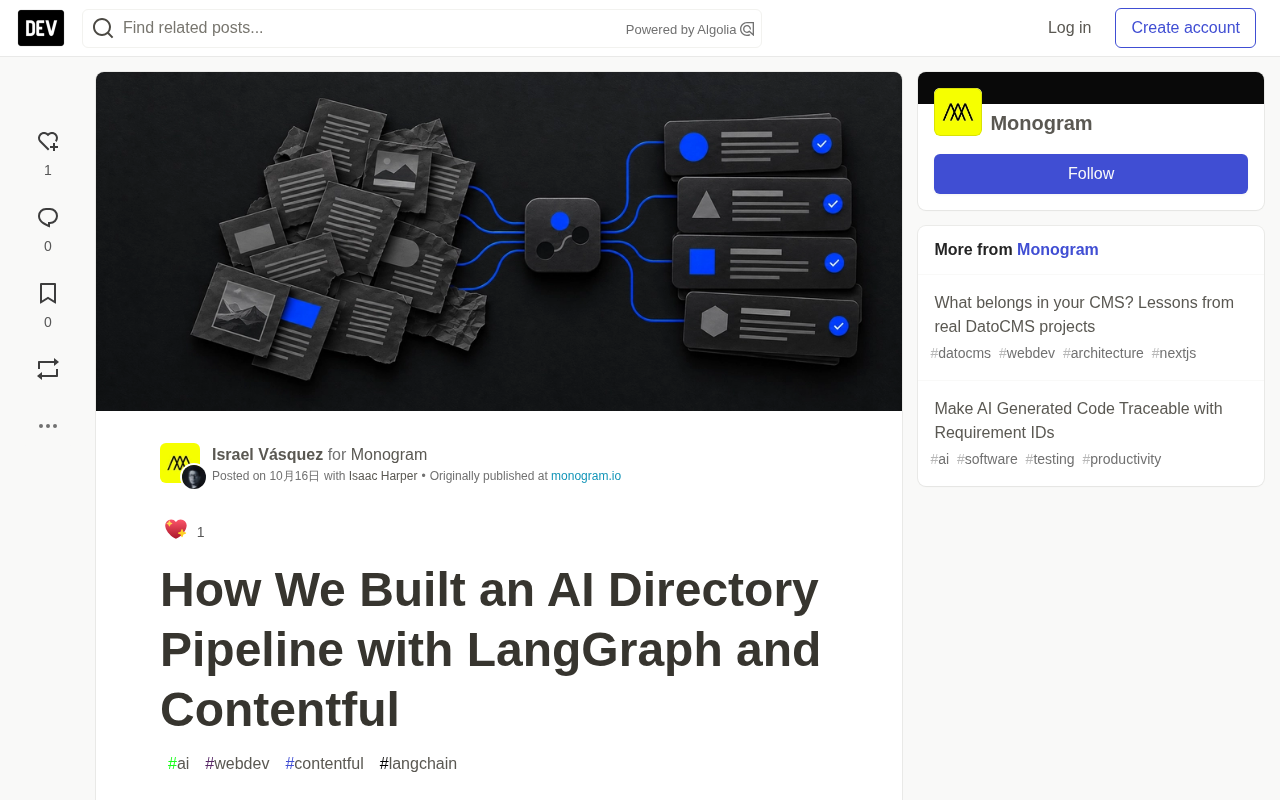
According to Monogram's Quicknode case study, they completed this pipeline using a 5-node LangGraph workflow, covering four key stages: retrieval, generation, category validation, and quality scoring, ultimately completing entry creation and asset association through the Contentful Management API. The core design philosophy behind this architecture isn't complicated: let each stage take on a clear responsibility, because evidence gathering, text generation, category judgment, and publishing decisions each require different acceptance criteria.
First Define What Evidence Each Field Requires
The content model determines the fields and relationship structure of entries, but in a directory context, it has another easily overlooked function: it lets you evaluate generated content at a level more precise than "does the whole thing read correctly."
When designing a similar pipeline, the first step should be describing the type of evidence required for each field. A descriptive summary needs enough context to explain what the tool is for; a pricing field needs information about specific quotes; a category assignment needs a definition to check against. These are different kinds of problems, and handling them separately is the only way to determine which fields are suitable for model generation and which must be directly linked to sources.
There's another design decision that's easy to skip but has serious consequences: how missing information is represented. Empty fields, explicit "unknown" labels, and model-generated guesses mean completely different things to readers. This behavior needs to be defined before letting the model complete entries, otherwise "completeness" becomes an incentive for the model to fabricate unsupported details.
A Content Model is the infrastructure in a content management system that defines content structure and relationships. In a headless CMS like Contentful, a content model consists of several Content Types, each containing a set of Fields, which can be short text, rich text, numbers, dates, references, etc. Reference fields enable entries to be linked to each other, for example connecting a tool entry to its corresponding vendor entry or category entry.
The value of a content model goes beyond constraining data format. Once fields are clearly separated, you can design prompts, define acceptance criteria, and evaluate generation quality for each field individually. For directory entries requiring over 60 fields, this field-level granularity is a prerequisite for quality control—judging the entire entry as a whole to determine whether it "reads correctly" makes it nearly impossible to pinpoint exactly where something went wrong.
Retrieve Evidence First, Then Generate Content
In Quicknode's implementation, the team used the Tavily API to find tool websites, documentation, and social links, then used GPT-4o to generate descriptions, pricing tiers, and use cases.
The key design question at this stage is: can the retrieved material support the fields you intend to publish? Finding a tool's page only establishes a candidate source—you still need to determine what that page can prove and which parts of the entry it can support.
Take pricing as an example. Before accepting a generated value, the reviewer needs to confirm whether the source describes current pricing, a limited-time promotion, or an earlier announcement. This distinction gives the reviewer a specific thing to verify, rather than just judging whether the generated text flows well.
The boundary between evidence and interpretation needs to remain visible throughout evaluation. Use case descriptions can synthesize reasoning from multiple sources; quoted prices require precise source support. Applying the same review method to both would obscure the essential difference between "valuable interpretation" and "unsupported factual assertion."
Tavily is a search API designed for AI applications. Its key difference from traditional search engines is that it's optimized for large language model consumption scenarios: results are typically extracted and condensed webpage content summaries rather than lists of links that need to be crawled and parsed. This makes it directly usable as a retrieval node in a Retrieval-Augmented Generation (RAG) pipeline.
GPT-4o is OpenAI's multimodal large language model that supports text and image inputs. In this case, it serves as the "generation" node—producing tool descriptions, pricing tiers, and use case text based on material retrieved by Tavily. Splitting retrieval and generation into two separate nodes means retrieval results can be reviewed and cached independently, and generation prompts can be iterated separately without touching the retrieval logic.
Category Validation Must Reference the Directory's Own Definitions
Quicknode's category validation step uses AI reasoning, but references the category system defined in Contentful. This suggests a practical boundary: the meaning of a category result should be provided by the directory's own taxonomy—a seemingly reasonable label only has value when it corresponds to how the directory organizes content.
When building your own workflow, you need to provide category definitions to the classification step and evaluate the model's assignment suggestions against those definitions. If categories overlap, decide at the content model level how to handle that overlap. Letting the model make the choice won't resolve the editorial ambiguity left by the definitions themselves.
Category quality can also be reviewed separately from text quality. An entry might accurately explain a tool but be placed in the wrong category; conversely, a correct category doesn't demonstrate whether the pricing description is supported. Separate evaluation makes these different types of failures easier to locate and discuss.
A Taxonomy is the category system used to organize and retrieve content in a directory. Its role isn't just to tag entries—it determines the paths through which users find content. How categories are divided, how deep the hierarchy goes, and whether multiple assignments are allowed all directly affect the directory's usability.
In AI classification scenarios, the taxonomy also serves as an evaluation baseline. If a model's category suggestions deviate from the directory's own definitions, even if the label names seem reasonable, they may not align with the directory's organizational logic. Therefore, providing category definitions as context to the classification step and using the same definitions to validate the model's assignment suggestions is a necessary condition for ensuring classification consistency. When the category definitions themselves have overlaps or ambiguities, this is an editorial decision-level problem that should be resolved in the content model, not left to the model's on-the-spot judgment.
Make Publishing Criteria Explicit
Content quality scoring happens before publishing, executed through the Contentful Management API. Notably, the case study doesn't disclose the specific scoring criteria and pass thresholds.
This means if you're building a similar system, you need to define what the score measures and what actions different scores trigger. Consider evaluating factual support, required field completion, and category match separately—but these are just suggested criteria that need to be tested and validated with representative entries before being used for publishing decisions.
Scoring results need to be actionable. A low score should point to specific fields or claims that need attention, providing a clear decision direction: supplement evidence, revise generated text, or hold publication for human review.
Quicknode's directory started with 700 manually curated tool entries, with a reported potential scale of over 5,000. This number describes the capacity ceiling. When evaluating similar automation solutions, beyond how many entries the system can generate, you also need to track how many entries pass the publishing criteria. The number of accepted entries is the reliable basis for deciding whether to scale up processing or first improve the workflow.
The Contentful Management API is the management interface provided by Contentful for programmatically operating on content, distinguished from the Content Delivery API for content delivery. The Management API supports creating, updating, publishing, and archiving entries, as well as managing content models, assets, and categories. In this case's workflow, after quality scoring passes, it's the Management API that completes the final steps of entry creation and asset association.
Using the Management API means the entire pipeline can run unattended—no manual copy-pasting needed from generation to publishing. But it also means publishing criteria must be clearly defined upfront: once the creation interface is called, the entry enters the content library. Therefore, placing the scoring step before the API call and making low scores trigger specific actions (supplement evidence, revise text, or escalate to human review) is the key control point for preventing low-quality content from entering the directory.
Takeaways from This Architecture
Looking back at this pipeline's design, what's most worth learning isn't the choice of any specific tool, but how "separation of concerns" is implemented in AI content production. Retrieval is retrieval, generation is generation, category validation needs independent criteria, and quality scoring needs traceable field-level feedback. Mixing these stages together and summarizing it as "make the model do better" is exactly where automated content pipelines are most prone to problems.
Related articles

AgentCore in Practice: Connecting Custom Tools and MCP Servers to Agents
DebuggerCafe tutorial shows how to connect custom tools and MCP servers to Amazon Bedrock AgentCore agents, covering tool contract design, MCP reuse, and production concerns.

816B Parameters Scores Only 39? The Real Cost-Effectiveness of the Open-Source LLM Parameter Race
Meta's 816B Muse Spark Open scores just 39 on Artificial Analysis, while 180B Qwen3.8-Flash-Next scores 40. This article analyzes 11 open-weight models' parameters vs. scores, exploring the real impact of activated parameters, quantized size, and deployment cost.

Aerial Manipulators: The Next Step for Drones from 'Seeing' to 'Changing'
Starting from a Reddit discussion, this article analyzes the technical challenges, potential applications, and deployment bottlenecks of aerial manipulators, exploring the key challenges for drones moving from environmental perception to physical manipulation.