Can Local LLMs Replace Cloud APIs? Lessons from Qwen and Hermes in Practice

A Warhammer-themed Reddit post showcases how Qwen + Hermes can replace cloud APIs with a fully local AI setup.
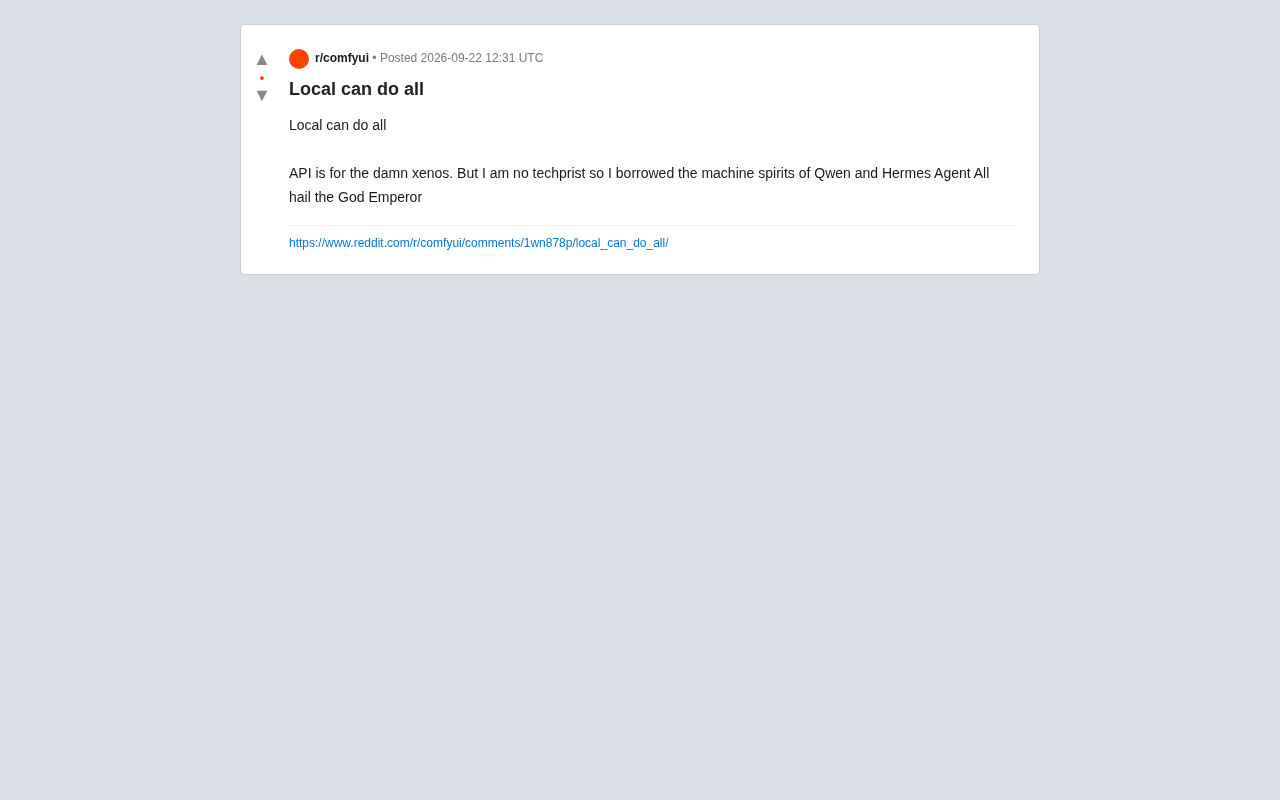
A meme-filled Reddit post declaring "Local can do all" — in true Warhammer 40K fashion — highlights a developer's real-world use of Qwen and Hermes to build a fully local Agent pipeline, resonating widely in the community. The post reflects a genuine technical shift: privacy, near-zero marginal costs, and full control are driving more users toward local deployment. Qwen handles general reasoning, while Hermes excels at function calling and instruction-following for Agent tasks — together rivaling commercial APIs. Though top closed-source models still lead on complex reasoning and long context, local models are already "good enough" for everyday use, and their practical scope keeps expanding as quantization and tooling mature.
Introduction: When Local Models Meet Cloud APIs
A recent Reddit post sparked lively discussion among local LLM enthusiasts. The poster, channeling the campy lore of Warhammer 40K, declared "Local can do all" — and dismissed cloud APIs as "something for xenos (aliens)" — while mentioning that they'd built a local Agent pipeline using two models: Qwen and Hermes.
The post itself was short and deeply steeped in meme culture, but it reflects a real and growing trend: more and more developers and hobbyists are experimenting with locally deployed open-source models as replacements for paid cloud API services.
Why Local Deployment Is Becoming More Appealing
The poster's stance is clear — no reliance on external APIs, everything runs locally. There are several practical motivations behind this preference.
Privacy and data sovereignty is the primary concern. Using cloud APIs means your prompts, context, and potentially sensitive business data all pass through third-party servers. For users who care about data security, running locally means data never leaves their own machine.
Cost control is another major factor. Cloud APIs typically charge per token, and costs can pile up quickly in high-frequency or long-context scenarios. Once a local model is deployed, the marginal cost per call is essentially zero — you're only paying for hardware and electricity.
Offline availability and freedom matter too. Local models are immune to network outages, provider rate limits, or policy changes. Users can freely fine-tune, quantize, and combine different models to build workflows that are entirely their own.
The technical feasibility of local deployment has improved dramatically in recent years, driven by two key advances. The first is quantization — compressing model weights from 32-bit or 16-bit floating point to 8-bit, 4-bit, or even lower integer representations, reducing VRAM requirements by up to 75% or more. This makes it possible to run billion-parameter models on consumer-grade GPUs like the RTX 3090 or 4090. The second is the maturation of local inference frameworks like Ollama, llama.cpp, and LM Studio, which have dramatically lowered the barrier to entry — users no longer need to understand CUDA programming to run open-source models with a single command. Together, these advances are what turned "Local can do all" from a rallying cry into a realistic option.
Qwen and Hermes: Two Compelling Local Choices
The two models mentioned in the post — Qwen and Hermes — represent two distinct powerhouses in today's open-source local model ecosystem.
The Qwen Series
Qwen (Tongyi Qianwen), developed by Alibaba, is an open-source model series that has become a popular choice for local deployment thanks to its range of sizes, strong bilingual Chinese-English capabilities, and an active community. It performs consistently across reasoning, coding, and multilingual tasks, and offers multiple parameter sizes — allowing users to pick the right trade-off based on their hardware.
The Hermes Series
Hermes is a fine-tuned model series from Nous Research, built on top of open-source base models and known for exceptional instruction-following and Agent capabilities. The poster specifically mentioned using it as an "Agent," which highlights the community's recognition of Hermes's strengths in function calling, task planning, and autonomous execution workflows.
Using both together — one handling general reasoning, the other driving Agent execution — is a classic strategy among local AI enthusiasts: combine different models for their respective strengths and assemble a pipeline that rivals, or even matches, commercial APIs.
The Hermes series has now reached Hermes 3, typically built on Meta's Llama series or Mistral series as a base, then refined through Nous Research's specialized instruction fine-tuning and alignment training. This makes the model particularly adept at following complex instructions, multi-step reasoning, and tool use. "Function calling" refers to the model's ability to recognize when an external tool (such as a search engine, calculator, or code executor) needs to be invoked, output structured call parameters, and then integrate the tool's response into a final answer — this is the core foundation of autonomous Agent workflows. Hermes's strong support for structured JSON output gives it excellent compatibility with mainstream Agent frameworks like LangChain and AutoGen, which is the primary reason the community has positioned it as a go-to model for Agent use cases.
"Local Can Do All": Ideal or Reality?
The poster's slogan radiates confidence, but a balanced assessment suggests the picture is more nuanced.
In terms of capability ceiling, top-tier closed-source models (such as the latest commercial flagships) still hold an edge in complex reasoning, ultra-long context handling, and multimodal tasks. Open-source local models have advanced rapidly, but fully replacing all use cases — especially those demanding extreme precision — remains a work in progress.
In terms of hardware requirements, running larger models demands substantial VRAM and compute power, which is a real barrier for everyday users. Quantization can lower those requirements, but it does introduce some performance degradation.
That said, for a broad range of everyday tasks — text processing, coding assistance, lightweight Agent automation — local models are genuinely "good enough," and in some cases offer a better experience than paid APIs. The poster's setup is a vivid illustration of this reality.
Conclusion
This brief Reddit post, wrapped in humor, points to a serious trend: local open-source models are becoming reliable productivity tools. The Qwen and Hermes combination demonstrates how ordinary users can build their own AI workflows entirely from the open-source ecosystem.
Whether to "abandon the cloud and go local" is a personal decision that depends on individual needs. But one thing is clear: as open-source model capabilities continue to improve and deployment tooling matures, the practical scope of local solutions will only keep expanding. For users who prioritize privacy, cost efficiency, and autonomy, now is a great time to give local LLMs a serious try.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.