#Ollama
100 related articles
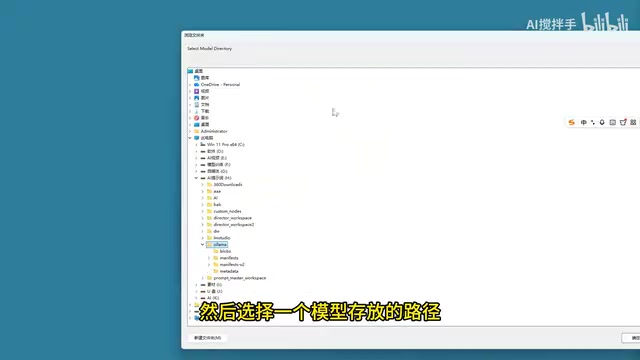
Complete Tutorial: Configuring Ollama Local Models in Director Master
A complete Bilibili tutorial on configuring Ollama local models in Director Master: from installation and model path setup to downloading Qwen and running topic, outline, script, and storyboard workflows.

Director Master Integrates Ollama Local Models: Configuration and Full Workflow Creative Practice
Bilibili tutorial explains how Director Master integrates Ollama local models: install Ollama, set model storage path, pull Qwen via command line, add provider in Agent settings, and run the full short film workflow from topic to storyboard with local Qwen 3.8.
Ollama Releases v0.40.12-rc1, Adds LFM3 and d1 Model Support
Ollama releases v0.40.12-rc1 candidate, adding LFM3 and d1 models to the MLX backend. We examine what this means for local inference on Apple Silicon and what developers should watch.
Ollama v0.40.10 Updates Gemma Renderer, Adds Speculative Decoding Support
Ollama v0.40.10 adds the gemma4-nemotron renderer, reorders assistant content vs. tool calls, and adds Gemma 4 speculative decoding with DFlash on MLX.
Ollama v0.40.10-rc0: Gemma 4 Renderer …
Ollama v0.40.10-rc0: Gemma 4 Renderer Update and MLX Speculative Decoding Enhancements
Ollama v0.40.10-rc0 updates the Gemma 4 renderer with a new gemma4-nemotron render order variant and adds DFlash speculative decoding support to the MLX backend, exposing hidden states and raw logits.

Ollama Local LLM Deployment Tutorial: From Installation to GUI Client
Complete Ollama local LLM deployment tutorial: three-platform installation, importing GGUF and SafeTensors models, connecting GUI clients to OpenCode and WebSearch with hands-on testing, plus key settings like model storage paths and selection advice.
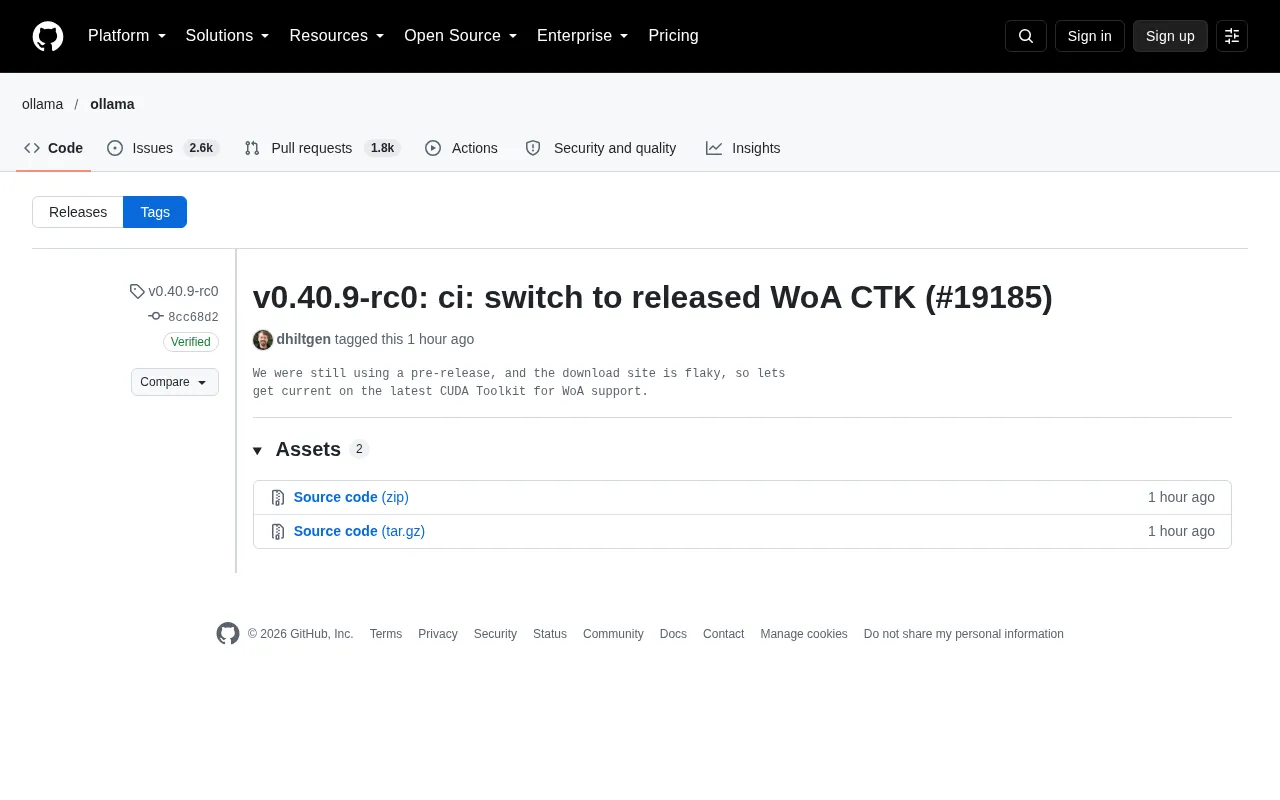
Ollama v0.40.9-rc0: WoA Support Switches to Released CUDA Toolkit
Ollama v0.40.9-rc0 switches CI from a pre-release CUDA Toolkit to the official release to improve Windows on Arm build stability. This article explains the motivation, impact on WoA inference support, and the risk pattern of pre-release dependencies in CI.

Ollama v0.40.7-rc1: MLX and GGML Share CUDA Runtime, Slimmer Package Size
Ollama v0.40.7-rc1 deduplicates the CUDA runtime shared by MLX and GGML, moving it into a sibling CUDA payload directory, retaining MLX private libs and JIT headers, packaging the full OpenBLAS Fortran runtime closure, and adding dependency checks at release to shrink the package and simplify dependency resolution.

Running Claude Code with Local Ollama: A Complete Hands-On Guide
A step-by-step guide to connecting Claude Code to local Ollama models across Windows, Linux, and macOS, covering both the ollama launch and environment variable methods, plus 8 GB RAM test findings and a troubleshooting checklist.

Meta's Open-Weight Model Muse Spark Open Lands on Ollama: 1M Token Context
Meta's open-weight model Muse Spark Open launches on Ollama, focused on coding and tool calling with a 1M token context window. Here's its positioning, run commands, availability, and practical observations.

Ollama Heads to Seoul: Partnering with FriendliAI to Expand in the Korean AI Market
Ollama announces a November trip to Seoul to meet Korean users, customers, and partners, confirming a partnership with local AI infrastructure company FriendliAI. This article analyzes the market context, the complementary logic of the partnership, and the signal of Ollama's shift from open-source tool to regional ecosystem.

DeepSeek-V4.1-Flash Lands on Ollama: Stronger Agentic Performance at Lower Cost
DeepSeek-V4.1-Flash-1017 is now on Ollama and Ollama Cloud, emphasizing strong agentic performance and lower cost per task, with US-based hosting and zero data retention. This article breaks down integration, cost framing, and compliance selling points, while noting that model parameters, context length, and other key details still await official confirmation.

Self-Hosting Open-Source LLMs in the EU: A Practical GDPR Compliance Checklist
A hands-on EU guide: self-host open-weight LLMs with Ollama to avoid GDPR transfer issues, including Docker Compose code, hardware sizing, and a 10-point checklist.

Ollama Crawling on K3s? A Practical Guide to GPU Passthrough Configuration
Ollama slow on K3s? The root cause is containers can't see the NVIDIA GPU, falling back to CPU. This guide breaks down the reasons and provides a complete GPU passthrough configuration: NVIDIA Container Toolkit, containerd template, Device Plugin deployment, and Ollama resource declaration, with verification and troubleshooting. Speed goes from 1 token/s to 60-90 tokens/s.

PrintBrief: Local AI Turns Messy Messages Into Print Orders
PrintBrief is a local AI assistant for small print shops, using Gemma 3 4B via Ollama to parse messy customer messages, extract print parameters, detect missing info, and generate deterministic quotes—keeping customer data on-device.

What Is Ollama? Putting Free AI Models on Your Own Computer
Ollama isn't a model but a tool for running AI models locally. This article explains its role, the four-step setup, three advantages of local AI, hardware limits, and what "free" really means—helping you decide if it can replace cloud services like ChatGPT.

Open WebUI in Practice: Giving Your Local LLM a Chat Interface
Open WebUI tutorial: build a web chat interface for local Ollama models. Distinguish port 8080 (web) from 11434 (model), install, verify connection, save chat history, and restart—plus layered troubleshooting tips.

Connecting Codex to Local Models: What Each GPU Tier from 8G to 24G Can Run
Connecting Codex and Claude Code to local models comes down to one subtraction: VRAM minus model file size leaves room for context. Here are runnable models, measured headroom, the four-step Ollama setup, and common pitfalls for 8G, 12G, 16G, and 24G GPUs.

Ollama Decision Models Tested: Local Inference Far Outpaces Claude
Hands-on test of Ollama decision models: a 0.8B model does email classification and scoring locally over twice as fast as the Claude API, and can even classify images on a Dell Pro Max. Deployment steps, speed comparisons, and multimodal results included.

SupplierSignal AI: An Open-Source Supplier Verification Tool
SupplierSignal AI is an open-source supplier verification tool by Code Killers. It uses Gemma via Ollama locally to compare supplier promises, invoices, and actual receipts, flag discrepancies, and generate reports — all local-first.