ChatGPT Is Not an AI Agent: Understanding the Core Difference in One Diagram

ChatGPT stops at answering; Agents autonomously complete tasks through a think-execute-observe loop.
The article distinguishes ChatGPT from AI Agents: ChatGPT is a conversational model whose output stops at answering, while an Agent is goal-oriented and autonomously decomposes and completes tasks through a think-execute-observe loop. An Agent comprises an LLM as the brain, tools as the hands, and memory as the diary—all three are essential. This distinction shifts evaluation from answer quality to task completion rate, expands the risk surface, and moves product forms from conversational assistants to task executors. The main bottleneck for deployment is tool reliability and permission boundaries, not model capability.
ChatGPT Is Not an AI Agent: Understanding the Core Difference in One Diagram
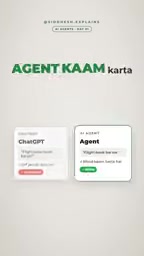
Many people conflate ChatGPT with AI Agents. In the "AI Agent Series Day 1" short video, the YouTube creator opens with a pointed question: "Do you also think ChatGPT is an AI Agent?" The answer is no—ChatGPT is only responsible for "answering," while an Agent is responsible for "doing things." This distinction seems simple, but it determines how we understand the shape of next-generation AI applications.
The Divide Between Answerer and Executor
ChatGPT is essentially a conversational model: you ask, it answers. It excels at generating text, explaining concepts, and offering suggestions, but its output stops at the act of "answering." An AI Agent is different—it receives a goal, not a question.
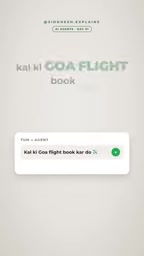
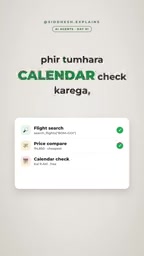
The example in the video is intuitive: when you tell an Agent "book me a flight to Goa tomorrow," it won't just tell you "you can book on such-and-such website." Instead, it breaks down the task itself—first searching for flights, then comparing prices, then checking your calendar, and finally completing the booking. The entire process requires no step-by-step direction from you.
This difference can be summed up in one sentence: ChatGPT is an information outlet, while an Agent is an acting subject. The former optimizes for "is the answer correct," while the latter optimizes for "was the task accomplished."
Think—Act—Observe: The Agent's Core Loop
The reason an Agent can autonomously complete tasks is that it relies on a continuously repeating loop. The video breaks it down into three actions: thinking, executing, and observing.
Take booking a flight as an example: the Agent first thinks about "what steps are needed," then calls a search tool to execute the query, observes the returned prices and times, and then decides whether the next step is comparing prices or checking the calendar. This loop continues running until the task is completed or it encounters an insurmountable obstacle.
The key to this mechanism is feedback. An ordinary chat model finishes after a single generation, while an Agent adjusts its subsequent strategy based on the result of each tool call—if a flight is sold out, it switches to another one; if the price exceeds the budget, it looks for alternatives. This ability to "adjust while doing" is the fundamental difference between it and a static question-answering system.
This "think—act—observe" loop originates from the feedback loop idea in cybernetics and is often called the ReAct (Reasoning and Acting) paradigm in the AI field. The core of ReAct is to have a language model alternately generate reasoning traces and action instructions, and to use the environment feedback from each action as input for the next round of reasoning. Unlike static methods that generate a complete plan in one shot, ReAct allows the model to dynamically revise its path when information is incomplete—which is precisely the theoretical basis for an Agent's ability to handle tasks in open environments. This paradigm was first proposed by Shunyu Yao and others in 2022, and has since become the mainstream framework for building tool-calling Agents.
The LLM Is the Brain, Tools Are the Hands, Memory Is the Diary
The video uses a set of metaphors to explain the composition of an Agent, and these metaphors are quite accurate:
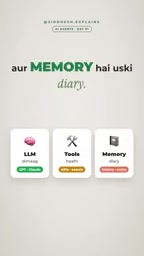
- The LLM is the brain: responsible for understanding goals, breaking down tasks, and making decisions. Without the reasoning ability of a language model, an Agent is just a rigid script.
- Tools are the hands: search APIs, calendars, payment interfaces, code execution environments—an Agent affects the real world by calling external tools. Without tools, it can only fantasize.
- Memory is the diary: recording what has been done, what results were obtained, and what the user's preferences are. Without memory, an Agent starts over at every step and cannot accumulate context.
None of these three can be missing. With only an LLM and no tools, it is ChatGPT; with only tools and no LLM, it is a traditional automation script; with an LLM and tools but no memory, an Agent will lose its way in multi-step tasks.
In technical implementation, "tools" usually exist in the form of function calling or tool use interfaces. Developers use JSON Schema to describe each tool's name, purpose, and parameters; the model outputs structured call requests during reasoning, and an external runtime executes them and returns the results to the model. OpenAI introduced function calling capabilities for the GPT series in June 2023, while Anthropic's Claude implements a similar mechanism through its "tool use" protocol. MCP (Model Context Protocol) is a standardization attempt that has emerged in recent years, aiming to unify the way models connect to various external tools and data sources, reducing the engineering cost of writing a separate adapter for each Agent.
Why This Distinction Matters
Understanding the difference between ChatGPT and an Agent is not just a conceptual game. It directly affects how we evaluate and use AI products:
The evaluation criteria have changed. Measuring a chat model is about answer quality; measuring an Agent is about task completion rate. An Agent may have unremarkable reasoning at every step, but if it ultimately gets the job done, that is a pass; conversely, no matter how elegant the reasoning, if the task fails, it fails.
The risk surface has expanded. When a chat model says something wrong, the cost is misinformation; when an Agent does something wrong, the cost may be actually booking the wrong flight, sending the wrong email, or modifying the wrong file. The stronger the autonomy, the higher the requirements for permission control and result verification.
Product forms are shifting. From "conversational assistants" to "task executors," the industry is embedding language models into concrete workflows. Booking tickets, writing code, conducting research, handling customer service tickets—the common feature of these scenarios is: clear goals, decomposable steps, and verifiable results, which is exactly the field where Agents excel.
An Easily Overlooked Prerequisite
The example of an Agent booking a flight in the video sounds smooth, but in reality such tasks place no small demands on the system: it needs a reliable flight search interface, structured calendar data, secure payment authorization, and the ability to handle exceptions. If any link is missing, the loop gets stuck.
This is also the main bottleneck for Agent deployment today—not that the model is not smart enough, but that the callable tools are not reliable enough and the permission boundaries are not clear enough. Treating an LLM as a brain is easy; giving it a reliable pair of hands and a diary it can remember is the real engineering challenge.
Returning to the initial question: Is ChatGPT an AI Agent? No. It is one of the Agent's brain components, but it is still missing tools, memory, and a continuously running execution loop before it can "finish things on its own."
The security authorization required for an Agent to perform real operations currently mainly relies on token mechanisms such as OAuth and fine-grained scope control. For example, when accessing a user's calendar, it requests only read-only permission; when initiating a payment, it requires secondary confirmation or sets an amount limit. Common protective measures in industry practice also include: a human approval step before action execution, sandbox environment isolation, operation log auditing, and rollback-capable transaction design. These mechanisms target exactly the risk of "doing something wrong" brought by Agent autonomy—the model may call a tool it should not call due to hallucination, or perform a destructive operation due to a misunderstanding of parameters. The principle of least privilege and verifiability of results are the core consensus of current Agent engineering standards.
One-line Summary
ChatGPT stops at answering; an Agent autonomously completes goal-oriented tasks through a think-act-observe loop.
Paragraph Summary
The article distinguishes the essential difference between ChatGPT and AI Agents: the former is a conversational model whose output stops at answering; the latter is goal-oriented and autonomously decomposes and completes tasks through a "think—act—observe" loop. An Agent consists of three parts: the LLM as the brain responsible for reasoning and decision-making, tools as the hands responsible for affecting the real world, and memory as the diary responsible for accumulating context—none can be missing. This distinction has three implications: evaluation criteria shift from answer quality to task completion rate, the risk surface expands due to autonomous action, and product forms migrate from conversational assistants to task executors. The article concludes by pointing out that the main bottleneck for Agent deployment today is not model capability, but tool reliability and permission boundaries.
Related articles

A New Paradigm for Text Editing in Compose: TextFieldState Replaces the Old API
Jetpack Compose introduces the TextFieldState API to fix dropped characters and cursor jumps from async input. The old value/onValueChange callbacks will be deprecated in 1.13. This article covers InputTransformation, OutputTransformation, four state hoisting patterns, and new formatted text editing capabilities.

Remote Compose: A New Document-Driven Paradigm for Cross-Platform UI on Android
Remote Compose transmits compact binary documents instead of screen pixels, enabling efficient UI rendering on remote surfaces like Wear OS and widgets. This article covers its document creation API, expression animations, size optimization techniques, and Wear OS progress.

How Crashlytics Eliminates Android Memory and Responsiveness Issues
Through the Chroma Clip case study, this article explains how Firebase Crashlytics uses Application Exit Info, Profiling Manager, GWP ASAN, and ARM MTE to pinpoint ANRs, OOMs, memory limit terminations, and native memory corruption—solving the challenge of stack traces that don't point to the real culprit.