Claude Code Local Deployment Guide: Run CC with Local Models to Save Tokens

Integrate Claude Code with local LLMs to run offline and cut token costs by matching model size to your GPU's VRAM.
This guide explains how to integrate Claude Code — a code-focused AI agent — with locally deployed large language models to bypass network restrictions and high token costs common in China. The key logic: Claude Code handles agent orchestration while the local model handles inference. Model selection should be driven by task complexity, with larger models offering more capability but requiring more VRAM. Quantization can significantly reduce VRAM usage. NVIDIA GPUs with CUDA offer the easiest setup; for limited local hardware, renting a cloud GPU server is a flexible and cost-effective alternative.
What Is Claude Code: A Code-Focused AI Agent
Claude Code (CC for short) is essentially an AI agent built for code-related tasks. As the name suggests, its core purpose is to leverage agent capabilities to help developers complete coding work — it's not a simple conversational tool.
For developers in China, connecting directly to the official cloud service comes with two unavoidable pain points: the need for stable internet access, and the cost pressure of per-token billing. This guide focuses on a specific approach — integrating Claude Code with a locally deployed large language model, enabling CC to work in an offline environment and fundamentally eliminating high token costs.
The value of this setup lies in the separation of concerns: Claude Code handles agent orchestration and engineering capabilities, while the local model handles inference. Once decoupled, cost becomes much more controllable.
AI Agent vs. Conversational AI: The core difference between an AI agent and an ordinary conversational AI lies in autonomous execution capability. A standard chat model only generates text responses. An agent actively breaks down tasks, calls tools (like reading/writing files, running terminal commands, searching codebases), and adjusts its next steps based on execution results — forming a closed loop of "perceive → plan → act → feedback." Claude Code operates exactly within this framework: rather than suggesting how to fix your code, it opens the file, edits the content, runs tests, checks error messages, and keeps iterating until the task is done. This autonomy fundamentally distinguishes it from tools like GitHub Copilot, which passively assists — CC actively executes.
Local Model Quality Depends on Model Size
Many people worry that local models won't be capable enough. The answer isn't black and white — it largely depends on the size of the model you deploy.
The general rule is: the larger the model and the more parameters it has, the more capable and "intelligent" it tends to be. Conversely, 7B, 8B, or even smaller 4B models have more limited capabilities, but they're much friendlier to your hardware.
Whether a model is "good enough" isn't an isolated technical metric — it has to be evaluated against your actual use case. The more complex the tasks you assign to the model, the higher the capability requirements, and the larger the model size you'll need. In other words, start by defining what you need the model to do, then work backward to determine the required model size. That's the right order for making a selection.
Understanding Parameter Counts: Model size is typically expressed in "B" (Billion), so 7B means 7 billion parameters. The more parameters, the richer the knowledge and patterns learned during pre-training, and the stronger the model's ability to handle complex reasoning, long contexts, and multi-step tasks. Popular open-source models suitable for local deployment include Meta's Llama series, Alibaba's Qwen series, and Google's Gemma series, ranging from 1B to 70B+ parameters. For code agent tasks that require multi-step reasoning, understanding project structure, and generating runnable code, industry experience shows that models above 14B significantly outperform those below 7B, and models around 32B can handle most moderately complex tasks at a usable level.
Choosing a GPU: VRAM Is the Key Metric
GPU selection and model size go hand in hand — the larger the model, the better the GPU you need, sometimes requiring multiple cards in parallel. Conversely, running 7B, 8B, or smaller models can typically be done with a single GPU.
The core metric for determining whether a GPU is sufficient is VRAM capacity. Here are a few concrete reference points:
- MacBook M5 Pro 48G: A quite capable configuration — 48GB of unified memory can support the deployment of relatively large models.
- RTX 3070 8G: Relatively weak compute performance, and 8GB VRAM is on the small side — only barely able to run smaller models.
- RTX 2080Ti 11G: The author's own desktop configuration — 11GB VRAM is still a bit tight for model deployment.
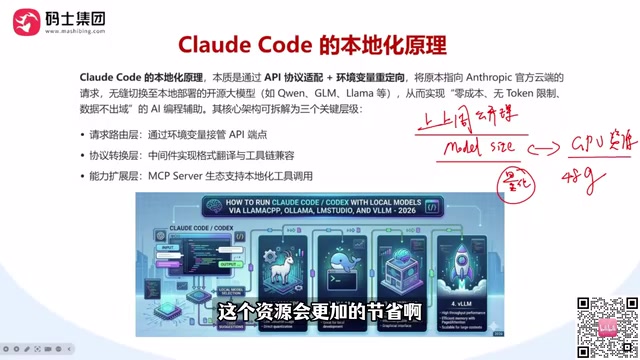
A useful technique: once you know your VRAM capacity, you can work backward to determine the maximum model size you can deploy. Additionally, using quantized models significantly reduces VRAM usage — the same model after quantization consumes far fewer GPU resources. This is an important optimization strategy when VRAM is limited.
What Is Quantization? Quantization is a model compression technique that reduces memory usage by lowering the numerical precision of model weights. Original models typically store parameters as 32-bit or 16-bit floating-point numbers; after quantization, they can be compressed to 8-bit (Q8), 4-bit (Q4), or even lower. For example, a 7B model at FP16 precision requires roughly 14GB of VRAM, while Q4 quantization brings that down to about 4GB — a ~60% reduction. Common quantization formats include GGUF (used with llama.cpp/Ollama) and GPTQ/AWQ (used with frameworks like vLLM). The trade-off is a slight reduction in model capability, with lower bit-widths causing more degradation. However, Q4/Q5 quantization typically has minimal impact in most scenarios, making it the best cost-effective option when VRAM is constrained.
NVIDIA vs. AMD vs. Cloud Servers: Making the Right Choice
When people talk about GPU acceleration, they're almost always referring to NVIDIA graphics cards. As long as CUDA is installed, models can leverage GPU acceleration. If you're using an AMD or Intel GPU, you'll need to find and install the corresponding acceleration toolkit — a significantly higher configuration barrier.
For users with weaker local GPUs, the author's practical recommendation is to go to the cloud. Since the author's own 2080Ti has limited VRAM, they personally choose cloud servers for model deployment, selecting more capable GPUs from available options. Cloud servers offer GPUs ranging from entry-level to high-end, selectable on demand — both solving the hardware shortage problem and offering more flexibility than purchasing high-end cards outright.
About CUDA: CUDA (Compute Unified Device Architecture) is NVIDIA's parallel computing platform and programming model. Since its release in 2006, it has become the de facto standard in deep learning. Major AI frameworks like PyTorch and TensorFlow are optimized with CUDA as the top priority, and most open-source model inference frameworks (such as Ollama, the GPU-accelerated version of llama.cpp, and vLLM) support CUDA by default. AMD's equivalent is the ROCm platform, and Intel Arc GPUs use oneAPI/IPEX-LLM — both lag noticeably behind CUDA in software ecosystem maturity and community support, with some model frameworks having delayed or incomplete support for non-CUDA platforms. For inference-focused use cases, NVIDIA's "works out of the box" advantage is significant.
Summary: The Core Logic of Local Deployment
Integrating Claude Code with a local model is fundamentally about finding the right balance between capability, cost, and hardware:
- More complex tasks → larger model needed → higher GPU requirements;
- Limited VRAM → use quantized models or switch to a cloud server;
- NVIDIA cards just need CUDA for acceleration; AMD/Intel cards require additional setup.
Understanding this logic chain allows you to make reasonable model size choices based on your available hardware — whether that's an M5 Pro or an entry-level NVIDIA card — and get Claude Code running in a cost-effective, offline-capable environment.
Related articles

AgentCore in Practice: Connecting Custom Tools and MCP Servers to Agents
DebuggerCafe tutorial shows how to connect custom tools and MCP servers to Amazon Bedrock AgentCore agents, covering tool contract design, MCP reuse, and production concerns.

816B Parameters Scores Only 39? The Real Cost-Effectiveness of the Open-Source LLM Parameter Race
Meta's 816B Muse Spark Open scores just 39 on Artificial Analysis, while 180B Qwen3.8-Flash-Next scores 40. This article analyzes 11 open-weight models' parameters vs. scores, exploring the real impact of activated parameters, quantized size, and deployment cost.

Aerial Manipulators: The Next Step for Drones from 'Seeing' to 'Changing'
Starting from a Reddit discussion, this article analyzes the technical challenges, potential applications, and deployment bottlenecks of aerial manipulators, exploring the key challenges for drones moving from environmental perception to physical manipulation.