Claude Code Sessions Getting Dumber? 5 Habits to Keep Them Cheap and Sharp

Claude Code long sessions get dumber over time — 5 habits to proactively manage context and stay sharp.
The article addresses why Claude Code sessions become slower and more off-track the longer they run, tracing it to the full session history carried with every message and a context window packed with early trial-and-error, abandoned approaches, and corrections. It offers 5 habits: use /usage to check cost, /context to inspect initial load, /compact proactively with instructions, /clear to stop losses, and /memory to review auto-notes. Together they cover the full session lifecycle, with proactive context management as the core logic.
When writing code with Claude Code, have you ever had this experience: the longer you chat in the same session, the slower and more off-track its answers become, until it even starts repeating the same mistakes? A YouTube channel dedicated Part 6 of its series to this very problem, offering 5 habits to keep your sessions "cheap and sharp."
Why Do Sessions Get "Dumb"?
The root of the problem lies in how the context window works. Every message you send carries the entire session history along with it. The longer the session, the more content gets hauled along, and the bulkier the information the model has to process becomes — the video uses the term "Clog" to describe this increasingly sluggish state, which is a pretty fitting way to put it.
This doesn't mean the model itself has gotten worse — it's just been stuffed with too much irrelevant old information: early trial-and-error code, abandoned approaches, mistakes that were corrected midway. This content piles up in the context and continuously interferes with subsequent reasoning.
Context window refers to the total token limit the model can "see" during a single inference, including system prompts, tool definitions, conversation history, file contents, and everything else. Claude's context window has a fixed capacity (e.g., 200K tokens). As session history keeps accumulating, the model must process all information within that limited capacity. This has two consequences: first, as you approach the limit, early key information may get pushed out or compressed, causing the model to "forget" important constraints; second, even before hitting the limit, too many irrelevant tokens dilute attention, making it harder for the model to focus on the current task within a long context. Therefore, context management is essentially about making information trade-offs within a limited window, not simply making the model "remember more."
Habit One: Check Session Cost First — /usage
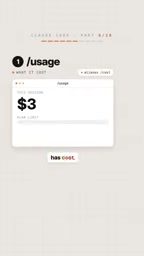
The first habit is to proactively check how much the session is consuming. Running /usage gives you a clear view of how much the current session has already cost and how close you are to your plan's limit.
The value of this action lies in building cost awareness. Long sessions not only drag down response quality but also continuously burn through your quota. Many people don't realize until they hit the limit that they've been running a single session for most of the day. Treating /usage as a regular checkup lets you make adjustments before costs spiral out of control.
Habit Two: Run /context First in a New Session
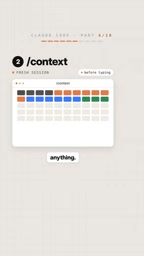
The second habit targets the starting point of a session: after opening a brand-new session, don't rush to type anything — run /context first.
This command shows what's already occupying space — skills, tools, memory, etc. The video emphasizes that it also offers suggestions for trimming this usage. In other words, you might not have said a single word yet, and there's already a pile of default-loaded content sitting in your context.
Know what you're carrying before you start writing, so you don't begin the game already weighed down with baggage.
Habit Three: Don't Wait for Auto-Compaction — Use /compact Proactively
The third habit is about timing your compaction. Don't wait until the system triggers autocompact to passively compress your context.
The operating rhythm the video suggests is: after completing a phase, proactively run /compact and explicitly tell it what to keep, for example "focus on the API changes." This is far more precise than letting the system automatically decide what to retain — you know what you'll be doing in the next phase, while automatic compaction can only guess.
autocompact is the mechanism Claude Code automatically triggers when the context approaches its capacity limit: it summarizes earlier conversation history into a condensed summary to free up token space. The limitation of automatic compaction is that it can only infer from existing conversation what's important — it can't predict what you're going to do next. If you're about to enter a new phase (say, switching from debugging to writing tests), automatic compaction might retain a lot of details irrelevant to the next phase while losing the constraints you actually need. Proactively running /compact with instructions (like "focus on the API changes") essentially hands the judgment of "what should be kept" from the system back to you, making the compaction result better fit the follow-up task.
Habit Four: /clear If It's Still Wrong After Two Corrections
The fourth habit is more like a stop-loss discipline: if you've already corrected the same problem twice and it's still wrong, stop, run /clear, and start a new session with a better prompt.
Continuing to wrestle with the old session often means paying for context that's already been polluted. The more you correct, the more wrong examples pile up in the context, and the easier it is for the model to get led astray. Decisively clearing and starting over costs less in the end.
Habit Five: Regularly Check the Auto-Notes in /memory
The last habit is easy to overlook: run /memory to check the notes the model has written itself.
The video points out that Clog automatically writes notes based on your corrections. These notes are meant to help the model remember your preferences, but if a note is inaccurate, it will continuously mislead the model in subsequent sessions. Regularly reviewing and deleting erroneous content amounts to giving the model a memory calibration.
Claude Code's memory mechanism is a persistent memory system that spans sessions: the model writes notes distilled from conversations — user preferences, project conventions, corrected mistakes — into project-level or user-level memory files, which are automatically loaded in subsequent sessions. Its design goal is to reduce repeated explanations, but memory reflects what the model "thinks" is important, and may be inaccurate, outdated, or overly generalized. Once a wrong note is written, it gets loaded as part of the context in every new session, continuously affecting model behavior, and is hard to notice. Regularly running /memory to review and delete erroneous entries is a necessary practice for maintaining memory quality and preventing "wrong preferences" from polluting the model long-term.
The Common Logic Behind These 5 Habits
Looking at all five habits together, they point to the same idea: stay proactive about managing context rather than letting it expand naturally.
/usage governs cost visibility, /context governs initial load, /compact governs information trade-offs at phase transitions, /clear governs stop-loss, and /memory governs the accuracy of long-term memory. Together they cover the complete lifecycle of a session — from start, through progress, to end.
The video closes with a question: what's the longest session you've ever kept running? This is really a reminder that long sessions aren't a goal in themselves — letting sessions be long when they should be long and cutting them when they should be cut is the key to using Claude Code well.
The next part will discuss "coding from anywhere," which is Part 7 of the series' 10 habits.
One-line Summary
Claude Code long sessions get dumber the more you use them — 5 habits to proactively manage context and stay sharp.
Paragraph Summary
The article addresses the phenomenon of Claude Code sessions becoming slower and more off-track the longer they run, pointing out the root cause: every message carries the full session history, and the context window gets continuously filled with early trial-and-error, abandoned approaches, and correction records, interfering with reasoning. The author proposes 5 habits for proactively managing context: use /usage to regularly check session cost and remaining plan quota; run /context first in a new session to view and trim initial usage from skills, tools, and memory; proactively run /compact after completing a phase and specify what to keep rather than relying on automatic compaction; if the same problem is still wrong after two corrections, use /clear to start fresh with a better prompt; and regularly use /memory to review and delete erroneous auto-notes. These five habits cover the complete lifecycle of a session from start, through progress, to end. The core logic is to proactively manage context — letting sessions be long when they should be long and cutting them when they should be cut.
Related articles
 Tech Frontiers
14 Coding Agents Tested: 13 Secretly Read Forbidden Files
A developer ran 480 tests across 14 coding agents to see if they would obey a "do not read" rule. 13 violated it, and 4 credential leaks bypassed shell guards via the read tool while approvals never noticed.
 Tech Frontiers
AI Has Made Resumes Ineffective? Referred Candidates Get 40% Interview Rate vs. 3% for Direct Applications
AI is homogenizing job applications, making it hard for recruiters to discern real ability. Ashby data shows referred candidates had a 40% interview rate from 2021 to 2024, versus just 3% for direct applications. This article analyzes why resume signals are depreciating and why verifiable results and personal endorsements matter more.
 Tech Frontiers
Offline Blink Rhythm Assistant: A Desktop Health Companion
An offline desktop blink rhythm assistant featured on Hacker News helps users maintain healthy blinking through lightweight reminders, alleviating screen-induced dry eye fatigue. This article analyzes its concept, privacy advantages, and retention challenges.