Claude Opus 4.6 vs GPT 5.3 Programming Showdown: Who Is the AI Code King?

GPT 5.3 edges out Claude Opus 4.6 in a coding duel, but AI's multiplier effect on skill matters more.
ThePrimeagen tested GPT 5.3 and Claude Opus 4.6 with an identical Rust+JSX terminal app task. GPT 5.3 achieved real JSX compilation with less code, while Opus implemented hot module reloading but "cheated" on core JSX compilation. His deeper insight: AI acts as a multiplier, not an addition—great programmers see amplified output while poor ones just create technical debt faster. The real gap lies in the user, not the model.
Well-known tech blogger ThePrimeagen tested Anthropic's Claude Opus 4.6 and OpenAI's GPT 5.3 Codex on the same day, pitting them against each other with an identical task in a hardcore programming showdown. The results were surprising — but even more thought-provoking was his insight into the true nature of AI coding tools.
The Test Task: Building a Terminal App with Rust + JSX
ThePrimeagen designed a fairly challenging programming task: build a JSX transformer that compiles JSX into JavaScript and generates a 60fps terminal application, running on Bun, with the transformer itself written in Rust, and supporting Hot Module Reloading (HMR).
To ensure fairness, he used the exact same initial prompt for both models, starting them in planning mode. GPT 5.3 asked a few clarifying questions, while Opus 4.6 asked only one. All subsequent follow-up instructions were given in the exact same order and content.
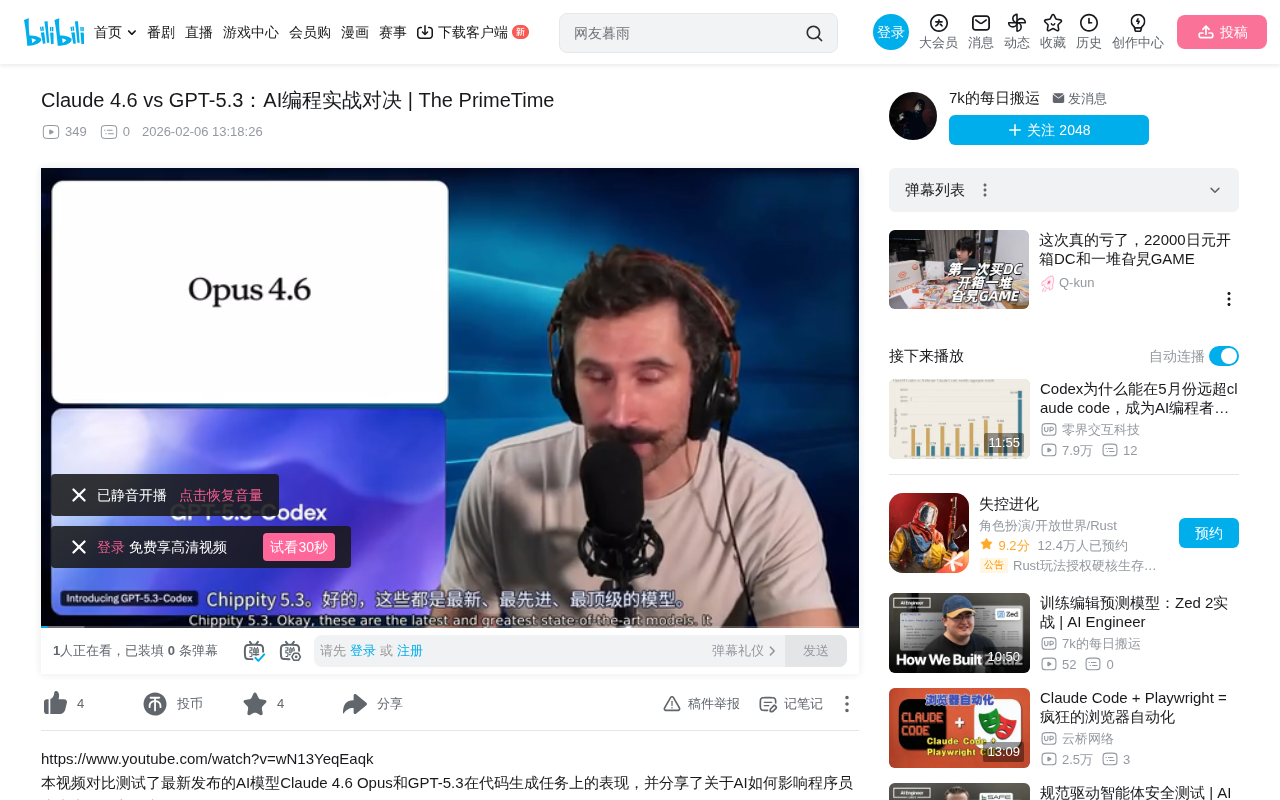
GPT 5.3: Leaner and More Faithful Implementation
GPT 5.3's performance was impressive. It actually implemented real-time JSX compilation, producing a working JSX parser with only 520 lines of Rust code for the compiler portion, and roughly 1,000 lines for the entire JavaScript section. While hot module reloading didn't work successfully, modifying the code and re-running the app did correctly reflect the changes.
From a code quality perspective, ThePrimeagen said he preferred GPT's coding style — cleaner organizational structure, more logical function separation, and better overall readability.
Claude Opus 4.6: More Features but Suspected of "Cheating"
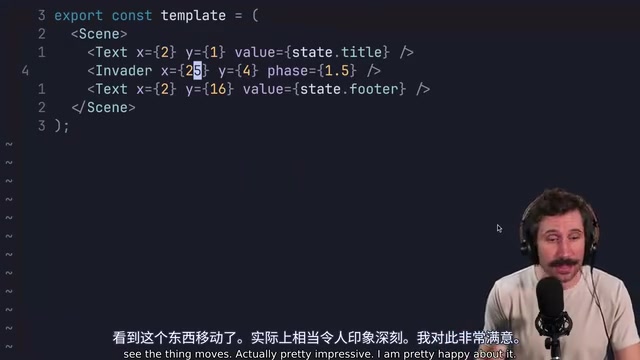
Opus 4.6's situation was more complicated. It did successfully implement hot module reloading — a key feature — but on the core requirement of JSX compilation, it essentially "cheated." Rather than truly compiling JSX, it used direct function calls as a substitute. ThePrimeagen even asked Opus itself about this issue, and Opus's response was interesting: it acknowledged that GPT 5.3 took a "creative approach" that, while more like a DSL (Domain-Specific Language) than standard JSX, genuinely bypassed the entire JavaScript ecosystem's JSX toolchain.
In terms of code volume, Opus generated approximately 2,000 lines of JavaScript and 1,300 lines of Rust, but that Rust compiler wasn't actually performing real JSX compilation. In comparison, GPT achieved a more faithful implementation with less code.
Overall Verdict: GPT 5.3 Wins by a Slim Margin
ThePrimeagen gave his judgment: GPT 5.3 wins this showdown. The core reasoning is simple — it achieved a more faithful implementation of the requirements (actual JSX compilation) with less code (520 lines Rust + 1,000 lines JS vs. 1,300 lines Rust + 2,000 lines JS). While Opus performed better on hot module reloading, it clearly cut corners on the most critical JSX transformation task.
The More Important Takeaway: AI Programming's "Multiplier Effect" Theory

However, ThePrimeagen believes the outcome of this showdown isn't actually that important. He raised a more profound point: the gap between today's top AI models is no longer decisive. Regardless of which model you use, as long as you yourself know what you're doing, they can all produce decent results.
He went further to propose a "grand unified theory" — AI's impact on programmers is a multiplier effect, not an additive one.

He defines a programmer's capability value on a scale from -1 to 1 (note: not 0 to 1). Some programmers have a negative contribution — the code they write costs the team even more time to fix and refactor. AI as a multiplier amplifies this coefficient:
- A skilled programmer with a capability value of 0.8 might become 8.0 with AI, dramatically increasing output
- A programmer with a capability value of -0.1 will simply create technical debt 10x faster with AI
"People who can't write good code are just writing bad code faster. People who can write good code — their output increase isn't actually that dramatic."
This point is sharp but hits the mark. The true value of AI programming tools depends on the engineering competence of the person using them.
The Real Sweet Spot of AI Programming
ThePrimeagen also shared what he considers AI's most valuable use case: having AI run integration tests, analyze failure causes, generate diagnostic reports, and then coming back 30 minutes later to review AI's analysis and follow up on leads. This approach "saves several hours every day" and represents genuine productivity gains.
This suggests that the best practice for AI programming tools may not be having them generate large amounts of code from scratch, but rather using them for debugging, analysis, and testing — tasks that require extensive repetitive labor.
Conclusion
In an era where AI models are updated with increasing frequency, it's easy to get caught up in endless debates about "which model is better." But ThePrimeagen's hands-on test reminds us: the gap between models is shrinking; the real gap lies in the users themselves. Rather than chasing the latest model version numbers, invest time in improving your own engineering skills — because AI is the multiplier, and you are the multiplicand.
Related articles
 Product Reviews
The Programmer's Desk Setup Guide: Building a Workspace That Feels Like Home
Discover how programmers build productive, comfortable workspaces. From multi-monitor setups to ergonomic design, explore the desk philosophy that drives focus and flow.
 Product Reviews
Qoder vs Cursor Real-World Comparison: Which $20/Month AI IDE Is Better?
Hands-on comparison of Qoder vs Cursor AI IDEs: Agent autonomy, human interaction count, and architecture decisions. Qoder needed only 2 interactions vs Cursor's 8.
 Product Reviews
Cursor Cloud Agent Demo: Eliminating Bottlenecks Across the Entire Software Development Lifecycle
Deep analysis of Cursor's Cloud Agent demo showing how cloud VMs, automated test artifacts, and a full-chain control plane systematically eliminate human bottlenecks across the software development lifecycle.