CMNIE: A Deep Dive into the Chinese Military News Information Extraction Benchmark Dataset

CMNIE: the first joint IE benchmark for Chinese military news, exposing critical LLM limitations in precise structured extraction.
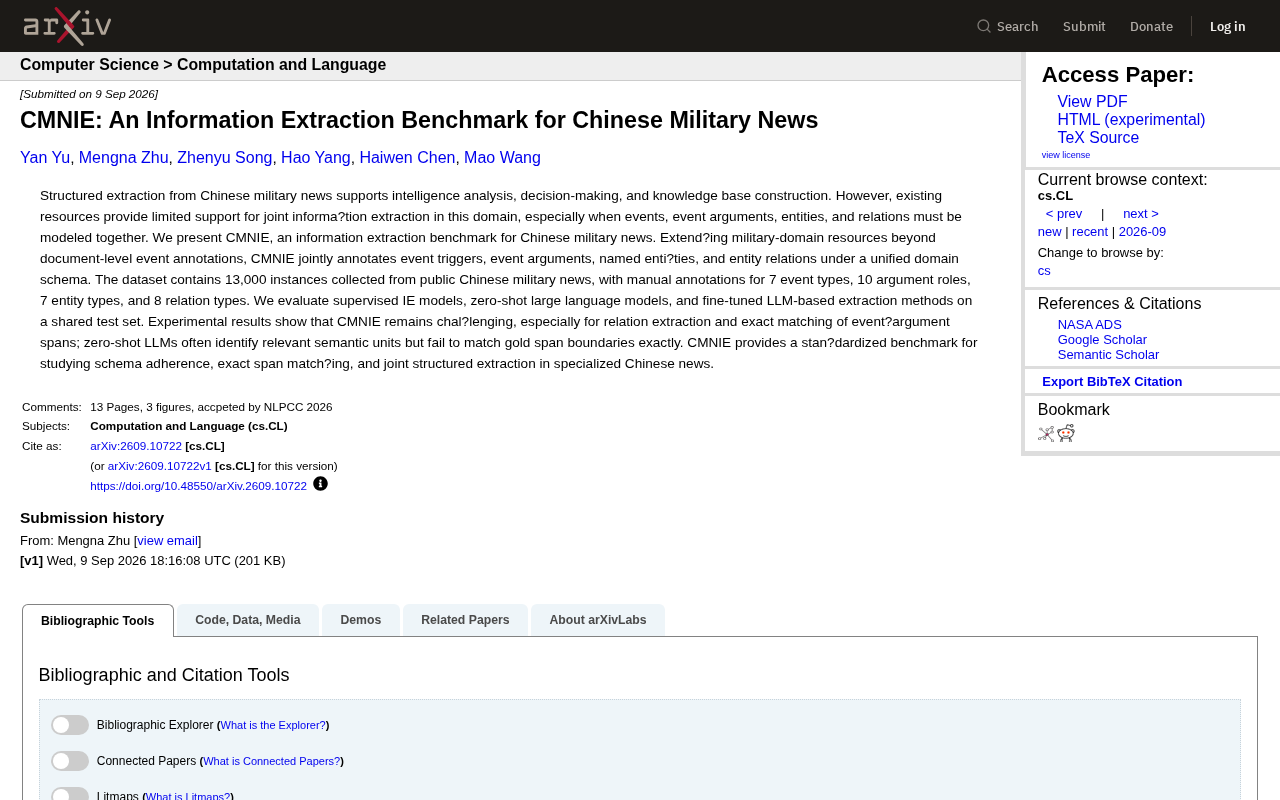
CMNIE (Chinese Military News Information Extraction) is a benchmark dataset for Chinese military news featuring 13,000 manually annotated instances with unified schema coverage of event triggers, arguments, named entities, and relations across 7 event types, 10 argument roles, 7 entity types, and 8 relation types. Experiments comparing supervised models, zero-shot LLMs, and fine-tuned LLMs reveal that relation extraction and exact argument span matching remain the primary challenges. Notably, zero-shot LLMs demonstrate strong semantic understanding but fail at character-level boundary alignment, confirming that supervised modeling and targeted fine-tuning remain essential in schema-constrained professional settings.
The Value of Structured Extraction in Military Intelligence
Extracting structured information from large volumes of Chinese military news is essential for intelligence analysis, decision support, and knowledge base construction. Yet for a long time, this domain has lacked high-quality resources capable of supporting Joint Information Extraction — particularly when events, event arguments, entities, and relations need to be modeled in a unified framework. Existing datasets have offered limited support for such requirements.
A recent paper published on arXiv introduces CMNIE (Chinese Military News Information Extraction), a benchmark dataset specifically designed for information extraction from Chinese military news. It aims to fill the gap in fine-grained, multi-task joint annotation resources within this domain.
Core Design of the CMNIE Dataset
A Unified Domain Annotation Schema
Unlike most prior military-domain resources that focus primarily on document-level event annotation, CMNIE jointly annotates four categories of information under a single unified domain schema:
- Event Triggers
- Event Arguments
- Named Entities
- Entity Relations
The significance of this design lies in how tightly interconnected information tends to be in military news. A combat event involves not just the trigger word itself, but also participating entities, time and location details, weapons and equipment, and the affiliation or adversarial relationships among entities. Only by modeling all these elements within the same framework can we truly reconstruct the structured knowledge embedded in news text.
Dataset Scale and Annotation Granularity
According to the paper, CMNIE contains 13,000 instances, all collected from publicly available Chinese military news and manually annotated. The annotation schema covers:
- 7 event types
- 10 argument roles
- 7 entity types
- 8 relation types
This level of granularity allows the dataset to support both traditional event extraction tasks and benchmarking for named entity recognition and relation extraction, providing a solid data foundation for multi-task joint modeling.
Experimental Evaluation: A Cross-Comparison of Three Mainstream Approaches
The research team evaluated three mainstream information extraction paradigms on a shared test set:
- Supervised IE Models
- Zero-shot LLMs
- Fine-tuned LLM-based Methods
By comparing these three paradigms, the paper seeks to answer a key question: what is the current state of information extraction technology when applied to professional-domain Chinese text?
Relation Extraction and Exact Span Matching Remain Core Challenges
Experimental results show that CMNIE remains highly challenging for existing models, particularly in two areas:
- Relation Extraction: Models perform poorly when identifying complex relationships between entities — consistent with the inherent difficulty of the relation extraction task.
- Exact Matching of Event-Argument Spans: Models struggle to accurately delineate argument boundaries.
One especially noteworthy finding is that zero-shot LLMs can often identify relevant semantic units, but fail to precisely match the gold span boundaries. In other words, LLMs have a rough sense of where the answer lies, but cannot achieve character-level precision alignment. This finding serves as a warning for practitioners relying on zero-shot LLMs for extraction tasks — strong semantic understanding does not translate directly into high-precision structured extraction.
Research Significance and Key Takeaways
A Standardized Evaluation Benchmark for Domain-Specific IE
The greatest value of CMNIE lies in providing a standardized benchmark for investigating three core research questions:
- Schema Adherence: Whether model outputs conform to predefined domain schemas;
- Exact Span Matching: The boundary precision of extracted results;
- Joint Structured Extraction: The capacity for multi-task collaborative modeling.
At a time when general-domain information extraction benchmarks are increasingly mature, evaluation resources for specialized vertical domains — especially high-value scenarios like Chinese military news — remain relatively scarce. CMNIE offers a reproducible, comparable evaluation platform for follow-up research in this direction.
Rethinking IE Paradigms in the LLM Era
As large language models have demonstrated impressive zero-shot capabilities across a wide range of NLP tasks, there was a period of optimism that LLMs could handle information extraction "out of the box." However, CMNIE's experimental results remind us that in professional scenarios requiring strict schema constraints and precise boundary alignment, zero-shot LLMs still exhibit clear limitations. Fine-tuning, supervised modeling, and targeted optimization for span boundary matching will remain indispensable technical approaches for the foreseeable future.
Conclusion: A New Benchmark for Chinese Military Information Extraction
Through joint annotation of events, arguments, entities, and relations under a unified schema, CMNIE fills a critical resource gap in Chinese military news information extraction. Its 13,000 manually annotated instances and multi-dimensional evaluation framework not only expose the limitations of current techniques in relation extraction and exact span matching, but also set a new standard for structured extraction research in specialized domains. For researchers focused on vertical-domain NLP, automated military intelligence analysis, and the structured output capabilities of large language models, CMNIE is a benchmark resource well worth close attention.
Related articles

Vibe Coding Full-Stack in Practice: AI Programming from Beginner to Enterprise Deployment
From Cursor to Claude Code, this Bilibili AI programming course uses four progressive projects to cover full-stack development, open-source secondary development, and team collaboration. The article analyzes the shock to frontend roles, the efficiency shift from 50 people to 5, and the methodology required for enterprise-grade projects.

David Blaine's Global Quest for Real Magic: From South Africa to Japan and India
David Blaine travels to South Africa, Japan, and India in his Do Not Attempt special, documenting Spinning drivers, black mamba rescuers, iaijutsu masters, and ascetics—exploring the boundary between magic and real human极限 challenges.

Is a Touchscreen MacBook Coming? Vergecast Reveals Apple Executive's Response
Vergecast podcast reveals a conversation between a reporter and Apple executive John Ternus about a touchscreen MacBook and Apple Pencil support. Ternus says iPad is the best device for a stylus, while the reporter bets MacBook will eventually support Apple Pencil.