Computer Use Benchmarks: Ten Pitfalls That Make a Single Correct Run Take 400 Hours
A practitioner's post-mortem on why computer use benchmark numbers can't be trusted, and how to run them properly.
Drawing on roughly 200 GitHub issues and maintainer experience, the article shows how easily computer use benchmark (e.g., OSWorld) scores are distorted. A clean evaluation takes ~400 machine hours, yet most teams publish after one run, where best-of and average can differ by 2.6 points. The author catalogs ten recurring distortion sources — capacity, preparation, rate limits, isolation, runtime failures, retries, scoring, reproducibility, observability, and cost — and gives a checkpoint and fix for each, such as warm pools, avoiding non-idempotent retries, preserving failure evidence, and maintaining a run manifest. The core conclusion: each fix exposes the next problem; a proper run must hold up under all ten at once with a unique attempt ID throughout. Before trusting any score, ask how it was run.
Most people run a benchmark once and publish the leaderboard. This practitioner's post-mortem explains why those numbers may not be worth trusting at all.
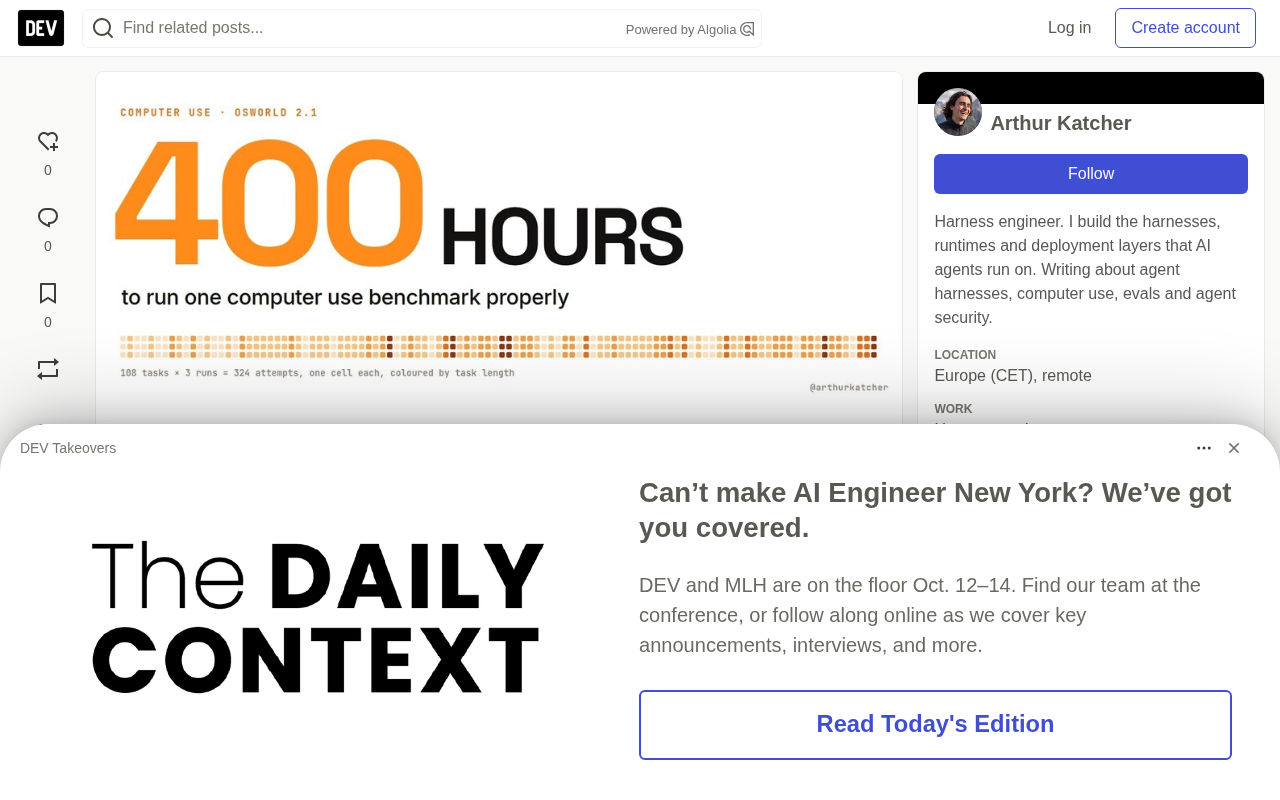
A single correct run of a Computer Use benchmark takes roughly 400 machine hours. That's not an exaggeration — OSWorld 2.1's 108 tasks, run three times and averaged after every change to the evaluation harness, works out to 324 attempts, with a median task taking 46 minutes in a clean run and the longest reaching 8.9 hours.
The original author read roughly 200 GitHub issues and pull requests, drawn from the maintainer teams behind OSWorld, SWE-bench, and Terminal-Bench, and found the same ten problems recurring again and again. Drawing on his own experience building an agent runtime, he offers a fix for each.
Why benchmark scores are so unreliable
Computer use is the hardest evaluation scenario. A code benchmark only needs a container with a shell, whereas a computer use benchmark needs an entire desktop environment for every attempt — its own apps, its own websites — with the agent executing hundreds of steps per task.
In the OSWorld-Verified results tracked by Yutori, 94 of 111 records that note how many runs were performed only ran once. A few teams do repeat: Anthropic ran Claude Fable 5.1 five times on OSWorld 2.0 and averaged, and Yutori ran its own Navigator n2 three times.
The problem is that within the same benchmark, taking the best of three runs versus the average can differ by 2.6 percentage points. Simular's published run data shows 0.7674 when counting each task's first clean run, versus 0.7938 when taking the best run. That gap is enough to change a model's position on a leaderboard.
What is a "computer use" benchmark? Unlike code benchmarks (SWE-bench needs only a Docker container with a shell), a computer use benchmark requires the agent to operate a graphical desktop like a human: opening apps, clicking buttons, filling out forms in a browser, dragging files across windows. Representative work includes OSWorld (108 cross-application tasks), Terminal-Bench (terminal operations), and Yutori's Navigator suite. Each task typically requires the agent to execute dozens to hundreds of steps of an "observe screen — decide action — execute action" loop, involving screenshots, coordinate clicks, and keyboard input. This brings a qualitative shift in evaluation: the environment is no longer a single reproducible process but a stateful virtual desktop with a GUI and network dependencies, where any step's latency or crash can send the whole trajectory off course — so the correctness requirements for isolation, retries, and scoring are far higher than for pure code tasks.
Ten problems that distort scores
The author lays the problems out in a table covering the full pipeline from resource scheduling to cost accounting:
| Problem | Impact on the number | What to check |
|---|---|---|
| 1. Capacity | The slowest task drags the whole round | Effective results per hour |
| 2. Preparation | Environment setup time hidden inside task time | Every readiness step |
| 3. Rate limits | Throttled tasks end early | Calls per attempt vs. quota |
| 4. Isolation | Attempts contaminate each other's results | Run two attempts concurrently |
| 5. Runtime failure | A crash looks like agent failure | Timeouts and real health checks |
| 6. Retries | Actions execute twice; best-of read as average | When retries happen |
| 7. Scoring | Infrastructure errors become zero scores | Whether it ran, whether it was scored, whether evidence was kept |
| 8. Reproducibility | Same model, different numbers | Run manifest |
| 9. Observability | Stuck looks like slow | One ID per attempt |
| 10. Cost | Cheap runs prove nothing | Cost per valid result |
Capacity and preparation: the underestimated time sink
Parallel desktops shorten waits but don't change the total work. 400 machine hours is 400 machine hours, and 40 desktops theoretically finish in 10 hours but never do in practice — because the whole round has to wait for the slowest task to end. Simular reports that with 30 parallel environments, a round of OSWorld takes 4 to 5 hours, sometimes 6, all spent waiting on the last few tasks.
40 desktops at default spec means 160 GB of guest memory and 160 virtual CPUs, not counting anything else on the host machine.
Hardware specs alone can change scores. Anthropic found that under strict per-task CPU and memory limits, up to 6% of Terminal-Bench tasks failed due to pod errors unrelated to the model; after relaxing the limits, scores moved by as much as 6 percentage points.
The preparation phase is similarly long. An environment being "ready" has four steps: the image is cached on the host, the VM has booted, the control channel is available, and the files and websites the task needs are in place. The OSWorld team saw LibreOffice take a minute to launch the first time because AWS lazily loads disks restored from snapshots; after compressing the image from 50 GB to 25 GB, first launch dropped to 5 seconds. Epoch found that SWE-bench's task images totaled 684 GiB, which dropped to 67 GiB after rebuilding.
The fix is a warm pool: pre-booting and pre-checking a number of desktops. In the system the author built himself, he measured deployment time dropping from about 60 seconds to under 1 second. But warm must also mean clean — a desktop can only return to the pool after a verified reset.
The relationship between machine hours and parallelism: Machine hours are the sum of CPU/GPU time tasks actually consume, representing incompressible total work. Parallel desktops can only divide wall-clock time by the degree of parallelism (theoretically 400 machine hours ÷ 40 desktops = 10 hours), but two constraints break that ideal: first, the long tail — the whole round must wait for the slowest task, and OSWorld's longest single task is 8.9 hours, so no matter how high the parallelism, you still wait for it; second, resource contention — 40 VMs booting at once compete for the host's disk I/O and network, slowing individual tasks themselves. So real wall-clock time is max(total work / parallelism, longest single task time) multiplied by an efficiency loss factor, which is why warm pools and image slimming (e.g., 50 GB down to 25 GB) can significantly cut time — they directly compress the fixed overhead before each task starts.
Retries and scoring: the two most booby-trapped steps
Retrying before the agent's first action is safe; afterward the desktop has state, and a retry may repeat something that already happened.
An OSWorld PR shows how easily this is overlooked: the desktop terminates commands running longer than 120 seconds and reports an error, and the controller retries every error, including commands that had already partially executed. In that log, 357 of 23,244 actions executed twice. When the duplicated command is a ctrl keypress, the key stays held down for the rest of the task, and the trajectory looks completely normal. Harbor's desktop runtime writes this rule into a code comment: replaying clicks is not idempotent.
Retries at different layers also stack. A Harbor issue describes the SDK and harness retries piling up, where a single hung call could take around 90 minutes.
The scoring step is even more insidious. Simular stepped in this pit while generating its OSWorld 2.1 reference run: the model key's usage cap made the task stop after one step, yet it was recorded as successful with a score of 0. The folder's average score came out to 0.40, which in their words "looked like a measurement result." In the end it was the step count that exposed the problem.
Graders themselves also manufacture false zeros. OSWorld maintainers have an unmerged fix targeting 14 of the 108 tasks — their graders turn failed calls to the judge model into a score of 0.
One team recorded 240 SWE-bench runs all at 0%, blaming their agent the whole time, until they discovered that the gold patch was failing too.
Idempotency: An operation is idempotent if executing it once and twice yields the same result; otherwise it's non-idempotent. Reading a file or querying state is idempotent, whereas "clicking the submit button," "pressing the ctrl key," or "sending a payment" are all non-idempotent — repeating them produces extra side effects. Harbor's runtime writes this rule into a code comment: "Replaying clicks is not idempotent." This is exactly the minefield of retries: when a framework automatically retries a partially executed action after a timeout or error, the agent's trajectory may look flawless while the desktop state has gone haywire (e.g., the ctrl key stays pressed after being pressed twice). The correct approach is to retry only failures that occur before the action is issued, or to give every action a unique ID, have the execution layer guarantee "at-most-once" semantics, and flag in the log whether a replay occurred.
What reproducibility really means
The evaluation harness itself can move the numbers. After fixing a bug in the zoom tool and raising the per-round token limit, Anthropic re-ran older models and found it had been under-reporting OSWorld scores all along. Claude Opus 4.7 went from 78.0% to 82.8% with no model change whatsoever.
The environment changes too. Between OSWorld 2.0 and 2.1, 174 pull requests against task files were merged. Simular ran the same agent on two desktop images and got 0.7766 on one and 0.7414 on the other. Princeton's HAL team notes that OpenRouter may serve differently quantized versions of a model under the same endpoint name — the same name doesn't guarantee the same model.
So every run needs a manifest recording everything that could move the number: task and grader versions, image digests and website builds, the model and the provider route that actually served it, the judge model, the harness commit, observation and action settings, screen size, step and time budgets, per-desktop resources, and retry and repeat policy (average or best-of).
A manifest can't make a model deterministic, but it can tell you what didn't change when the number moves.
The purpose of a run manifest: In machine learning experiments, a random seed alone is far from enough. A reproducible evaluation result depends on a long chain of external state: model weight version and quantization precision, the inference provider actually routed to, the judge model and its prompt, the evaluation harness's git commit, desktop image digest, dependent website build versions, screen resolution, step and time budgets, per-desktop CPU/memory quotas, and retry and repeat policy. The manifest serializes and records all of this, turning problems like "the same model scores differently" into a diff you can investigate rather than mysticism. It can't make results deterministic, but it guarantees that when the number moves, you know which variable moved — a key step from "a single run" toward "verifiable evidence."
Cost and observability
Simular published the model cost of its OSWorld 2.1 reference campaign: 27,662 gateway calls totaling $2,417.63, or about $18 per clean attempt. Desktop hours are not included in that figure.
Leftover resources pile up fast. OSWorld's Docker provider used to leave a 32 GB volume behind per task, filling the disk in under an hour of a full run, until it was fixed.
At scale, cost determines method. HAL spent about $40,000 on its rollouts and still had to rely on single runs for most evaluations. Some models they never ran at all.
Observability, meanwhile, is what distinguishes "slow" from "stuck." One Harbor user spent two days on this kind of stall: experiments waited silently until a 30-minute timeout. The cause was two crashed experiments whose 4 GB sandboxes kept running, filling the account's 10 GB memory cap, so every new sandbox was rejected and silently retried.
The fix is a single attempt ID running from allocation to cleanup, threaded through model calls, desktop actions, scoring, and cleanup, recording the time each stage takes and preserving evidence of failed attempts instead of deleting it.
What a proper run looks like
Each fix looks unremarkable on its own. The problem is that each fix exposes the next one, so a daily run must hold up under all ten at once. That requires eight stations — queue, admission control, ready desktops, attempts, watchdogs, scoring, evidence, and reporting — with a unique attempt ID threaded through everything.
These stations all exist today: parallel desktops, warm pools, retries, and dashboards are found in OSWorld's own runner, Harbor, HUD, Cua, and various sandbox vendors. But a complete setup that runs daily on the exact benchmark package and holds up under every step at once is still rare.
The author's advice is blunt: a benchmark score is the output of a single operation. Before trusting it — whether yours or a lab's — ask how it was run. Keep that table and the manifest; they apply equally to SWE-bench and Terminal-Bench.
For anyone following AI agent evaluation, the value of this article isn't that it provides a "correct answer," but that it reveals an industry reality: many of the numbers on public leaderboards may never have been independently re-run and verified by anyone.
Related articles

ChatGPT Space Launches: Team Collaboration and New Pages Features Explained
ChatGPT Space is OpenAI's new team collaboration feature with Pages, real-time collaboration, and Slack/Google Drive sync. We break down its privacy design, multi-platform integration, and the full workflow from conversation to document.

Migrating Apache Spark UDFs to GPU Acceleration with AI Agents
NVIDIA developer blog explains how AI Agents rewrite Apache Spark UDFs for GPU acceleration, covering migration criteria, agent rewriting and verification workflows, plus pitfalls like result consistency and CPU-GPU transfer overhead.

Zed Editor v0.40.4-rc2 Released: Usage Credits Now Available Without Upgrading
Zed editor releases v0.40.4-rc2, allowing users to use usage credits for AI features without upgrading to a paid plan, lowering the trial barrier.