Context Encoders Deep Dive: Self-Supervised Feature Learning via Image Inpainting

Context Encoders learns transferable visual features via image inpainting — a foundational work in masked modeling.
Context Encoders (2016) proposes image inpainting as a self-supervised task for learning visual features. The network predicts missing content from masked images using an encoder-decoder architecture, with the key innovation being channel-wise fully connected layers that enable long-range spatial communication without parameter explosion. A joint loss of L2 reconstruction and GAN adversarial terms handles structural continuity and output sharpness respectively. No labels are needed, and the learned features transfer competitively to classification, detection, and segmentation — making this a key precursor to modern masked modeling methods like MAE.
Our visual world is highly diverse yet full of structure, and humans possess an almost ineffable ability to understand that structure.
When faced with an incomplete image, humans have an almost instinctive ability to predict what's missing. See a building with one corner obscured, and we automatically "fill in" the missing part — because we know there should be windows, walls, and corresponding textures. Can computer vision develop this same capability? That's precisely the question answered by the classic paper Context Encoders: Feature Learning by Inpainting. This article walks through the core ideas and implementation details of Context Encoders based on the original paper, alongside a from-scratch PyTorch + CelebA reproduction.
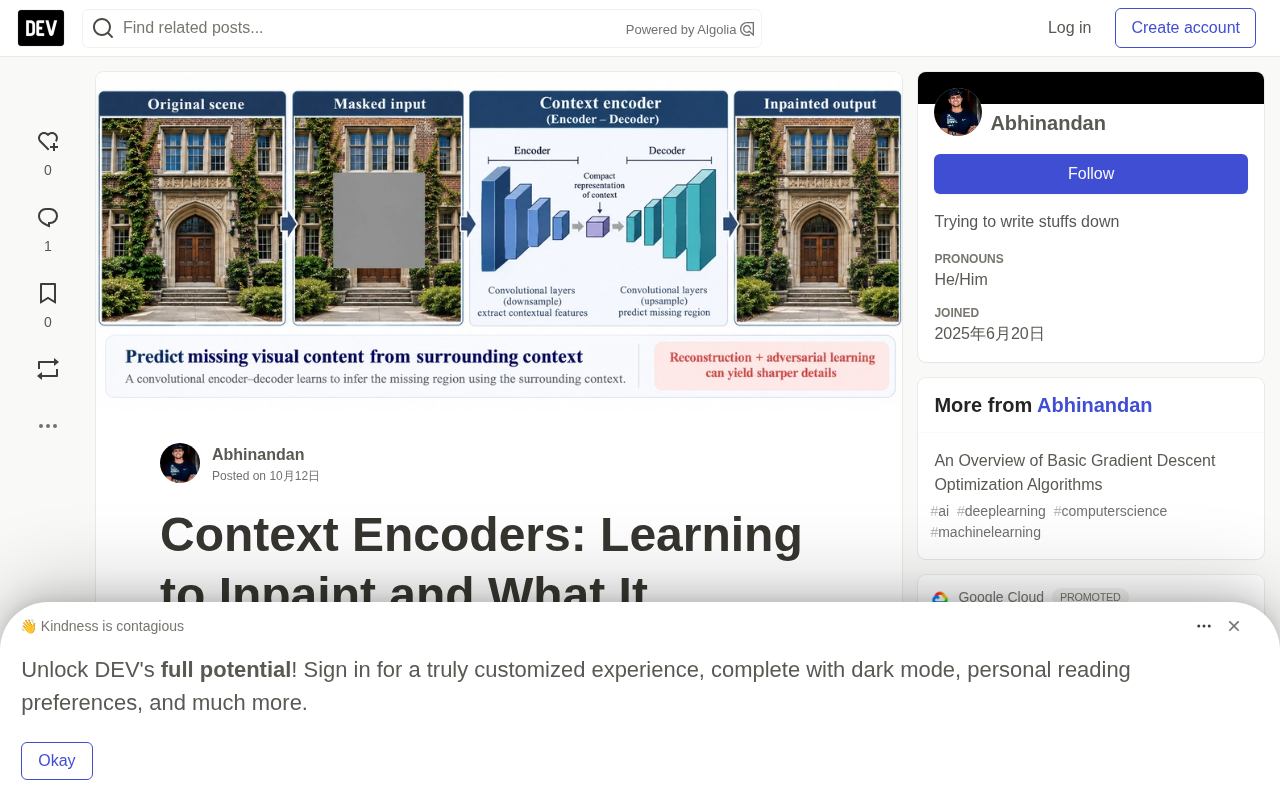
What Is Image Inpainting, and Why Can It Learn Features?
Inpainting refers to restoring or filling in missing, damaged, or unwanted regions of an image so that the repaired areas blend seamlessly with their surroundings. There's a key insight buried in this definition: for a network to reasonably fill in a missing region, it must understand what's actually in the image — and this understanding requires no human-annotated labels whatsoever.
This is exactly the bet Context Encoders makes. It pursues two goals simultaneously:
- Semantic Inpainting: Generate plausible content for the hole, rather than simply smearing in neighboring pixels.
- Unsupervised Feature Learning: Demonstrate that an encoder trained solely on a "fill in the blank" task learns features that transfer to downstream tasks like classification, detection, and segmentation.
In other words, inpainting is just the surface — the real payoff is that the encoder is forced to learn semantic representations of images in the process. This is why it's considered a foundational step in self-supervised learning.
The Encoder-Decoder Architecture: Why There's No Bottleneck
A Context Encoder is essentially a convolutional encoder-decoder structure. The encoder compresses a masked image into a compact latent feature representation, and the decoder uses that representation to generate the missing image content. The overall approach resembles the classic autoencoder, but with one critical difference.
The encoder in the original paper is taken from the first five convolutional layers plus pooling from AlexNet, mapping a 227×227 input down to a 6×6×256 representation. But it isn't trained for ImageNet classification — it starts from random weights and is trained only on the inpainting task.
The most significant departure from a traditional autoencoder is that there is no narrow bottleneck layer. A standard autoencoder must reconstruct the entire input, so it needs a small encoding to prevent the network from simply "copying" the input. In a Context Encoder, however, the input already has a hole, and the target is the missing content — the network is naturally forced to "infer" rather than "copy." No artificially narrow bottleneck is needed to create learning pressure.
In the 128×128 CelebA version reproduced here, the AlexNet style is preserved but strides are adjusted so that the latent feature map becomes 8×8×256, with BatchNorm and LeakyReLU added after each convolution. The BatchNorm is an additional stabilization measure not described in the original paper.
class Encoder(nn.Module):
    def __init__(self):
        super().__init__()
        def block(cin, cout, k, s, p):
            return nn.Sequential(
                nn.Conv2d(cin, cout, k, s, p, bias=False),
                nn.BatchNorm2d(cout),
                nn.LeakyReLU(0.2, inplace=True))
        self.net = nn.Sequential(
            block(3,   64,  7, 2, 3),   # 128 -> 64
            nn.MaxPool2d(3, 2, 1),      # 64  -> 32
            block(64,  192, 5, 1, 2),   # 32
            nn.MaxPool2d(3, 2, 1),      # 32  -> 16
            block(192, 384, 3, 1, 1),   # 16
            block(384, 256, 3, 1, 1),   # 16
            block(256, 256, 3, 1, 1),   # 16 (conv5)
            nn.MaxPool2d(3, 2, 1),      # 16  -> 8 (pool5)
        )
    def forward(self, x):
        return self.net(x)
An autoencoder is a neural network that compresses its input into a low-dimensional "bottleneck" representation and then reconstructs it. The core assumption is that if the network must reconstruct the input from an encoding much smaller than the input itself, it is forced to retain only the most important information, thereby learning meaningful features. However, this assumption has a pitfall — a bottleneck that's too small loses too much detail, while one that's too large degenerates into simple copying. Context Encoders sidestep this dilemma entirely: the presence of the hole eliminates the possibility of direct copying, and the network must rely on context to "infer" rather than "memorize" the missing parts — no artificially narrow bottleneck required. This design philosophy was later taken further by works like MAE (Masked Autoencoders), which use a high masking rate in place of a bottleneck constraint to force the model to learn semantic representations.
Channel-Wise Fully Connected Layers: Letting Information Span the Entire Image
This is the most central architectural innovation in Context Encoders. Convolutional layers connect all feature maps together, but never connect distant spatial positions within a single feature map — meaning information in one corner cannot flow directly to the opposite corner. For inpainting, this is a genuine limitation: the pixels most predictive of the center of a face may be located far from the center.
A fully connected layer would solve this problem, since every activation is connected to every other, but at the cost of an explosion in parameters. Connecting a 256-channel, n×n feature map to the decoder with a full FC layer requires m²n⁴ parameters — the paper notes this exceeds 100 million parameters, which was simply infeasible to train on GPUs of that era.
The solution is a channel-wise fully connected layer: each feature map has its own n²×n² weight matrix, with no connections across different feature maps. This reduces the parameter count from m²n⁴ to m·n⁴. For the 8×8×256 latent features used here, that means roughly 256 × 8⁴ ≈ 1.05 million weights, versus approximately 268 million for a full FC layer. Since this layer doesn't mix channels, the paper follows it with a stride-1 convolution (implemented here as a 1×1 convolution) to propagate information across channels.
class ChannelWiseFC(nn.Module):
    def __init__(self, channels, size):
        super().__init__()
        self.n2 = size * size
        self.weight = nn.Parameter(torch.empty(channels, self.n2, self.n2))
        self.bias = nn.Parameter(torch.zeros(channels, self.n2))
        bound = 1 / self.n2 ** 0.5
        nn.init.uniform_(self.weight, -bound, bound)
    def forward(self, x):
        B, m, n, _ = x.shape
        x = x.reshape(B, m, self.n2)
        x = torch.einsum('bmi,mij->bmj', x, self.weight)
        return (x + self.bias).reshape(B, m, n, n)
The decoder consists of the channel-wise FC layer, a 1×1 convolution, and five up-convolution layers that progressively upscale the feature maps back to pixel space, ending with Tanh to match the [-1, 1] normalization range.
Dual Loss: The Division of Labor Between Reconstruction and Adversarial Loss
A hole often has multiple plausible fills, so Context Encoders use a decoupled joint loss function that handles "continuity with context" and "multimodality of outputs" separately.
Reconstruction Loss: Capturing Structure, at the Cost of Blurriness
The first component is a normalized masked L2 distance, comparing predictions to ground truth only within the hole. The mask M zeros out all pixels the network has already seen, preventing the model from scoring by copying context.
class ReconstructionLoss(nn.Module):
    def forward(self, pred, target, mask):
        diff = mask * (target - pred)
        sq_err = diff.pow(2).sum(dim=(1, 2, 3))
        norm = mask.sum(dim=(1, 2, 3)) * pred.size(1) + 1e-8
        return (sq_err / norm).mean()
The reconstruction loss has a well-known weakness: it encourages the general shape of missing objects but fails to capture high-frequency detail. The reason is that when multiple fills are plausible, the safest L2 prediction is the "mean" of the distribution — and the mean of many sharp faces is a blurry face.
Adversarial Loss: Using a GAN to Turn Blur into Sharpness
To fix this blurriness, the paper introduces a GAN-style adversarial loss. A discriminator D learns to distinguish real images from Context Encoder outputs, while the Context Encoder acting as generator G tries to fool it. This way, generating a sharp, realistic face scores better than generating a blurry mean.
The paper makes two key choices in adapting the GAN:
- The generator is conditioned on context, but the discriminator is not. If the discriminator also sees the context, it can trivially exploit visible discontinuities between the generated and original regions to identify fakes — a shortcut that undermines learning.
- No noise vector is used. The authors found that omitting noise actually worked better; the context itself provides sufficient variation.
class AdversarialLoss(nn.Module):
    def __init__(self):
        super().__init__()
        self.bce = nn.BCEWithLogitsLoss()
    def d_loss(self, d_real, d_fake):
        return (self.bce(d_real, torch.ones_like(d_real)) +
                self.bce(d_fake, torch.zeros_like(d_fake)))
    def g_loss(self, d_fake):
        return self.bce(d_fake, torch.ones_like(d_fake))
The final objective is a weighted sum of both losses, with the reconstruction term dominant and the adversarial term acting as a "sharpening push." The generator and discriminator are jointly optimized through alternating updates. It's worth noting that the paper reports adversarial training diverges in its AlexNet feature learning experiments — so the adversarial loss is used only for inpainting experiments, not for feature learning pretraining.
Generative Adversarial Networks (GANs), proposed by Goodfellow et al. in 2014, pit a generator against a discriminator: the generator tries to synthesize convincingly real samples, while the discriminator tries to expose them. The two train alternately in a dynamic "cat and mouse" game that theoretically converges to a Nash equilibrium. The key advantage of GANs is that they define an implicit, data-driven loss function — the discriminator automatically learns to penalize any output inconsistent with the real distribution, including blurriness, color artifacts, and missing textures that L2 loss cannot perceive. But GAN training is notoriously unstable and prone to mode collapse (where the generator produces only a few types of outputs) or outright divergence. The fact that adversarial loss in Context Encoders is used only for inpainting and not for feature learning pretraining reflects exactly this instability — the paper's authors observed divergence in the AlexNet feature learning setting.
Masking Strategy, Training, and Results
The paper uses three masking strategies:
- Central Region: A square block at the center of the image. The simplest approach, but the network may overfit to the fixed hole location and learn features that don't generalize.
- Random Block: Multiple small rectangles at random positions. The location varies, but sharp rectangular edges still give the network positional hints.
- Random Region: Irregular patches drawn with a random-walk brush stroke. This most closely resembles real-world occlusions, and the paper reports it works best for feature learning.
In this implementation, each mask covers at most roughly one quarter of the image. During training, one mask type is chosen randomly per batch, and training runs for 20 epochs.
class ContextEncoder(nn.Module):
    def __init__(self):
        super().__init__()
        self.encoder = Encoder()   # AlexNet style
        self.decoder = Decoder()   # Channel-wise FC -> 1x1 conv -> 5 up-convolutions
    def forward(self, masked_img):
        return self.decoder(self.encoder(masked_img))
The paper's conclusion is that reconstruction loss alone produces blurry completions, while adding the adversarial loss yields sharper, more realistic results. More importantly, encoders pretrained this way — when fine-tuned on PASCAL VOC — achieve classification, detection, and segmentation results competitive with the unsupervised pretraining methods of the time, all without relying on ImageNet labels.
For small-scale reproductions, a few thousand CelebA images and a few dozen epochs typically produce reasonable but somewhat soft completions. Faces are relatively tractable due to their high structural regularity, but fine-grained textures like hair and skin require far more data and training — a reflection of data and compute constraints, not architectural flaws.
Limitations and Impact: From Context Encoders to Masked Modeling
This approach has real limitations: output sharpness depends on a delicate GAN balance; a single deterministic output cannot capture the multiple plausible fills for large holes; and the channel-wise FC layer is tied to a fixed latent size, making it difficult for the network to natively handle images at different resolutions.
But its ideas have carried forward. Subsequent GAN-based inpainting methods added global and local discriminators, contextual attention, and gated convolutions to handle larger, more irregular holes. Meanwhile, masked modeling approaches like Masked Autoencoders (MAE) return to the same core bet: mask part of the input, predict it, and collect well-learned representations as a byproduct. Context Encoders is one of the earliest and clearest demonstrations that this approach works for images — a pivotal contribution to the history of self-supervised visual learning.
Masked Autoencoders (MAE), proposed by He et al. in 2021, combine the masked modeling idea with Vision Transformers (ViT), pretraining an encoder at an extremely high masking rate of 75% to achieve strong downstream transfer performance. Compared to Context Encoders, MAE uses no adversarial loss — it relies entirely on pixel-level reconstruction loss — yet benefits from the Transformer's global attention mechanism, which naturally enables cross-location information flow without the need for a specially designed channel-wise FC layer. This contrast clearly illustrates how architectural advances can make a simpler objective function yield stronger representations. When Context Encoders was proposed (2016), GPU compute and large-scale dataset limitations forced numerous engineering compromises; by the time MAE arrived, "aggressive masking + large models" had become viable — but the core assumption underlying both works is identical.
Related articles

JobRunner MCP Server: AI Agents Can Now Fix Failed Java Jobs
JobRunner launches an open-source MCP server enabling AI agents to view cluster status, diagnose failures, and recover Java jobs—incident response from any cloud coding environment or existing agent.

MLAI Digital Launches 9 Security Agents: MCP Server Safeguards the Full Lifecycle of Agentic AI
MLAI Digital launches Security MCP Server with nine built-in specialized security agents covering vulnerability discovery, attack simulation, prompt injection detection, API and infrastructure assessment, and accelerated remediation—embedding security validation across the full Agentic AI lifecycle from development to production.

Running Isaac Lab on H100 GPUs: Exploring Better Approaches
Exploring optimization methods for running Isaac Lab on NVIDIA H100 GPUs, including MIG configuration, mixed precision, TensorRT acceleration, and community experience to improve robotics simulation and reinforcement learning efficiency.