Cube Studio: Tencent's Open-Source One-Stop AI Platform — A Deep Dive into Full MLOps Lifecycle

Cube Studio is Tencent Music's open-source one-stop cloud-native MLOps AI platform.
Cube Studio is a one-stop ML/DL/LLM AI platform open-sourced by Tencent Music, built on Kubernetes cloud-native architecture. It covers the full MLOps lifecycle including data labeling, Notebook development, Pipeline orchestration, multi-framework distributed training, LLM fine-tuning (SFT/RLHF), and inference deployment. Key highlights include comprehensive adaptation for domestic CPUs/GPUs/Huawei Ascend NPUs for Xinchuang compliance, VGPU virtualization for fine-grained GPU management, and integration with mainstream inference engines like vLLM — ideal for medium-to-large enterprises and government customers building unified AI platforms.
Project Overview: What is Cube Studio?
Cube Studio is a one-stop machine learning/deep learning/large model AI platform open-sourced by Tencent Music, built on a cloud-native architecture. It has garnered nearly 5,000 stars on GitHub. The project covers the entire MLOps lifecycle from data labeling and model training to inference deployment, making it one of the few open-source AI platforms in China with such comprehensive functionality.
MLOps (Machine Learning Operations) is a methodology that brings DevOps principles into the machine learning domain, aiming to solve the "last mile" problem of getting models from experimentation to production. A complete MLOps workflow typically includes data collection and labeling, feature engineering, model training and validation, model registry and version management, deployment, monitoring, and feedback loops. In traditional approaches, each stage might use different tools (e.g., Airflow for scheduling, MLflow for experiment tracking, Seldon for inference serving), leading to high integration costs and broken pipelines. Cube Studio's value lies in unifying these stages within a single platform, reducing "glue code" and operational overhead.
For enterprises and teams, building a complete AI infrastructure often requires integrating dozens of open-source components. Cube Studio addresses this pain point with a unified platform — allowing algorithm engineers to focus on the models themselves rather than infrastructure setup and maintenance.
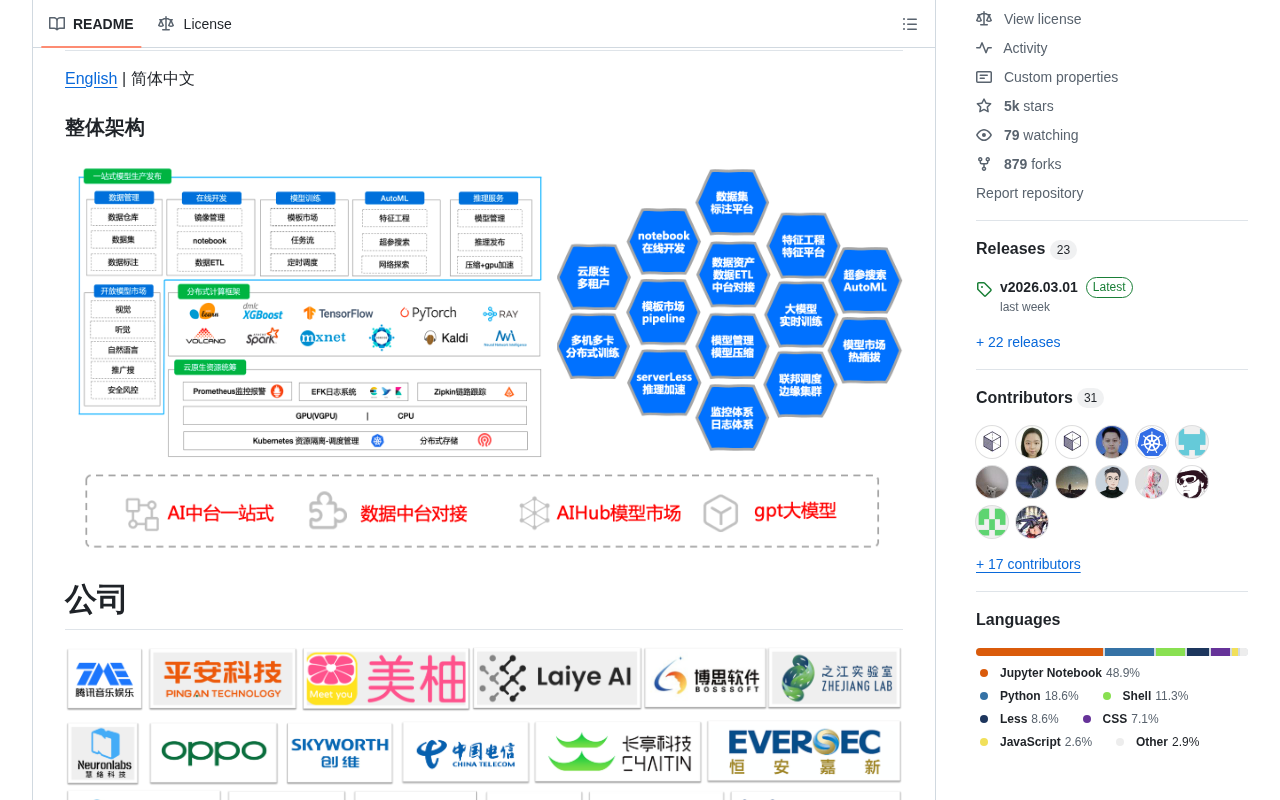
Core Feature Modules in Detail
Notebook Online Development Environment
Cube Studio provides a web-based Notebook online development environment supporting mainstream development tools like Jupyter. Developers can write code, debug, and experiment directly in the browser without configuring a local environment, significantly lowering the barrier to entry for AI development.
Pipeline Drag-and-Drop Workflow Orchestration
The platform supports drag-and-drop Pipeline workflow orchestration, allowing users to chain together data processing, feature engineering, model training, evaluation, and other steps into complete workflows through a visual interface. This low-code approach makes managing complex algorithm pipelines intuitive and reproducible, while boosting team collaboration efficiency.
Multi-Framework Distributed Training
At the training layer, Cube Studio supports multi-node, multi-GPU distributed training with extensive framework compatibility:
- Deep Learning Frameworks: PyTorch, TensorFlow, MXNet, PaddlePaddle
- Distributed Acceleration Frameworks: DeepSpeed, ColossalAI, Horovod
- General Computing Frameworks: Ray, Volcano
Large-scale AI model training requires distributing computational workloads across multiple GPUs on multiple machines, involving various parallelism strategies such as data parallelism, model parallelism, and pipeline parallelism. DeepSpeed is Microsoft's open-source deep learning optimization library, renowned for its ZeRO (Zero Redundancy Optimizer) technology that shards optimizer states, gradients, and parameters across devices, dramatically reducing memory usage. ColossalAI, developed by HPC-AI Tech, offers automatic parallelism and heterogeneous memory management. Horovod, open-sourced by Uber, achieves efficient gradient synchronization based on the Ring-AllReduce algorithm. Ray is a general-purpose distributed computing framework whose Ray Train module supports elastic training. Volcano is a CNCF batch scheduling system designed for HPC and AI training scenarios, supporting Gang Scheduling to ensure all Pods of a distributed task start simultaneously.
The platform also supports RDMA high-speed network communication, ensuring that communication efficiency across nodes doesn't become a bottleneck for large-scale training tasks. RDMA (Remote Direct Memory Access) is a network communication technology that bypasses the OS kernel to transfer data directly between network adapters. In traditional TCP/IP communication, data undergoes multiple memory copies and kernel/user space context switches, with latency typically in the microsecond to millisecond range. RDMA reduces latency to sub-microsecond levels with bandwidth utilization approaching line rate (e.g., 200Gbps InfiniBand). In large-scale distributed training, gradient synchronization (AllReduce) is the primary communication bottleneck — RDMA's low latency and high throughput characteristics can significantly reduce communication wait times, improving training efficiency by 20%-50%. Common RDMA implementations include InfiniBand and RoCE (RDMA over Converged Ethernet).
Large Model Training and Fine-Tuning
Keeping pace with the large model era, Cube Studio integrates SFT (Supervised Fine-Tuning), reward model training, and RLHF (Reinforcement Learning from Human Feedback) training capabilities for large models like DeepSeekAd. Enterprises can quickly perform domain adaptation and alignment training based on open-source large models without building training pipelines from scratch.
Large model training typically consists of three stages: Pre-training, Supervised Fine-Tuning (SFT), and Reinforcement Learning from Human Feedback (RLHF). The SFT stage uses high-quality human-annotated instruction-response pairs to fine-tune the pre-trained model, enabling instruction-following capabilities. The RLHF stage first trains a Reward Model to simulate human preference judgments, then uses reinforcement learning algorithms like PPO (Proximal Policy Optimization) to optimize the language model's output policy, making generated content better aligned with human expectations. This workflow was systematically proposed by OpenAI in the InstructGPT paper and has become the mainstream paradigm for current alignment technology. Chinese large models like DeepSeek follow similar training procedures.
Inference Services and Model Deployment
At the inference layer, the platform supports mainstream large model multi-node inference solutions including vLLM, Ollama, and MindIE, along with VGPU virtualization capabilities for fine-grained GPU resource management and sharing. Additionally, the platform supports model deployment in edge computing scenarios to meet diverse business needs.
vLLM is a high-performance large model inference engine open-sourced by UC Berkeley. Its core innovation is PagedAttention technology — borrowing from the OS virtual memory paging management concept, it dynamically allocates and reclaims KV Cache (key-value cache) by pages, solving the memory fragmentation and waste issues in traditional inference. This achieves 2-24x throughput improvement compared to HuggingFace Transformers. Ollama positions itself as a local large model runtime tool, providing a Docker-like model management experience. MindIE is Huawei's inference engine built on the Ascend ecosystem, deeply optimized for Ascend NPUs. Multi-node inference (Tensor Parallelism + Pipeline Parallelism) distributes ultra-large model shards across multiple machines to overcome single-machine memory limitations.
Domestic Ecosystem: Full-Stack Chinese Hardware Adaptation
A key highlight of Cube Studio is its comprehensive support for Chinese domestic hardware ecosystems, covering:
- Domestic CPUs
- Domestic GPUs
- Huawei Ascend NPUs
Given the current international landscape, this domestic hardware adaptation capability is especially critical for government and enterprise customers, enabling the entire AI platform to run stably in a purely domestic computing environment and meeting Xinchuang (信创) compliance requirements.
Xinchuang (Information Technology Application Innovation) is China's national strategy to promote autonomous control of critical information infrastructure, requiring core systems to gradually transition to domestic software and hardware. In the AI computing domain, the domestic ecosystem primarily includes: Huawei Ascend NPU series (e.g., 910B/910C) using the Da Vinci architecture, with the companion CANN computing framework and MindSpore deep learning framework; Hygon DCU (Deep Computing Unit), compatible with the ROCm ecosystem; and Cambricon MLU series with the Cambricon Neuware SDK. On the domestic CPU side, there are Kunpeng (ARM architecture), Phytium, Loongson, and Hygon. Cube Studio's adaptation to these heterogeneous hardware platforms requires extensive compatibility development at the operator, communication, and scheduling layers — this is crucial for compliant deployment in government, finance, and telecommunications sectors.
Platform Operations Capabilities
Computing Power Leasing and Multi-Tenant Resource Management
The platform includes built-in computing power leasing functionality, supporting multi-tenant resource isolation and quota management. Combined with VGPU virtualization technology, physical GPUs can be partitioned into multiple virtual GPUs, significantly improving resource utilization and reducing idle computing waste.
VGPU (Virtual GPU) virtualization technology allows splitting a physical GPU's computing power and memory into multiple logical GPU instances, assigned to different containers or virtual machines. In AI platform scenarios, many inference tasks or small-scale training tasks don't require an entire GPU's resources. VGPU technology enables fine-grained GPU resource allocation (e.g., allocating 0.5 cards, 2GB memory), increasing overall GPU utilization from a typical 30%-40% to over 70%. Common implementation approaches include NVIDIA MPS/MIG, Fourth Paradigm's VGPUScheduler, and Tencent's in-house GPU Manager. Cube Studio's VGPU capability allows multiple users to safely share the same GPU while preventing mutual interference through memory isolation.
Data Labeling and AI Model Marketplace
Cube Studio integrates an automated labeling platform, effectively reducing the labor costs of data annotation. It also provides an AI model marketplace and private knowledge base functionality, facilitating internal model sharing, version management, and knowledge accumulation within teams.
Technical Architecture and Community Ecosystem
Cube Studio is built on a Kubernetes cloud-native architecture, inherently providing elastic scaling, high availability, and containerized deployment capabilities.
Cloud Native is a methodology for building and running applications using containers, microservices, declarative APIs, and immutable infrastructure. Kubernetes (K8s), as the core orchestration engine of cloud native, handles automatic container scheduling, elastic scaling, service discovery, and fault recovery. For AI platforms, Kubernetes advantages include: managing distributed training tasks through the Operator pattern (e.g., PyTorch Operator, TF Operator), managing heterogeneous hardware resources like GPUs/NPUs via the Device Plugin mechanism, and achieving multi-tenant isolation through Namespaces and ResourceQuotas. Cube Studio builds its resource management and task scheduling system on these K8s-native capabilities.
With Python as the primary development language, it's also easy for AI developers to get started and contribute to the community.
The project currently has 877 forks with an active community and continuous iterative updates.
Use Cases and Selection Recommendations
Cube Studio is particularly well-suited for the following scenarios:
- Medium to Large Enterprises: Building unified internal AI platforms to consolidate fragmented algorithm toolchains
- Government and Enterprise Customers: Organizations requiring domestic hardware adaptation and Xinchuang compliance
- Large Model Teams: Business scenarios requiring large model fine-tuning and private deployment
- Computing Resource Management: Organizations needing fine-grained GPU scheduling and multi-team sharing
Conclusion
As one of the most feature-complete open-source AI platforms in China, Cube Studio integrates the entire MLOps lifecycle into a single platform, forming a complete closed loop from development and training to deployment. Comprehensive functionality also means relatively higher deployment and maintenance complexity, but for teams with adequate infrastructure capabilities, it provides an extremely valuable starting point — saving the enormous cost of assembling multiple open-source components on their own.
Related articles
 Product Reviews
The Programmer's Desk Setup Guide: Building a Workspace That Feels Like Home
Discover how programmers build productive, comfortable workspaces. From multi-monitor setups to ergonomic design, explore the desk philosophy that drives focus and flow.
 Product Reviews
Qoder vs Cursor Real-World Comparison: Which $20/Month AI IDE Is Better?
Hands-on comparison of Qoder vs Cursor AI IDEs: Agent autonomy, human interaction count, and architecture decisions. Qoder needed only 2 interactions vs Cursor's 8.
 Product Reviews
Cursor Cloud Agent Demo: Eliminating Bottlenecks Across the Entire Software Development Lifecycle
Deep analysis of Cursor's Cloud Agent demo showing how cloud VMs, automated test artifacts, and a full-chain control plane systematically eliminate human bottlenecks across the software development lifecycle.