DeepSeek 4.1 Flash 1017 Now Free: A Roundup of Limited-Time Offers Across Three Platforms

DeepSeek 4.1 Flash 1017 is free for a limited time on OpenCode and Coder, with key usage tips.
The article rounds up the free availability of DeepSeek 4.1 Flash 1017 on two platforms. OpenCode offers DeepSeek 4.1 Flash 1017 and GLM 5.3 Flash for free (both 200K context, no end date announced), plus MiniMax M3.1 Flash free for only three days (1M context); quotas are per-IP. Coder offers international and domestic versions with an October 24 deadline and limited first-come quotas. Before use, set context to "EM" in model management to unlock full long-context capability. Rules come from a creator's roundup; platform policies may change, so check the pages.
DeepSeek 4.1 Flash 1017 has recently become available for free on multiple platforms, offering developers and AI enthusiasts a low-cost window to try it out. According to a roundup by Bilibili creator "AI Egg Daily Report," both OpenCode and Coder currently offer free quotas for this model, alongside GLM 5.3 Flash, MiniMax M3.1 Flash, and others. Here's a breakdown of the key details.
OpenCode: Three Flash Models Free at Once
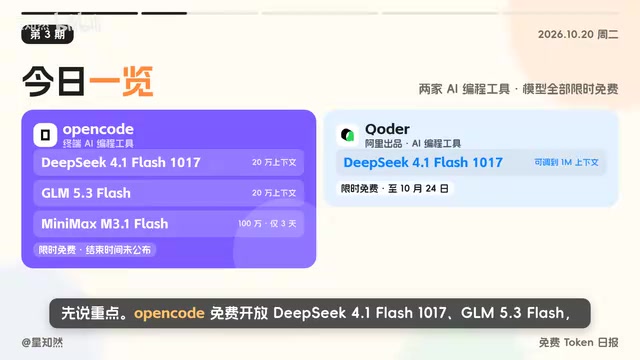
OpenCode isn't just offering one model this time—it's three Flash-series models: DeepSeekAd 4.1 Flash 1017, GLM 5.3 Flash, and MiniMax M3.1 Flash.
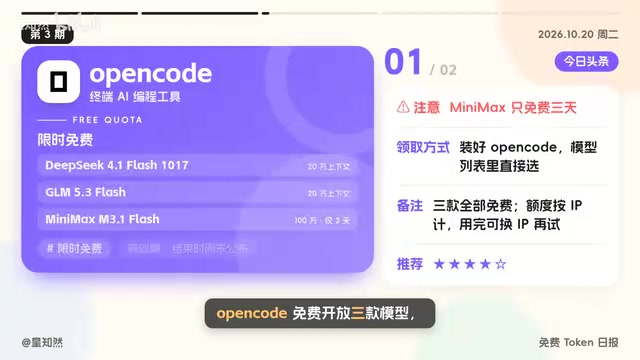
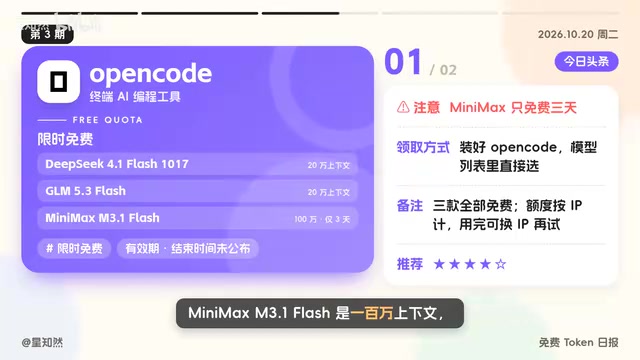
DeepSeek 4.1 Flash 1017 and GLM 5.3 Flash both offer a 200K context window, with no end date announced yet. MiniMax M3.1 Flash offers a 1M context window but is free for only three days.
Quotas are calculated per IP address—once you've used yours up, switching to another IP lets you continue. This means shared network environments will burn through quotas faster, while individual users should find it relatively generous.
The context window is a core metric for how much information a large model can process in a single pass, typically measured in tokens. A 200K context is roughly equivalent to over 100,000 Chinese characters or several thousand lines of code, meaning the model can "see" an entire technical document, a mid-sized codebase, or a long conversation history at once—without the fragmented information that comes from feeding it in chunks. A 1M context further supports coherent understanding of full books, large project source code, or multi-turn ultra-long sessions. Note that nominal context length often differs from actual usable length: some platforms enable a smaller window by default and require manual adjustment in model settings, and long contexts also bring higher inference costs and the "lost in the middle" problem, where the model retrieves information in the middle of the window less reliably than at the beginning or end. So when evaluating these free models, look beyond the headline number—confirm the actual window size the platform enables and whether your task genuinely needs such long inputs.
Coder: DeepSeek 4.1 Flash 1017 Available in Two Versions
Coder also offers DeepSeek 4.1 Flash 1017 for free, in both international and domestic versions, with a deadline of October 24.
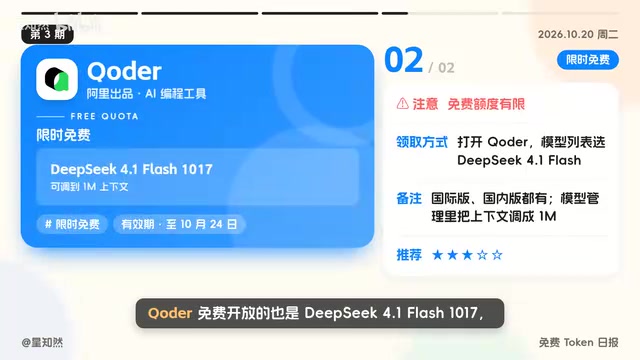
Free quotas are limited and available on a first-come, first-served basis. For users who need cross-border access or have specific routing requirements, the dual-version entry points offer more flexibility.
The difference between "international" and "domestic" entry points typically comes down to service node location, access routing, and account systems. The international version is mostly deployed in overseas data centers—domestic users connecting directly may experience higher latency or need additional network conditions, but model versions tend to update faster. The domestic version is optimized for local networks, offering more stable access and lower response latency, suitable for daily high-frequency use. For developers, the choice should depend on call volume, sensitivity to latency, and whether you need to interface with overseas services. The same model may have subtle differences in inference parameters or default context values between versions, so when comparing results, keep version variables fixed to avoid mistaking routing differences for model capability differences.
One Key Setting Before Use
The creator specifically reminds users: before using, go to model management and set the context to "EM." This setting is easy to overlook but directly affects whether the model can leverage its full context capability—especially with long documents or large code blocks.
"EM" is the platform's internal name for a context tier—not a universal term for the model itself. Different platforms may use different codes for modes like "extended context" or "maximum context." This setting matters because many inference services enable shorter windows by default to control VRAM usage and response costs; only by explicitly switching in model management or call parameters will the full context load. Without adjustment, even if the model nominally supports 200K or 1M tokens, long documents may be truncated in practice—showing up as missing earlier information in answers or incomplete code completion. Before use, confirm the current tier, the per-request token limit, and whether switching affects billing or rate limits.
A Few Practical Takeaways
Looking at the information itself, the common thread here is "limited time + limited quota + per-IP." DeepSeek 4.1 Flash 1017 is free on both platforms, but Coder has a clear deadline (October 24), while OpenCode hasn't announced an end date—meaning it could change at any time.
Among the three models, MiniMax M3.1 Flash's 1M context is the differentiator, but the three-day window is very short—best suited for focused testing of scenarios with clear long-context needs. GLM 5.3 Flash and DeepSeek 4.1 Flash 1017 both offer 200K context, making them suitable for side-by-side comparison.
Note that the quota rules and deadlines above come from the creator's roundup; platform policies may change at any time, and the actual terms on each platform's pages should prevail. Following update channels like "New Nature" can help you stay informed about changes to free quotas.
One-line Summary
DeepSeek 4.1 Flash 1017 is free for a limited time on OpenCode and Coder, with key usage tips.
Paragraph Summary
This article summarizes the free availability of DeepSeek 4.1 Flash 1017 on two platforms. OpenCode offers DeepSeek 4.1 Flash 1017 and GLM 5.3 Flash for free (both with 200K context, no end date announced), plus MiniMax M3.1 Flash free for only three days (1M context); quotas are per-IP, and switching IPs lets you continue. Coder offers both international and domestic versions of the model, with an October 24 deadline and limited first-come, first-served quotas. Before use, set the context to "EM" in model management, or the long-context capability won't be fully utilized. The article notes that these rules come from the creator's roundup, platform policies may change at any time, actual terms on the pages should prevail, and following update channels is recommended for quota changes.
Related articles

Cursor Can Now Control Your Computer: AI Agents Can Drive Desktop Apps for Testing
Cursor adds desktop control: AI agents can drive desktop apps like the iOS Simulator to test their own features. We analyze the impact on dev workflows, possible technical approaches, and reliability concerns.

Vibecoding a Custom Inference Engine: High Hopes, Harsh Reality
A Reddit developer shares the real experience of vibecoding a custom inference engine: running GGUF Q4 models in the browser with WebGL2 and GLSL, only to fall into tokenizer debugging hell. This article analyzes the engineering challenges of browser-side LLM inference and why cloning llama.cpp is the more rational choice.

How High Are Anthropic's Early Investor Paper Returns Ahead of IPO?
Anthropic's early investor paper returns draw attention ahead of IPO. This article analyzes sources of book gains, capital structure, pre-IPO games and risks, and implications for the AI startup ecosystem.