DeepSeek Elastic Compute (DSec) Hits Hacker News Front Page

DeepSeek's DSec elastic compute paper trends on Hacker News, spotlighting GPU resource scheduling for large models.
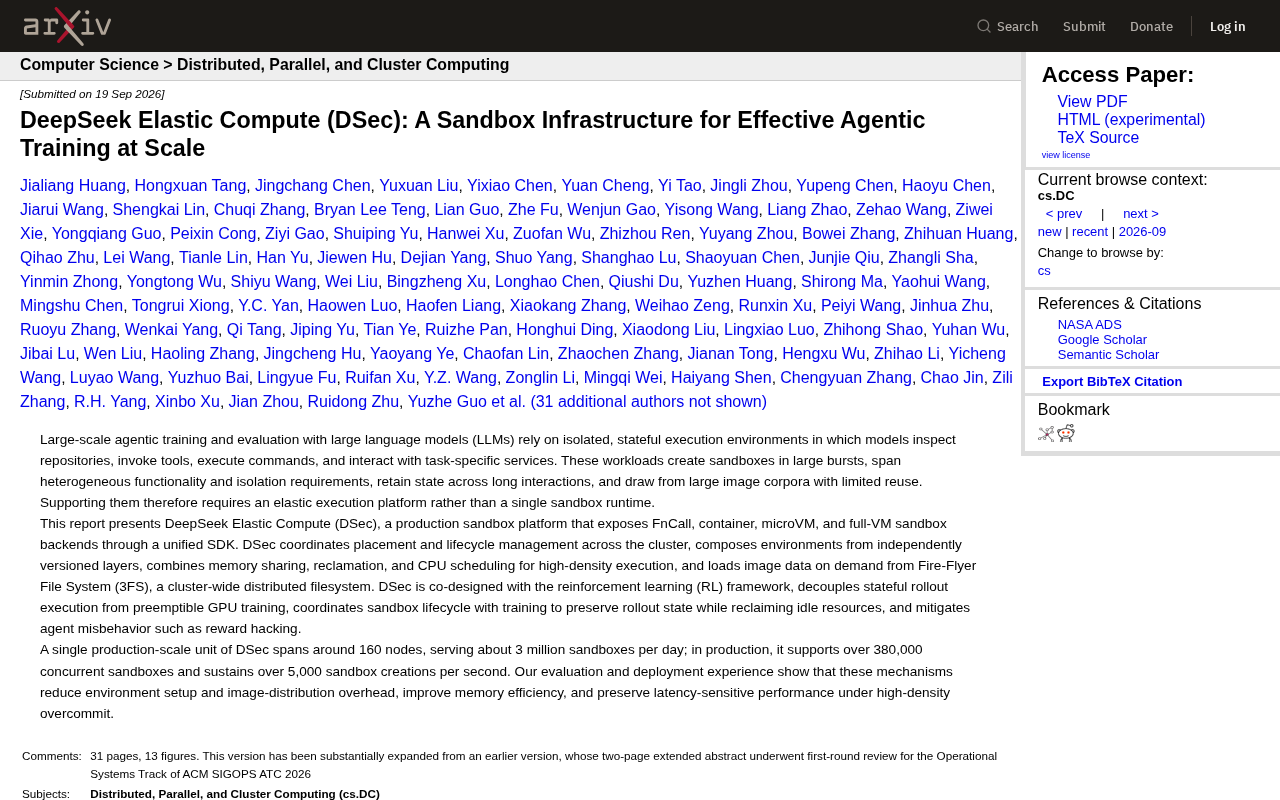
An arXiv preprint titled DeepSeek Elastic Compute (DSec) recently reached the Hacker News front page with 186 upvotes and 57 comments. Based on its name, DSec appears to be an elastic compute scheduling framework for large model inference or training, aimed at dynamically scaling GPU resources across traffic peaks and valleys to balance service quality and operational cost. GPU idle waste is a core pain point in AI infrastructure today, making any meaningful engineering solution a natural draw for the technical community. Due to limited source material — only the title, links, and engagement data were available — the article cannot assess DSec's specific technical mechanisms or performance claims, and readers are encouraged to consult the arXiv paper and Hacker News discussion directly.
Introduction
A paper titled DeepSeekAd Elastic Compute (DSec) recently made it to the Hacker News front page, accumulating 186 upvotes and 57 comments and sparking interest in the technical community around DeepSeek's elastic compute approach. Unfortunately, the source material available for this article is limited to the links for the paper and discussion page along with basic engagement metrics — the full text of the paper itself was not accessible. As a result, this article focuses primarily on the context and significance of the topic rather than a deep technical breakdown.
Topic Overview
Based on the Hacker News page data, the content listed as DeepSeek Elastic Compute (DSec) originates from the arXiv preprint platform and points to an academic paper. The combination of 186 points and 57 comments suggests the topic carries genuine discussion value among technical readers — that level of engagement typically signals content that addresses real problems practitioners care about, rather than mere marketing.
From the name alone, DSec most likely centers on elastic compute scheduling for large model inference or training workloads. "Elastic Compute" is a well-established concept in cloud computing — its core goal is to dynamically scale computational resources up and down in response to load fluctuations, striking a balance between cost and performance. Applied in the context of DeepSeek, it likely refers to elasticity optimizations tailored to the specific architecture of their models.
In cloud computing, elastic compute typically relies on mechanisms like Auto Scaling Groups, triggering instance addition or release based on CPU/memory utilization thresholds. Applying this same idea to GPU-intensive large model inference, however, introduces additional challenges: GPU instance startup latency is far higher than for CPU instances; loading model weights — often hundreds of gigabytes — can itself take tens of seconds to several minutes. Beyond that, synchronizing KV Cache state across multiple instances, enabling lossless request migration, and coordinating batching strategies across nodes are all problems that general-purpose cloud elasticity solutions have never had to solve. A truly purpose-built elastic compute framework for large models therefore requires targeted innovations at the systems design level, not a simple reuse of existing cloud-native scaling capabilities.
Why This Matters
DeepSeek has been one of the most closely watched large model teams in recent times, with its engineering practices around inference efficiency and training cost consistently drawing industry attention. If DSec is indeed a framework for elastic compute at the scale of large model serving, it directly addresses one of the most critical pain points in today's AI infrastructure: how to reduce the idle waste of expensive resources like GPUs while maintaining service quality.
In practice, large model request traffic often exhibits pronounced peaks and valleys. Statically reserving compute capacity leads to enormous waste during off-peak periods, while insufficient capacity causes latency spikes during peak periods. Any solution that meaningfully improves this tradeoff will naturally attract the engineering community's attention — which explains why this topic landed on the Hacker News front page.
Resource scheduling for large model inference services is particularly complex from an engineering standpoint. Transformer-based large models exhibit a significant imbalance in KV Cache memory usage and compute intensity during inference: the prefill phase is compute-bound, while the decode phase is constrained by memory bandwidth — and the two make fundamentally different demands on GPU resources. When request concurrency fluctuates sharply, statically allocated GPU instances struggle to handle sudden peaks while sitting largely idle during quiet periods. Given the rental costs of high-end GPUs like A100s and H100s, this kind of waste places considerable pressure on commercial operations. Research efforts such as Splitwise and Sarathi have already explored separating the Prefill and Decode phases to improve throughput, while elastic scheduling frameworks address the problem at the resource orchestration layer — enabling dynamic scale-out across instances. This makes it an indispensable component of the overall systems stack.
A Note on Source Limitations
It is worth being transparent: the source material available for this piece is quite limited. We have access only to the paper's title, its arXiv link, the Hacker News discussion link, and the upvote and comment counts. The paper's abstract, methodology, experimental results, and the specific viewpoints raised in community discussion were not accessible. As a result, this article cannot draw definitive conclusions about DSec's technical mechanisms, performance improvements, or applicable scenarios.
Readers interested in the subject are encouraged to visit the arXiv paper directly and the Hacker News discussion page for primary sources and in-depth community commentary.
Conclusion
The traction gained by DeepSeek Elastic Compute (DSec) reflects the industry's sustained focus on optimizing AI compute efficiency. Elastic compute remains a critical pathway for reducing the operational costs of large models, and it will continue to be a shared challenge for both academia and industry. As more details become public, we will follow up with a closer look at the technical merits and real-world impact of this approach.
Related articles

FastAPI: A High-Performance Python Framework and a Production-Ready API Development Powerhouse
FastAPI is a high-performance web framework based on Python type hints, supporting async and automatic OpenAPI docs. With over 100k GitHub stars, this article analyzes its core strengths, production readiness, and selection advice.

Tesla Optimus Begins Mass Production: Can the Goal of 20,000 Units Per Week Be Achieved?
Tesla Optimus officially begins mass production as Musk sets a target of 20,000 units per week. This article analyzes the supply chain challenges behind mass production, the real gap in capacity ramp-up, and the competitive landscape for humanoid robots.

PCL: A Minecraft Launcher with 8.5k Stars — Why Was It Written in VB.NET?
An in-depth analysis of PCL, the GitHub Minecraft launcher with 8,500+ stars: why it chose VB.NET, its features and China network advantages, and the limits of Windows-only.