Depth Estimation Under Mirrored Clothing: Subject Stays Sharp, But Why Does the Background Disappear?
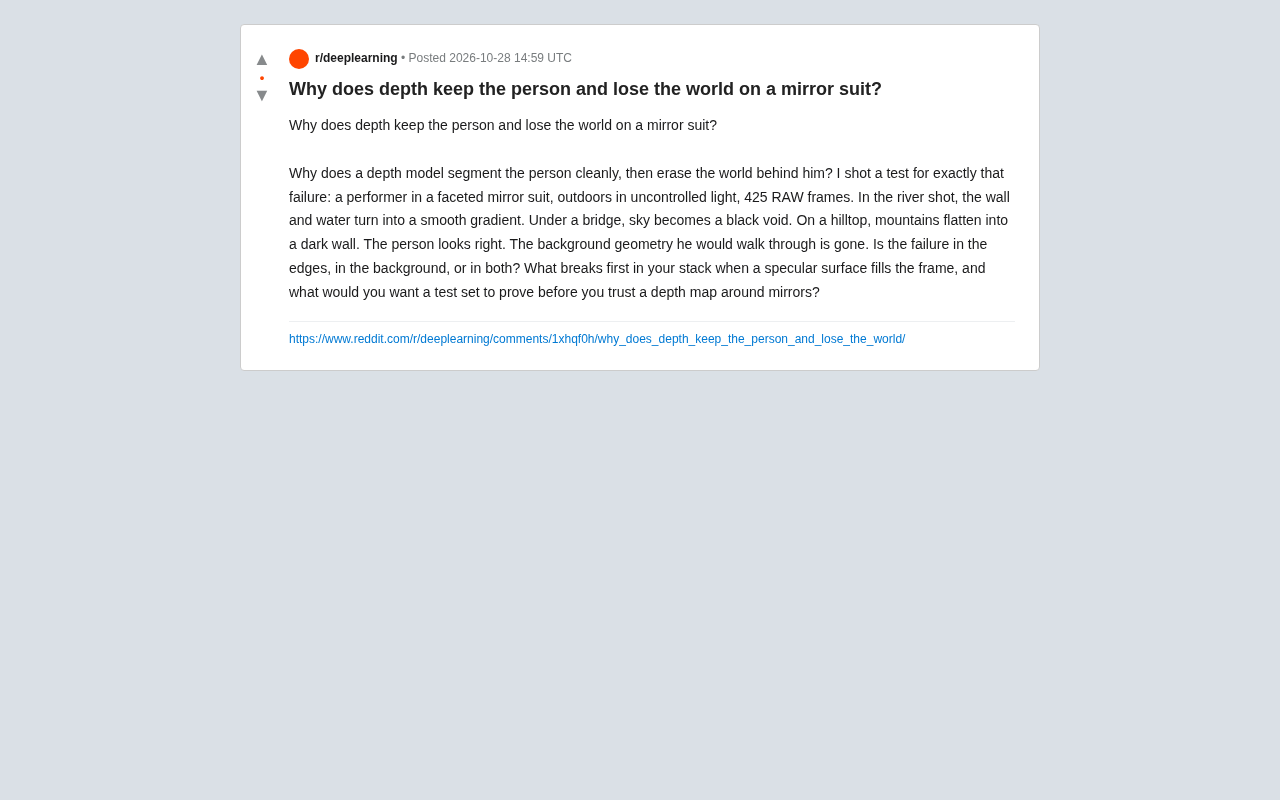
Mirrored clothing makes depth models lose background geometry while person segmentation stays clear.
A Reddit user tested a performer in a multi-faceted mirrored suit using 425 RAW frames and found the depth model segmented the person accurately but severely lost background geometry: riverside walls and water became smooth gradients, sky under a bridge became a black hole, and distant mountains flattened into a black wall. The root cause is specular reflections destroying depth cues like texture and shadow, preventing the model from distinguishing reflected virtual images from real background. Edge and background issues combine, but background degradation is more fundamental. Solutions require mirrored test sets and reflection-aware modules or multi-view constraints.
In computer vision, depth estimation models typically segment people accurately, but when faced with mirror-like materials, the background is often erased. A Reddit user tested a performer wearing a multi-faceted mirrored suit using 425 RAW frames and found that riverside walls and water surfaces turned into smooth gradients, the sky under a bridge became a black hole, and distant mountains were flattened into a black wall. The subject's outline was precise, but the background geometry was lost. This raises a key question: does the failure occur at the edges or in the background, or both?
Test Scenario and Observations
The test was conducted outdoors under uncontrolled lighting, with the subject wearing a multi-faceted mirrored suit, and a total of 425 RAW images were captured. In the riverside scene, the walls and water surface should have had rich textures and geometric structures, but the depth map compressed them into smooth gradients, losing distance information. In the under-bridge scene, the sky region was predicted as a black void, whereas in reality the sky has infinite depth. In the mountain-top scene, the distant mountains were simplified into dark walls, lacking a sense of depth. The segmentation of the person remained clear, indicating that the model has strong person recognition capabilities but suffers from systematic flaws in depth reasoning for highly reflective regions.
RAW frames refer to unprocessed raw data output by the image sensor, retaining complete linear light information and high dynamic range, without white balance, demosaicing, or tone mapping. In depth estimation research, using RAW frames instead of compressed formats like JPEG avoids artifacts and dynamic range compression introduced by post-processing, more faithfully reflecting the lighting information captured by the sensor, and thus more accurately evaluating the model's robustness to extreme lighting conditions such as specular reflections.
Root Cause of Failure: Edges or Background?
The mirrored clothing surface reflects the surrounding environment, causing local pixel values to be highly similar or even identical to the background. This poses a challenge for edge detection: the boundary between the person and the background may be blurred by reflections, but in the test the person's outline remained complete, suggesting that edge processing is not the main bottleneck. The more likely issue lies in the background region: depth models rely on texture, shadows, and perspective cues, but specular reflections destroy these cues, making it impossible for the model to distinguish between the "reflected virtual image" and the "real background geometry." When mirrors occupy most of the frame, the model may misinterpret the reflected content as the background itself, or output uniform depth values due to the lack of reliable features. Therefore, the failure is a combined result of edges and background, but background degradation is more fundamental.
A Lambertian surface refers to an ideal diffuse reflecting surface that follows Lambert's cosine law, where the reflected light intensity is independent of the viewing angle and depends only on the direction of incident light and the surface normal. Most depth estimation models assume during training that the scene consists of Lambertian surfaces, relying on diffuse cues such as texture and shadows to infer depth. Mirrored materials, however, exhibit non-Lambertian characteristics, with strongly directional reflections that mirror the surrounding environment, breaking the diffuse assumption on which the model relies and causing depth cues to fail.
Technical Challenges and Possible Directions
To solve this problem, both data and models need to be addressed. At the data level, test sets containing mirrored materials should be constructed, covering different lighting, angles, and scene complexities, to verify the model's robustness under reflective conditions. At the model level, reflection-aware modules can be introduced to explicitly separate the reflection layer from the transmission layer, or multi-view geometric constraints can be used to recover background structure. Additionally, depth estimation models should learn to identify specular regions and reduce their confidence to avoid over-smoothing. Before trusting a depth map, the test set should demonstrate that the model can still maintain plausible background geometry when mirrors fill the frame, for example by comparing with ground-truth depth or validating with synthetic data.
The core idea of reflection-aware modules is to decompose the image into a reflection layer and a transmission layer (or intrinsic image decomposition), thereby explicitly modeling specular reflections. Traditional methods include physics-based reflection models or blind source separation; in recent years, deep learning methods have trained networks to predict reflection components and have been applied in tasks such as reflection removal and intrinsic image decomposition. Introducing such modules into depth estimation can help the model distinguish between virtual images from specular reflections and real scene geometry, reducing the interference of reflections in depth reasoning.
Multi-view geometric constraints use images of the same scene from different viewpoints to recover 3D structure through triangulation. For mirror regions, because the reflected content changes with viewpoint, the multi-view consistency assumption is violated; however, by detecting and removing inconsistent pixels, non-mirror regions can still be used to constrain background geometry. By incorporating multi-view information, depth models can more reliably infer background structures occluded by mirrors, or identify reflective regions and reduce their confidence.
Conclusion
Mirrored clothing exposes the fragility of current depth estimation models on non-Lambertian surfaces. The accuracy of person segmentation masks the failure of background reconstruction, reminding us that in complex real-world scenes, depth perception still requires more robust algorithms and more comprehensive evaluation benchmarks.
One-line Summary
Mirrored clothing causes depth models to lose background geometry while person segmentation remains clear.
Paragraph Summary
A Reddit user tested a performer wearing a multi-faceted mirrored suit using 425 RAW frames and found that the depth estimation model accurately segmented the person but severely lost background geometry: riverside walls and water surfaces turned into smooth gradients, the sky under a bridge became a black hole, and distant mountains were flattened into a black wall. Analysis shows that the root cause is that specular reflections destroy depth cues such as texture and shadows, making it impossible for the model to distinguish reflected virtual images from the real background. Edge and background issues act together, but background degradation is more fundamental. Solutions require both data and models: building mirrored test sets and introducing reflection-aware modules or multi-view constraints.
Related articles
OpenAI Breaks ETH? P=NP Could Upend the Cryptography World
OpenAI reportedly disproved ETH with a sub-exponential algorithm, sparking P=NP speculation. What it means for RSA, blockchain, and protein folding.
When an Anti-Fingerprinting Script Is …
When an Anti-Fingerprinting Script Is Flagged as a Bioweapon: The Detection Dilemma of Security Tools
An anti-fingerprinting script was flagged as a bioweapon by security scanning, sparking Hacker News debate. This analysis covers the causes of keyword-matching false positives, how developers respond, and the long-term imbalance between automation and precision in security tools.
41,000 DHS Employee Records Leaked, Including Undercover ICE Agents
Data breach exposes 41,000 DHS employees, including undercover ICE agents. Analysis of sensitive data risks, law enforcement security gaps, and protection measures like access control and auditing.