Embodied AI and Humanoid Robots: Cross-Disciplinary Exploration of Cognitive Architectures
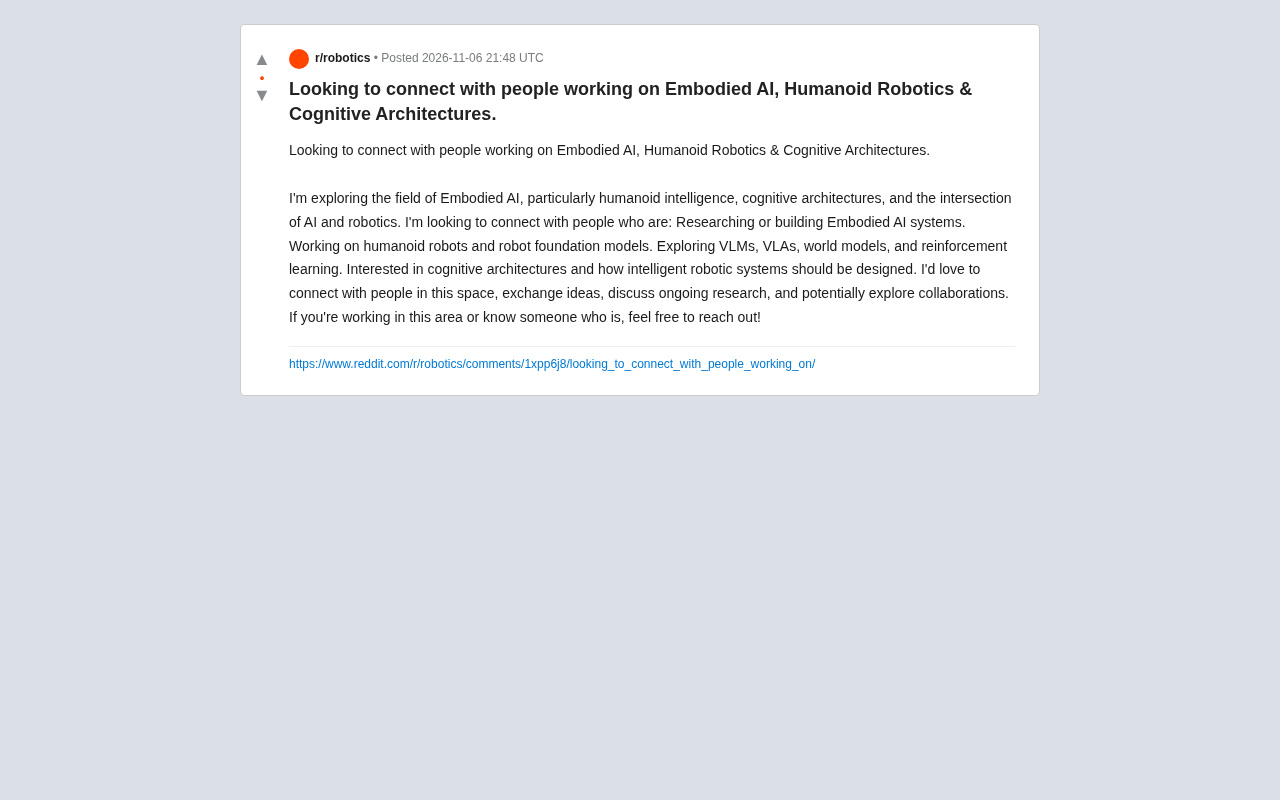
A Reddit connection post reflects the embodied AI community's interest in cross-layer collaboration among systems, humanoid robots, and cognitive architectures.
Using a Reddit post as a starting point, this article analyzes the embodied AI community's landscape of concerns. The poster seeks to connect with peers in embodied AI systems, humanoid robot foundation models, VLM/VLA, world models, reinforcement learning, and cognitive architectures, reflecting cross-layer interests. The article notes that embodied AI requires tight coupling among algorithms, hardware, and cognitive theory, which a single discipline can hardly cover. VLM, VLA, and world models form the current technology stack, while cognitive architectures offer a framework-level perspective for integrating perception, planning, and learning—though no consensus approach exists yet. Community connections can reduce repeated trial-and-error costs in hardware and data collection, but the post is merely a personal request lacking project details and should be viewed as a snapshot of community activity. The article suggests practitioners focus on the full perception-cognition-action pipeline and supplement cognitive architecture knowledge to build a differentiating advantage.
Embodied AI is moving from the lab into the real world, and the intersection of humanoid robots, cognitive architectures, and multimodal models has become one of the most active focal points of discussion in this field. Recently, a researcher posted on Reddit seeking to connect with peers working on embodied AI systems, humanoid robot foundation models, VLM/VLA, world models, reinforcement learning, and cognitive architectures. Though brief, the post reflects the current landscape of concerns within the embodied AI community.
Why Embodied AI Needs Cross-Disciplinary Connection
According to the post, the author is simultaneously interested in three levels: embodied AI system construction, humanoid robots, and cognitive architecture design. This cross-layer interest is no accident. The core challenge of embodied AI is that agents must perceive, decide, and act in the physical world, which requires tight coupling among algorithms, hardware, and cognitive theory. A single disciplinary background can hardly cover all these aspects, making community connection and collaboration an essential need.
The technical keywords listed in the post—VLM (Vision-Language Model), VLA (Vision-Language-Action Model), world models, and reinforcement learning—precisely outline the current embodied AI technology stack. VLMs give robots the ability to understand multimodal instructions, VLAs map visual perception directly to actions, and world models enable agents to predict the consequences of their actions. How these components integrate into a unified cognitive architecture remains an open question.
VLA (Vision-Language-Action Model) is a model paradigm that has emerged over the past two years, with representative works including RT-2 and OpenVLA. Unlike VLMs that output only text, VLA jointly encodes visual observations and natural language instructions and then directly decodes them into robot-executable action sequences (such as end-effector pose increments or joint commands). Training data typically comes from joint pre-training on large-scale robot teleoperation demonstrations and internet vision-language data, giving the model a certain degree of instruction generalization and object generalization capability. Key challenges include action space alignment, real-time inference latency, and cross-embodiment transfer. World models, on the other hand, are internal simulators of environmental dynamics that can predict future observations or rewards based on the current state. They are commonly used in model-based reinforcement learning and planning, with representative directions including the Dreamer series and prediction models based on video generation.
Cognitive Architectures: A Classic Topic Revisited
The poster specifically mentions "cognitive architectures and how intelligent robotic systems should be designed." This question brings classic cognitive architectures (such as ACT-R and SOAR) back into robotics discussions. Traditional cognitive architectures excel at modeling symbolic reasoning and memory mechanisms, but often fall short when dealing with continuous perception and real-time control. The rise of embodied AI is prompting researchers to think about how to combine the perceptual capabilities of neural networks with the modular reasoning of cognitive architectures.
There is no consensus approach in this direction yet. The post itself does not offer a specific technical roadmap but instead aims to "exchange ideas and discuss ongoing research," indicating that the field is still in a broad exploratory stage. For researchers working on humanoid robots or robot foundation models, cognitive architectures provide a framework-level perspective for integrating perception, planning, and learning, and are worth incorporating into design considerations.
ACT-R (Adaptive Control of Thought—Rational) and SOAR are two of the most representative cognitive architectures in cognitive science. ACT-R, proposed by John Anderson's team, decomposes cognition into modular buffers and production rules, and excels at modeling human memory retrieval, attention allocation, and decision timing, with parameters often fitted to behavioral experimental data. SOAR, stemming from the general problem-solving tradition of Newell and Simon, centers on problem-space search and chunking learning, emphasizing goal stacks and subgoal decomposition. Both are symbolic paradigms with strong interpretability and explicit reasoning processes, but they rely on manually encoded knowledge representations and struggle to directly handle high-dimensional continuous perceptual input. In the context of embodied AI, they are often used as upper-layer skeletons for task decomposition and memory management, while low-level perception and control are handled by neural networks, forming hybrid architectures.
The Value and Boundaries of Community Connection
The poster explicitly states the desire to "explore potential collaborations." In fields like embodied AI that are heavily hardware-dependent and have long experimental cycles, cross-team collaboration can significantly reduce the cost of repeated trial and error. The mechanical platforms, simulation environments, and real-world data collection for humanoid robots all require substantial investment, and open connections help share resources and benchmarks.
However, it should be noted that the post is merely a personal connection request and does not disclose specific projects, institutions, or results. For researchers who wish to follow up, it is more appropriate to view it as a snapshot of community activity rather than an authoritative roadmap. Progress in embodied AI should still be judged by formal papers and open-source projects.
Implications for Practitioners
From this post, one can observe that the embodied AI community's interest in the full perception-cognition-action pipeline is growing, rather than pursuing isolated single-model metrics. For AI engineers and robotics researchers, while paying attention to VLA and world models, supplementing knowledge of cognitive architectures and system design may become a differentiating advantage. Cross-background connections and discussions are precisely one of the most needed driving forces in this field today.
One-line Summary
A Reddit connection post reflects the embodied AI community's interest in cross-layer collaboration among systems, humanoid robots, and cognitive architectures.
Paragraph Summary
Using a Reddit post as a starting point, this article analyzes the landscape of concerns within the embodied AI community. The poster seeks to connect with peers working on embodied AI systems, humanoid robot foundation models, VLM/VLA, world models, reinforcement learning, and cognitive architectures, reflecting cross-layer interests. The article notes that embodied AI requires tight coupling among algorithms, hardware, and cognitive theory, which a single discipline can hardly cover. VLM, VLA, and world models constitute the current technology stack, while cognitive architectures offer a framework-level perspective for integrating perception, planning, and learning—though no consensus approach exists yet. Community connections can reduce the cost of repeated trial and error in hardware and data collection, but the post is merely a personal request lacking project details and should be viewed as a snapshot of community activity. The article suggests that practitioners focus on the full perception-cognition-action pipeline and supplement their knowledge of cognitive architectures to build a differentiating advantage.
Related articles
 Tech Frontiers
MuJoCo: An Analysis of DeepMind's Open-Source General-Purpose Physics Simulator
An in-depth analysis of Google DeepMind's open-source physics simulator MuJoCo: high-performance C++ kernel, MJCF modeling format, contact solving principles, MJX GPU acceleration, and robot reinforcement learning use cases.
 Tech Frontiers
Claude API Quick Start: The Official Quickstarts Project Collection
Anthropic's official claude-quickstarts project collection helps developers quickly build deployable apps with the Claude API. Nearly 20k stars, Python-based, great for beginners and prototyping.
 Tech Frontiers
AI Agents Connecting Directly to APIs: Which Calls Can Be Safely Allowed?
AI agents can call any API, but the real challenge is deciding which calls can be safely allowed. This article analyzes allowance decisions from three dimensions—intent matching, least privilege, and controllable impact—and argues that the control layer should sit outside the agent, combined with audit traceability to build a trustworthy API call governance mechanism.