Fine-Tuning Qwen3 Small Models End-to-End: From Theory to Production

An 8-module hands-on tutorial for fine-tuning Qwen3-0.8B from theory to production deployment.
This article outlines a hands-on tutorial series using Qwen3-0.8B as the vehicle for learning LLM fine-tuning end-to-end. The curriculum is broken into eight progressive modules spanning foundational theory (LLM principles, loss functions, Transformer architecture), fine-tuning methodology (full fine-tuning vs. LoRA), data preparation, and full engineering deployment. Small models are chosen to lower the compute barrier, while the core methodology transfers directly to larger models. The article also emphasizes that data quality sets the true ceiling on fine-tuning results, and that completing the full train-evaluate-deploy pipeline is what separates API users from engineers who can ship models to production.
Fine-Tuning Qwen3 Small Models End-to-End: From Theory to Production
LLM fine-tuning is rapidly becoming one of the highest-ROI skills in the developer job market. Browse any job board and the trend is hard to miss: roles that include "LLM fine-tuning" in the job description often command salaries two to three times higher than comparable positions without it. According to the Bilibili tutorial series this article is based on, a standard backend developer role typically pays around ¥15K–25K per month, while positions requiring LLM fine-tuning experience can reach ¥30K–60K. This reflects a genuine surge in enterprise demand for engineers who can actually get models running, tuned, and deployed in production.
This article draws from a hands-on tutorial series focused on fine-tuning Qwen3-0.8B — a small but capable model — to map out the knowledge framework and learning path it covers. The goal is to help engineers who are just starting out, or transitioning from traditional development, build a complete mental model of the space.
Why Start with a Small Model
Many people hear "LLM fine-tuning" and immediately worry about compute costs. In practice, small models like Qwen3-0.8B are ideal for learning fine-tuning precisely because their parameter count is manageable. A single consumer-grade GPU is sufficient to run training end-to-end, which means learners can work through every step of the real training pipeline without getting blocked by hardware.
From a career development perspective, mastering the complete fine-tuning pipeline on a small model is every bit as valuable as jumping straight to a massive one. The core methodology — data preparation, understanding the loss function, monitoring training, evaluating results — transfers across model scales. Getting the fundamentals right on a small model first, then applying them to larger ones, is the more robust growth path.
Eight Progressive Learning Modules
The tutorial series breaks LLM fine-tuning into eight progressive modules, forming a closed loop from theory to hands-on practice.
Theoretical Foundations
The first four modules focus on underlying principles. "What is a Large Language Model" establishes an overall mental model; "How Large Models Are Trained" clarifies the distinction between pre-training and post-training; "What is a Loss Function" dives into the mathematical core of model optimization — the loss function is the key metric for measuring the gap between model predictions and ground truth, and understanding it is essential for interpreting convergence curves during training. "Deep Dive into Transformer Architecture" then confronts the foundational architecture behind every major LLM in production today.
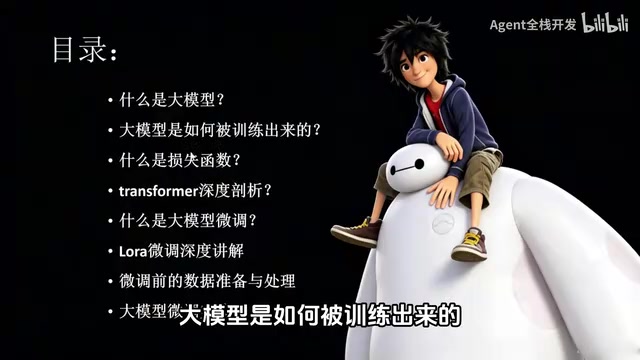
The design of this layer reflects the tutorial's philosophy of rejecting surface-level coverage — the goal isn't to memorize definitions, but to understand what each component actually does during training.
The Transformer architecture was introduced by Google in 2017 in the paper Attention Is All You Need and serves as the backbone of virtually every major large language model today — GPT, Qwen, LLaMA, and others. Its core mechanism is self-attention: when processing each token, the model dynamically computes relevance weights between that token and every other token in the sequence, capturing long-range dependencies. Compared to earlier RNN/LSTM approaches, Transformers are highly parallelizable, dramatically improving training efficiency. Understanding the three core components — the encoder-decoder structure, multi-head attention (Multi-Head Attention), and positional encoding (Positional Encoding) — is a prerequisite for understanding how parameter updates work during fine-tuning. The attention weight matrices in particular are precisely what parameter-efficient fine-tuning methods like LoRA operate on.
Fine-Tuning Methods
The middle modules shift focus to fine-tuning itself. "What is LLM Fine-Tuning" provides a high-level overview of different strategies — full fine-tuning, LoRA, and others — and when to use each. The follow-up module, "Deep Dive into Fine-Tuning Principles," unpacks the mechanics of parameter updates in more detail. At its core, fine-tuning takes a pre-trained model and continues training it on domain-specific data to adapt it to a particular task.
Understanding the tradeoffs between fine-tuning strategies is critical: full fine-tuning delivers the best results but is expensive; parameter-efficient methods like LoRA achieve strong performance with limited resources, which is why they dominate in small-model fine-tuning scenarios.
LoRA (Low-Rank Adaptation) is currently the dominant parameter-efficient fine-tuning method, introduced by Microsoft Research in 2021. The core idea: instead of updating the full pre-trained weight matrices, two low-rank matrices A and B are introduced alongside them (rank r typically set between 4 and 64). Only these small matrices are updated during training while the original weights remain frozen. Because the low-rank matrices contain far fewer parameters (roughly 0.1%–1% of the full model), VRAM usage and training time drop dramatically while performance remains close to full fine-tuning. On a small model like Qwen3-0.8B, LoRA makes fine-tuning feasible on a single consumer GPU with 8GB of VRAM — which is the fundamental reason it's so widely recommended for getting started. Common variants include QLoRA, which combines 4-bit quantization to further reduce memory footprint.
Data Preparation and Engineering Deployment
The ceiling on fine-tuning quality is usually set by data quality, not the model itself. The tutorial's "Data Preparation and Processing for Fine-Tuning" module drives this point home: from data cleaning and format alignment to sample construction, every step directly affects final model performance. Poor data will produce poor models regardless of how solid the training pipeline is.
The final module, "LLM Fine-Tuning in Practice," ties everything together — covering environment setup, data processing, model training, evaluation, and real-world project deployment in a complete walkthrough. This kind of end-to-end engineering exercise is exactly what separates engineers who can "call an API" from those who can actually ship a model into production. For developers transitioning from traditional backgrounds, this is the module that converts theory into deliverables.
Fine-tuning data typically needs to be structured in an instruction-following (Instruction Tuning) format, where each sample consists of three parts: a system prompt (System Prompt), user input (User), and expected output (Assistant), forming a conversational pair. The two most common format standards are the Alpaca format and the ShareGPT format, both of which are natively supported by major training frameworks such as LLaMA-Factory and Axolotl. In terms of data volume, domain adaptation tasks typically need hundreds to a few thousand high-quality samples — more is not always better. Mixing in large amounts of low-quality data actively degrades model performance, which is why data cleaning cannot be skipped. Common pitfalls in practice include inconsistent answer formatting, excessive duplicate samples, and misaligned annotation standards. These issues tend to be amplified on small models, so they deserve particular attention during debugging.
Who This Is For
This curriculum is fairly clearly positioned: whether you're a CS student, a backend developer, or a full-stack engineer looking to break into the LLM space, there's a meaningful entry point here. The series starts from environment setup, keeping the barrier to entry reasonable, while still covering production deployment with enough depth to matter.
One important caveat: genuinely mastering fine-tuning requires hands-on practice. Understanding the theory is only the first step. You need to iterate on real data and real models — watching loss curves, adjusting hyperparameters — to develop the kind of transferable engineering intuition that actually sticks. Small models provide exactly that: a low-cost space to experiment and fail fast.
Taken as a whole, this is a "theory → methods → data → practice" four-part learning path with strong reference value for developers who want to systematically build out their LLM fine-tuning capabilities.
Related articles

Understanding DeepSeek in 3 Minutes: The Rise from a Quant Hedge Fund to an Open-Source AI Leader
DeepSeek's history in 3 minutes: from High-Flyer Quant's compute build-up to V2's MLA inference cost cuts, V3's $5.576M training bill, R1's open-source global shock, and V4 with a $7B Series A.

Local Creative Writing Model Showdown: Fine-tuned Qwen3.8 27B Wins, DeepSeek v4.1 Underwhelms
Bilibili creator tests seven local creative writing models: Hemingway and HumanLike Chat based on Qwen3.8 27B perform best, DeepSeek v4.1 is plain, Dongfang Shuo ranks last with confused characters. Includes three test prompts, scores, and usage advice.

Liang Wenfeng's Three Big Bets: Why Did DeepSeek Open-Source Its 82% Gross Margin?
Why did DeepSeek open-source DeepInfer, its 82% gross margin inference framework, and then launch a hundred-billion funding round? An analysis of Liang Wenfeng's three big bets and the open-source strategy.