Five AI Models Face Off: Breaking Down GPT, Gemini, Claude, Grok, and DeepSeek

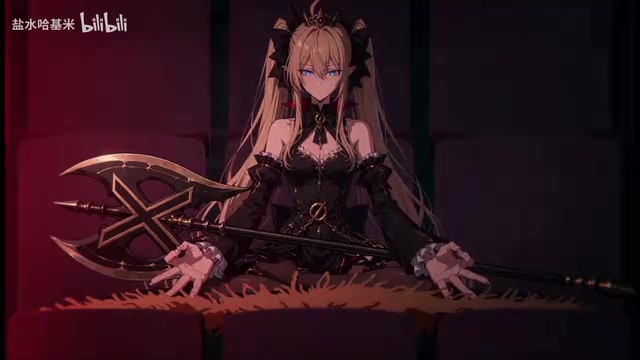
A viral Bilibili teaser frames GPT, Claude, Gemini, Grok, and DeepSeek as rivals in a dramatic AI model showdown.
A Bilibili teaser called "Model Migration" uses a gamified "slaughter match" narrative to pit the five leading AI models against each other: GPT as the all-around "awakened dragon" that reclaims the top spot with one update; Claude as the high-output workhorse trusted by developers; Gemini as Google's multimodal speed champion; Grok as the Multi-Agent task executor; and DeepSeek as the open-source, locally deployable value pick from China. Beyond the entertainment packaging, the video accurately reflects a real industry truth — technical leads are temporary, a single version update can reshuffle everything, and knowing each model's core strengths is what helps users choose the right tool.
An AI Arms Race Already Underway
The pace of AI model iteration is staggering — new versions are replacing old ones far faster than most observers expected. A teaser video for the "Model Migration" series on Bilibili takes a personified, dramatic approach to pit today's five leading AI models — GPT, Gemini, Claude, Grok, and DeepSeekAd — against each other on the same stage, using the metaphor of a "slaughter match" to capture the intense rivalry between them.
Each model has its own areas of strength, and each is waiting for the next version update to deliver its next capability leap. This "neck-and-neck" dynamic is the most accurate portrait of the current large model industry: no one stays on top for long, and a single major update can reshuffle the entire deck.
Capability Profiles of the Five Models
The teaser assigns each model a symbolic "score" and capability positioning. While the numbers lean toward entertainment, the underlying capability descriptions align closely with how each model is actually perceived in the real world.
Grok: The Complex Task Decomposer
Grok is described as specializing in "breaking down complex goals and handing them off to multiple autonomous agents for continuous execution." This points to Multi-Agent architecture and long-chain task execution — splitting a large objective into executable subtasks and having multiple agents collaborate to complete them. In the current wave of agent-based AI, this capability is becoming a key benchmark for measuring a model's practical value.
What is Multi-Agent architecture? Multi-Agent architecture refers to distributing a complex task across multiple cooperating AI agents, each responsible for a specific subtask, with the ability to pass information and invoke one another. The advantages of this paradigm lie in parallel processing and separation of responsibilities — it can overcome the limitations of a single model's context window and single-pass reasoning depth. Take planning a trip as an example: one agent searches for flights, another books the hotel, a third consolidates the itinerary, and a coordinating agent compiles the final output — all without human intervention. Frameworks like AutoGPT, LangGraph, and CrewAI have already productized Multi-Agent orchestration, and foundation models with native agent capabilities tend to perform more reliably within this architecture.
Claude: Data Breadth and High Output Capacity
Claude is positioned as one that "treats the data trails left by countless users as its own domain," with a score of 53 and the title of "highest output capacity among all models." This aligns with Claude's reputation for long-form text processing, code generation, and consistent output — many developers consider it a powerhouse workhorse.
Gemini: Multimodal and Fastest Output Speed

Gemini scores 41, hails from the Google ecosystem, and is labeled a "multimodal competitor" with strong creative capabilities and "the fastest output speed currently available." Multimodality has always been a central emphasis for Google, and while output speed is often underestimated in product discussions, it directly shapes the user experience in practice.
What does Multimodal mean? Multimodal refers to a model's ability to understand and generate multiple types of information simultaneously — including text, images, audio, and video — rather than handling only plain text. Google's Gemini was designed from the ground up with native multimodality as a core goal, taking a different path from GPT-4, which started text-first with vision capabilities added later. In practice, multimodal capability means users can upload images and ask questions directly, have the model analyze chart data, or convert video content into text summaries. Output speed (i.e., token generation rate) affects how long users wait for a response; in low-latency scenarios like real-time conversation or code completion, a speed advantage translates directly into product competitiveness.
DeepSeek: The Open-Source, Locally Deployable Value Champion

DeepSeek scores 40, with keywords of "open-source" and "local deployment," and is known for "performance capable of crushing models in its class." As a rising domestic Chinese force in recent years, DeepSeek broke through with an open-source strategy and exceptional cost-efficiency, enabling more developers to deploy high-performance models in local environments — a core advantage that sets it apart from closed-source competitors.
What do "open-source" and "local deployment" mean in the LLM context? An open-source model is one where the developer publicly releases the model weights (i.e., the parameter files), allowing anyone to download and run them on their own hardware for free — no paid API calls required. Local deployment means the model runs on hardware the user controls, with data never passing through third-party servers. This matters greatly for enterprise scenarios with strict privacy or compliance requirements. DeepSeek's MoE (Mixture of Experts) architecture activates only a subset of parameters during inference, significantly reducing hardware requirements and enabling larger-scale models to run on ordinary consumer-grade GPUs — the technical foundation behind its "high value-for-money" reputation.
The Industry Metaphor Behind the "Slaughter Match"
The teaser dubs this competition a "model slaughter match" and depicts each player "holding its breath, waiting for the next version to arrive." This metaphor captures the brutal nature of large model competition: technical leadership is always temporary. Once a competitor ships a major update, existing advantages can evaporate overnight.

This "arms race" dynamic isn't necessarily bad news for users. Each player constantly pours resources into R&D to stay competitive, and the entire ecosystem ultimately benefits — stronger capabilities, faster speeds, and lower barriers to entry.
GPT's "Dragon Awakening"
The teaser's climax centers on GPT. It's described as having "fallen behind" at one point, only to stage a dramatic comeback — the "dragon awakens" — returning to the top on the strength of a single update, crowned "the contemporary pinnacle spanning every domain," also scoring 53.
This narrative reflects OpenAI's unique position in the industry: even when temporarily surpassed by competitors, it can reclaim the lead through deep technical reserves and one pivotal version release. This is precisely what makes large model competition so fascinating — among the top players, the gap often comes down to just one version number.
Conclusion: Real Competition Beneath a Personified Story
The "Model Migration" teaser transforms dry technical specs into a tension-filled showdown through personification and gamification, giving everyday viewers an intuitive sense of what each of the five models stands for. While the scores and "combat power" settings are clearly for entertainment, the core message is genuine:
The competition among AI large models has entered a white-hot phase. There are no permanent kings — only continuous iteration. For users, the key is understanding what each model does best: GPT's all-around capability, Claude's high output, Gemini's multimodality and speed, Grok's Multi-Agent execution, and DeepSeek's open-source value. Only then can you choose the right tool for the right scenario.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.