Fixing the Twin, Not the Detector: Sim-to-Real Roadside LiDAR Detection
UrbanTwin challenge winning solution reveals: Sim-to-Real performance gains mainly come from correcting systematic discrepancies between the digital twin and the real site, not from improving the detector.
This article introduces the winning solution from the IEEE BigData 2026 Cup UrbanTwin Sim2Real LiDAR Challenge. The team won first place in the LUMPI track with 0.5541 and placed fifth in V2X-Real. All detectors used CenterPoint, trained entirely on synthetic data on a single 8 GB laptop GPU. The core finding: most gains came from correcting systematic discrepancies between the digital twin and the real site (coordinate systems, point density, annotation conventions), not from the detector architecture. Learning-free resampling aligned twin point cloud density with the real distribution, raising LUMPI realism from 0.589 to 0.947, and label-free post-processing exploited physical priors of fixed roadside sensors. The study also found that corrections targeting systematic biases transfer to the test set, while choices fitted on small validation sets do not.
In autonomous driving and intelligent transportation, training roadside LiDAR detectors has long been hampered by the high cost of real annotated data. Digital twin technology has been touted as a promising solution, attempting to replace real labels with a virtual world. However, a detector trained in a twin environment, once deployed at a real intersection, faces different sensors, different object distributions, and different annotation conventions. How exactly should this Sim-to-Real gap be bridged?
In the UrbanTwin Sim2Real LiDAR Challenge held at IEEE BigData 2026 Cup, one team offered their answer: fix the twin, not the detector. They won first place in the LUMPI track with an overall score of 0.5541 and placed fifth in the V2X-Real track with 0.8102. All detectors used the CenterPoint model, were trained entirely on synthetic data, and ran on a single 8 GB laptop GPU. This result reveals the key to putting Sim-to-Real into practice.
Core Finding: Gains Come from Twin Alignment, Not the Model Itself
According to the team's paper, most of the performance improvement did not come from improvements to the detector architecture, but from correcting the discrepancies between the digital twin and the real site. They systematically aligned the twin environment's coordinate system, point density, and bounding box conventions to match the test sensor; they also generated pedestrian and cyclist targets missing from the twin data, and added street clutter to training as unlabeled negative samples. In addition, they reconstructed objects in the twin at real dimensions and real point density.
This approach stands in sharp contrast to the traditional "tune the model" path. When there are systematic biases between simulated and real data, simply increasing model complexity or training epochs often yields limited results. The team's work shows that alignment at the data level is the primary lever for Sim-to-Real performance improvement.
Digital twin is a high-fidelity mirror of a physical entity (such as a real intersection) in virtual space, typically built through 3D modeling, sensor simulation, and physical rendering. In autonomous driving, digital twins are used to generate large amounts of annotated training data to replace expensive manual annotation. However, systematic biases often exist between the twin environment and the real world, including inconsistencies in sensor parameters (such as LiDAR beam distribution, mounting height, and angle), scene content (such as the frequency of pedestrians and cyclists), and annotation conventions (such as bounding box size definitions and orientation conventions). These biases constitute the main source of the Sim-to-Real gap. The team's work systematically identifies and corrects these biases so that the twin data approximates real data in statistical characteristics, thereby improving the generalization ability of downstream detectors.
Learning-Free Resampling: Making Twin Point Clouds Approximate the Real Distribution
On the key dimension of point cloud density, the team adopted a learning-free resampling method to adjust twin point clouds to the per-cell point density of unlabeled real frames. This operation raised the LUMPI dataset's realism metric from 0.589 to 0.947, while the metric between real frames was 0.949. This means that after resampling, the twin data was nearly indistinguishable from real data in terms of point density distribution.
This learning-free approach is noteworthy. It does not rely on any trainable parameters, but directly uses the statistical characteristics of unlabeled real frames for distribution matching. For resource-constrained scenarios—such as a laptop with only an 8 GB GPU—this lightweight solution has significant practical value.
Point cloud density refers to the number of LiDAR return points per unit space, affected by factors such as the number of sensor beams, scanning pattern, object distance, and reflectivity. In Sim-to-Real scenarios, if the density distribution of twin point clouds is inconsistent with that of real sensors, the detector will learn incorrect geometric features. Learning-free resampling statistically measures the per-cell point density of unlabeled real frames and downsamples or upsamples the twin point clouds to match the real data distribution, without introducing any trainable parameters. This method has low computational overhead and does not depend on real labels, making it particularly suitable for resource-constrained deployment environments.
Label-Free Post-Processing: Exploiting the Physical Priors of Fixed Roadside Sensors
The LiDAR sensors at real intersections are fixed in position, and this physical constraint brings two priors that can be exploited: static structures repeat in every frame, and real objects have characteristic point statistics. Based on this, the team designed a label-free post-processing strategy to further mine information from unlabeled real data.
This post-processing does not rely on any real labels, but instead uses the determinism of sensor deployment to filter and correct detection results. For roadside perception scenarios, this is an underestimated free signal.
Label-free post-processing refers to correcting detection results during the model inference stage without relying on any real annotations, using only the statistical regularities or physical constraints of the data itself. In fixed roadside sensor scenarios, static backgrounds (such as roads, guardrails, and buildings) are highly repetitive across consecutive frames, and false detections can be filtered through inter-frame consistency; meanwhile, the point clouds of real objects (such as vehicles and pedestrians) have characteristic distributions in height, density, and reflection intensity, which can be used to remove low-confidence false detections. This post-processing strategy requires no additional training and can generalize to different sites, making it an effective supplement when deploying models trained on simulated data to real scenarios.
The Difference Between Validation Set Gains and Test Set Gains: Which Corrections Actually Transfer?
One of the most valuable analyses in this study is the side-by-side reporting of each component's gains on the validation and test sets. They found that corrections targeting systematic Sim-to-Real discrepancies transfer to the test set, typically retaining one-quarter to three-quarters of the validation gain; whereas choices fitted on a small number of validation set objects do not transfer.
This finding has methodological significance for Sim-to-Real research. It suggests that researchers should prioritize components that correct systematic biases, rather than heuristic rules tuned on small-scale validation sets. The former has cross-dataset generalization ability, while the latter is prone to overfitting.
Implications for Sim-to-Real Practice
This work sends a clear signal: in the development of perception systems driven by digital twins, fidelity alignment of the twin environment is more critical than the choice of detector architecture. Once the gap between simulation and reality is systematically narrowed, even a standard CenterPoint model can achieve competitive results on a consumer-grade GPU.
For industry, this means that the focus of Sim-to-Real investment should shift upstream to the construction of data pipelines—coordinate system alignment, point density matching, annotation convention unification, and completion of missing categories. Although these tasks are less eye-catching than model innovations, they may be the key to determining whether simulated data can truly replace real labels.
One-line Summary
UrbanTwin challenge winning solution reveals: Sim-to-Real performance gains mainly come from correcting systematic discrepancies between the digital twin and the real site, not from improving the detector.
Paragraph Summary
This article introduces the winning solution from the IEEE BigData 2026 Cup UrbanTwin Sim2Real LiDAR Challenge. The team won first place in the LUMPI track with a score of 0.5541 and placed fifth in the V2X-Real track. All detectors used the CenterPoint model, were trained entirely on synthetic data, and ran on a single 8 GB laptop GPU. The core finding is that most performance gains came from correcting systematic discrepancies between the digital twin and the real site (such as coordinate systems, point density, and annotation conventions), rather than from the detector architecture itself. The team used learning-free resampling to align twin point cloud density with the real distribution, raising the LUMPI realism metric from 0.589 to 0.947, and exploited the physical priors of fixed roadside sensors for label-free post-processing. The study also found that gains from correcting systematic biases transfer to the test set, while choices fitted on small-scale validation sets do not.
Related articles
AgentScope Java Quick Start: A Java Developer's Guide to Building AI Agents
AgentScope Java is Alibaba's open-source enterprise Agent framework. This guide covers environment setup, model integration, Agent creation, multi-agent collaboration, and production deployment tips for Java developers.
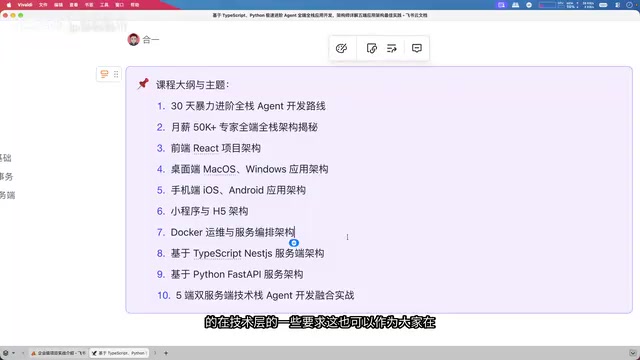
Full-Stack Agent in Practice: One Codebase Running Across Five Clients and Dual Server Architectures
Based on a Bilibili AI full-stack course, this analyzes how one Agent project runs on iOS, Android, mini programs, desktop, and H5, with NestJS and FastAPI dual servers, Docker orchestration, and tool-calling demos.
Google EGM Plugin in Practice: Spec-Driven Development with Claude Code
Google's EGM plugin uses elephant-goldfish agents and seven skills to productize spec-driven development with Claude Code. Here's how it works in practice.