From Silicon to Token Economics: Full-Stack Optimization of AI Inference Infrastructure

The AI industry shifts from training to inference, making full-stack token cost optimization the new competitive frontier.
This article uses Dylan Patel's appearance at Fireworks Forge as a jumping-off point for a deep dive into AI inference economics. As large models enter large-scale deployment, industry focus has shifted from one-time training costs to the ongoing operational costs of inference. A full-stack perspective — from chip to application — reveals that the true per-token cost is determined by four compounding layers: chip architecture, server systems, inference engines, and service scheduling. For companies building AI products, per-token cost directly impacts business model viability, making full-stack cost literacy an essential strategic competency.
A Conversation About AI Inference Costs
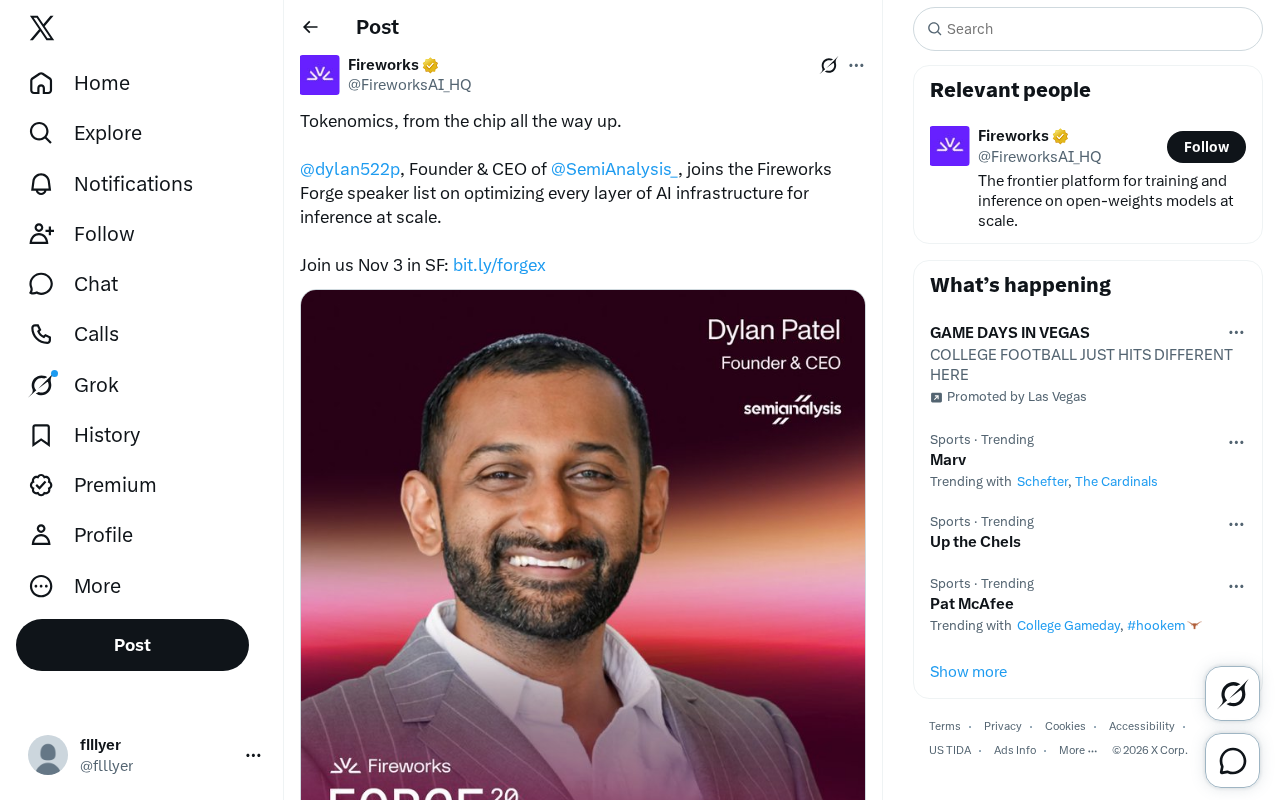
Dylan Patel (@dylan522p), founder and CEO of SemiAnalysis, is set to join the speaker lineup at Fireworks Forge — an event focused on a increasingly critical topic: how to optimize every layer of AI infrastructure, from the chip level all the way up to the application layer, in support of large-scale inference. The event will be held on November 3rd in San Francisco.
Behind this brief event announcement lies one of the most fundamental cost questions in today's AI industry: Tokenomics. As large models move from the training phase into large-scale deployment and inference, measuring the economic efficiency of AI services is no longer just about peak compute — it's about the real cost of generating each individual token.
What "From the Chip All the Way Up" Tokenomics Really Means
The tagline "Tokenomics, from the chip all the way up" neatly captures a full-stack perspective. The cost of AI inference isn't determined by any single factor — it's the cumulative result of decisions made at every layer, from hardware all the way up to software services:
- Chip layer: GPU/accelerator architecture, memory bandwidth, and interconnect capability directly determine power consumption and throughput per unit of compute.
- Systems layer: Network topology, cooling efficiency, and power delivery in server clusters affect overall utilization.
- Inference engine layer: Techniques like batching, KV cache management, and quantization determine how hard the hardware can be pushed.
- Service layer: Scheduling strategies, load balancing, and multi-tenant isolation determine the actual per-token cost delivered to end users.
SemiAnalysis, the firm Dylan Patel founded, has long specialized in deep industrial analysis of semiconductors and AI hardware — starting from the chip layer and working upward to deconstruct the cost structure of the entire AI infrastructure stack. This perspective is especially valuable for understanding the bottlenecks in today's inference economics.
KV cache is a particularly critical mechanism at the inference engine layer and deserves its own explanation. When a large language model generates each new token, it must repeatedly access the attention key-value pairs for all previous tokens. The KV cache stores these intermediate computation results in GPU memory, avoiding redundant computation and dramatically improving throughput. However, KV cache memory usage grows linearly with context length — in long conversation or long-document scenarios, it can quickly exhaust GPU memory, making it one of the key bottlenecks in inference costs. Techniques like PagedAttention were specifically developed to manage KV cache memory allocation more efficiently, and represent one of the core optimization directions in modern inference engines like vLLM.
Why Inference Optimization Has Become the Industry's Focus
The industry's attention is shifting from training to inference. Training is a one-time, capital-intensive investment, while inference is a continuous, high-volume operating expenditure directly tied to revenue. When a model is called by millions of users on a frequent basis, even a fraction of a cent in per-token cost compounds into massive operational overhead.
This is also the implicit meaning behind Fireworks naming its event "Forge" — the real value lies in forging raw hardware compute into efficient, low-cost, scalable inference services. Optimizing every layer of the infrastructure stack means serving more requests from the same hardware investment, or reducing capital and energy expenditure while maintaining the same quality of service.
From a cost structure perspective, the economic logic of training and inference are fundamentally different. Training is a highly parallel batch processing task that can fully exploit GPU compute density (FLOP/s). Inference — especially online, real-time inference — typically involves small batches or even single requests with low-latency requirements. The bottleneck is usually not compute, but memory bandwidth: generating each token requires repeatedly reading hundreds of billions of parameters from GPU memory. This means the core metric for inference efficiency isn't peak TFLOPS, but rather Memory Bandwidth Utilization and effective batch size. This also explains why hardware designs optimized for inference (such as HBM optimizations focused on bandwidth) and software scheduling strategies have fundamentally different optimization targets compared to training workloads.
The Real-World Implications of Full-Stack Optimization
For companies building AI products, inference costs directly determine whether a business model is viable. A service that cannot control its per-token cost will struggle to achieve sustainable profitability in a competitive market. As a result, understanding the complete cost chain from chip to application has evolved from a niche topic for hardware engineers into a strategic concern that product decision-makers can no longer ignore.
Inviting an expert like Dylan Patel — who combines deep semiconductor industry insight with AI systems analysis — speaks directly to the industry's hunger for "full-stack cost awareness." Simply stacking more GPUs is no longer sufficient to build a competitive moat. The real advantage comes from meticulously optimizing efficiency at every layer.
Summary
This November 3rd event in San Francisco may be just a brief announcement, but it reflects a broader shift in the AI industry — from a compute race to an efficiency race. As inference becomes the core cost center for AI services, token economics viewed "from the chip all the way up" is fast becoming the key benchmark for measuring a company's technical and commercial maturity.
Note: This article is based on an event announcement. Specific technical details from the talk will be available after the event takes place.
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.