Google Gemini Omni 1.2 Flash Hands-On: The Six-Dimension Pelican-on-a-Bicycle Test Fails

Gemini Omni 1.2 Flash hands-on: stable lighting and camera work, but spatial reasoning and prompt following still fall short.
A Bilibili creator stress-tested Gemini Omni 1.2 Flash with a six-dimension pelican-on-a-bicycle prompt. The model performed well on lighting and camera movement, but showed clear weaknesses: a missing rearview mirror and mirror clipping, imprecise wing poses, scrambled mirror reflections, a misspelled Chinese character, an inaccurate clock, and composition that ignored the required walkway direction.
After Google's newly launched video generation model Gemini Omni 1.2 Flash went live on AI Studio, creators quickly put it to the test. A Bilibili creator stress-tested it with a self-designed "six-dimension pelican riding a bicycle" prompt, and the results exposed quite a few detail problems. Based on that test material, this article breaks down the model's performance and shortcomings.
Test Method: Designing a Six-Dimension Prompt
The creator designed a prompt with multiple constraints: a pelican riding a bicycle, with its left wing resting on the handlebars and the other wing folded, beak kept open; the scene includes a mirrored retaining wall, a walkway extending from upper right to lower left, a wall clock pointing to three o'clock, and the Chinese text "齐傲" (Qi Ao), among other elements. The test scored the model dimension by dimension across six areas: subject integrity, limb and mechanical reasoning, mirror reflection and spatial reasoning, Chinese text and clock, liquid and buoyancy motion, and camera movement/composition/lighting.
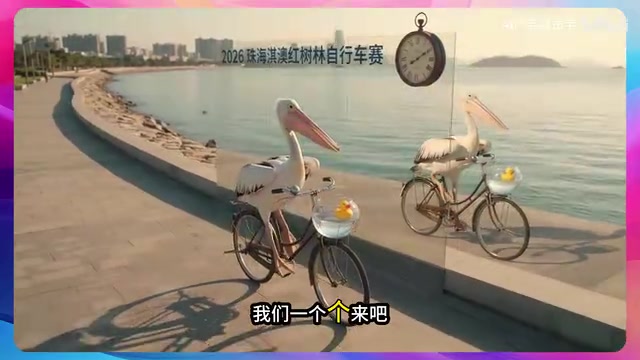
Prompt Engineering plays a key role in this kind of test. A video generation model's ability to follow prompts is often called "Instruction Following." When a prompt contains multiple parallel constraints (such as simultaneously specifying limb poses, object parts, spatial layout, and text content), the model needs to balance all conditions during generation, and constraint conflicts or omissions easily occur. The industry commonly uses "Compositional Prompts" to evaluate a model's ability to parse complex, multi-object, multi-relationship scenes. The six-dimension prompt in this test is exactly this kind of compositional stress test, designed to expose the model's priority allocation and detail retention under multiple constraints.
Dimension One: Subject Integrity and Cross-Layer Consistency
In the generated frame, the bicycle is missing the specified handlebar rearview mirror. More obviously, the mirrored retaining wall is not a single uninterrupted floor-to-ceiling mirror—there's a glaring flaw: besides the mirror wall, an extra "pelican in the mirror" appears in the frame, clearly a clipping/penetration error. This shows the model has an insufficient understanding of spatial structures like "continuous mirror surfaces," and tends to fill areas by generating similar objects.
Cross-layer Consistency refers to the coherence of object attributes and positional relationships across different spatial layers (such as foreground, background, and reflective surfaces) in a generated video. In mirror scenes, the model needs to understand the geometric mapping between the reflection layer and the physical layer, ensuring that reflected content changes synchronously with the physical object's movement. Current video generation models are mostly based on Diffusion Models or autoregressive Transformer architectures. Mirror reflection samples are relatively scarce in their training data, and the models tend to treat reflective areas as independent generation regions rather than physically strict mirror transformations, thus easily producing approximate behavior of "copying similar objects," leading to clipping errors and symmetry confusion.
Dimension Two: Limb and Mechanical Reasoning
The prompt required the pelican's left wing to rest on the handlebars and the other to be folded, but in the frame both wings are folded—the "resting on handlebars" action was not performed. Meanwhile, the pelican's beak later closes, failing to stay open as required. The model lacks precise control over limb-object interactions, and action instructions are simplified into static poses.
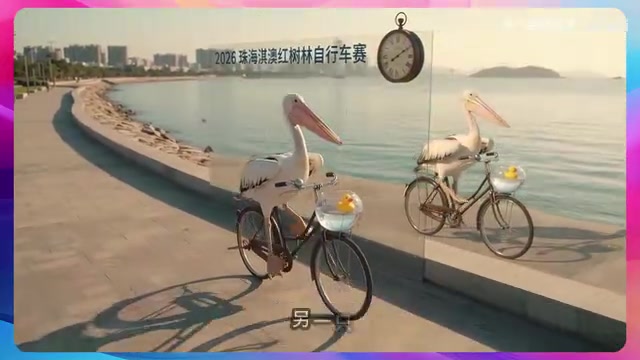
Dimension Three: Mirror Reflection and Spatial Reasoning
The bicycle chain, cloth cover, and bell in the mirror do not correctly flip left-right relative to the physical objects, and the symmetry relationship is disordered. Rather than generating a symmetric mirror image, the model seems to copy a similar pelican into the scene. This shows its mirror reflection is not based on physical spatial reasoning but on approximate generation based on image patterns, causing the reflected content to be disconnected from the physical objects.
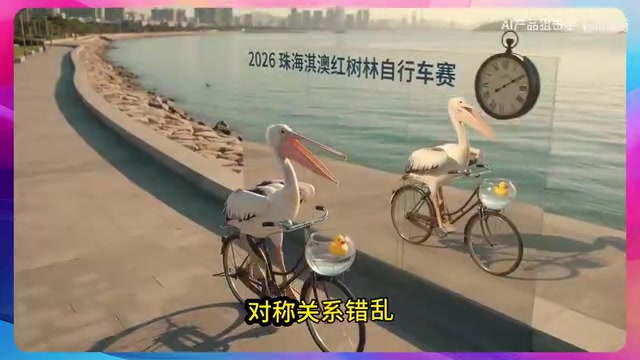
Spatial Reasoning is a core challenge for video generation models. Humans can easily infer an object's position, orientation, and mutual occlusion relationships in 3D space, and use that to predict left-right mirror flips. However, most video generation models lack explicit 3D scene representations and instead generate based on statistical patterns in 2D image sequences. When a prompt requires precise mirror reflection, the model often relies on "mirror patterns" in training data for pattern matching rather than performing true geometric transformations. This explains why reflected content becomes disconnected from physical objects—the model does not establish an "object-mirror-observer" spatial coordinate system, but generates the reflective region as an independent picture element.
Dimension Four: Chinese Text and Clock
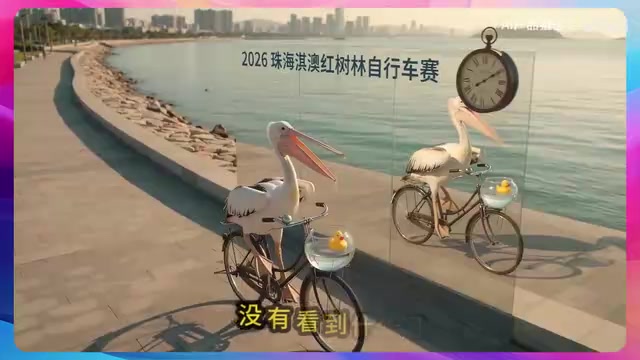
For the Chinese text "齐傲" in the prompt, the model wrote the character "傲" incorrectly; the wall clock's time is also not exactly three o'clock, deviating noticeably from the actual position. Chinese text generation and precise time indication remain weak points for video models—text easily deforms, and clock hands are hard to align precisely.
Chinese text generation faces unique difficulties in video models. Unlike English, Chinese characters have complex structures and fine strokes, and Chinese-text video samples are relatively scarce in model training data. Video generation models typically treat text rendering as a pixel-level generation task, lacking explicit modeling of glyph structures, so missing strokes, structural misalignment, or confusion with similar-looking characters easily occur. Precise clock indication involves fine spatial alignment of hand angles with dial markings, requiring the model to have fine-grained geometric control. When generating clocks, current models often can only produce "clock-like" patterns and struggle to precisely control hands pointing to a specific time, reflecting a general shortcoming of models in fine numerical and geometric constraints.
Dimension Five: Liquid and Buoyancy Motion
No problems were seen in this dimension, indicating the model performs relatively stably on continuous physical motion like fluids and buoyancy—at least no obvious errors appeared in this test scenario.
Dimension Six: Camera Movement, Composition, and Lighting
Composition has serious problems: the prompt required the walkway to extend from upper right to lower left, with the mirror wall on the upper side of the walkway, but the generated frame clearly does not meet this requirement. Camera movement and lighting, however, showed no issues—there's an opening 45-degree high-angle shot, then horizontal tracking, and lighting performs normally.
Summary: Strengths and Weaknesses Coexist
Gemini Omni 1.2 Flash performs stably on lighting and basic camera movement, but still has obvious shortcomings in precise spatial relationships, mirror reflection, limb instruction following, Chinese text, and fine composition. For creative scenarios that require strict adherence to complex prompts, it should still be used with caution; for atmosphere-focused video generation without precise constraints, its strengths may come into play.
The creator invited viewers to score it at the end of the video. Based on the actual test, this model still has some way to go before it can be called "really impressive."
One-line Summary
Gemini Omni 1.2 Flash hands-on: stable lighting and camera movement, but spatial reasoning, mirror reflection, and instruction following still have obvious shortcomings.
Paragraph Summary
A Bilibili creator stress-tested Gemini Omni 1.2 Flash with a self-designed "six-dimension pelican riding a bicycle" prompt, evaluating it across six dimensions: subject integrity, limb reasoning, mirror reflection, Chinese text and clock, liquid and buoyancy, and camera movement/composition. Results show the model performs stably on camera movement and lighting, with no obvious problems in the liquid and buoyancy dimension; however, subject integrity issues include a missing handlebar rearview mirror and mirror clipping errors, limb instruction following is imprecise (wings not on handlebars, beak not kept open), mirror reflection symmetry is disordered, the Chinese character "傲" is written incorrectly, the clock points inaccurately, and composition fails to follow the walkway direction requirement. Overall, the model still has obvious shortcomings in precise spatial relationships and complex prompt adherence, making it suitable for atmosphere-focused rather than strictly constrained creative scenarios.
Related articles
 Tech Frontiers
Coldframe: A Honeypot Disguised as a Supermarket Freezer Controller
Coldframe is a honeypot disguised as Danfoss AK-SM 800A and Dixell XWEB freezer controllers, built as a single Python file that detects CVE-2025-41450 attempts and is identified as real devices on Shodan.
 Tech Frontiers
GRFNet: A Lightweight PyTorch Model Designed for Multichannel Time-Series Classification
GRFNet is a lightweight PyTorch model for multichannel time-series classification, originating from EEG decoding research. With only 3,847 parameters, it is based on the ROCKET architecture, combining random convolution kernels with learnable spatial filters, supports arbitrary input lengths, and will soon be evaluated on the PhysioNet dataset.
 Tech Frontiers
CUDA-Accelerated Rocket League Simulator: A Player-Made Hardcore Experiment
A Reddit post shows a "100% Accurate" Rocket League simulator accelerated with CUDA. We analyze its technical context, CUDA's value in game physics simulation, and the significance and limitations of such community projects.