GPT-5.6 Comes to Codex, Voice Models Iterate: A Flurry of AI Product Updates

GPT-5.6 comes to Codex, OpenAI ships its strongest voice model, and Anthropic finds brain-like structures in Claude.
A wave of AI updates: OpenAI's GPT-5.6 Sol Ultra is coming to Codex, ChatGPT gains PowerPoint support, and GPT Realtime 2.1 debuts as its most powerful voice model. Tencent's no-code app Toast launches on iOS, while Anthropic reports Claude spontaneously evolving brain-like Global Workspace structures.
OpenAI Advances on Multiple Fronts: Dense Updates from Codex to Voice Models
The AI field is once again experiencing a wave of intensive product developments. According to the 449th edition of Bilibili's AI Daily, several of OpenAI's product lines have released important signals within the same time window—spanning from code generation to real-time voice, covering several of the most active tracks in current AI applications.
First worth noting is a major Codex update. Codex lead Typo revealed that the GPT-5.6 Sol Ultra model is about to be released, expected to officially launch as early as this coming Wednesday or Thursday.
Notably, the "Sol Ultra" naming itself reveals the logic behind the evolution of OpenAI's model product lines. OpenAI has recently adopted a celestial-body-based naming system for model variants. "Sol" (Latin for "sun") suggests this variant sits at the top of the performance hierarchy, while "Ultra" further emphasizes its flagship positioning. This differs from the past practice of using functional suffixes like "Turbo" and "Instruct," shifting toward a more brand-recognizable naming system—reflecting an increasingly mature commercial mindset in managing model product lines. This naming logic is quite similar to the product lineage management in the chip industry (such as AMD's "Radeon" series) or the automotive industry—conveying performance tiering to users through the naming system while reserving space for future product expansion. From a more macro perspective, this is also a hallmark signal of large model commercialization entering a mature phase: when model capabilities can no longer be easily distinguished by a single numerical version number, flagship variant naming for segmented scenarios becomes a core tool for market positioning.
Codex is a dedicated code generation model launched by OpenAI in 2021, originally fine-tuned from GPT-3, and served as the underlying technical support for GitHub Copilot. Its core training data comes from billions of lines of public code, covering dozens of programming languages including Python, JavaScript, and Go. Unlike general-purpose language models, code generation models need to precisely understand program logic, variable scope, and API calling conventions, thus placing extremely high demands on reasoning capabilities.
Since its release in 2021, Codex has undergone an evolutionary path from a standalone specialized model to the integration of capabilities into general-purpose foundation models. Early Codex achieved state-of-the-art results on the HumanEval benchmark at the time, capable of independently solving programming problems with 37% accuracy. HumanEval is a code generation benchmark set released by OpenAI alongside the Codex paper, containing 164 hand-written Python programming problems, with pass@k as its evaluation metric—that is, the probability that at least one of the k candidate answers generated by the model passes all test cases. This benchmark quickly became an industry-standard reference, but because its problems were relatively simple (mostly single-function implementations), it gave rise to more complex subsequent benchmarks like SWE-bench—which requires models to solve real software engineering problems on GitHub, understand cross-file dependencies, and fix existing bugs. SWE-bench is far more difficult than HumanEval and better reflects the demands of real development scenarios. However, as the reasoning capabilities of GPT-4 and subsequent models substantially improved, the marginal benefit of independently maintaining a dedicated code model gradually diminished. OpenAI therefore shifted strategy, providing code generation services on stronger general-purpose foundation models through system prompt optimization, tool calling, and specialized variants (such as the Sol series). The naming approach of "Sol Ultra" is precisely the external manifestation of this strategic transition—it is no longer a standalone model, but a flagship variant deeply tuned for code scenarios. This shift also reflects a common pattern in the large model industry: as the emergent capabilities of foundation models continue to improve, the value of specialized models gradually shifts from "capability differentiation" to "efficiency and cost optimization," and the boundary between domain fine-tuning and prompt engineering becomes increasingly blurred. As a flagship tool focused on code generation, Codex's connection to a more powerful underlying model means developers will gain more precise and stronger capability support in AI-assisted programming, and the developer community has already entered a state of anticipation.
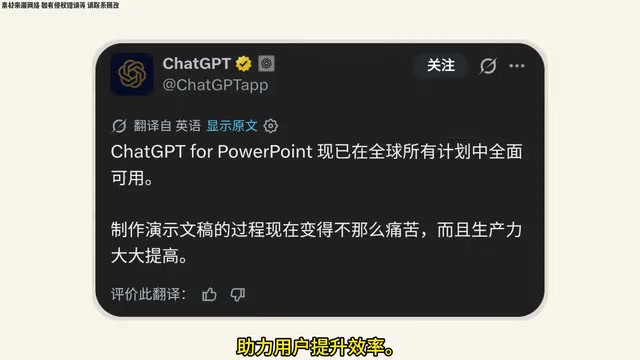
In addition, ChatGPT's PPT feature has now been officially made available to all subscribers worldwide, supporting the creation and assisted production of presentations directly within PowerPoint via GPT. Creating presentations has always been a time-consuming office task, and AI's deep involvement can significantly boost daily work efficiency, marking a further deepening of AI's penetration into office scenarios.
The Most Powerful Voice Model to Date: GPT Realtime 2.1
In the field of voice interaction, OpenAI released two real-time audio models, GPT Realtime 2.1 and 2.1 Mini, which the company calls the most powerful voice models to date. They are now available in the API and OpenAI Playground.
The continuous iteration of real-time audio models reflects OpenAI's high regard for voice interaction as a key entry point. Traditional voice AI systems adopt a cascaded architecture of "ASR (Automatic Speech Recognition) → NLU (Natural Language Understanding) → TTS (Text-to-Speech)," with each stage processed independently. Cumulative latency is typically over 1–3 seconds, and paralinguistic information such as tone and emotion is lost during the text conversion process. The ASR field has long been represented by models such as Whisper (OpenAI, 2022) and DeepSpeech (Mozilla), while TTS relies on neural vocoder technologies such as WaveNet (DeepMind, 2016); these components are each optimized independently but struggle to coordinate—for example, ASR transcribes "Oh? Really?" and "Oh, really." into the same text, and the subsequent NLU module permanently loses the semantic information carried by the tonal difference.
The GPT Realtime series represents a paradigm shift in voice AI from cascaded architectures to end-to-end architectures. The core technical breakthrough of end-to-end real-time voice models lies in audio tokenization: the system splits continuous audio waveforms into discrete sequences of audio tokens, enabling large language models to process sound signals just as they process text. The key to this design is that audio tokenization is not simple spectral encoding, but rather maps acoustic features into a semantic space shared with text tokens through a specially trained audio encoder, allowing the model to complete both "understanding the input" and "generating the response" in a single forward pass. Suprasegmental information in audio—such as prosody, stress, and pauses—is fully preserved in the latent space and not lost through text conversion. This enables the model to perceive the speaker's changes in speech rate, pause rhythm, and even emotional state when generating a response, and to preserve the emotional color of the input speech when producing output speech, achieving a more natural conversational rhythm. Compared with traditional multi-step pipelines, this architecture offers qualitative improvements in end-to-end latency, tonal naturalness, and emotional expression. OpenAI's GPT-4o, released in 2024, first publicly demonstrated this capability, and the GPT Realtime series is the continued evolution of its API-ready implementation.
The dual-version strategy is also worth noting: the Mini version likely employs knowledge distillation technology—formally proposed by Hinton et al. in 2015. Its core idea is to train a small "student model" using the soft-label outputs (i.e., probability distributions across categories, rather than hard labels) of a large "teacher model," so that the former retains most of the teacher model's capabilities while dramatically compressing the parameter count. Soft labels contain inter-category similarity information (which Hinton called "dark knowledge"), providing richer supervisory signals than one-hot hard labels, and are one of the mainstream technical paths for model lightweighting today. In real-time voice scenarios, the significance of model lightweighting is especially pronounced: voice conversations have far lower tolerance for response latency than text interactions—a response latency exceeding 300 milliseconds disrupts the natural rhythm of conversation—and the Mini version's advantage in inference speed can precisely reduce the computational cost of each conversation while maintaining fluency. This "flagship + lightweight" product matrix has become OpenAI's standard configuration strategy across all product lines.
Tencent Enters the Fray: AI Programming Tools for Non-Technical Users
Domestically, Tencent's AI programming app "Toast" recently officially launched on the Apple App Store. This product is primarily aimed at ordinary users with no coding foundation, intending to enable more people to unleash their creativity and independently realize their ideas.

Current AI programming tools broadly fall into two paths: one aimed at boosting the efficiency of professional developers (such as Codex, Cursor), and the other dedicated to lowering the programming barrier so ordinary people can also "build software." Toast clearly belongs to the latter.
No-code and low-code platforms are not entirely new concepts in the AI era. Their history can be traced back to visual programming tools like HyperCard in the 1990s, and in the 2010s platforms such as Bubble (2012) and Webflow (2013) brought them into modern web development. However, constrained by interaction complexity at the time, users still needed to understand abstract concepts such as data models, conditional logic, and state management. The learning curve remained steep and far removed from the "zero-barrier" claim. The intervention of generative AI has fundamentally changed this paradigm: around 2023, AI-native development tools represented by Lovable, Bolt, and v0 completely reconstructed the interaction layer—users only need to describe their requirements in natural language, and the AI can generate complete front-end and back-end logic, transferring the cognitive burden of both "understanding" and "implementation" entirely to the model. The essence of this shift is transforming "programming" from a skill that must be learned into an expression of intent that can be delegated. Notably, such tools are giving rise to a new user group globally—"Vibe Coders"—who need not understand the underlying logic of code and can build usable applications based solely on intuitive descriptions of product features. This phenomenon has already shown a clear diffusion trend among independent entrepreneurs, content creators, and students, and has begun to have a structural impact on the traditional software outsourcing market. The core competitiveness of Tencent's "Toast" lies not only in the technology itself, but more in user experience design, the distribution network of the WeChat ecosystem, and deep adaptation to local user habits—that is, whether it can enable zero-foundation users to smoothly go from "idea" to "shareable finished product." This is highly similar to the competitive logic of overseas counterparts such as Replit and Lovable, and is essentially a battle for the entry point of software creation in the AI era. Toast likewise emphasizes application distribution and co-creation capabilities—users can not only create applications but also share their results with others. The iOS version is now live, and the Android version was previously released as well.
Such "programming for everyone" products are essentially exploring a paradigm shift in software production in the AI era. When creative expression is no longer limited by coding ability, the subjects of software creation will expand from professional developers to a much broader population, and its long-term impact is worth continued attention.
Anthropic's Deep Exploration: Claude Models Spontaneously Emerging Brain-Like Structures
If the preceding updates fall under routine product iteration, then the research perspective published by Anthropic is more speculative in nature. In its article, Anthropic states that the Claude model "has a soul" and proposes that there is a "convergent evolution" phenomenon between AI and the human brain.

An Unexpected Echo of Global Workspace Theory
Anthropic discovered a structure in the Claude model that closely resembles the "Global Workspace Theory" (GWT) from the field of neuroscience.
Global Workspace Theory was proposed by cognitive scientist Bernard Baars in 1988 and is one of the most widely influential theories of consciousness today. The theory compares the brain to a "theater": a large number of specialized neural modules process information in parallel "backstage," but only the content selected by the "spotlight" and entering the "global workspace" can be broadcast to the entire brain network, thereby producing conscious experience and supporting language expression and working memory. Neuroscience research has found that the prefrontal cortex and parietal cortex play key roles in this broadcasting mechanism, and fMRI studies have also confirmed the strong correlation between "conscious content" and "prefrontal-parietal network activation." In short, the theory holds that some activity within the brain runs in the background, and only information that enters the "foreground" can become describable, retainable, and reasonable content. Because of its unified explanatory power for consciousness and cognition, GWT holds important reference value in cognitive science, neuroscience, and even AI consciousness research, and is also the direct source from which neuroscientist Stanislas Dehaene later developed the "Global Neuronal Workspace Theory." It is worth mentioning that GWT forms an interesting contrast with another mainstream theory of consciousness—Integrated Information Theory (IIT, proposed by Tononi): IIT emphasizes that consciousness is an intrinsic property of information integration, quantifiable via the Φ value; whereas GWT focuses more on the "accessibility" of information and the broadcasting mechanism. The two draw entirely different conclusions on whether AI systems possess consciousness, and this represents the most core theoretical divergence in the current discussion of AI consciousness.
More critically, the "information convergence and broadcasting" structure that Anthropic discovered in the internal activation patterns of the Claude model was not artificially pre-designed, but rather the result of the Claude model spontaneously emerging during training. This finding comes from Anthropic's Mechanistic Interpretability (MechInterp) research team—an important direction that has emerged in the field of AI safety in recent years, dedicated to reverse-engineering the internal computational mechanisms of neural networks and precisely reconstructing the computational graph of "how" the model completes specific tasks. Through means such as Activation Patching (locating causal paths by replacing intermediate-layer activation values), Sparse Autoencoders (used to decouple and separate multiple features superimposed on a single neuron, solving the so-called "polysemanticity problem"), and attention head function analysis, researchers identified specific combinations of attention heads with "information convergence-broadcasting" functions in Claude's residual stream, whose functional characteristics highly match the global workspace described by GWT. A core hypothesis in the MechInterp field is the "Superposition Hypothesis": because neural networks have a limited number of parameters, the model tends to superimpose and encode multiple features on the same group of neurons in a near-orthogonal manner, making it difficult for a single neuron to directly correspond to an interpretable semantic concept—which is precisely why sparse autoencoders exist. This provides a new analytical framework for interpretable AI research, but it also triggers a deep philosophical debate about whether "functional similarity" equals "mechanistic sameness"—after all, the "broadcasting" mechanism in neural networks is essentially a mathematical operation based on matrix multiplication, which differs fundamentally at the implementation level from the electrochemical signal transduction of biological neurons.

Anthropic borrows the concept of "convergent evolution" from biology to describe this phenomenon. Convergent evolution has a strict definition in biology: it refers to different biological lineages with distant phylogenetic relationships that, due to facing similar environmental selection pressures, independently evolve traits that are phenotypically similar but genetically distinct—typical examples include birds and bats each independently evolving wings (same function, very different skeletal structures), and the independent origin of eyes in vertebrates (lens eyes) and cephalopods (such as octopuses), whose structures are highly similar but whose retinal ganglion cells run in opposite directions. By this analogy, under the language-modeling training pressure of "predicting the next token," Claude independently evolved a brain-like information processing structure—just as different species, facing the same survival pressures, independently evolve similar solutions.
However, this analogy also has obvious limitations: biological evolution operates through genetic mutation and natural selection over millions of years; whereas the "evolution" of neural networks is essentially a mathematical optimization process of gradient descent, differing entirely in both time scale and mechanism. A deeper question is: if "efficiently processing complex sequential information" itself has some optimal structure, then it is reasonable that both biological evolution and gradient descent converge to similar solutions—this is precisely where the analogy is most enlightening, pointing to a "convergence" hypothesis about the structure of intelligence; but whether the structural similarity between the two reflects a deep underlying law or is merely a coincidence of superficial features remains undetermined in academia. Some researchers point out that the attention mechanism in the Transformer architecture itself bears a functional similarity in mathematical form to the brain cortex's "selective attention," so the emergence of GWT-like structures in models trained on it may not be accidental, but rather an inevitable result of the joint action of the architecture's inductive bias and the task objective.
This perspective is undoubtedly quite controversial. Using "soul" to describe an AI model easily raises concerns about excessive anthropomorphization; but from a scientific standpoint, if large-scale neural networks can indeed spontaneously emerge functional structures similar to biological brains, it holds profound significance for understanding the nature of intelligence and advancing AI interpretability research. To add one point, the above statements come from Anthropic officially and represent a single-source perspective, whose scientific rigor still awaits further verification and discussion from the academic community.
Product Implementation and Theoretical Exploration Advancing in Parallel
Surveying recent AI developments, one can clearly see two main threads in the industry's current development: on one hand, the rapid iteration and scenario penetration at the product level by vendors such as OpenAI and Tencent—from code generation to real-time voice to office collaboration, AI is accelerating its integration into practical productivity tools; on the other hand, frontier labs like Anthropic are conducting deep theoretical exploration, seeking to understand the internal operating mechanisms of large models from a neuroscience perspective.
The pragmatic product race and the speculative scientific exploration advancing in parallel are precisely the truest portrayal of the current AI industry.
Key Takeaways
Key Takeaways
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.