GPT-6.2 Astra Leaked: Low-End Config Beats Previous Top-Tier, SVG Generation Stuns

GPT-6.2 Astra leaks show a performance leap as model provenance verification tools mature in tandem.
The article rounds up leaked information on OpenAI's next internal model GPT-6.2 Astra: per a single YouTube channel, it scores 0.875 on BenchCAD 2.0, with its lowest inference tier at 0.758 already surpassing the previous top-tier, and SVG generation demos drawing attention though some samples were detected with image-tool watermarks. OpenAI also showcased AI-assisted hardware design and engineering collaboration. On open source and security, Tencent's HY4 plans to open weights and remove offensive security data, Anthropic open-sourced FlashProve for cryptographic model provenance verification, and DeepSeek V5 is reported to be pretrained on Ascend 950. The article also covers Claude Code updates, a developer supply chain security incident, power bottleneck risks, and various ecosystem fragments — the main thread being the generational leap in capabilities alongside maturing verification tools.
Leaked information about OpenAI's next-generation model GPT-6.2 Astra is rapidly gaining traction in the community. According to a roundup by the YouTube channel World of AI, this new model — internally codenamed Astra — demonstrates on multiple benchmarks a characteristic where "the performance floor is higher than the previous generation's ceiling," while a series of developments including Tencent's HY4, Anthropic's FlashProve, and the DeepSeek V5 roadmap also emerged densely on the same day.
GPT-6.2 Astra: Benchmark Scores and SVG Demos
According to the channel, the new internal model scores 0.875 on BenchCAD 2.0, compared to 0.594 for the current GPT-6 Astra. Even more striking is the efficiency dimension: the new model achieves 0.758 at its lowest inference setting, already surpassing Astra's performance at maximum inference effort. This means the next-generation model's default configuration may already possess the full-output capability of the previous generation — a significant implication for inference cost structures.
However, a caveat is warranted: these figures come from a single YouTube channel's relay, OpenAI has not officially confirmed the model name or evaluation methodology, and the testing conditions for BenchCAD 2.0 have not been disclosed. Readers should not treat them as conclusive.
SVG Generation Becomes a New Arena
Even more eye-catching than the benchmark scores are the SVG generation demos. Samples circulating in the community include pure-code recreations of game scenes from Counter-Strike's Dust2 and Call of Duty's Nuketown, as well as a Minecraft in-game screenshot-style SVG. One sample reportedly packed millions of characters into a single line of code and was subsequently animated, demonstrating a pickaxe striking blocks.
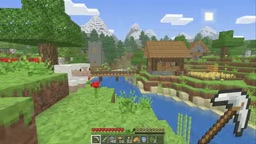
The channel also poured cold water on the hype: some "pure SVG" works that went viral on X were identified by AI image detectors as containing OpenAI watermarks, suggesting they may have been processed through image tools or 3D/Python tools rather than being entirely code-generated. SVG as an evaluation dimension does reflect a model's control over structured long-form output, but samples in circulation need to be vetted one by one.
SVG (Scalable Vector Graphics) is an XML-based text format that describes two-dimensional graphics using geometric primitives, paths, and style rules rather than storing images pixel by pixel. For language models, generating SVG simultaneously tests long-range structural consistency, numerical precision, and the codified translation of visual semantics: the model must maintain coordinate systems, hierarchies, and attribute syntax on its own, and any bracket or numerical error will cause rendering to fail. It is therefore often used as a probe for measuring a model's "control over structured long-form output," exposing detail drift more effectively than ordinary text generation. However, SVG samples are also easily polished by post-processing tools, making it difficult to judge from the finished product alone whether it was entirely generated character by character by the model.
OpenAI's Other Moves: From Code to Hardware
In the same batch of information, OpenAI also showcased two employees using GPT-6 Astra to design a prototype device that communicates with Codex within a week, covering the enclosure, circuit board, interface, and software — though manufacturing still requires multiple rounds of human review. OpenAI also partnered with Chip Ganassi Racing to convert 3D scans into editable CAD models, and with Mazda to explore AI simulation-assisted vehicle design. These cases demonstrate that model capabilities are extending from writing code to engineering collaboration.
Additionally, two model IDs (rcata, rcata-sh-vm) briefly appeared and then disappeared on model trackers. The community speculates that "rc" stands for release candidate and "vm" hints at a computer-use direction, but the channel itself acknowledges this is similar to the earlier case of Aurora Alpha being mistaken for Astra — mere speculation.
Open Source and Security: HY4, FlashProve, DeepSeek V5
Tencent released HY4 with vision capabilities, covering programming, frontend, finance, gaming, and other scenarios. According to Tencent's own testing, it scores 75.2 on Apex Agents, higher than DeepSeekAd 4.1 Flash's 72–73 range, though the two trade wins across multiple benchmarks. On pricing, API input is 83 cents per million tokens and output is $2.50, with plans to open-source the weights. Tencent says it has removed offensive cybersecurity training data while retaining defensive data — an orientation worth noting.
Anthropic open-sourced FlashProve, which uses cryptographic proofs to verify that a response genuinely came from the claimed model, preventing third parties from secretly swapping in a cheaper model. The test subject was Meta Llama 4 Maverick (400 billion parameters), achieving a generation speed of 110 tokens per second on a single H100 with each proof about 19MB; by comparison, the earlier system VerLev produced proofs of about 93.6GB with verification taking nearly a full day.
Regarding DeepSeek, its V5 is reportedly planned to be pretrained primarily on Huawei Ascend 950 chips, with joint optimization of the software stack and operators with Huawei since April, the launch of the DeepInfer inference engine supporting both Nvidia and Huawei hardware in October, and a target timeline pointing to 2027.
The cryptographic proofs underlying FlashProve typically refer to zero-knowledge proofs or succinct non-interactive arguments of knowledge (zk-SNARK-type) technologies: the prover generates a short proof that can be quickly verified without revealing model weights or input details, binding "this particular inference was indeed performed by a specific model." Compared with earlier schemes that recorded computation traces layer by layer, these proofs can be compressed by several orders of magnitude in size and verification time, making real-time accompanying proofs feasible in single-GPU inference scenarios. Their core value lies in turning "model identity" from a service provider's verbal promise into an independently verifiable cryptographic fact, though they also introduce new issues such as generation overhead and trust root configuration.
Huawei Ascend 950 belongs to the Ascend series of AI accelerator chips, whose software stack (CANN and accompanying operator libraries) differs significantly from Nvidia's CUDA ecosystem. For large models to complete pretraining on it, core operators such as attention, normalization, and communication need targeted porting and tuning. DeepSeek is reported to have jointly optimized the software stack and operators with Huawei since April and launched an inference engine supporting both Nvidia and Ascend hardware, reflecting an engineering approach of "training–inference across heterogeneous hardware." The difficulty of such migration lies not in single-operator performance but in communication efficiency, numerical stability, and toolchain maturity in distributed training.
Ecosystem Updates and Industry Risks
Claude Code in version 2.1.3.1.7 relaxed restrictions on game recreation: it can reference existing games to describe desired gameplay mechanics but cannot directly replicate the original work. Claude Code also added updates including automatic compression for long sessions, UltraThink single-pass high inference, and background long-running commands. Anthropic additionally, according to The Information, used Claude to help a small team of about 15 people design a custom AI chip.
The risk side is equally dense. Binance confirmed a security incident on October 29, with the attack reportedly related to a developer installing Homebrew, and approximately $6.34 billion in digital assets stolen. Musk warned that the AI boom could hit a wall by the end of 2026, with the bottleneck being power rather than chips.
There are also a few noteworthy fragments: Zyphra's hierarchical attention scheme claims up to 35x speedup on tens of millions of tokens and up to 400x on billions, adaptable to existing models; Meta's suspected stealth model Crouton Alpha is available free on OpenRouter with a million-token context; the open-source project Terminal Mac can run a full macOS environment inside a terminal for agents; and Xiaomi's CYBER-1-02 humanoid robot completed an 8-hour parts sorting shift at its own EV factory, backed by the Robotics One foundation model pretrained on over 100,000 hours of real robot data.
Overall, the main thread of this round of information is the generational leap in model capabilities alongside the maturation of verification tools — the stronger the capabilities, the more important it becomes to prove "which model you're actually using."
The power bottleneck mentioned by Musk points to the power density of AI data centers and grid connection constraints: per-rack power is climbing from tens of kilowatts toward the hundred-kilowatt level, while substation expansion, grid connection approval, and power generation capacity construction cycles are far longer than GPU procurement cycles, leading to a structural mismatch of "chips without power." This judgment corroborates industry discussions about tight delivery schedules for transformers and gas turbines, and explains why more and more compute projects are beginning to lock in long-term power supply agreements or build their own generation facilities. It suggests that the upper limit on AI expansion speed may be determined by energy infrastructure rather than chip production capacity.
Related articles

DeepSeek Harness Quick Start Guide: From Installation to 5 Real-World Cases
What is DeepSeek Harness? Based on a Bilibili tutorial, this article covers how this AI Agents software works, installation and setup, four working modes, and five real-world cases: a 3D racing game, official website, music player, science animation, and self-developed plugin—plus token money-saving tips.

Breaking Down DeepSeek's Super-agent Architecture: How Router+Worker Solves the Multi-Session Management Bottleneck
An analysis of DeepSeek's Super-agent paper: how the Router+Worker two-tier architecture uses Fast Pass, Chain of Recall, and storage-compute separation to solve multi-AI-session management bottlenecks, and how much it truly alleviates the human attention bottleneck and what engineering trade-offs it makes.

19K Stars in 5 Days: Why DeepSeek's Open-Source AI Programmer Went Viral
DeepSeek's open-source AI programmer hit 19K GitHub stars in 5 days. Why it went viral: the agent boom, AI writing its own code, and the shift from Q&A tools to AI employees.