How AI Agents Actually Work: The Four-Step Loop and Built-In Tools

Anthropic breaks AI Agents down into a four-step loop — gather context, act, verify, repeat — with built-in tools included.
Anthropic's definition of an AI Agent is surprisingly simple: a four-step loop of gather context, take action, verify the work, and repeat. At the SDK level, each loop iteration is called a turn — Claude decides which tools to call, the SDK executes them and returns results, and token usage and cost are reported when the task ends. Using a failing test fix in auth.ts as an example, the Agent runs tests first, reads the code to find the issue, then edits and re-verifies — mirroring how an engineer actually solves problems. Built-in tools covering file I/O, search, Bash, web access, and subagent orchestration mean developers can start building without writing tool logic from scratch.
The Core of an AI Agent: A Loop
Many people overcomplicate AI Agents, but Anthropic's definition is surprisingly straightforward — at the heart of every agent is a continuously repeating loop. This loop breaks down into four beats: gather context, take action, verify the work, and repeat.
Here's an analogy to make it concrete: a bread-baking robot observes first, then bakes, then sniffs to check doneness, and repeats if something's off — until the bread is just right. That's essentially what an Agent does. It doesn't produce a one-shot answer; instead, it converges on a goal through multiple rounds of probing and correction.
This looping structure is what sets Agents apart from ordinary single-turn model calls. A standard call runs once and stops. An Agent continuously adjusts its next action based on feedback from each previous step.
One Loop Iteration = One Turn
In Anthropic's SDK, each iteration of the loop is called a turn. The flow is straightforward:
Claude reads your prompt, decides what to do, and requests tool calls. The SDK executes those tools and feeds the results back to Claude. This repeats until Claude determines the task is complete.
When the task is finished, you receive a final result that includes not just the answer, but also token usage and cost. This matters a great deal in production environments — it gives developers clear visibility into how many resources each Agent run consumed, rather than leaving them with an uncontrollable black box.
It's worth noting that a "turn" in the Agent context differs from the conventional notion of a conversational turn. In a typical chat, one turn means the user says something and the model replies. In an Agent context, a single turn can encompass multiple tool calls — Claude might call Bash to run tests, then Read to examine a file, then Edit to modify code, all within the same turn. The SDK executes each call sequentially and appends results to the context until Claude decides to stop calling tools. This "multiple tool calls within a single turn" mechanism is the underlying engine that enables Agents to complete complex, multi-step tasks. Token usage and cost are also aggregated at the turn level, giving developers a useful middle ground for cost monitoring — more granular than tracking the entire task as a unit, but not as fine-grained as individual tool calls.
A Real-World Example: Fixing Failing Tests
The official documentation offers a clear, concrete illustration of how this loop plays out in practice. The task: fix failing tests in auth.ts.
- Turn 1: Run the tests, find three failures.
- Turn 2: Read the source and test files, understand the problem.
- Turn 3: Edit the file, run the tests again — all green.
Claude then delivers a closing message: "Fixed — all three tests passing."
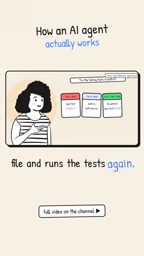
What makes this example worth studying is what the Agent didn't do — it didn't blindly start rewriting code. It first ran the tests to establish the current state, then read the code to pinpoint the issue, then made changes and used the test results to verify its own work. That's the "verify the work" beat in action, and it's what makes Agent output reliable rather than wishful.
Tools Included Out of the Box — No Need to Build Your Own
Powering this loop is a set of built-in tools. Developers don't need to implement these capabilities from scratch — they come ready to use:
- File operations: Read, Edit, Write — for reading, modifying, and creating files.
- Search: Glob and Grep — for matching file paths and searching text content.
- Command execution: Bash — for running shell commands.
- Web access: Web Search and Web Fetch — for searching and scraping web pages.
- Extended capabilities: Tools for launching subagents and loading skills.
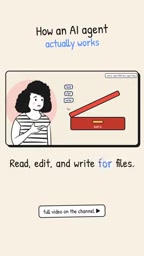
This "batteries included" design philosophy dramatically lowers the barrier to building Agents. In the past, developers had to define their own tool interfaces, handle invocation protocols, and write execution logic from scratch. Now, the most common capabilities are standardized and packaged. You describe the task — the loop handles the rest.
The subagents capability deserves a closer look. For complex tasks, a primary Agent can dynamically spin up one or more sub-Agents, delegate subtasks to them (in parallel or in sequence), and then aggregate the results. This multi-Agent collaboration pattern mirrors the "divide and conquer" approach in software engineering — the primary Agent acts as an orchestrator, while each sub-Agent focuses on its specific subtask, communicating through tool call interfaces. This is exactly why "launch a subagent" is listed as a built-in tool: from the model's perspective, calling a sub-Agent and calling a Bash command are structurally identical — both are "invoke a tool and wait for a result." This design means an Agent's capabilities can scale indefinitely through nesting, without stuffing all logic into a single monolithic loop.
Why This Model Matters
Peel back the layers, and Agents aren't mysterious: a loop, a set of callable tools, and the model's ability to decide when to call which tool. The real "intelligence" lies in how the model interprets feedback at each step and keeps iterating until the task is done.
For developers building Agent applications, understanding the concept of a "turn" and the four-step loop matters more than assembling a complex framework. The chain from running tests to reading code to editing files maps directly onto how a human engineer actually solves problems — observe first, analyze, act, then verify. The value of Agents lies in automating exactly that methodology.
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.