How AI Applications Can Break Through Homogeneous Competition: From GPT Wrappers to Real Products

How AI applications can differentiate beyond being GPT wrappers through vertical depth, data flywheels, and product thinking.
As LLM capabilities strengthen, AI applications face the existential challenge of being dismissed as GPT wrappers. This article uses an Arabic grammar learning app as a case study to explore how developers can build real product moats through vertical domain depth, validation layers, data flywheels, community building, and structured user experiences that go far beyond simple API calls.
Starting with a Real Dilemma
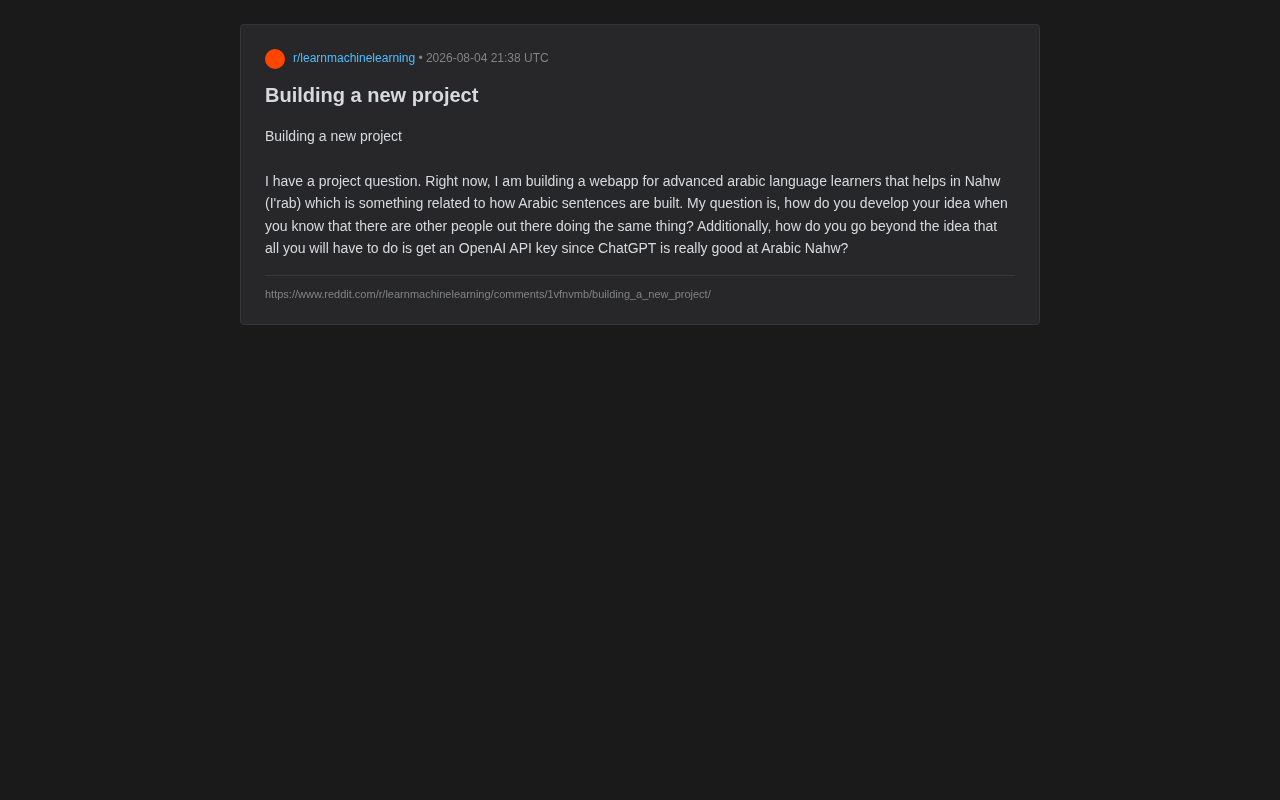
I recently came across a highly representative project dilemma on Reddit that's worth deep reflection for every developer looking to build AI applications. A developer was building a web app for advanced Arabic learners, focused on Nahw (i.e., I'rab, involving grammatical structure analysis of Arabic sentences).
Nahw is the core branch of Arabic grammar studies, and I'rab specifically refers to the case-ending marking system. Arabic is a highly inflected Semitic language where a word's grammatical role in a sentence (subject, object, adverbial, etc.) is distinguished through vowel endings rather than word order as in English. This means the same root word takes different endings depending on its grammatical position. For advanced learners, mastering I'rab is the critical threshold for understanding Classical Arabic texts (especially the Quran and classical literature). The uniqueness of this field lies in: its vast rule system full of exceptions, the need for deep syntactic tree understanding in machine processing, and the fact that while general-purpose LLMs have some capability, their accuracy drops significantly in complex scenarios like multi-layered nested clauses and rhetorical inversions.
He raised two questions that cut straight to the heart of the matter:
- When you know others are already doing the same thing, how do you develop your own idea?
- Since ChatGPT already performs remarkably well in Arabic grammar, how do you break free from the dilemma of "ultimately just connecting to an OpenAI API Key"?
These two questions may seem aimed at a niche domain, but they actually represent the core challenge facing all AI application entrepreneurs today. As LLM capabilities grow increasingly powerful, the accusation of being a "GPT wrapper" is virtually everywhere.
"GPT Wrapper" has been one of the most controversial topics in the AI startup circle since 2023. After OpenAI opened its API, thousands of startup projects emerged, with a significant portion whose core functionality was merely wrapping a simple interface around the ChatGPT API. Partners at Y Combinator have publicly stated that a large number of AI projects in their application batches fall into this category. The fundamental risk these projects face is: once OpenAI itself launches similar features (like GPTs, Custom Instructions), or model capabilities improve dramatically enough that users can simply use ChatGPT directly, these products instantly lose their reason to exist. This is why the industry increasingly emphasizes product-level differentiation rather than mere API calls.
In the LLM Era, Where Are the Moats for AI Applications?
General Capability Does Not Equal Product Value
ChatGPT can do Arabic grammar analysis—that's a fact. But there's a huge chasm between "the model can do it" and "the product is usable."
A bare dialog box that directly calls an API is not low-barrier for average users: they don't know how to write precise prompts, can't verify the correctness of outputs, and cannot receive structured feedback during the learning process. Real product value lies precisely in filling these gaps.
In other words, OpenAI provides the "raw materials," and your job is to process those raw materials into a "finished product" that users are actually willing to pay for. With the same flour and water, a bowl of street-side noodles and handmade pasta at a Michelin-starred restaurant have vastly different value.
Vertical Depth Is the Best Differentiation Strategy for AI Products
For specialized domains like Nahw, general-purpose models often have obvious shortcomings:
- Unstable accuracy: Grammar analysis demands extremely high precision, and general models may make errors on complex sentence structures that learners cannot independently identify.
- Lack of pedagogical logic: Models can provide answers but may not explain things progressively according to Arabic language teaching methodology.
- No progress tracking: A real learning product needs to record users' weak areas and provide targeted practice.
Deep cultivation in these dimensions is the key to building product moats.
How to Face Homogeneous Competition: What If Others Are Already Doing It?
The Existence of Competition Is Proof of Demand
Many founders retreat the moment they see competitors, which is actually a misconception. A field with absolutely no competitors usually means one of two things: either the market is too small, or the demand is a false demand. Others doing the same thing actually validates that real demand exists in this direction.
The real question isn't "is anyone doing this" but "where are existing solutions falling short?" Taking Arabic learning tools as an example, you can look for breakthroughs from these angles:
- Is the competitor's user experience smooth enough?
- Have they specifically optimized for advanced learners?
- Is there room for improvement in pricing, content quality, or community atmosphere?
Find Your Unique Entry Point
This developer's positioning is actually quite smart—he's targeting advanced learners as a specific segment, rather than a comprehensive Arabic learning solution. This precise positioning is itself the starting point for differentiation.
Further questions to consider include: Can you combine authoritative grammar textbooks to build structured courses? Can you design an interactive sentence parsing tool that lets users "deconstruct" sentences rather than passively receive answers? Can you introduce a Spaced Repetition mechanism to reinforce memory?
Spaced Repetition is a learning method based on the "forgetting curve" theory in cognitive psychology, first systematically studied by German psychologist Hermann Ebbinghaus in the late 19th century. Its core principle is: memory decays along an exponential curve over time, but after each successful recall, the rate of forgetting slows down. Based on this, spaced repetition algorithms (such as SuperMemo's SM-2 algorithm and Anki's improved version) schedule reviews at optimal time points to achieve maximum memory retention with minimal learning investment. In the language learning field, products like Duolingo, Anki, and Memrise all deeply employ this mechanism. For Arabic grammar learning, breaking I'rab rules and typical sentence patterns into reviewable knowledge cards, combined with spaced repetition scheduling, can significantly improve long-term memory—this is a structured learning experience that purely conversational AI cannot automatically provide.
These are all product capabilities that general-purpose LLMs cannot directly offer.
The Progression Path from GPT Wrapper to Real Product
LLMs Are the Capability Layer, Not the Product Layer
In a healthy AI application architecture, the LLM is just one of the underlying capabilities. What truly determines product success or failure is the complete experience built around it:
- Data layer: Accumulate domain-specific corpora, exercises, and error databases—these are unique assets beyond the model itself.
- Interaction layer: Design interfaces and workflows suited to learning scenarios, lowering the barrier to use.
- Validation layer: Compensate for LLM accuracy shortcomings through rule engines or expert verification.
- Growth layer: As more user data accumulates, personalized recommendations become more precise, forming a positive feedback loop.
Among these, the validation layer design is particularly critical in professional domains requiring high precision. A Rule Engine is a system that makes judgments based on predefined logic rules. In Arabic grammar analysis, deterministic grammar rules (such as subjects must be in nominative case marfu', nouns after prepositions must be in genitive case majrur, etc.) can be encoded as hard rules to verify the correctness of LLM outputs. This hybrid architecture of "neural networks + symbolic reasoning" (Neuro-Symbolic AI) is becoming an industry trend. Additionally, introducing domain experts for human verification (Human-in-the-Loop) can further establish content authority. When the validation layer detects conflicts between model output and rules, it can automatically trigger corrections or flag items for review, thereby raising accuracy to the level required by professional educational products.
Data Flywheel and Community Are Long-Term Barriers
Once the product has been running for a while, you'll accumulate user learning behavior data, common error patterns, and effective teaching strategies. This data can in turn optimize the product, or even be used to fine-tune a proprietary model. This "data flywheel" is something no competitor who simply calls an API can replicate in the short term.
The Data Flywheel concept originates from Amazon founder Jeff Bezos's famous "flywheel effect" business thinking, later widely applied in AI product strategy. Its operational logic is: more users bring more data, more data trains better models or recommendation algorithms, better product experiences attract more users, forming a self-reinforcing positive cycle. In the context of AI applications, the key to the data flywheel lies not only in the quantity of data but in its uniqueness and domain specificity. For example, the behavioral data accumulated by an Arabic grammar learning platform—"which sentence patterns do advanced learners repeatedly get wrong" and "which explanation methods lead to higher comprehension rates"—is virtually nonexistent in public datasets. This data can be used to fine-tune models, optimize learning paths, and build personalized recommendations, ultimately forming a structural advantage that competitors cannot easily overcome.
Furthermore, the community built around professional learners, expert endorsements, and brand trust are all soft barriers that transcend technology itself.
Practical Advice for AI Application Developers
Returning to the original questions, we can summarize several practical principles:
- Don't fear competition—what you should fear is the absence of demand.
- Don't treat the LLM as the product—it's just one component of your product.
- Go deep in vertical domains—the shortcomings of general models are your opportunities.
- Accumulate proprietary data and community—these are the true long-term moats.
- Start from solving specific pain points, not from showing off technology.
For this Arabic learning app developer, rather than agonizing over "ChatGPT already knows Nahw," it's better to think about "how to help advanced learners master Nahw more efficiently and enjoyably." The former is a technology perspective; the latter is a product perspective—and the latter is where real value is created.
Key Takeaways
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.